Count-domain fitting (α calibration & single histograms)
Count-domain fitting works on raw detector counts rather than the reduced asymmetry. Two modes are available from the Fit target selector at the top of the Multi-Group Fit window, alongside the existing All groups grouped fit:
Forward + Backward (free α) — fit a forward and a backward count histogram simultaneously with α as a free fit parameter. This is the statistically proper way to obtain α from a transverse-field calibration run, superseding the grid estimators in the Grouping dialog.
Single group — fit one detector histogram to the count model N₀·exp(−t/τ_μ)·(1 + A·P(t)) + bg. This is the musrfit single-histogram (fittype 0) analogue, used for calibration and diagnostic work, and it is the natural mode for continuous-source data where a single detector already carries the full decay envelope.
A fresh count request prepares the retained acquired histograms with its current grouping and corrections. A failed cached asymmetry curve does not block that request after its grouping is repaired; the cached diagnosis remains history. Current unavailable corrections, missing acquired observations, and unsupported count likelihoods still receive their own diagnostics.
The grouping background preflight retains its typed decisions as
count_background_preflight. An unusable automatic tail is a warned skip,
coordinated over the count groups contributing to the fit. Count inputs retain
their full background: the joint count model still owns its background nuisance.
Fit warnings and saved summaries retain the preflight request, status, and
reason; an applied preflight records an available estimate, not subtraction
from the joint model’s observations.
The shared scriptable TF calibration operation in Alpha calibration chooses its objective from the resolved deadtime outcome: raw Poisson for off/skipped correction, or weighted counts with retained measured/supplied variance after an applied correction. It reuses the same prepared banks and joint solver as the explicit count-fit targets. Its automatic background terms retain the distinction above; grouping fixed values and range/tail estimates do not constrain or seed the model terms.
Active Background run subtraction is unsupported for Single group,
F + B (free α), and All groups count-fit inputs, for either cost.
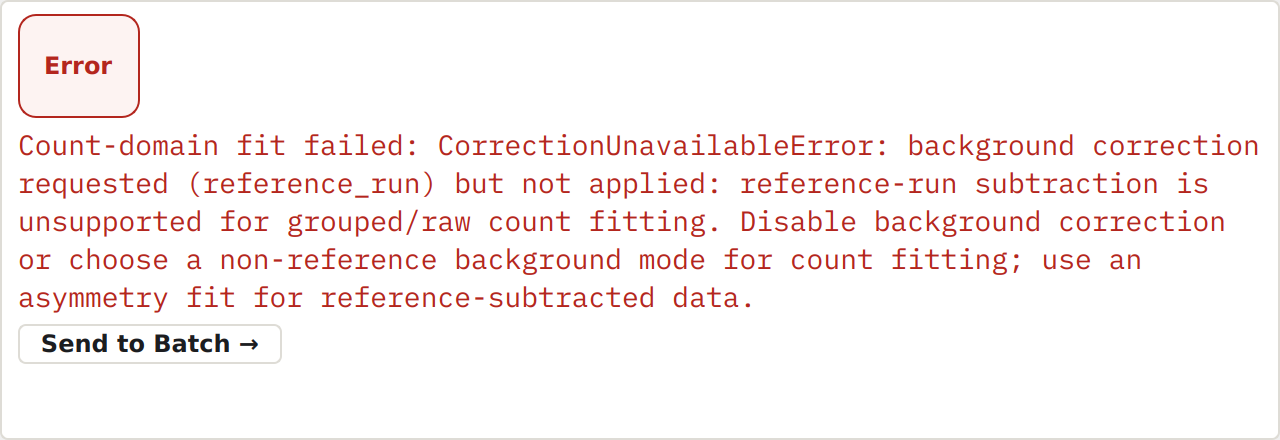
The shared input boundary raises CorrectionUnavailableError with:
background correction requested (reference_run) but not applied: reference-run subtraction is unsupported for grouped/raw count fitting. Disable background correction or choose a non-reference background mode for count fitting; use an asymmetry fit for reference-subtracted data.
Loading the reference does not enable this workflow. Disable background correction in Grouping, or select a non-reference mode when its preflight is needed, and fit the full counts with the count model’s background nuisance. Inactive reference settings do not block a count fit. For a justified reference subtraction, use the reduced asymmetry workflow described in Background correction. A difference of independent counts is not a raw Poisson observation, even when its value is positive and integral. Physical sample/holder polarisation belongs in the model; the flat count nuisance describes accidental events.
When to use this. Reach for the free-α fit whenever you need a defensible α from a calibration measurement and want its uncertainty and — importantly — its correlation with the signal amplitude. In a transverse field the count balance can trade against the asymmetry amplitude, so α and A are strongly correlated; the joint fit reports that correlation, which a grid estimate cannot. Reach for the single-histogram fit when one detector is the object of study: a continuous-source run where you want the bare envelope and background, or a diagnostic check that one detector’s N₀ and background behave as expected. For ordinary physics extraction from balanced data, the regular F–B asymmetry fit remains the faster path — count-domain fitting is a calibration and diagnostic tool, not a replacement for asymmetry fitting.
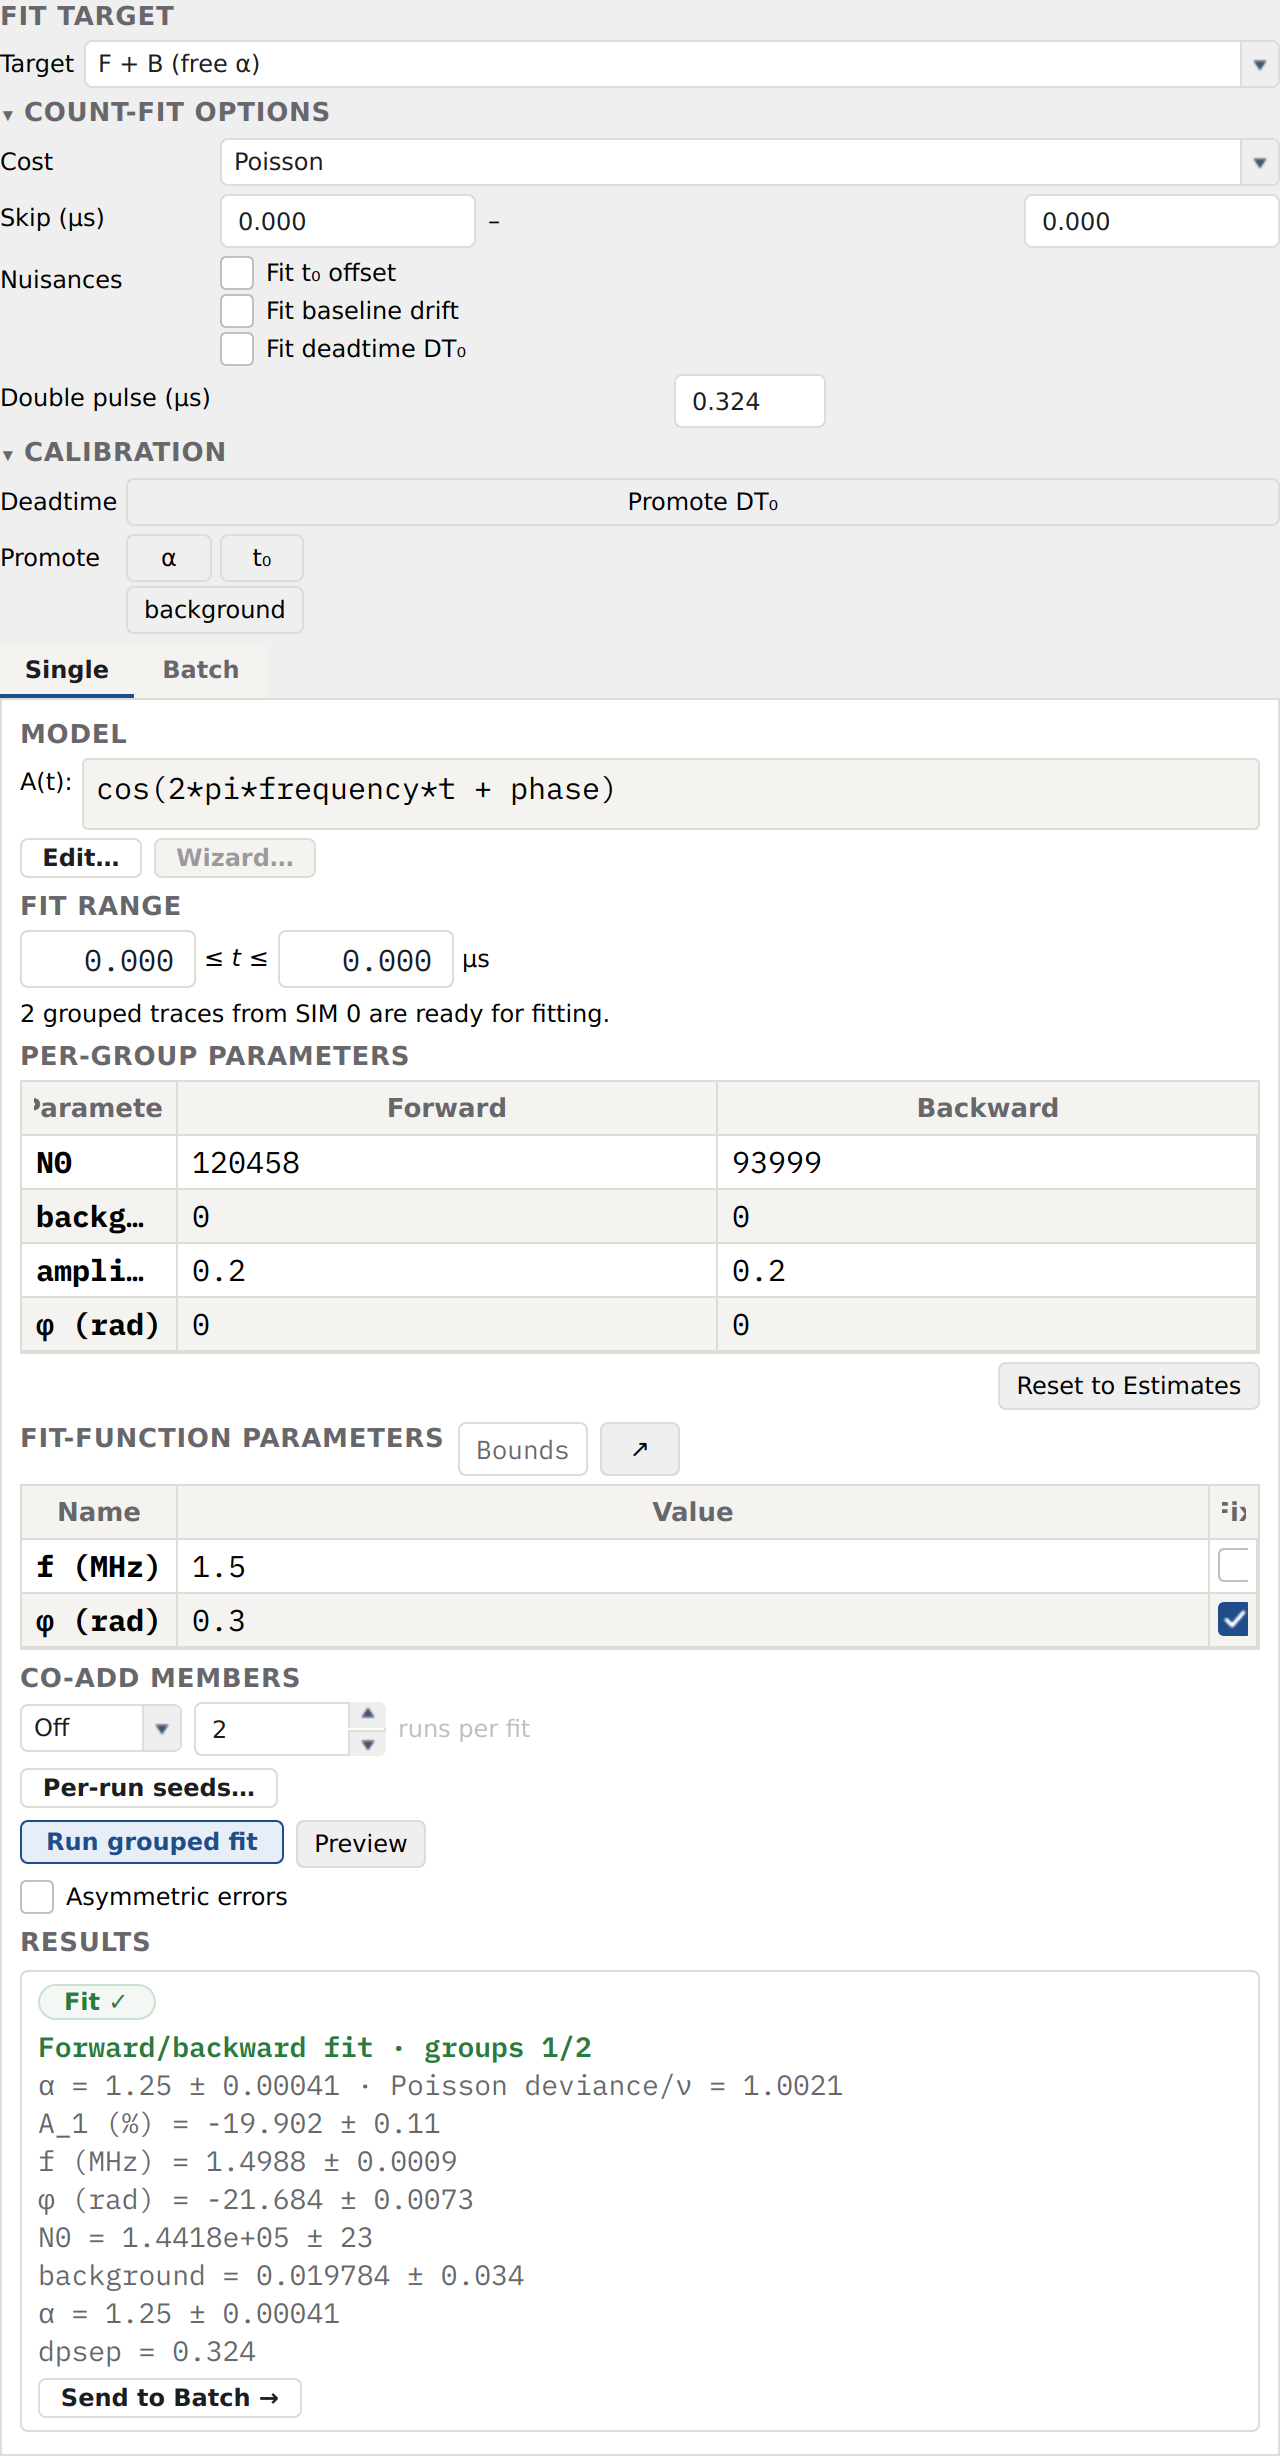
The Multi-Group Fit window in count-domain mode. The Fit target is “F + B (free α)”; the “Count-fit options” section (the Cost selector, the skip window, the nuisance toggles and the double-pulse field) and the “Calibration” section (the Promote α / t₀ / background / DT₀ actions) are expanded. A Poisson forward/backward fit of a transverse-field calibration run recovers the detector balance α = 1.250(1) at χ²ᵣ ≈ 1.
What these modes fit
Both modes fit raw counts. The count model is
where \(P(t)\) is the chosen fit function’s polarisation, \(A\) its
amplitude, \(\tau_\mu\) the fixed physical muon lifetime, and \(s\) a
sign that is +1 for a forward histogram and -1 for a backward one. The
muon lifetime is held fixed at the physical value.
For the free-α fit the forward and backward histograms share one normalisation split by the balance,
so that \(\alpha = N_{0,F}/N_{0,B}\). The shared amplitude \(A\), the physics parameters and α are fitted together; each side keeps its own background. Forward and backward here are the two detector groups designated in the Grouping dialog; sum multi-detector banks into those two groups upstream.
Raw-count preparation uses the requested groups, good-bin limits, bunching,
and fit masks. Every native bin contributing to a retained merged bin is
corrected before summation; incomplete terminal bunches and unconsumed excluded
bins add no dependency. Active background checks retain their estimator samples.
Fixed packing keeps the authored grouping factor, including when it exceeds
the selected window. Asymmetry also checks that the request leaves usable fit
bins after complete-group trimming, centre-based time limits, and exclusions.
A single/pair count request with none raises, for example,
Count-domain group 1 produced no usable bins; grouped fitting reports
Grouped time-domain fitting produced fewer than two usable groups.
This outcome precedes unused deadtime/background preflight. Reduce the factor
or widen the selected window to repair the request. Raw loading, inspection,
and saved settings remain available; no source observations are changed.
TF calibration uses this same fixed-packing boundary.
Explicit single-group fits remain available when that group is not included in a multi-group fit.
Missing or incomplete required File deadtime coefficients produce a warned skipped
outcome and leave the observations uncorrected by that operation. Count fits
continue under their existing count-source and background requirements;
the grouped count domain retains the requested and actual deadtime outcome.
A joint fit skips deadtime for its whole requested cohort.
When a residual DT₀ fit succeeds but unused File coefficients are unknown,
the fit remains usable and promotion is withheld. The result reports
“Deadtime promotion unavailable: coefficients are unknown for detector(s)
3, 4. Fit results remain usable.” (with the actual detector numbers).
Promotion is also withheld after a skipped File correction. The warning is
“Deadtime promotion unavailable: File deadtime correction was skipped because
required coefficients are unavailable. Fit results remain usable.”
An explicitly disabled correction retains its existing residual-fit calibration
behaviour. No unknown File value is replaced with zero to create a Manual table.
Invalid Manual settings, missing required exposure, and saturation remain
errors. See Detector Grouping and Layout for the shared correction contract.
Scripts can compare four TF calibration envelopes through the same count solver
using select_tf_calibration().
Undamped, exponential, Gaussian, and stretched candidates share one prepared
bank pair, correction/variance outcome, and fixed/free-beta intent. The usable
candidate with minimum summed objective is recommended, retaining all fits and
failures. This operation has no effect on this workspace’s controls; see
Alpha calibration for its constraints and conditional errors.
Choosing the cost
A Cost selector chooses how the counts are weighted:
Poisson (default) — the Cash statistic, the correct treatment for the low-count bins at late time and on continuous-source data, where the count distribution is visibly skewed and a Gaussian σ underweights the constraint.
Gaussian √N — ordinary least squares with σ = √N. Faster and adequate when every fitted bin has high counts; it matches the historical WiMDA weighting.
Poisson fits require finite, non-negative integer counts from the raw acquisition. Deadtime-corrected, lifetime-corrected, weighted, signed, and supplied-noise counts are ineligible, even when a final value happens to be an integer. Independent raw unit run sums retain the Poisson limit; see Run arithmetic: co-add and co-subtract. The error for corrected deadtime data is “Poisson likelihood needs raw counts; these counts were deadtime-corrected. Use the DT₀ count-domain model or the Gaussian cost.” Disable the reduction’s deadtime correction and fit DT₀ in the expected raw counts, or select Gaussian √N for corrected observations. That Gaussian cost uses \(\sigma=\sqrt{\max(v,1)}\), where \(v\) is the grouped and binned counting variance. For deadtime-corrected histograms this retains measured count variance, or explicitly supplied independent variance, rather than inferring it from corrected counts. For retained supplied/arithmetic variance, Gaussian fits use \(\sigma=\sqrt{v}\) without a floor, including \(v<1\); nonpositive or nonfinite errors receive the typed fit-input diagnostic. Lifetime correction scales σ and counts by the same factor. Coefficient and exposure uncertainty are excluded.
The Poisson statistic is the deviance \(D=2\sum_i[\mu_i-n_i+n_i\ln(n_i/\mu_i)]\), with the zero-count limit \(D_i=2\mu_i\), including exactly zero at \(n_i=\mu_i=0\) [baker_cousins]. It equals Cash’s statistic up to a data-only constant. Invalid trial expectations receive a restoring penalty; a reported optimum outside the Poisson domain fails and identifies the affected bins. Positive observations require positive expectations; zero observations permit zero. The result is labelled Poisson deviance/ν, including the detailed results window. A χ² quality verdict is shown only when every fitted expected count is at least five; sparse fits show the reason in the tooltip. This display threshold is an approximation, not a calibrated goodness-of-fit test. Fit ✓ reports convergence. See Assessing a Fit for the assumptions. Gaussian and Poisson fits approach agreement at high counts.
Seeding N₀, and the spurious minimum
The right N₀ is a per-run count level, not a number a script can guess. Seeded generically — 10⁴, say, against a run whose first-bin count is 10⁵ — the forward/backward fit does not fail: it converges, cleanly and with credible errors, on a spurious minimum at a tiny α with a compensating amplitude balance. Nothing in the fit result distinguishes that from a real detector balance.
So fit_fb_alpha() seeds N₀ from the
data by default. Omit the N0 parameter, or supply it with the value
SEED_FROM_DATA when you want to
state its bounds, and the seed becomes the forward window’s first positive bin
lifted back to \(t = 0\). An explicit positive value is used as given, and a
fixed N₀ is never overruled. The GUI has always seeded from the loaded run, so
this matters most for scripts driving the core API directly — for instance to
free the muon lifetime, which the β-calibration wrapper does not expose.
A converged fit is also checked against the counts, because that spurious
minimum is a genuine minimum: the fitted α must sit within a factor of three of
the window’s observed forward/backward count ratio, and the fitted forward scale
\(N_0\sqrt{\alpha}\) within two decades of the observed count level at
\(t = 0\). A violation reports success=False with a message naming the
discrepancy — and repeats it in each group result’s warnings — rather than
presenting the walk-off as a clean convergence. Neither check applies to a
parameter you fixed yourself.
Reading the result
The result panel reports the fitted parameters with uncertainties — for example a recovered balance of α = 1.250(1) — together with the per-degree statistic. For the free-α fit, the forward result carries the full covariance, so the α–amplitude correlation is available for inspection.
A successful fit also draws its model curve over the data in the Individual groups plot — the single-histogram fit over its one group, the free-α fit over both the forward and backward banks. The fit minimises a raw-count model, but the plot shows lifetime-corrected counts, so the overlay is scaled by exp(t/τ_μ) to land on the displayed data; a good fit traces the group exactly, and a poor one shows where it departs.
Window and nuisance flexibility
Three optional controls refine the fit window without splitting the run; each is off by default and, when off, leaves the fit numerically unchanged.
Skip window (μs) — drop an interior window of bins from the fit. Set the two fields so the upper bound exceeds the lower; the bins inside are removed (endpoints inclusive). Use it to reject a laser or RF artefact, a spike, or any localised corruption — the fitted parameters then match what the clean data alone would give, where leaving the artefact in pulls the amplitude. The label distinguishes this drop from the MaxEnt de-weight window of the same units (see Exclusions: a glossary of six mechanisms).
Fit t₀ offset — add a free time-zero offset that shifts the model time axis. Enable it when a small time-zero error is suspected; on clean data it recovers an offset consistent with zero and changes nothing else.
Fit baseline drift — add a stretched-exponential damping exp(−(λ_b·t)^β_b) on the polarisation (β_b held at 1, simple exponential, by default), for a slowly relaxing non-precessing baseline.
Note
WiMDA applies its baseline drift only to a dedicated constant-offset component; Asymmetry has no single privileged offset parameter, so the drift multiplies the whole polarisation. The term is off by default.
Free muon lifetime — the core API exposes an optional
tauparameter that frees the muon lifetime (musrfit-style), defaulting to the physical value τ_μ = 2.197 μs. Free it to fit the bare decay of a single histogram or as a detector-time diagnostic; with it fixed the fit is byte-identical to the standard fixed-lifetime fit. It is not combined with the double-pulse model.
Count loss and double pulse
Fit deadtime DT₀ — fit the non-paralysable mean count model [Knoll]:
\[M_i = \frac{N_i}{1 + aN_i}, \qquad a = \frac{\mathrm{DT}_0}{\Delta t\,F}.\]Here \(N_i\) and \(M_i\) are true and observed counts for detector \(i\), \(F\) is the good-frame count, and both DT₀ and the bin width \(\Delta t\) are in microseconds. The formula is the exact algebraic inverse of the Grouping dialog’s deadtime correction. Signed calibration coefficients are supported. Trial values with an undefined mean (\(1+aN_i\leq0\)) receive infinite cost; counts are never clipped. Good frames must be finite and positive whenever DT₀ is supplied.
Detectors in a group are assumed to share their time dependence: \(N_i=w_iN_G\), with \(\sum_iw_i=1\). Their means are summed individually. Shares are estimated from per-detector counts in the fit window, inverted at each trial DT₀. This accounts for unequal detector rates; a high-rate run is needed to determine DT₀. Bunching uses \(\Delta t_{\mathrm{eff}}=k\Delta t\) for \(k\) raw bins. Treating the rate as constant within a bunch is an approximation whose error is second order in its within-bunch variation. The count likelihood does not propagate uncertainty in the estimated shares or establish an acquisition variance model for deadtime losses.
Promote DT₀ adds the fitted increment to the table actually applied to the fitted counts. This composition is exact for the rational model: \(f_a(f_b(N))=f_{a+b}(N)\). The captured total table is independent of later edits to the live grouping. A forward/backward fit promotes both banks; a single-group fit adds its increment only to that group’s detectors. For example: “Group 1 detectors: DT₀ +0.0012 µs added to the applied correction. Re-reduce the run to apply.” The correction is enabled in Manual mode and records the
count_fitmethod and source run. Promotion writes the captured total, so repeating it does not add the increment a second time.A successful residual fit does not guarantee a transferable total table. Skipped File correction or unknown unused-detector coefficients leave the fit usable with a warning and no calibration to promote; unknown values are never treated as zero. Explicit
Offretains its supported zero-base residual calibration.When available,
FitResult.deadtime_calibrationholds the immutable total coefficients, errors in µs, method and source run. An error is unknown when a nonzero applied base has no recorded covariance with the residual fit; promotion does not invent a total uncertainty.Double pulse (µs) — supply a fixed separation; 0 selects the single-pulse count model. Equal incident double-delta pulses carry polarisation evaluated only at live ages t ± dpsep/2 ≥ 0, including age zero, with absolute muon survival. The clock origin is the midpoint of the two births on the resolved observation axis. Both single-histogram and F+B targets retain their established count objectives. F+B also supports detector beta, fixed or free, on the shared count path: beta scales only backward polarisation. Backgrounds occur once, and bins before either birth predict background only. This instantaneous-pulse approximation consumes no finite source width. Packed-bin expectations are evaluated at retained centres, with N0/background in counts per packed bin, without bin-edge integration. Onset-straddling bins can differ substantially from an integrated-rate model; no automatic onset or facility veto is applied.
Separation estimation is unsupported. After both arrivals, a single TF line can absorb a different separation into amplitude, phase, and count scale; a sharp-gate simulator round trip does not establish separation recovery or finite-width onset-bin accuracy. Supply an independently established value. Errors are conditional on that fixed input.
Asymmetry also checks that API
dpsepparameters are fixed without following links or constraints, nonnegative, and finite, returning actionable input guidance before minimisation. A free parameter is never silently fixed. Recorded results remain history.
Compared with other programs
WiMDA 1.326 provides a supplied Double Pulse setting. In Mantid,
DoublePulseFit v1
uses supplied PulseOffset and pulse weights. These are configured source
inputs, rather than evidence for free-separation estimation. Asymmetry uses
fixed equal incident strengths with survival weighting. The comparison does
not claim a fresh native WiMDA or full Mantid fit. musrfit 1.12.1 can represent
an explicit two-component post-arrival TF signal; that is not a verified
built-in pulse-response feature.
Promoting α, t₀ and the background
The deadtime promote above is one of a family: the same suggest-only Send-to-Group pattern promotes the other fitted calibrations into the grouping, each reporting before/after and a Re-reduce the run to apply message. Like deadtime, α and t₀ are per-sample, per-setup calibrations — α “needs to be determined for each sample”, and the analysis time-zero “is the beginning of the spin dynamics” — so a value fitted from the run’s own counts is a legitimate calibration to persist.
Promote α writes the free-α forward/backward balance into the grouping with
alpha_method="count_fit"provenance. This is the statistically best of the four α routes — see Alpha calibration. Available after a Forward + Backward (free α) fit.Promote t₀ converts the fitted continuous time-zero offset (μs) to the nearest integer
t0_binvia the bin width and discloses the sub-bin residual the integer index cannot represent. The model evaluatest_eval = time + t0, so a positive fitted t₀ means the data’s stamps run early against the physics — the stored zero was too late — and the promotion moves it earlier:new_bin = current − round(t0 / w). The good window moves with it (first_good_binand any resolved per-detector offset shift by the same applied delta), so the offset from t0 is preserved. The fitted t₀ is per group butt0_binis a single run-level index, so the promote applies the fitted group’s value run-wide and says so. Available after a fit with Fit t₀ offset enabled.Promote background writes the fitted flat count background into the grouping’s fixed background mode as a
[forward, backward]pair. Because the count fit reads raw counts, this background term measures the full flat rate — if the grouping already corrects the background, the fit still sees it, so do not fix the fit’s background to zero (the panel notes this when a grouping background correction is active).
Worked example — α from a TF calibration run
Load the calibration run and open its Grouping dialog; confirm the forward and backward groups.
Open the Multi-Group Fit window and choose a transverse-field model (an oscillation with a free amplitude and frequency) in the model builder.
Set Fit target to Forward + Backward (free α) and leave Cost at Poisson.
Fit. The recovered α is the calibration balance; cross-check it against the Grouping dialog’s diamagnetic / general / ΣF/ΣB estimators — they should agree to a few percent, with differences explained by the estimators flattening an asymmetry window while the fit weights the whole count trace.
References
S. J. Blundell, R. De Renzi, T. Lancaster, and F. L. Pratt, Muon Spectroscopy: An Introduction (Oxford University Press, Oxford, 2022) — the count equation N(t) = N₀·e^(−t/τ)(1 + A·P(t)) + B, the detector-balance parameter α, and the Poisson nature of detector counts.
A. Suter and B. M. Wojek, Phys. Procedia 30, 69 (2012) — musrfit, the single-histogram (fittype 0) count fit and its cost options.
G. F. Knoll, Radiation Detection and Measurement, 4th ed. (Wiley, 2010), Chapter 4, “Dead Time”.
Compared with other programs
Asymmetry uses required observations for grouped count preparation, preserving measured or supplied count variance with fixed coefficients and exposure. WiMDA traverses requested group/bin observations; the compared musrfit 1.12.1 path visits the selected histograms’ raw arrays. Mantid 6.16.1 standard muon preprocessing corrects before cropping. These are preparation conventions, not agreement claims about each program’s count-fit objective. See Required F/B deadtime observations and Detector Grouping and Layout.
The per-detector rational mean used by dedicated Estimate/Cal is algebraically equivalent to the published ISIS regression \(M\exp(t/\tau_\mu)=N_0-N_0Md/(\Delta t F)\) (Kilcoyne, RAL-94-080, §4). It fits the rational mean to raw counts with plug-in standard deviations \(\sqrt{\max(M_\mathrm{observed},1)}\), using a one-count floor; it does not fit the transformed correlated observables. This algebraic identity does not equate the estimators or their errors. Estimate averages fitted detector coefficients, rather than fitting a pooled spectrum. The dedicated calibration fixes the lifetime and has no background or polarisation term; a count-domain fit instead uses its configured physical model, objective, and fit window. A residual DT₀, its rational mean, and a complete transferable calibration are distinct quantities. See Detector Grouping and Layout for dedicated source/window and conditional-error assumptions, and Deadtime calibration methods for reference differences.
A recorded Mantid 6.16.1 CalMuonDeadTime v1 binary check used noiseless
coefficients −0.02, 0 and +0.02 µs, \(N_0=10000\) counts/bin, lifetime
2.1969811 µs, one million frames, 0.016 µs bins with edges
\(0.496+k\times0.016\) µs (\(k=0,\ldots,282\)), and fit range
0.5–5 µs. Mantid recovered each coefficient within \(2\times10^{-12}\) µs;
Asymmetry agrees within \(10^{-9}\) µs. The weighting conventions differ
for noisy data, so this check establishes agreement on the noiseless mean,
not statistical equivalence of the estimators. See
Detector Grouping and Layout for the primary ISIS report and
Asymmetry in the μSR software landscape for the bounds of the program comparisons.
The core F/B result also exposes joint_fit: one complete parameter and
covariance solution, including both backgrounds. Bank results remain projections
for plotting and existing consumers. Use the joint statistic/dof for a joint
fit-quality diagnostic; summing bank degrees of freedom counts shared parameters
twice. F/B fits explicitly evaluate HESSE before optional MINOS. The fixed/free
beta TF calibration API is described in Alpha calibration
and TF calibration.
S. Baker and R. D. Cousins, Nuclear Instruments and Methods 221, 437–442 (1984), doi:10.1016/0167-5087(84)90016-4.