Synthetic runs and degraded statistics
Asymmetry generates ideal per-detector Poisson count histograms with grouping and provenance, and can write them as loadable NeXus files. Statistics degradation below one instead uses binomial thinning of recorded counts. Supported synthetic runs use the standard grouping, balance, binning, and fitting operations; this shared processing does not reproduce every acquisition mechanism or uncertainty. The Conditional simulation: the pull distribution states the conditions and omissions of repeated refits.
Generate a synthetic run
When to use this. Three situations call for synthetic data. Fit validation: before trusting a fit on real data, check that the analysis recovers known parameters — simulate from the fitted model, refit, and compare. Teaching: produce realistic datasets for any relaxation or oscillation function without beam time. Method development: manufacture test inputs with controlled statistics for binning, Fourier or fitting studies. It is not a substitute for calibration measurements — α, t0 and backgrounds in a synthetic run are inputs, not measurements.
Open File → Generate Synthetic Run… with at least one run loaded. The loaded run acts as the instrument template: the synthetic run copies its detector count, time binning, per-detector t0, good-bin window, detector grouping and α. The dialog seeds its model and parameter values from the template run’s current fit when one exists; otherwise pick any time-domain model with Edit Model… (the same builder used by the fit panel).
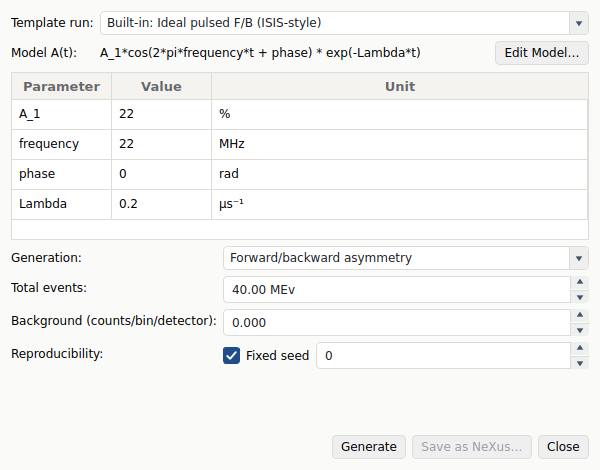
The Generate Synthetic Run dialog opened with no run loaded, so the Template run list falls back to the two idealised instruments — here Built-in: Ideal pulsed F/B (ISIS-style) . The Model A(t) is a damped Larmor precession (an Oscillatory × Exponential composite) at ν ≈ 22 MHz, a below-Tc EuO signal from the archetype gallery, with its parameter table populated in percent. The Total events budget pre-fills from the chosen instrument, the Generation mode is Forward/backward asymmetry, and Fixed seed keeps the draw regenerable.
Each detector in the forward group accumulates expected counts
with the backward group seeing \(1 - a(t)\), where \(a(t)\) is the chosen model (the dialog works in percent, matching the fit panel), \(\tau_\mu = 2.1969811\) μs (PDG 2024; see Physical constants), and \(b\) is an optional flat background per bin. The α balance enters as the relative efficiency of the two groups — forward detectors are weighted by \(2\alpha/(1+\alpha)\) and backward by \(2/(1+\alpha)\) — so the reduction \((F - \alpha B)/(F + \alpha B)\) recovers \(a(t)\) with the template’s α restored. The recorded counts are independent Poisson draws of these expectations; bins before t0 contain only the background. Total events sets the expected event budget over the histogram window (the realised total fluctuates, as it would on the beamline), and defaults to the template run’s own statistics so the synthetic noise level matches the data you are used to looking at.
The result appears in the Data Browser as SIM 90001 (and counting),
tinted and carrying a tooltip with its provenance: the generating model,
parameter values, seed, event budget and template run. The run’s metadata
records the same information permanently. Save as NeXus… writes the run
as a standard ISIS muon NeXus file with explicit temperature, field, and
timing units that reloads through Open Data
File(s)… with identical counts — this is also how a synthetic run persists
across sessions, since project files reference data files rather than
storing histograms. A synthetic run that has not been saved this way is held
in memory only; saving a project that still references one raises a warning,
because the project will not be able to reload it.
The same template, model, parameters, events, seed, and numerical environment reproduce the count draw; cross-version or cross-platform bitwise identity is not guaranteed. Leave Fixed seed checked when you want a regenerable dataset (the seed is recorded in the provenance either way); untick it to draw a fresh seed per generation.
Two caveats worth knowing. The ISIS NeXus format has no field for α, so a
reloaded synthetic file starts from the loader’s default balance, exactly
as real data would — the generating α is recorded in the file’s
simulation group for reference. And the synthetic counts contain no
deadtime distortion, so the file’s deadtimes are correctly written as zero;
do not enable deadtime correction for synthetic runs.
Generation modes: asymmetry, counts, and periods
When to use this. The Generation dropdown chooses what kind of synthetic run to make. Leave it on the default for asymmetry work; switch it when you need raw single-histogram counts for a count-domain fit, or a red/green period structure.
Forward/backward asymmetry (default) is the run described above: the antisymmetric \(\pm a(t)\) split across the forward and backward groups, reduced to an asymmetry curve. This is what feeds the standard fit panel and the α-free forward/backward count fit, which needs the F/B pair to separate the balance \(\alpha\) from the amplitude.
Count histograms (single-group) imprints the same \(+a(t)\) on every group, so each detector group is an independent single-histogram measurement
with no balancing backward detector. This is the data the single-histogram count fit expects — fit any one group and recover its \(N_0\), the amplitude inside \(a(t)\), and the flat background. Use it for longitudinal-field / zero-field (LF/ZF) single-detector work, or to manufacture a clean test case for the count-domain fit modes.
Two-period (red/green) generates two period histograms in one run, the way a light-on/off or RF-on/off measurement is recorded. Red carries the full model; the Green amplitude (×) factor scales green’s signal — leave it at \(0\) for a flat reference period (the usual light-off case), so the green-minus-red combination \(G - R\) recovers the red signal cleanly. Each period is an independent Poisson draw from one seed. The run lands in the Data Browser with the full red/green machinery: pick the period or the \(G \mp R\) combination in the grouping dialog exactly as for a loaded period-mode file. Save-as-NeXus flattens a two-period run to its red period — period-mode synthetic runs live in memory and through the project, not on disk.
Built-in instrument templates
When to use this. Teaching and quick experiments with no data to hand. The dialog opens without a loaded run and offers two idealised instruments that supply the geometry a real template would, so you can go straight from a model to a synthetic run.
The two F/B built-ins are the contrasting source archetypes of the field. The ideal pulsed F/B mirrors an ISIS-style spectrometer — 32 forward and 32 backward detectors, 16 ns bins over a 32 μs window, and no uncorrelated background, since a pulsed source has essentially none. The ideal continuous F/B is a PSI-style pair with fine 1 ns binning over a short 10 μs window and a flat background of about 10 counts/bin/detector: the time-independent uncorrelated background that characterises a continuous source, where muons arrive one at a time and the time-zero clock runs free. Select either from the Template run list; the event budget and background spinners pre-fill with values for the chosen idealised template. Generation, NeXus transport, and refitting use the same supported operations as a loaded-run template, under the stated ideal-count assumptions.
A third built-in, the ideal continuous octant ring
("ideal_continuous_ring8"), supplies the geometry for a PSI HAL-9500-style
high-transverse-field ring instead of a plain F/B pair: 8 detector groups (one
detector each) at 45° azimuthal spacing, the same fine 1 ns binning and flat
background as the continuous F/B template. Each group’s azimuth (0° at 90°/top,
numbering clockwise) is recorded on the template’s grouping and carried
through to every synthetic run built from it — see group_azimuths_deg()
and Arbitrary per-group signals below. The default forward/backward pair
(group 1 vs. its 180°-opposite group 5) makes the plain Generate Synthetic
Run… dialog work on it too, exactly like a loaded run; the ring’s own value
is the per-group azimuths a multi-group or arbitrary-signal simulation needs.
Any built-in template’s binning can be resized from a script with
build_builtin_template()’s n_bins/bin_width_us/t0_bin
keywords, without hand-building a new InstrumentTemplate.
The archetype gallery
When to use this. A one-click route to a physically realistic dataset for a named material, for teaching or for a sanity check that the analysis chain reproduces textbook behaviour. File → Simulate Preset lists each archetype; choosing one generates a badged synthetic run (or a whole scan) from a fixed seed, so the same preset always yields the same data.
The presets and the physics they carry:
Ag — ZF Gaussian Kubo–Toyabe. The canonical static nuclear-dipolar reference, \(\Delta = 0.39\) μs-1.
Ag — LF decoupling series. The same Kubo–Toyabe in longitudinal fields of 0, 10, 25 and 50 G, the textbook test that the dipolar fields are static.
EuO — ferromagnet through Tc. A zero-field temperature scan across \(T_c = 69\) K: below it the muon precesses at a frequency that tracks the magnetic order parameter \((1 - T/T_c)^\beta\); above it the signal is paramagnetic relaxation that broadens through the critical region.
PbF₂ — F-μ-F entanglement. The dipolar beat pattern of a muon bound between two fluorine neighbours at \(r \approx 1.17\) Å.
YBCO — transverse-field precession. Knight-shifted Larmor precession in a 200 G transverse field.
Because each preset is a real synthetic run, you can refit it and recover the input physics. Fitting the Ag preset, for instance, returns \(\Delta = 0.389(1)\) μs-1, and the F-μ-F preset returns \(r_{\mu\mathrm{F}} = 1.170(1)\) Å — the generating values, within the counting errors. The parameter values follow Blundell et al. (see the references); the preset tooltips name the relevant chapter.
Multi-group simulation
When to use this. Synthesising a transverse-field ring whose detector groups see the same precession at different phases — for instance to manufacture test data for the multi-group time-domain fit, or to show how the relative phase around a ring maps onto the geometry. File → Generate Multi-Group Run… opens a per-group table of amplitude, relative phase and relative count rate, over a shared normalised polarisation model.
The forward/backward dialog applies one signal with the α split; here each group \(g\) instead carries
the shared polarisation \(P(t)\) scaled by the group’s own amplitude \(A_g\) and shifted by its own phase \(\phi_g\). The amplitude owns the overall scale and the count-rate weight owns the background, so the shared model is a unit-amplitude, zero-baseline polarisation — exactly the contract the grouped time-domain fit expects. If you have just run a grouped fit on the selected run, the table is seeded from that fit’s per-group amplitudes and phases, so “simulate what I just fitted” is one click. The reduction recovers each group’s seeded signal bin-for-bin in expectation.
Arbitrary per-group signals
When to use this. The forward/backward and multi-group tools above both
drive their signal from a registered fit model. Some signals do not come
from one — a forward model computed elsewhere, a numerical lookup table, a
measured trace being replayed as a synthetic instrument test — and PSI
HAL-9500-style high-transverse-field data in particular needs an independent,
non-analytic polarization per octant. asymmetry.core.simulate.simulate_signal_run()
is the scriptable entry point for that case; it has no dialog, since a
caller-supplied signal is by definition not something a GUI form can capture.
Each entry of signals assigns one detector group a callable
\(a(t)\) (time in μs, fractional units) or an array pre-sampled exactly
on that group’s post-t0 bin grid — no implicit padding or truncation, unlike
the lower-level simulate_run_from_group_signals()
it shares its Poisson-sampling machinery with. Groups with no entry get the
bare lifetime envelope. The same forward model applies,
with an optional per-group count-rate weight (group_weights) and an
optional per-group background (background_per_bin as a
group_id -> counts/bin mapping, or one flat rate for every group). A
signal may be negative and exceed \(|a| > 1\) — a transverse-field ring
routinely has both — but if it would drive the expected count negative for
some detector and bin, generation fails loudly with a
ValueError naming the group, detector and time, rather than silently
flooring the count at the background level the way the model-driven tools do.
The result is an ordinary synthetic Run:
it reduces through reduce_run_to_dataset() and
degrades through degrade_run() exactly like
every other synthetic run, and a ring template’s per-group azimuths
(group_azimuths_deg()) survive both unchanged —
they are ordinary grouping metadata, not something the signal path has to
know about.
Degrade statistics
When to use this. Answering “would half the beam time have been enough?” — for planning proposals, for checking that a marginal feature survives at realistic statistics, or for testing how a fit degrades as counts shrink. Because the thinned run is a new entry beside the original, a single measurement yields a whole family of statistics levels.
Right-click a run in the Data Browser and choose Degrade Statistics…. A factor \(f < 1\) keeps each recorded count independently with probability \(f\) — binomial thinning. For independent Poisson source counts with fixed rates, the unconditional thinned counts are Poisson at the reduced exposure. Conditional on the observed source, the draw is binomial; its replicas are not independent new acquisitions and do not reproduce omitted physical effects. Relative errors scale approximately as \(1/\sqrt{f}\) in the informative count limit. The derived run appears beside the source (which is never modified), badged with its factor, seed and parent run, and can be saved as NeXus like any synthetic run.
A factor \(f > 1\) is also accepted but is an extrapolation, not a simulation: drawing \(\mathrm{Poisson}(f k)\) from the recorded \(k\) inflates the variance by roughly \(1 + f\) relative to a genuinely longer measurement. Use it for qualitative “more statistics” sketches only — never for quantitative sensitivity claims.
Conditional simulation: the pull distribution
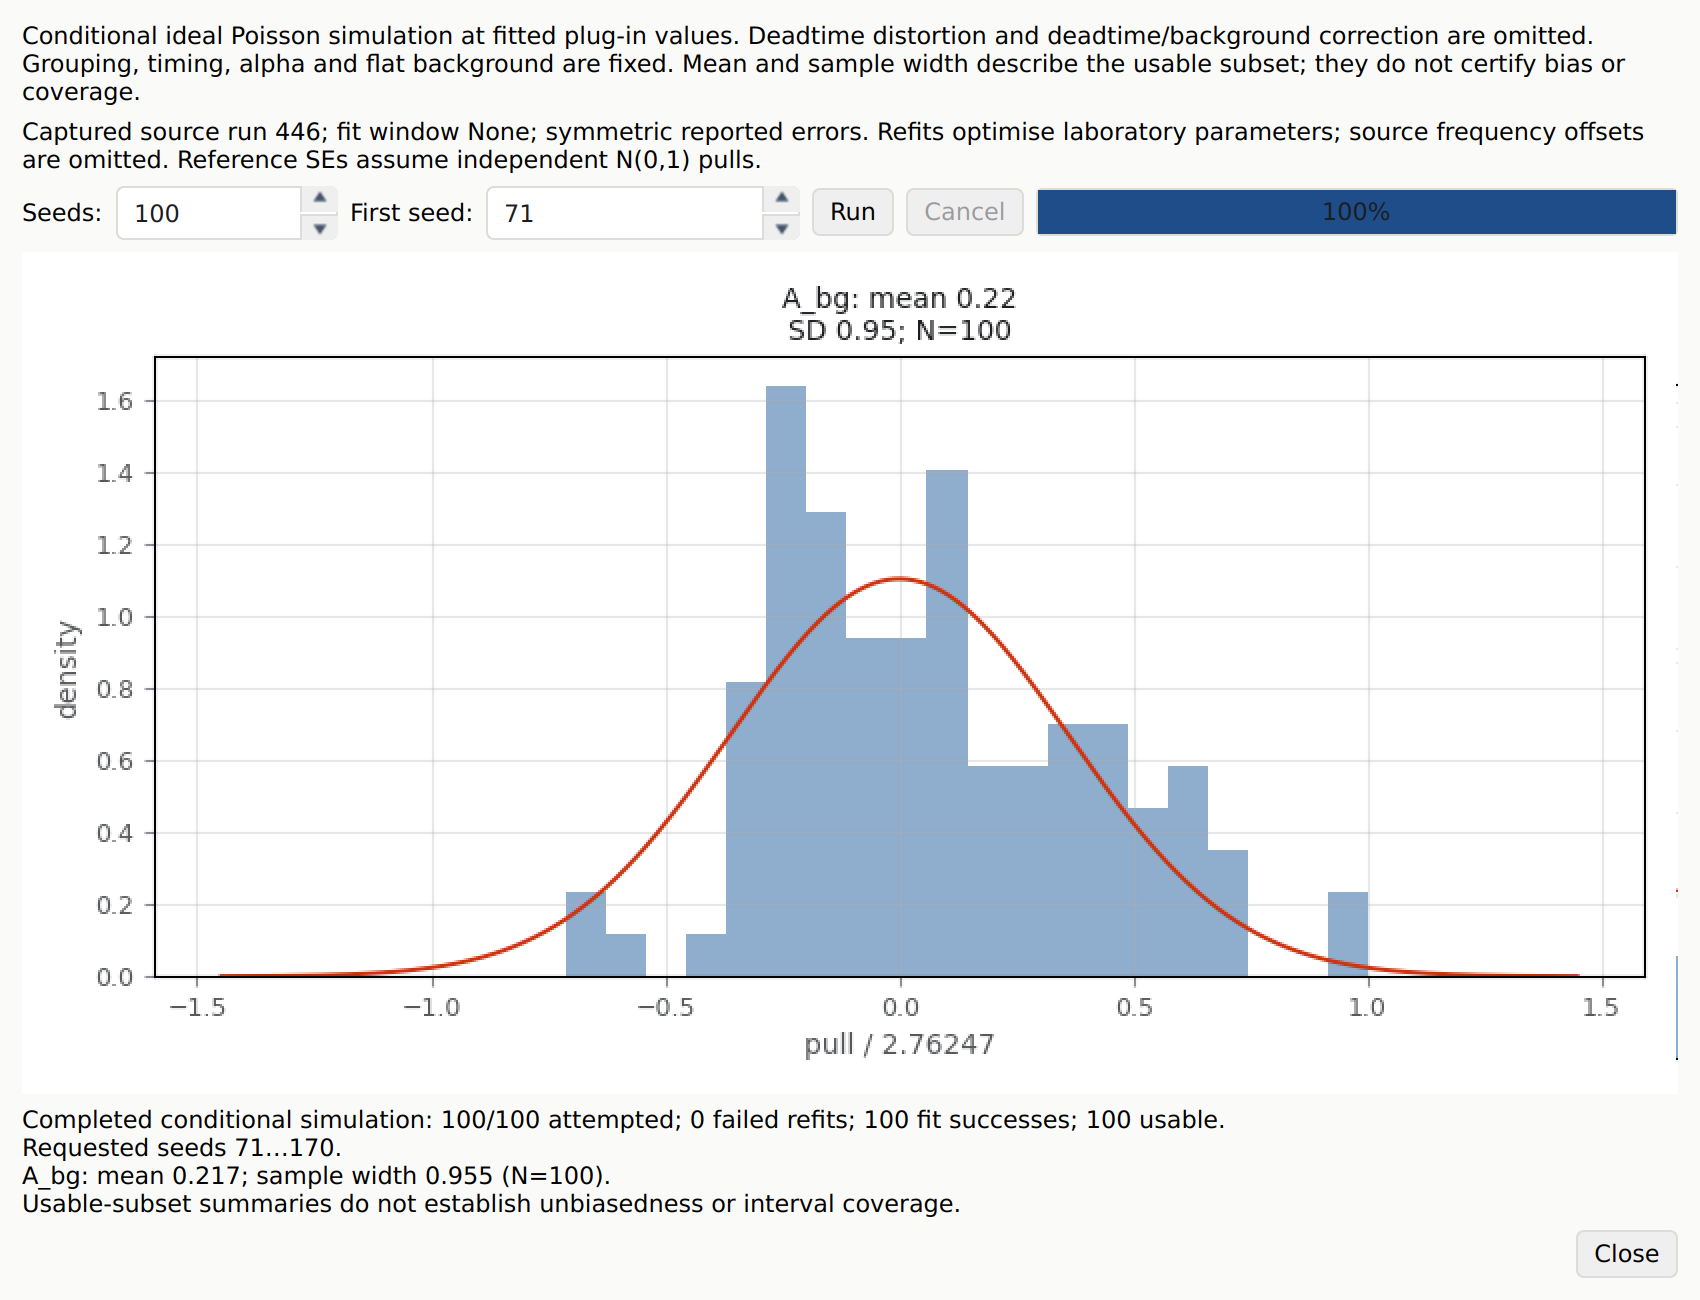
After a converged Single-tab fit, Diagnostic… opens Pull Distribution Diagnostic, bound to that completed execution. The fitted parameters are plug-in generating values for a supported ideal experiment. They are not known physical truth for the acquisition. Choose Seeds: and First seed:, then Run. Cancel requests a cooperative stop; an interrupted seed and earlier attempts remain an explicitly partial result. Generating-model validation, generation, and individual array operations are indivisible; cancellation is also polled during supported numerical refits, without a fixed response-time guarantee. Closing discards late delivery. The source fit, project history, and grouping remain intact.
The experiment draws independent Poisson detector counts from the simulator’s single-source lifetime model. Event budget and flat background are fixed plug-in conditions estimated from the captured selected detector pair after exclusions and resolved integer source origins. Background counts are added to the signal budget. Deadtime distortion is absent and detector deadtimes are zero; deadtime and background correction are off in synthetic reduction. Source corrections remain source context, distinct from the recorded synthetic recipe. A nonzero generated flat background can therefore change the mean asymmetry; this is a simpler experiment, not replay of background-subtracted observations. Timing, alpha, detector membership/exclusions, and calibration are fixed.
Captured count packing, centre-selected fit support, model, bounds, fixed/tied parameters, Gaussian objective, and optional MINOS are reused through the ordinary fitting engine. Replicas start at the fitted plug-in values; original execution starts and parameter history remain source context. Source frequency offsets are recorded; synthetic refits optimise laboratory parameters, omitting that numerical conditioning reparameterisation. Frequencies and generating values remain in the laboratory frame; amplitudes and symmetric errors use percent. FFT error oversampling is recorded with the captured options, but transformed/FFT observations have no matching generator in this diagnostic. No uncertain response, calibration draws, deadtime acquisition process, general cross-bin covariance, or model-selection uncertainty is added.
Asymmetry also checks representability at this diagnostic boundary. Fixed-only fits have no free-parameter diagnostic. Frequency-offset expressions or equality links with unequal offsets cannot be translated here and are unavailable. Non-unit beta, combined period/run observations, fractional source-clock residuals, and models outside finite ±100 percent on generated support are unavailable here. Positive ordinary pulse separation retains its explicit refusal: a matched normalised mean does not provide the required two-birth count generator. Ordinary fitting and file loading remain available. Captured integer detector origins and exclusions are resolved through the standard grouping owner; native detector support is retained.
For each tracked free parameter the pull is
Here \(s_{\hat\theta}\) is the engine’s symmetric parabolic error, without residual scaling. Optional MINOS signed endpoints are recorded separately and never substituted into this denominator. A usable attempt requires a successful refit and every tracked value, positive finite symmetric error, and computed pull to be finite, including subtraction/division overflow. Missing results, unsuccessful fits, missing values/errors, unavailable or invalid uncertainty, nonfinite values/pulls, and cancellation have explicit reasons. All parameters use the same usable subset. Coding errors surface as diagnostic errors.
Attempted, failed-refit, fit-success, and usable counts appear beside the histograms. Histograms include tails and normalise over all usable pulls. The mean is a mean standardised residual; the sample width is a sample standard deviation. Neither establishes estimator unbiasedness, and width near one alone is not interval coverage. Constraints, skewness, variable uncertainties, failure selection, or a misspecified generating experiment can change both summaries. Two usable observations permit a sample SD, without scientific certification. The reference standard errors \(1/\sqrt{N}\) and \(1/\sqrt{2(N-1)}\) assume independent standard-normal pulls; they are not calibrated sampling uncertainties for arbitrary pull samples [pdg-pulls].
Reduction uses first-order ratio propagation, not an exact ratio variance. For independent Poisson F/B counts and fixed alpha with beta one, the fractional variance approximation is
The familiar \((1-A^2)/(F+B)\) limit holds at alpha one. Percent errors multiply by 100 (variances by 10000). The authoritative general-alpha/beta and shared-error treatment includes represented background/shared terms and its conditional limitations; see also [gum-pulls].
The core exposes make_pull_request(),
run_pull_request(), and strict
JSON-compatible request/result to_dict/from_dict methods. Records retain
requested/attempted/usable seeds, runtime/RNG identity, outcomes, fitted plug-in
truth, constraints/options, source context, and actual synthetic recipes. Actual per-refit selected/omitted observations and fitter attribution are retained.
Common recipes are stored once; any seed-dependent recipe differences retain their
own references. Replay supplies the same model/refit callable and environment.
Supported EngineRefit settings can be reconstructed from their configuration;
opaque callable settings remain unknown. No executable functions are serialised,
no universal cross-version bitwise replay is promised, and loading records never
simulates or refits. Diagnostics are not automatically added to project history.
Compared with other programs
WiMDA’s documented generate test data workflow selects a fitting function, sets event statistics, and permits refitting and recording errors. The checked WiMDA 1.326 environment does not establish an identical automated seeded pull workflow; the public manual describes the closest operation [wimda-pulls]. Mantid 6.16.1 Fit and musrfit 1.12.1 Gaussian fitting provide independent supplied-error controls, rather than equivalent pull products. The recorded three-point constant control retains all selected observations, absolute supplied errors, native statuses, objective conversion, and precision/tolerances. Value/error agreement is separate from rounded objective precision. These checks do not validate acquisition physics, fit-selection coverage, or arbitrary likelihood conventions.
Scripting
The same machinery is available without the GUI, in
asymmetry.core.simulate:
from asymmetry.core.io import load
from asymmetry.core.io.nexus_writer import write_nexus_v1
from asymmetry.core.simulate import degrade_run, reduce_run_to_dataset, simulate_run
from asymmetry.core.fitting.composite import CompositeModel

template = load("EMU00020722.nxs").run

model = CompositeModel.from_expression("Oscillatory * Exponential")
params = dict(model.param_defaults) | {"frequency": 1.35, "Lambda": 0.21}

run = simulate_run(template, model, params, total_events=40e6, seed=7)
dataset = reduce_run_to_dataset(run)      # browser-ready asymmetry curve
write_nexus_v1(run, "SIM90001.nxs")       # loadable through load()

half = degrade_run(run, 0.5, seed=1)      # "half the beam time"
No run to hand? Build one of the idealised instruments instead of loading a file:
from asymmetry.core.simulate import build_builtin_template, simulate_run

template = build_builtin_template("ideal_pulsed_fb")   # or "ideal_continuous_fb"
run = simulate_run(template, model, params, total_events=40e6, seed=7)
The textbook archetypes are one call each, returning the run (or the whole scan family), badged and ready to plot or fit:
from asymmetry.core.simulate_presets import build_preset_runs

ag = build_preset_runs("ag_zf_kt")[0]          # single run
euo_scan = build_preset_runs("euo_tscan")      # five temperatures
Count-mode and two-period synthesis have their own entry points. Count-mode
returns a run whose per-group histograms feed the single-histogram count fit;
two-period takes a PeriodSpec for red and
green and returns the loadable red/green payload.
from asymmetry.core.simulate import (
    PeriodSpec, simulate_count_run, simulate_two_period_run,
)

counts = simulate_count_run(template, model, params, total_events=40e6, seed=7)

# Red carries the full model; green a half-amplitude variant (scale=0 makes
# a flat reference period, so G−R recovers the red signal). Each period can
# instead pass its own model/parameters/alpha/total_events.
red = PeriodSpec(model, params)
green = PeriodSpec(model, params, scale=0.5)
periods = simulate_two_period_run(
    template, [red, green], total_events=40e6, seed=7,
)
Multi-group simulations (a different amplitude and phase per detector group —
phases around a transverse-field (TF) ring, for instance) use
asymmetry.core.simulate.simulate_multi_group_run() with a
GroupSignalSpec per group; the
forward/backward dialog exposes only the single-signal α-split case.
from asymmetry.core.simulate import GroupSignalSpec, simulate_multi_group_run

ring = CompositeModel(["Oscillatory"])        # normalised polarisation
specs = [GroupSignalSpec(g, amplitude=0.2, relative_phase=phi)
         for g, phi in [(1, 0.0), (2, 1.57), (3, 3.14), (4, 4.71)]]
run = simulate_multi_group_run(template, ring, specs,
                               total_events=40e6,
                               base_parameters={"frequency": 2.7})
An arbitrary, caller-supplied signal — not drawn from the fit-model registry —
uses asymmetry.core.simulate.simulate_signal_run() directly, one
callable or array per group. Building it on the "ideal_continuous_ring8"
built-in gives a PSI HAL-9500-style ring with no run to hand, and
group_azimuths_deg() reads back each group’s
azimuth for a signal that itself depends on the detector’s angle:
import numpy as np

from asymmetry.core.simulate import (
    build_builtin_template, group_azimuths_deg, simulate_signal_run,
)

ring = build_builtin_template("ideal_continuous_ring8")  # 8 groups, 45 deg apart
azimuths = group_azimuths_deg(ring)                      # {1: 90.0, 2: 45.0, ...}

def signal_at(phase_rad):
    return lambda t: 0.2 * np.cos(2 * np.pi * 5.0 * t + phase_rad)

signals = {gid: signal_at(np.deg2rad(az)) for gid, az in azimuths.items()}
run = simulate_signal_run(ring, signals, total_events=40e6, seed=7)
The engine-agnostic asymmetry.core.pull_diagnostic.run_pull_distribution()
validates and runs a conditional simulation request. Supply a refit callable
refit(dataset, cancelled) returning RefitOutcome (or None for an
unavailable result). Propagate unexpected errors and cooperative cancellation;
reported numerical failure is distinct from an unusable symmetric uncertainty.
Use the descriptive summaries and retained attempt records with the limitations
above.
References
S. J. Blundell, R. De Renzi, T. Lancaster, and F. L. Pratt, Muon Spectroscopy: An Introduction (Oxford University Press, Oxford, 2022), Chs. 14–15.
F. L. Pratt, Physica B 289–290, 710 (2000) — WiMDA, whose Simulate and Degrade Statistics tools this feature parallels.
G. Cowan and L. Lista, Particle Data Group, Statistics (2025), Secs. 40.2 and 40.4, PDG review.
Joint Committee for Guides in Metrology, Evaluation of measurement data — Guide to the expression of uncertainty in measurement, JCGM 100:2008, Secs. 5.1–5.2, doi:10.59161/JCGM100-2008E.
WiMDA, User manual, Sec. 3.7, manual and overview.