GUI usage
This chapter is the comprehensive reference for the Asymmetry GUI — menus, panels, dialogs, keyboard shortcuts. New users coming from a real experiment should normally read Analysis workflows first and dip into this chapter as a lookup when the case studies reference a specific dialog; the section headings below are organised for that kind of targeted navigation rather than for cover-to-cover reading.
Launching the GUI
From the command line:
asymmetry-gui
Or from Python:
from asymmetry.gui.app import main
main()
Main window layout
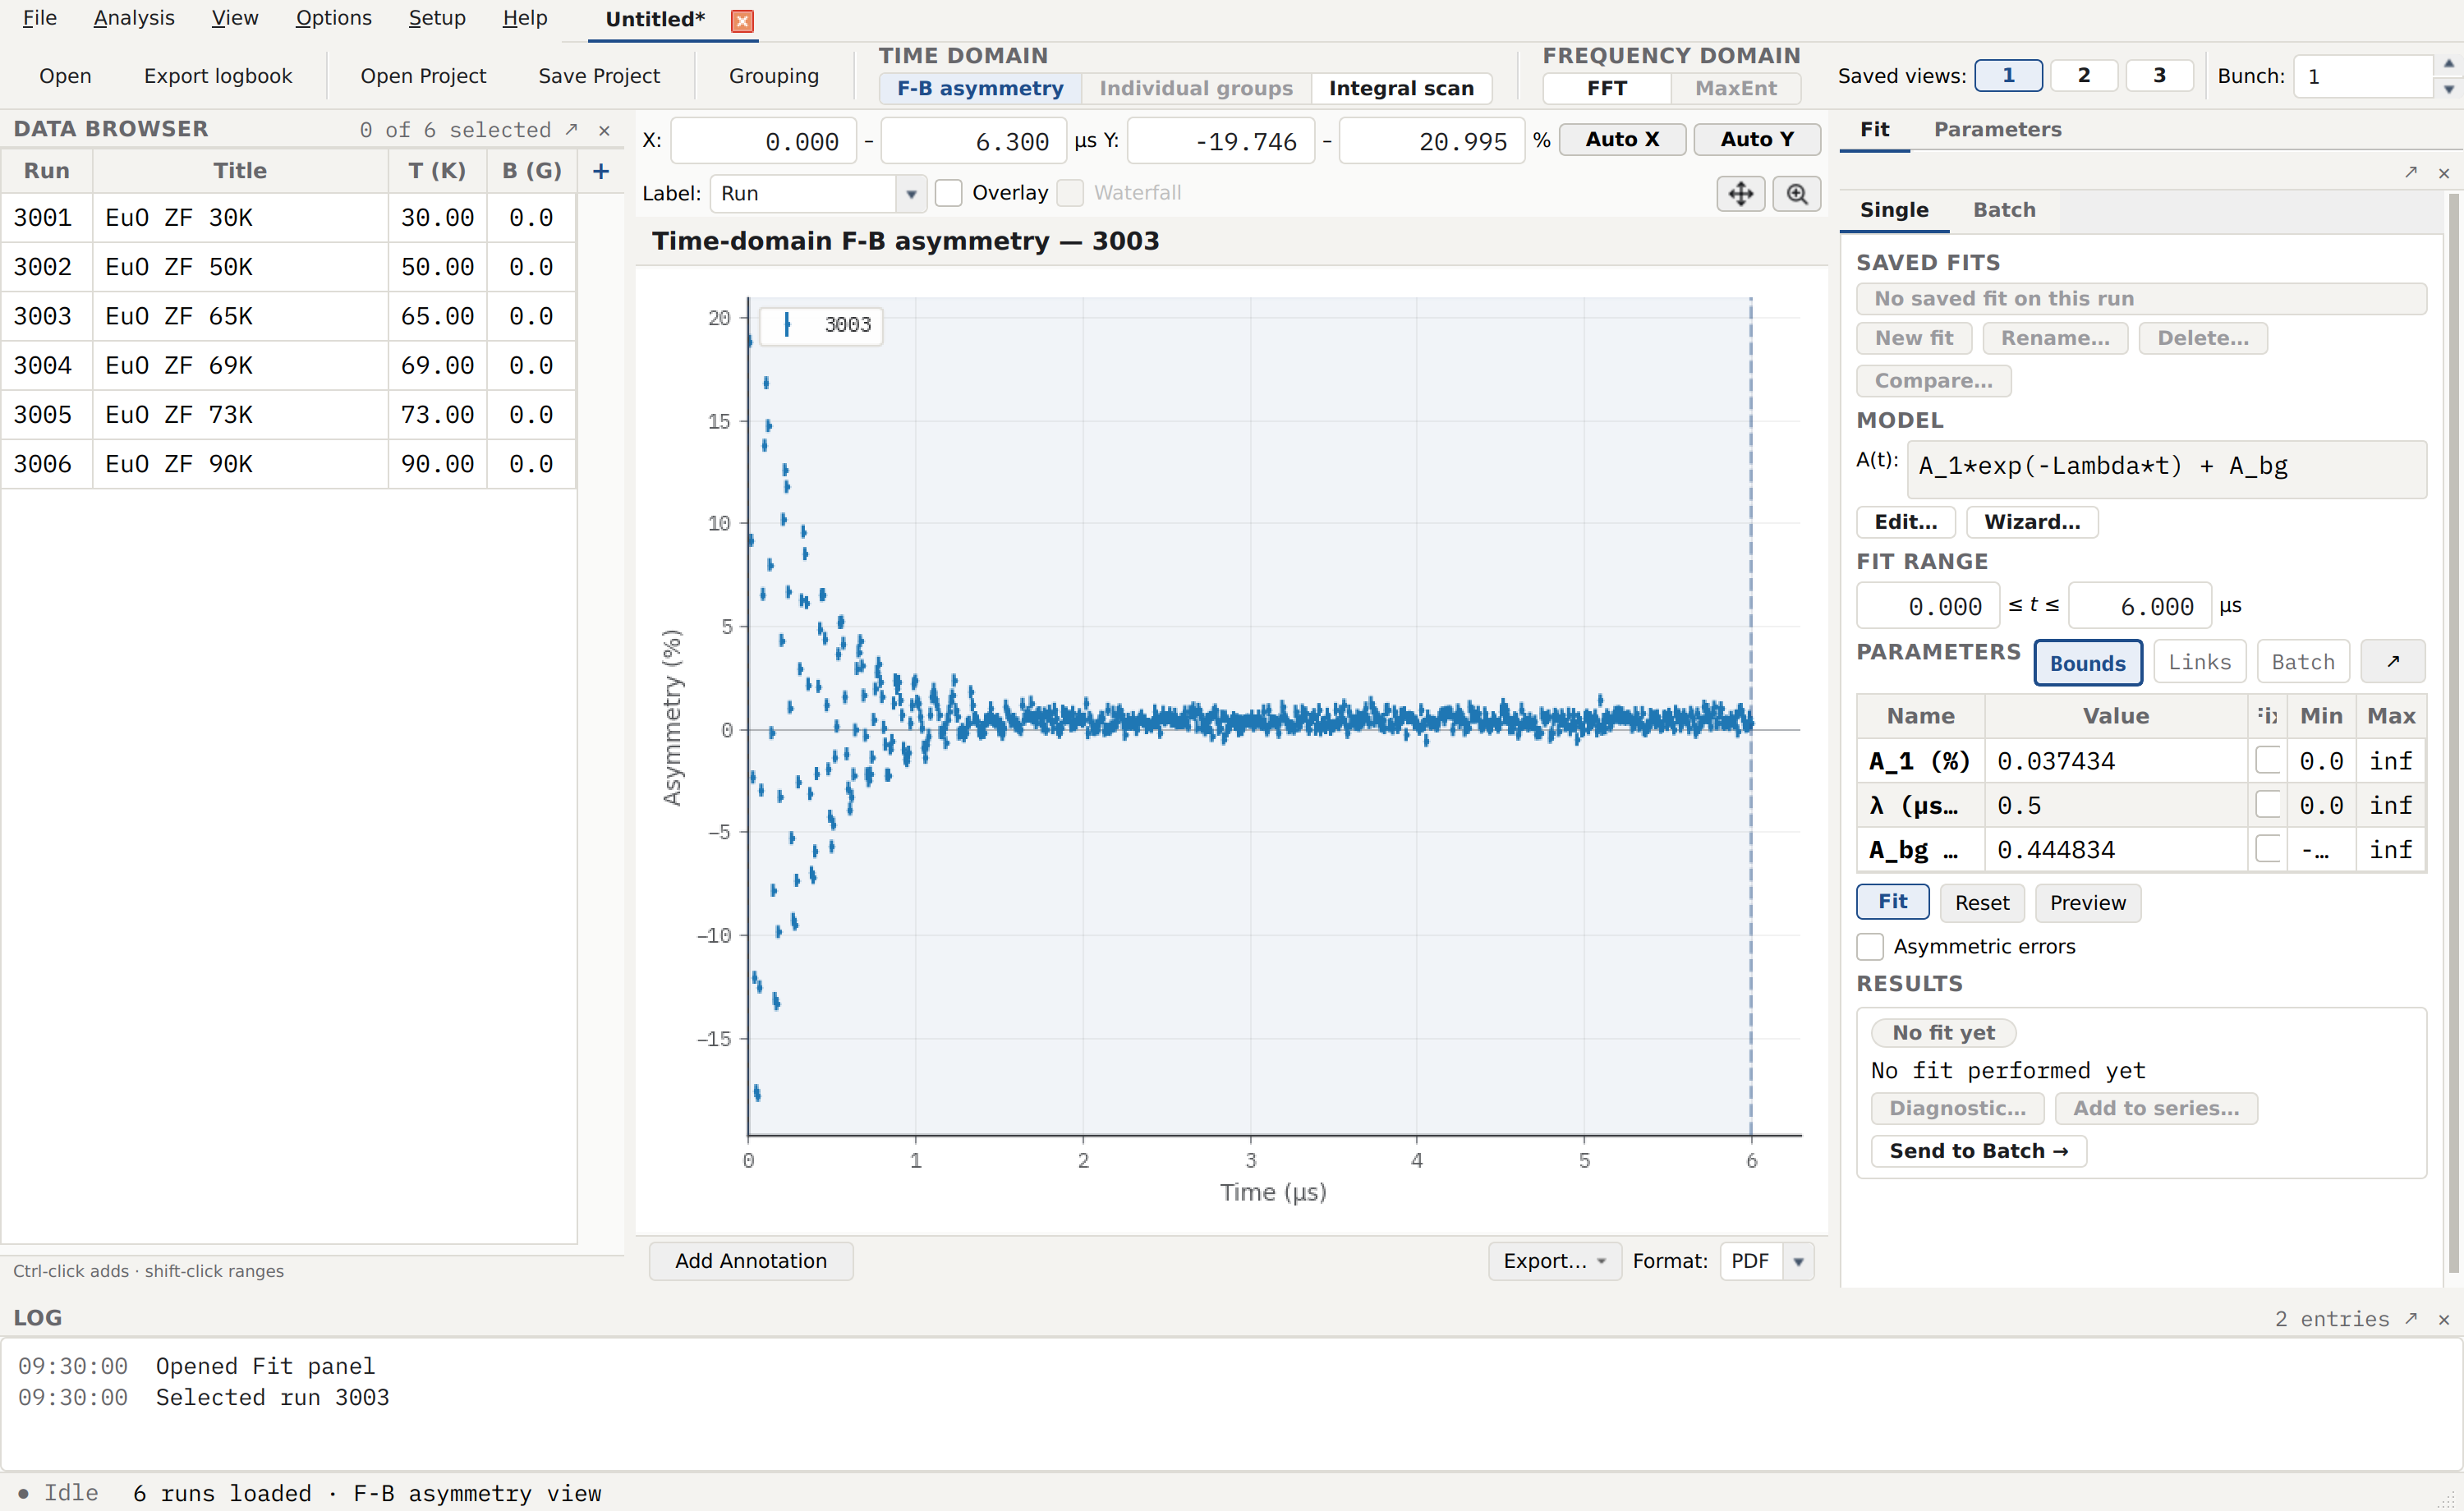
Synthetic EuO ferromagnet temperature scan crossing the Curie point at Tc=69 K — six zero-field runs from 30 K up to 90 K (cf. Blundell et al., Muon Spectroscopy: An Introduction, Oxford University Press, Oxford, 2022, Fig. 6.6). The selected run at 65 K is just inside the ordered phase where the spontaneous-field precession is at its slowest and the critical damping is largest.
The main window has four main areas:
Data Browser (left): Table of loaded datasets
Plot Panel (centre): Interactive plot display
Analysis Panels (right): Fit and Fourier controls
Log Panel (bottom): Status messages and command history
Loading data
Multiple file selection
Click File → Open (or toolbar “Open” button)
Select one or multiple supported data files (use Ctrl+Click or Shift+Click)
All selected files will be loaded into the data browser
The data browser shows:
Run number
Title
Temperature (K)
Magnetic field (G)
Use Options → Use temperature from log to switch the fixed temperature column from the scalar/header temperature to the average of the sample temperature log when a supported log is available. The menu option applies the same choice to every loaded run and clears any per-run overrides. Temperature cells whose value comes from a log are shown with red text. Untick the option to return the column to the scalar/header value.
The value shown here is also the one a batch parameter trend plots against and exports to TSV: with the option on, a temperature trend uses each run’s logged temperature rather than its parked setpoint — see How the T / B abscissa is sourced.
Data Browser features
Sorting
Click any column header to sort by that field:
Left-click: Toggle between ascending and descending order
Numeric columns (Run, T(K), B(G)) sort numerically
Text columns (Title) sort alphabetically
The sorting is robust and works correctly even after filtering.
Excel-style column filtering
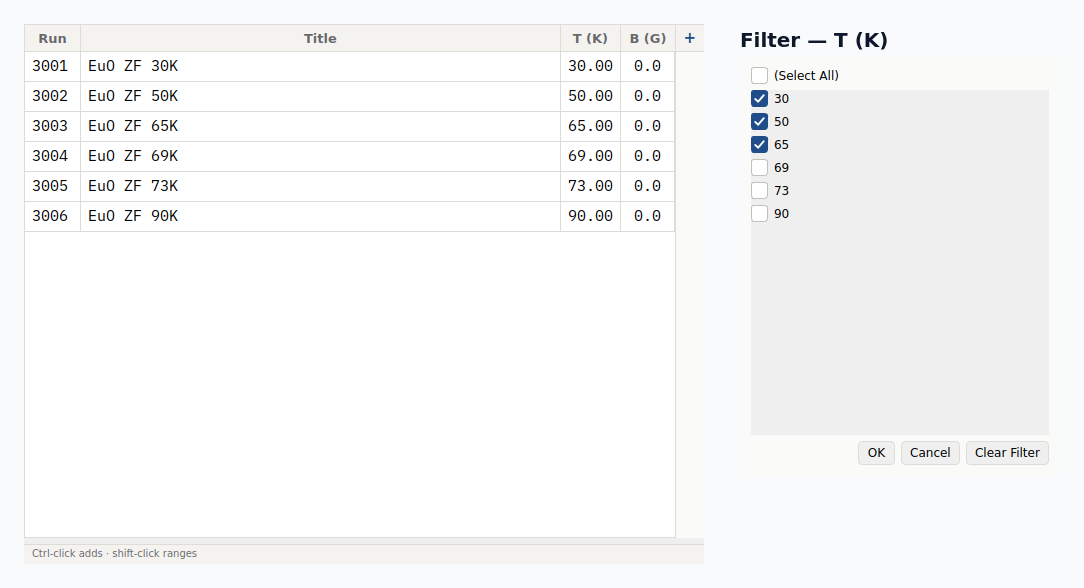
Right-click filter dialog applied to the T(K) column of the EuO ZF temperature scan, with the three runs at or below Tc=69 K selected to isolate the ordered ferromagnetic phase.
Right-click any column header to open an Excel-style filter dialog:
Right-click a column header (Run, Title, T(K), or B(G))
A dialog appears showing all unique values in that column
Check/uncheck values to show/hide rows with those values
Use Select All / Deselect All for quick control
Click OK to apply the filter, or Cancel to abort
Features:
Multiple columns can be filtered simultaneously
Filters persist while you work with other data
Clear filters by right-clicking and selecting all values again
Works seamlessly with sorting
Multi-selection
Click a row to select it
Ctrl+Click to add/remove from selection
Shift+Click to select a range
When more than one dataset is selected, the main plot overlays all selected runs on the same axes using distinct colours when Overlay is enabled (default).
If Overlay is disabled, only the most recently selected dataset is shown. For a single selected Data Group, Asymmetry keeps the most recently displayed dataset if it belongs to that group; otherwise it shows the first dataset in the group.
Viewing data
Click any dataset row to plot it in the main panel.
Data groups
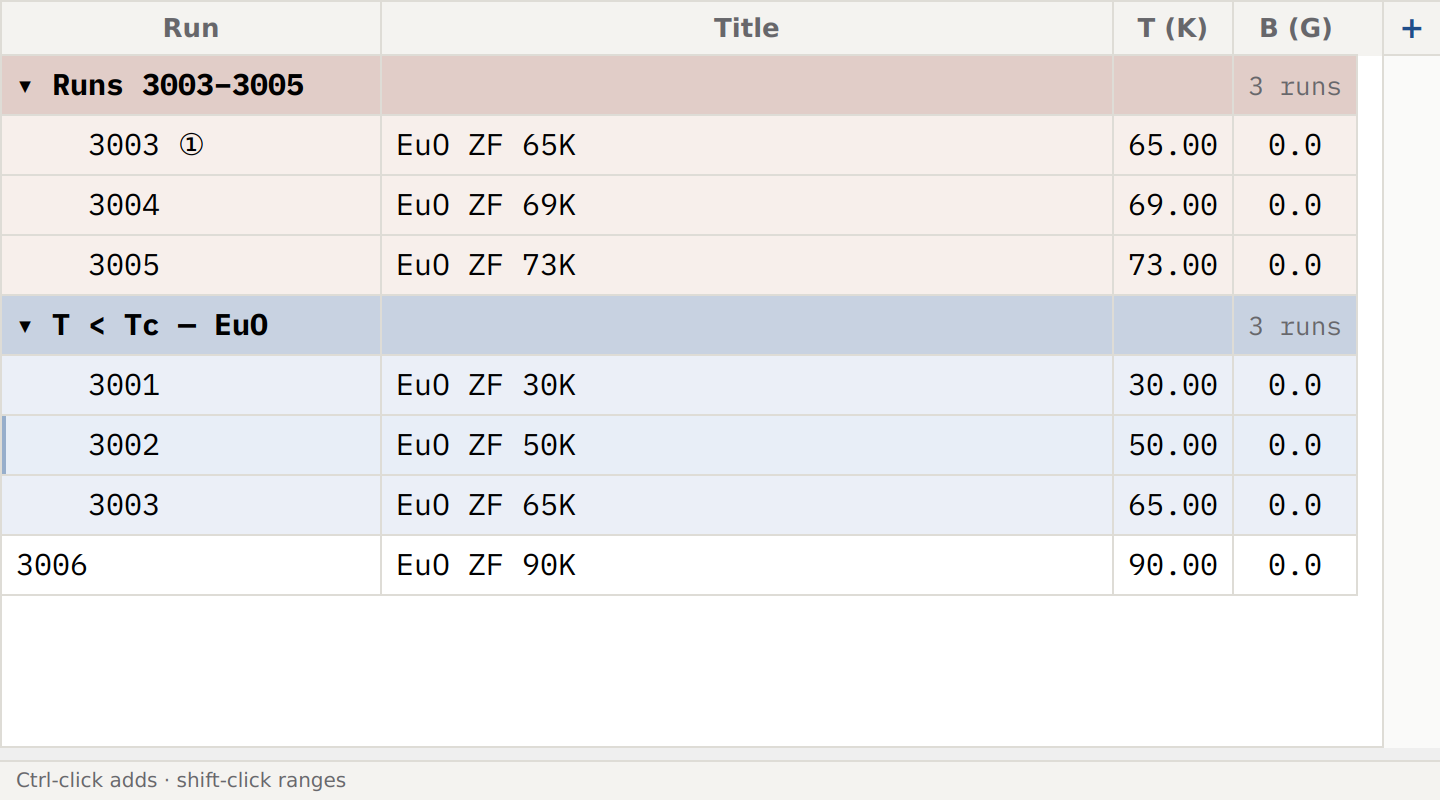
A user group (blue, “T < Tc — EuO”) and an auto-created group (red-grey, “Runs 3003–3005”, named the way an ad-hoc batch fit would mint one automatically) sharing run 3003. The shared run renders under its primary (user-group) row and again as a marked copy row under the auto group.
A data group is a named, ordered collection of runs — a temperature scan, a field sweep, or any set of runs you want to treat together. Groups organise the Data Browser and drive batch and global fitting: a group is the vehicle a batch fit runs over, and its owned fit series stay attached to it (see Group-bound series and staleness in Parameter trending).
Select two or more loaded runs, right-click, and choose Form Data Group to create one; a Group name: prompt asks for its display name. Groups appear as headers in the browser with their member runs nested beneath, and a group’s context menu (right-click its header) offers:
Collapse Group / Expand Group — hide or show its member rows.
Rename Group — change the display name.
Ungroup — dissolve the group. If it owns no fit series this happens silently; if it does, a dialog asks whether to Keep fits (the owned series become standalone, frozen analyses with their last-fitted membership as a fixed snapshot) or Delete fits (remove the group and its series together), with Cancel to back out.
Fit this group… — bind the fit dock’s Batch tab to this group so the recorded series stays attached to it; see Batch fitting below.
Show series from this group — filter the Fit Parameters panel to this group’s series.
Right-click a selection of ungrouped (or already-grouped) runs and choose Send to Group to add them to an existing group — this always adds a membership rather than moving the run out of any group it already belongs to, so one run can belong to several groups at once (a run in both a field scan and a temperature scan, say). A run with more than one membership renders once per group: its entry in every group but the first (its primary membership) carries a small circled-digit marker (①, ② …), and hovering the marker shows an Also in: tooltip naming its other groups. Selecting any of a run’s rows reaches the same underlying dataset, so plotting, fitting, and co-add never double-count it. Remove from Group (or Remove from Groups, for a multi-row selection) removes just the clicked membership; removing a run’s primary membership promotes its earliest remaining copy to primary.
Two further markers relate to detector grouping (see Detector Grouping and Layout): a run released from its grouping profile carries a trailing ⊗ with an amber run number, and when a run’s instrument has several grouping profiles in the project (one per sample, say) each run’s number is coloured with its assigned profile’s identity colour — the same colour the Grouping window uses for that profile, with runs on the ★ default profile staying plain black — and the tooltip “Grouping profile: <name>” names it. Right-clicking a run selection then offers Assign Grouping Profile to move the runs to another of the instrument’s profiles.
Batch and global fits over an ad-hoc run selection (not bound to a group) automatically create — or, for an identical run set, reuse — a group for the fit, so every recorded batch series always has an owning group. These auto-created groups are named from their run range (e.g. “Runs 1001–1010”) and paint in a red-grey tint distinct from the blue used for groups you name yourself, so the two are easy to tell apart at a glance; renaming an auto-created group promotes it to an ordinary (blue) group.
Phases within a group
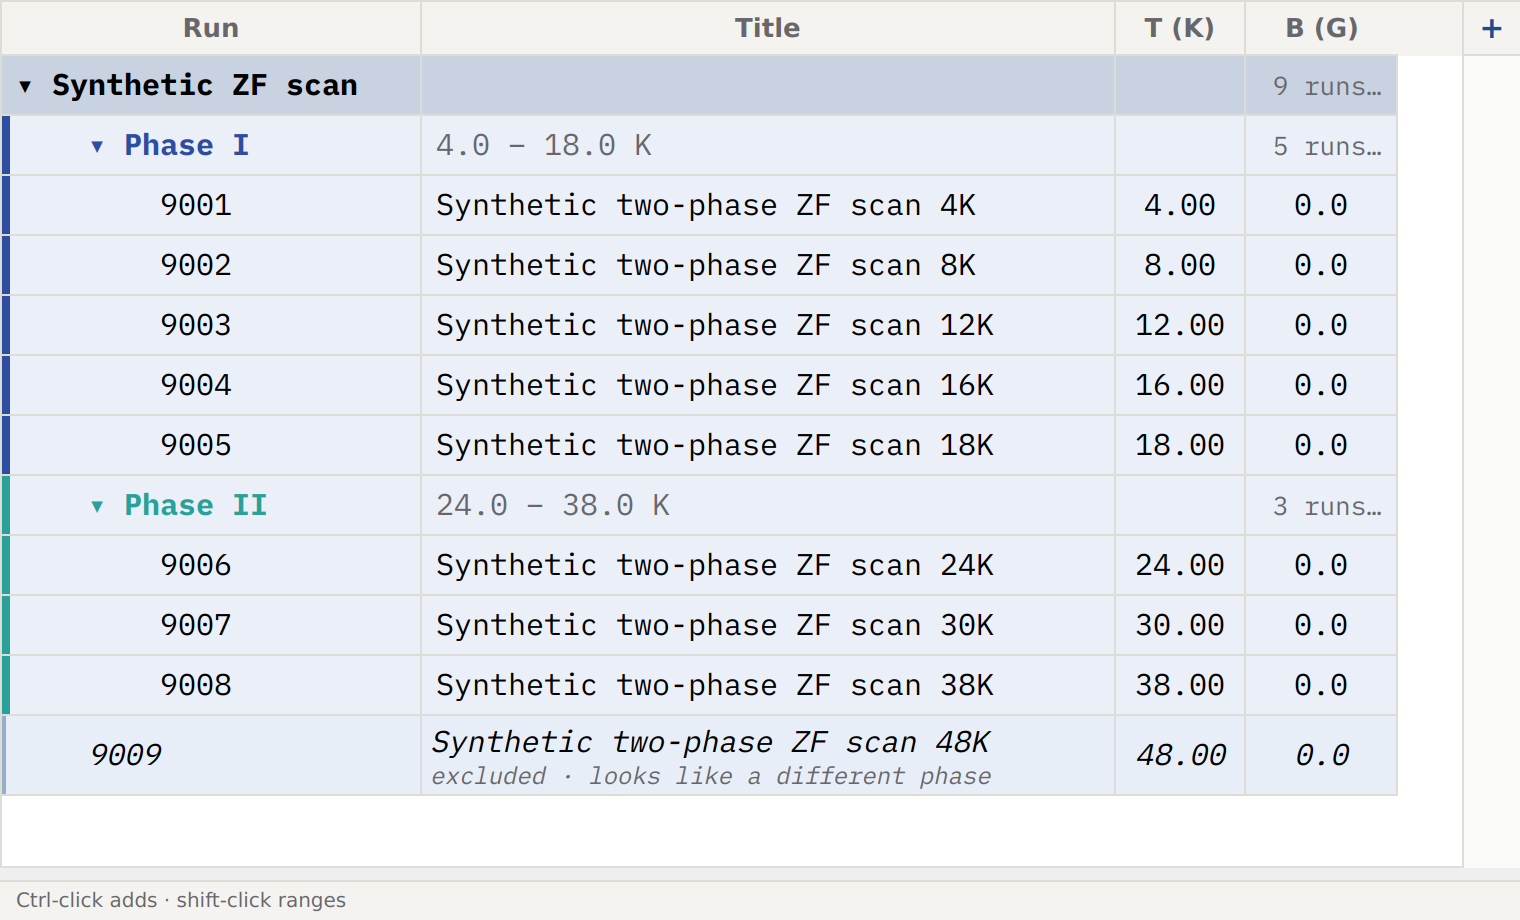
A temperature-scan group the Global Fit Wizard has partitioned into two phases, plus one run at the top end the partition left out of both.
When you Apply phases from the Global Fit Wizard’s Phases step (see
Phases: transitions and the penalty path in Global fit wizard), the series
group gains one nested sub-group per phase — a contiguous run of the series
sharing one template and one Global/Local assignment. A phase renders as a
sub-header beneath its parent group, indented one level deeper than an
ordinary group header: a collapse chevron, the phase’s colour swatch, a name
and range (▾ Phase I, with 1.8 – 16.0 K in the Title column), and a
run count carrying an ⓘ indicator (3 runs ⓘ). Phase names are Roman
numerals in sweep order — Phase I is the coldest (or lowest-field) phase —
and each phase keeps a stable identity colour from a five-colour, cold-to-hot
palette that cycles for a sixth phase and beyond.
A phase’s member rows sit beneath its sub-header, each carrying a 4 px stripe in the phase’s colour down its left edge (never a background tint, which would fight with row selection and filtering). Phase membership is a refinement of the parent group’s membership, not a second, independent one — a run in a phase never renders twice and never carries the ①-style “also in” marker a genuine multi-group membership does. A run the partition did not assign to any phase renders after the phases, as a direct member of the series group again: italic, with a hatched grey stripe in place of a phase colour, and a Title-column badge reading “excluded · looks like a different phase”. Selecting the series header’s row selects every run, phases and excluded members alike; selecting a phase header selects just that phase’s runs.
Right-click a phase header for Collapse Phase / Expand Phase, Rename Phase, Fit this phase… (bind the fit dock’s Batch tab to this phase), Show series from this phase (filter the Fit Parameters panel to its series), and Ungroup, which dissolves every phase of the partition at once (the same keep-fits/delete-fits choice as an ordinary group). Right-click a run inside a partitioned series for Move to phase ▸ — a submenu listing every phase (with its swatch and a check mark on the run’s current phase) plus Exclude from phases — the manual override for a boundary the wizard placed one run off; moving a run marks both the losing and gaining phases’ series stale (see Group-bound series and staleness in Parameter trending).
Click a phase header’s ⓘ for what its compact header leaves out: the
template it was fitted with (Model), how that fit went (Global fit,
e.g. converged · 1.04 · high), which parameters are shared across the
phase (Shared), the estimated break at each end of the phase
(Boundaries), and when and how the partition found it (Found by, e.g.
2026-09-06T09:00:00 · 1 breaks · gains 12.4) — plus the same Fit this
phase… / Show series / Rename actions as the context menu. The
series header’s own ⓘ instead summarises the whole partition — how many
phases and transitions it has (2 phases · 1 transition) and when each
phase was found — since “how is this scan split?” is a different question
from “what happened in this phase?”.
Co-adding datasets
To average multiple datasets:
Select 2 or more datasets (Ctrl+Click or Shift+Click)
Right-click any selected row and choose “Co-add Selected”
A new combined dataset appears at the position of the first selected dataset
Display shows run numbers combined:
3077 + 3076
The co-added dataset:
Uses the first dataset’s time grid
Averages asymmetry values
Propagates errors correctly: σ_combined = √(Σσ²) / N
Requires identical grouping on every selected source dataset
Mirrors the shared grouping state of its source datasets
Can be plotted and analysed like any other dataset
If the selected datasets do not share the same grouping (groups, alpha, good-bin limits, bunching, deadtime settings, and related grouped-data controls), co-add is blocked and the browser leaves all source rows unchanged. Align grouping first, then retry the co-add.
Separating combined data
To remove a co-added dataset:
Select the combined dataset (display shows combined run numbers)
Right-click and choose “Separate Combined”
The combined entry is replaced by its source datasets at the same position
Source datasets are restored with the current grouping of the combined view
Grouping a combined dataset edits its hidden source datasets behind the scenes, then rebuilds the combined row from those updated sources. Separating the combined dataset therefore returns single runs with the same grouping that was active on the combined entry.
Deleting datasets
To remove a dataset from the browser:
Select one or more datasets
Right-click and choose “Remove Entry” or “Remove Selected Entries”
Alternatively, press the Delete key
This removes the dataset(s) from the browser; they can be reloaded via File → Open.
Exporting the logbook
Use the Export logbook toolbar button (immediately after Open) to write the current Data Browser contents to a file.
Export behaviour:
- Exports the currently active Data Browser columns, including dynamic columns
added from Run Info.
Preserves data-group organisation by writing a section header for each group.
Includes datasets hidden by filters and collapsed groups.
- Writes section headers and data rows with a consistent column count so header
labels and values align cleanly.
Formats:
- TSV (recommended, default): Fastest export path and best choice for large
logbooks. Opens directly in spreadsheet tools with clear column alignment.
- RTF: Rich text output with italicised T and B header labels.
Useful for report-style sharing, but slower than TSV for large tables.
Default filename:
- If the current project has a name (for example
My_Project.asymp), the default export filename is
My_Project_logbook.tsv.
- If the current project has a name (for example
If no project name is available, the default is
logbook.tsv.
Plot panel controls
The plot panel displays the selected dataset(s) with error bars.
Axis limits
Each axis — X and Y — is independently either Auto (it follows the data on every redraw: a run switch, a recomputed spectrum, a view-mode change) or Held (it keeps its value across all of that). Browsing holds the window by default, so paging through a run series to compare the same window needs no extra step; Auto X / Auto Y are the way to tell an axis to follow the data instead.
X min/max: Time axis range (μs)
Y min/max: Asymmetry axis range
Press Enter after editing any limit value to apply immediately — typing a value holds that axis and turns off its Auto X / Auto Y button
Click Auto X to make the X axis follow the data; click Auto Y to do the same for Y
Pan and Zoom are the four-way-arrow and magnifier icon buttons at the right end of the second toolbar row (hover for their names); click one to drag the view or drag a box to zoom, and click it again to stop
Auto-Y uses points inside the currently selected X range and prefers reliable foreground points (excluding undefined/low-confidence bins when available). On the Frequency-domain plot, Auto X frames the spectrum sensibly — the dominant line, or the field-derived Larmor window — rather than the full Nyquist span. The very first plot in a new session has nothing held yet, so it frames from the data even with both Auto buttons off — an axis with nothing held simply takes the data’s frame, no toggle needed.
A Zoom or Pan gesture holds only the axis (or axes) it actually moved: a horizontal-only zoom leaves Auto Y exactly as it was, and a vertical-only pan leaves Auto X alone. Re-enable either button at any time to release that axis back to following the data.
Default limits automatically adjust to fit the data including error bars, with 5% padding.
A blank canvas — browsing onto a run with no spectrum computed yet, for example — never touches a held value, so the window you left an axis in is exactly what you see once data reappears. Closing a project or starting a new one is the only thing that forgets held limits; project files otherwise remember each axis’s Auto/Held state (and its held value), so reopening a saved project restores the same view.
Dense-data display (decimation)
Very dense traces (e.g. high-resolution ROOT histograms or many-point
spectra) are display-decimated: only a bounded number of points is
rendered so panning, zooming, and switching runs stay responsive. A small
corner chip — for example 4.0k of 1.2M pts — appears whenever the
current view is decimated, and disappears once you zoom in far enough that
every visible point is drawn.
Decimation affects the display only. Fits, transforms (FFT, MaxEnt, moments) and exports always use the full-resolution data.
Time-domain scatter is decimated by uniform sampling, which is an unbiased visual sample of noisy data. Frequency-domain spectra instead keep the minimum and maximum of each display bucket, so a narrow spectral peak can never vanish from the screen.
Legend label field
Use the Label dropdown (left side of toolbar row 2) to choose how each selected run is labelled in the legend:
Run (default)
Field (G)
Temperature (K)
Comment
The same Label dropdown is available on the frequency (FFT / MaxEnt) toolbar and labels the overlaid spectra there, including custom columns such as an Angle (°) field. The time-domain and frequency views keep their own independent Label selection.
If the selected metadata value is unavailable for a run, Asymmetry automatically falls back to the run label.
Overlay (to the right of Label) controls whether multi-selection and group selections are drawn together on one set of axes, or reduced to one dataset view as described above in Multi-Selection.
For single-dataset views, the main plot also shows the active grouping
alpha value above the canvas when one is available. The overlay is hidden
for multi-dataset comparisons.
Waterfall stacking
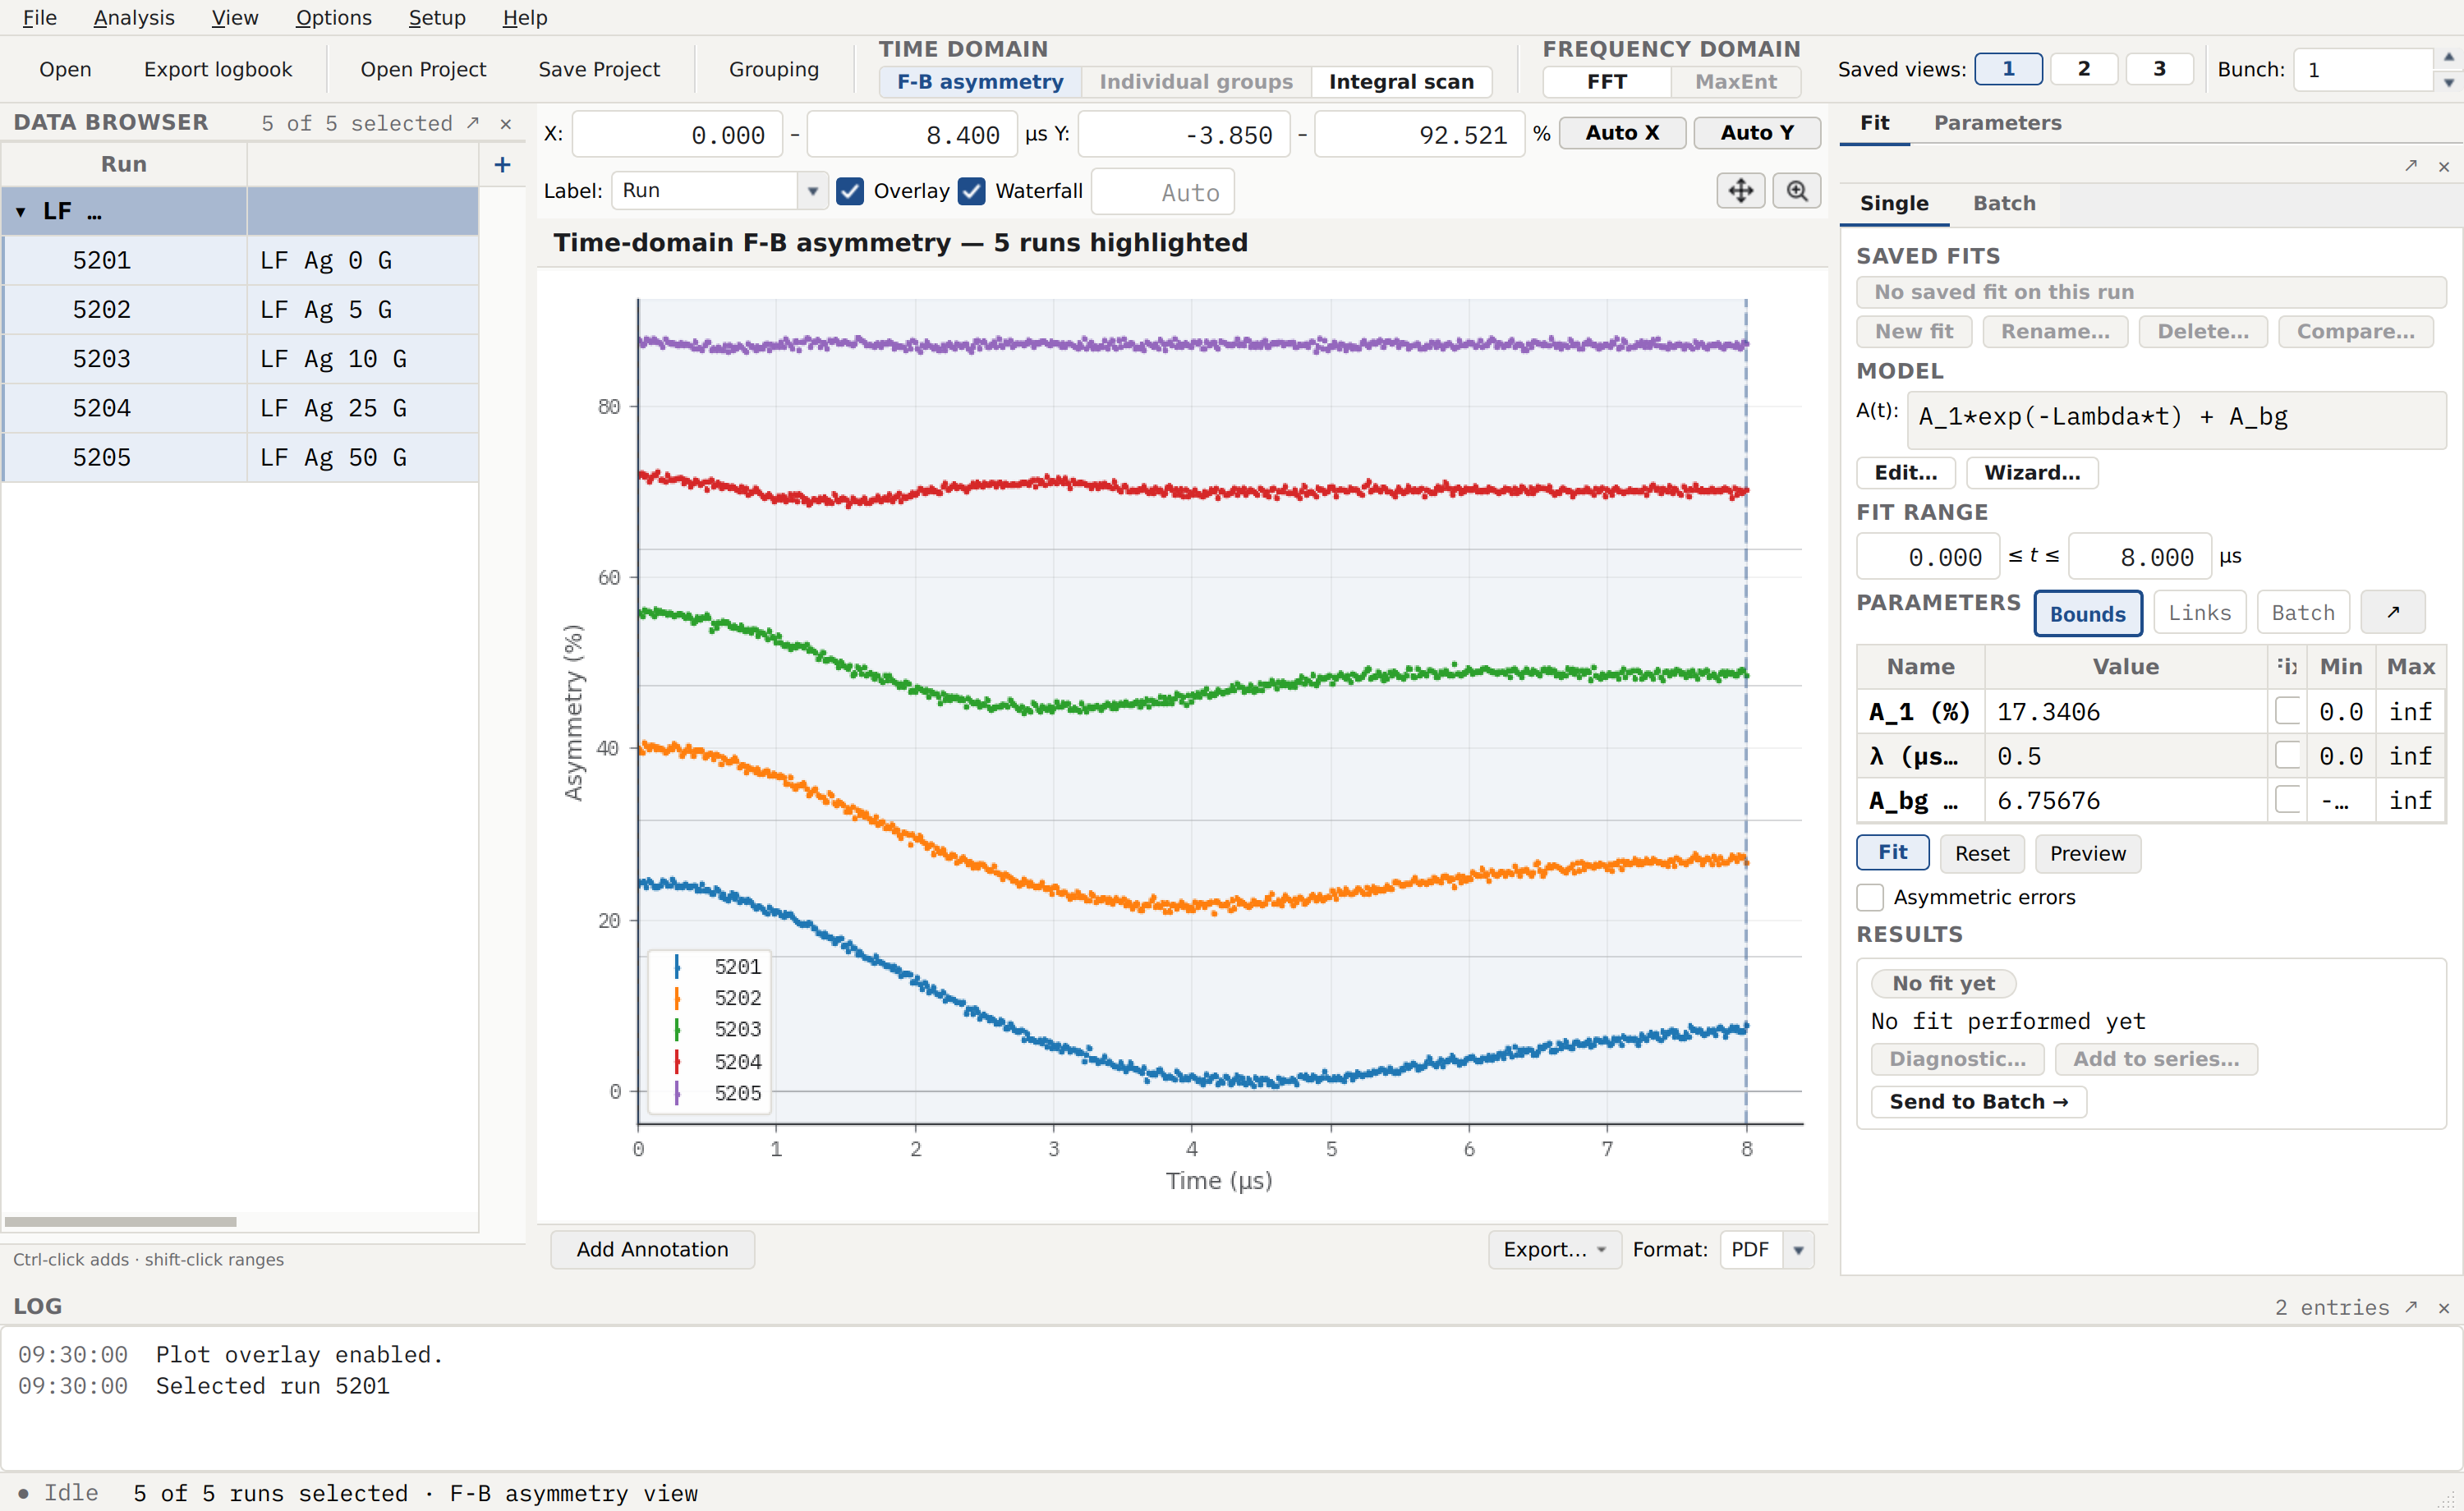
The same five-field Ag LF Kubo–Toyabe decoupling series as the LF decoupling walkthrough, now with Waterfall enabled: each field’s trace is shifted onto its own baseline instead of sharing one axis with the rest.
An overlay of several runs is easiest to compare when every trace shares one baseline, but that is exactly what makes closely-spaced curves hard to read apart. Waterfall (next to Overlay, both on both the time-domain and frequency-domain plot panels) resolves this by shifting each trace vertically by a uniform per-trace offset \(i \cdot \Delta\), so an n-run overlay reads as n cleanly separated curves stacked bottom to top in selection order.
Waterfall only makes sense once there is more than one trace to separate, so its checkbox tracks Overlay: it stays disabled and unchecked until Overlay is on, and switching Overlay off unchecks it again. Stacked-subplot views — Individual Groups and other multi-axis layouts — are unaffected; waterfall only ever modifies the single-axis overlay.
The spacing Δ is automatic by default: 1.4× the median robust span (98th minus
2nd percentile of the finite samples, which ignores a handful of
saturation/outlier bins) across the traces about to be drawn, measured over
the displayed x-range rather than the full arrays — an FFT magnitude spectrum
keeps a long near-zero tail beyond the framed peak region that would otherwise
shrink Δ to a fraction of the visible spans. Neighbouring curves therefore
clear each other with a little breathing room without any tuning; zooming
afterwards does not re-space an already-drawn stack.
To fix Δ manually instead, type a value into the field that appears beside
the checkbox while Waterfall is on — its placeholder reads Auto, and
clearing the field (leaving it blank) returns to automatic spacing.
In the time domain, each stacked trace also gets a faint horizontal hairline at its own shifted zero, so a curve’s depolarisation or oscillation reads against its own reference rather than the axis origin. Frequency-domain waterfalls stack the same way but skip the hairline, since a spectrum already sits on its own zero baseline.
Export to GLE and the plain-text data/fit exports both reproduce the
on-screen stack, but differ in where the offset lives. With gleplot >= 1.7
the GLE export applies each per-trace offset in the GLE script itself (a GLE
let that shifts the trace at plot time), so the exported .dat/.fit
sidecars keep their raw, unshifted values — the stack is a property of the
figure, not of the data, and can be retuned in the script. Against
older gleplot (and always for the plain-text export, which has no script to
carry the offset) the offset is baked into the written column instead. Either
way each file records a waterfall offset: header line documenting the
applied shift.
The waterfall setting — on/off and the manual Δ (or automatic, if left blank) — is saved per plot panel in the project file and restored on reopen.
Run Info and metadata columns
Use Get Info (context menu on a run) to open the Run Info window.
Primary Run Info table
The primary table shows key run parameters in four columns:
Include in Data Browser (checkbox)
Field
Value
Log Plot
Ticking a checkbox adds that field as a dynamic column in the Data Browser. Unticking removes it.
Known summary fields use friendly Data Browser headers rather than raw metadata
paths. For example, run_info.points appears as Points, and
nexus_fields.sample.shape appears as Orientation.
For parameters backed by time-series NeXus logs, a Plot button appears in the right column and opens the full log trace. NeXus sample-temperature logs follow the same Data Browser rule as PSI and ROOT logs: the fixed Temperature (K) column uses the scalar/header temperature by default, and switches to the log mean while Options → Use temperature from log is enabled. The menu option applies to every loaded run. The Temperature (K) include checkbox in Get Info overrides only the run whose Get Info window is open, so it can be used to make per-dataset exceptions after setting the global option. Temperature values shown in red are using log averages.
PSI-BIN .mon temperature logs are exposed through the same time-series
path. When a matching sidecar is loaded, the summary Temperature (K) row
gets a Plot button and the individual channels are listed in Advanced as
nexus_time_series.psi_temperature/Temp_<channel>.mean rows.
MusrRoot ROOT slow-control histograms are handled in the same way. If the file
contains histos/SCAnaModule/hSampleTemperature, Get Info shows the average
temperature from that histogram, provides a Plot button, and lets the
Temperature (K) checkbox replace the Data Browser’s default header
temperature with the log mean for that run only. FLAME ROOT files can store the
same information under sensor names such as SAM_ts_value; when the header
temperature references that sensor, the Temperature (K) row uses it for
the log plot.
Advanced subwindow
Click Advanced to open a separate, scrollable subwindow containing a full metadata table with the same include-checkbox and log-plot behaviour.
This allows promoting any advanced NeXus field into the Data Browser without leaving the Run Info workflow.
For PSI-BIN temperature sidecars, Advanced also lists psi_temperature_log
provenance fields, including the source .mon path and the
Mantid LoadPSIMuonBin-compatible reader provenance.
For MusrRoot slow-control logs, Advanced lists musrroot_slow_control_log
provenance fields and nexus_time_series.musrroot_slow_control/... summary
rows.
The Advanced window now includes a search box, so you can filter the metadata table by field name or rendered value before adding a column or opening a log trace.
Grouping and bunching
Grouping configuration is opened from Grouping (toolbar/menu). Supported
raw data runs use the full Grouping dialog, seeded with detector labels
and per-detector t0 values from the file when those metadata are available.
This keeps fit inputs consistent with the run grouping settings and project state.
When you open the Grouping dialog from a run selection, the currently selected datasets are pre-ticked in the dialog. When loading new runs into an existing project, Asymmetry reuses the grouping payload from the highest run number currently present in the Data Browser when that payload is well-defined.
Full Grouping dialog
The full Grouping dialog supports editing grouping assignment, alpha, correction toggles, good-bin limits, and bunching. Deadtime correction is enabled only when the source file provides deadtime constants; background correction is enabled for PSI BIN/MDU and PSI/LEM ROOT data.
Changing bunching refreshes both the displayed curve and the dataset passed to the fitting panel.
Detector Layout editor
The full Grouping dialog includes a Detector Layout… button that opens a visual grouping editor for ISIS instruments HiFi, MuSR, EMU, and the PSI FLAME and HAL-9500 spectrometers, for data loaded from NeXus, BIN, MDU, or ROOT files.
The editor has three panels:
- Detector schematic (left): click detector sectors to toggle membership in
the currently active group. FLAME detectors are shown as rectangular plates in a top-view diagram; detector plates that are not in any group are left unfilled.
- Group slots (centre): eight group buttons (Group 1 to Group 8),
each with an editable name field.
- Presets (right): instrument selector plus a preset dropdown with
Apply Grouping.
Key behaviour:
A detector can belong to multiple groups at the same time.
Instrument is identified using the following priority when opening the editor:
Saved instrument — if a previous session already set the instrument for this dataset, that choice is restored directly.
Run metadata — fields such as
instrument,instrument_name,beamline, orspectrometerin the file’s embedded metadata. PSI FLAME BIN/ROOT files are recognised when metadata identifyFLAME, including values such asLMU_BULKMUSR_FLAME.Source filename — if the filename contains a recognisable instrument token (e.g.
emu,hifi,musr,flame).Histogram count — 64 histograms → HiFi; 96 histograms → EMU; other counts → no automatic selection.
The instrument can always be overridden from the instrument dropdown, and the chosen instrument is saved with the dataset so it survives project reloads.
Group names are saved in project grouping payloads.
Preset highlights:
HiFi and MuSR include longitudinal/transverse-style presets.
- EMU includes a Vector Polarization preset with six groups:
Pz Forward,Pz Backward,Py Top,Py Bottom,Px Left, andPx Right.
- FLAME includes Longitudinal (Forward / Backward) and Transverse
presets. The transverse preset groups
Right,R_B, andR_Ftogether, andLeft,L_B, andL_Ftogether.
- PSI detector-layout names follow the PSI beam-direction convention. The main
Grouping dialog uses spin-direction forward/backward for asymmetry calculation, so longitudinal PSI/FLAME analysis defaults are swapped: Forward Group =
Group 2: Backwardand Backward Group =Group 1: Forward. ISIS datasets are unchanged.
Note
Vector-polarisation mode is not exclusive to EMU. Any dataset whose six
group names follow the canonical pattern
(Pz Forward / Pz Backward, Py Top / Py Bottom,
Px Left / Px Right) will activate vector-mode features in the main
plot regardless of the instrument field.
When vector grouping is active, the main plot header shows a Polarization dropdown near the alpha display. You can select:
x — display the \(P_x\) pair (Left / Right detectors).
y — display the \(P_y\) pair (Top / Bottom detectors).
z — display the \(P_z\) pair (Forward / Backward detectors).
- All — display all three polarisation components as stacked subplots
sharing the same time axis. Each subplot carries its own Y-axis label and colour-matched error bars.
When vector grouping is active, the Grouping dialog replaces the single alpha control with per-axis alpha controls:
alpha_xforP_xalpha_yforP_yalpha_zforP_z
Each axis has its own Estimate alpha button, and an Estimate All alpha button is available to update all three axis values in one step.
All of these are available without reopening the Grouping dialog.
The main-plot Y limits are remembered separately for each polarisation axis, so changing between axes restores your previous Y-range for that axis. In All mode the Y-axis controls are read-only; adjust the limits for each component individually by switching to that axis first.
Note
When a project is saved with All mode active, all three subplots are rendered immediately on the next project load — no manual axis switch is required.
Note
The alpha value shown in the main plot header is axis-specific in x,
y, and z modes, and hidden in All mode.
In the Detector Layout Editor, the preset panel shows a status line under the
preset dropdown, for example (Current: Vector Polarization). This remains
until the grouping is edited away from the applied preset, then changes to
(Current: Custom).
Two-period RG mode
When the reference run contains two periods in the full Grouping dialog, an RG Mode row with WiMDA-style radio buttons:
Red
Green
G minus R
G plus R
The selected mode is applied during grouping recomputation:
Red uses period-1 histograms.
Green uses period-2 histograms.
- G minus R computes asymmetry for Green and Red separately, then subtracts
them in asymmetry space: \(A_{G-R} = A_G - A_R\).
G plus R pools corrected, aligned counts and retained variances, applies group background once, then bins counts and forms one shared-α/β ratio: \(A_{G+R}=A(F_G+F_R,B_G+B_R)\).
Both combined modes use common observed native support before binning. Equal-total 20%/80% periods give G+R 50% and G−R 60%.
For G−R, the independent set asymmetry uncertainties add in quadrature:
Colour behaviour in the main plot:
Single-run views use the RG mode colour directly.
- Multi-run overlays keep the first trace in the selected RG mode colour and
use contrasting colours for additional selected runs so traces remain distinguishable.
The selected RG mode is saved in the grouping payload as period_mode.
Low-count tail display
At late times, grouped counts can become very small. Asymmetry bins with a non-positive denominator \(F + \alpha B\) are treated as undefined and are not drawn in the main plot.
Bins with very small but positive denominator may still show large point-to-point variation (including values near \(\pm 100\%\)), which is expected for low-statistics tails.
Main plot labels and export
The main plot now supports interactive labels and direct GLE export for the currently displayed dataset or dataset overlay.
For full detector schematics and vector grouping reference material, see Detector Grouping and Layout and Vector-polarisation mode.
Interactive labels
- Click Add Annotation, then click on the plot to place text at that data
coordinate.
Drag a label with the mouse to reposition it.
Double-click a label to edit its text.
Right-click a label to delete it.
Export Plot(s) to GLE
Main-plot export is now driven directly from the plot toolbar, using:
Export Plot(s) to GLE button
Format dropdown (PDF or EPS)
The export writes a self-contained <name>.gleplot folder by default. That
folder contains the .gle script plus the per-dataset sidecar files for the
currently displayed datasets. This works for:
Single-dataset views
Multi-selection overlays (all selected datasets currently plotted)
What is exported:
Data as error bars (no connecting lines)
Fit curves as lines when a fit overlay is available
User plot labels/annotations (same text and coordinates)
Output files and naming inside <name>.gleplot:
<name>.glefor the exported script<label>.datfor each exported dataset (time, asymmetry, error)<label>.fitfor each exported fit curve when present (time, fitted asymmetry)- file stems are derived from the selected Label field value and sanitised
for safe filenames, lowercased, and given distinct suffixes for duplicate stems
The .dat sidecar includes structured comment headers describing the run
and source settings captured for export, including run number,
title/comment timestamps when available, histogram/binning information,
forward/backward grouping, alpha, good-bin limits, bunching, and deadtime
correction state.
The grouping block states Context: source settings at export capture.
Its editable source settings are separate from the result’s immutable
effective_recipe. Captured result settings: effective_recipe identifies
that authority; Captured result settings: unknown preserves missing history.
The .fit header includes run metadata and fit metadata, including:
fit function description
\(\chi^2\)
reduced \(\chi^2\)
fitted parameter values and uncertainties (when available)
Compilation behaviour:
If
gleis available, Asymmetry compiles the.gleinside the export folder to the selected format from the Format dropdown.If
gleis not available, Asymmetry still saves the.gleand sidecar files so you can compile later.If
gleplotregenerates matching.datfiles while saving, Asymmetry rewrites the metadata-rich sidecars afterwards so those headers are retained.
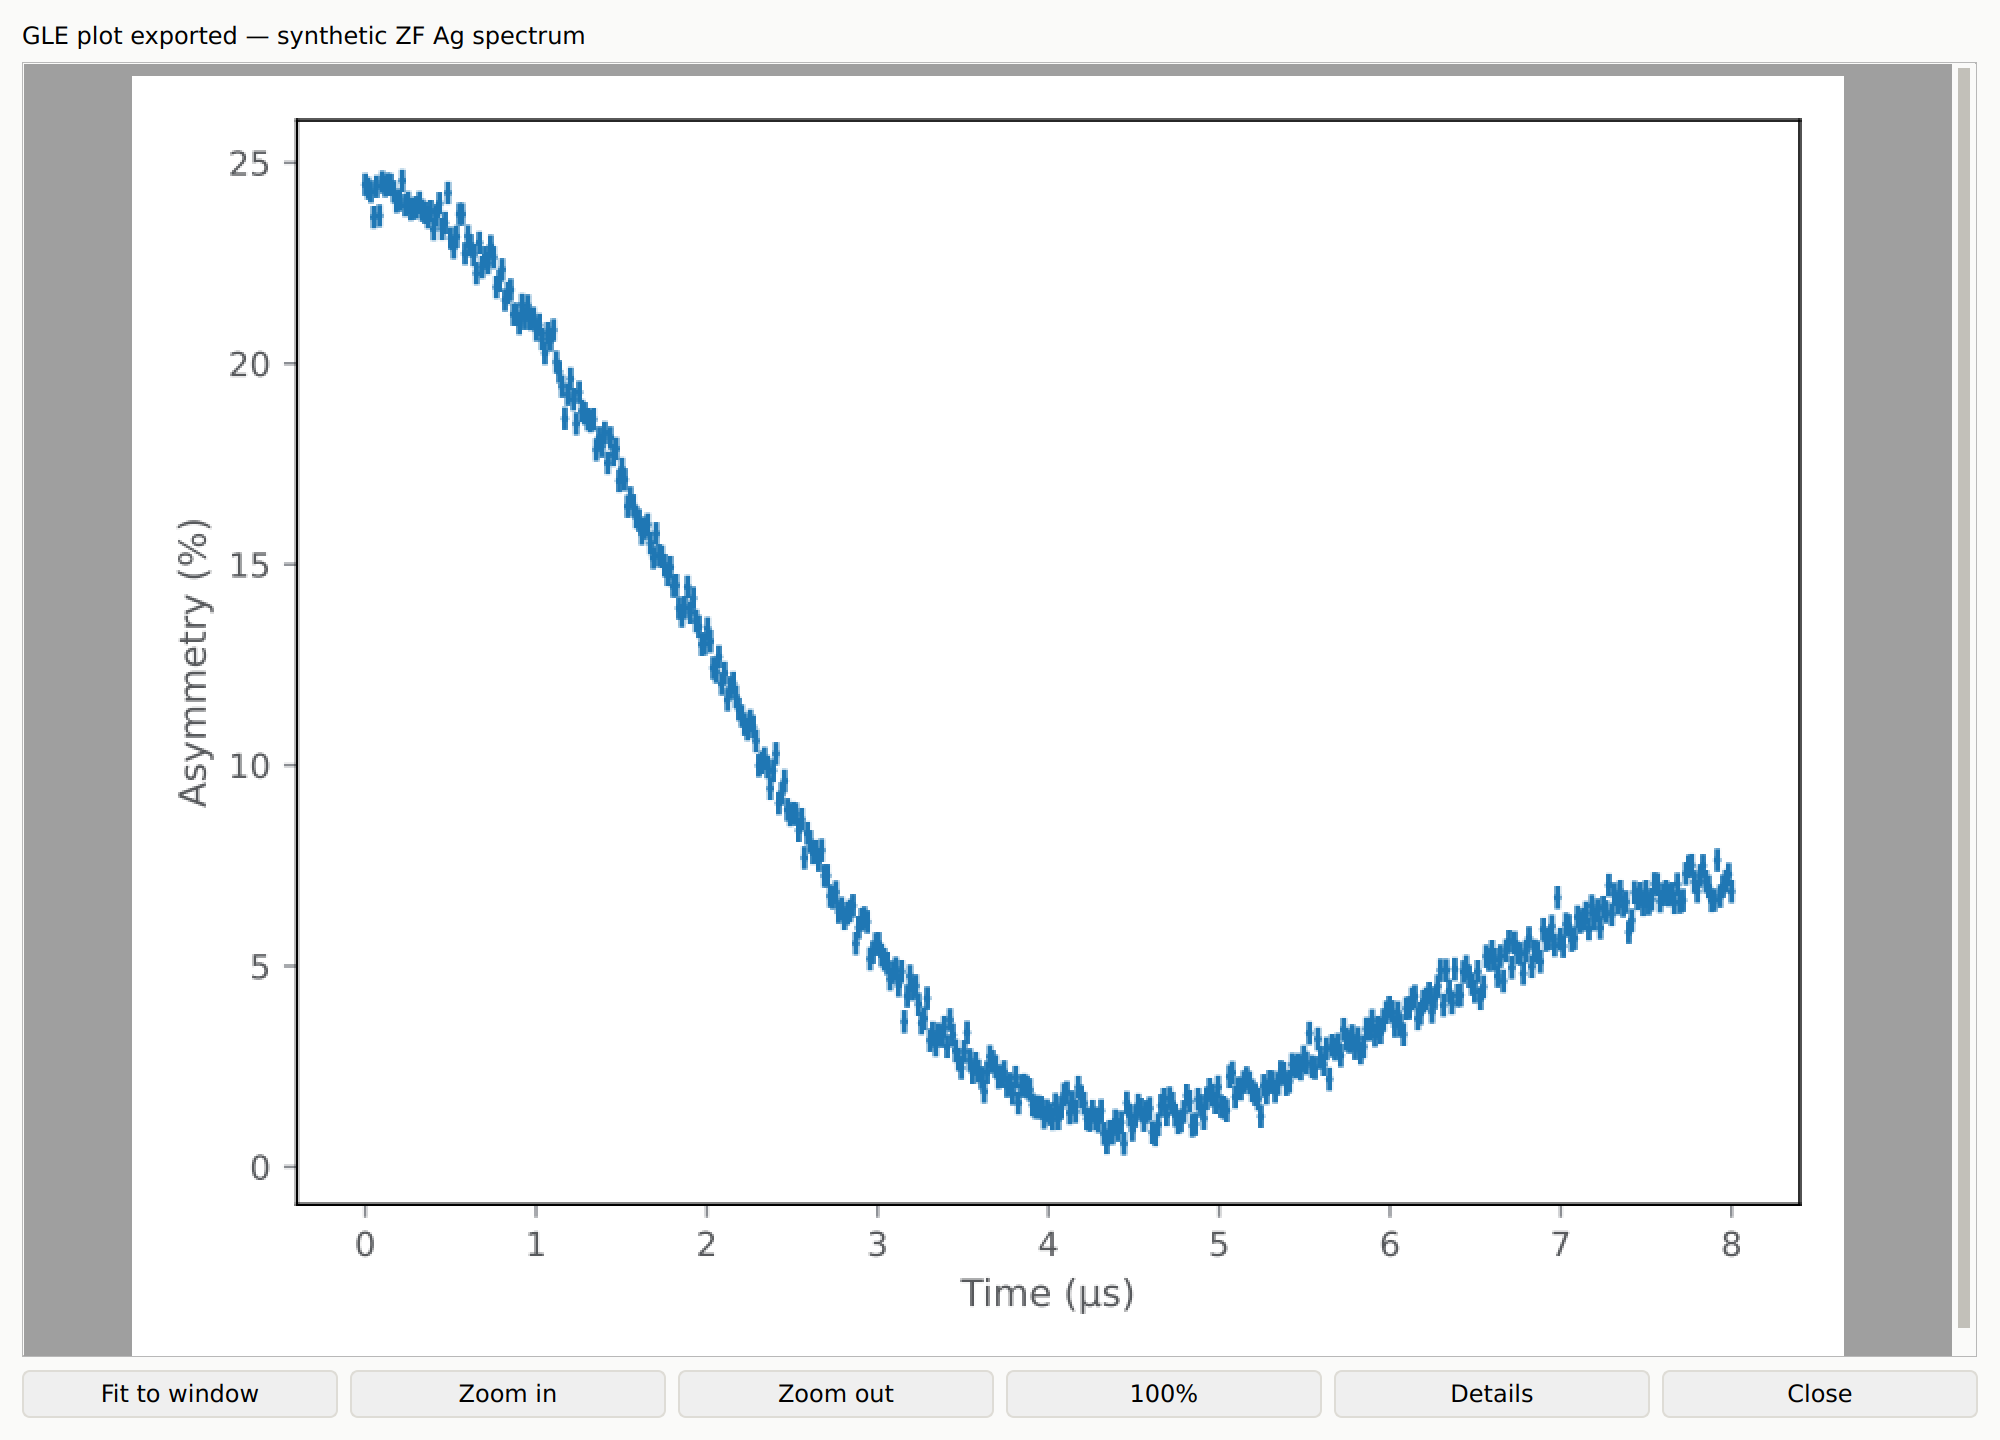
The GLE Plot Preview window displays the compiled vector figure. Use Fit to window, Zoom in, Zoom out, and 100% to inspect the plot. Drag with the middle mouse button to pan. Details shows the saved files. The window is non-modal. EPS exports include a PDF companion used for the preview. The configured Setup ▸ GLE Setup… compiler is used. Generation and compilation run in the background; Close cancels an active export. Without GLE, the script and sidecars are still saved.
Fitting panel
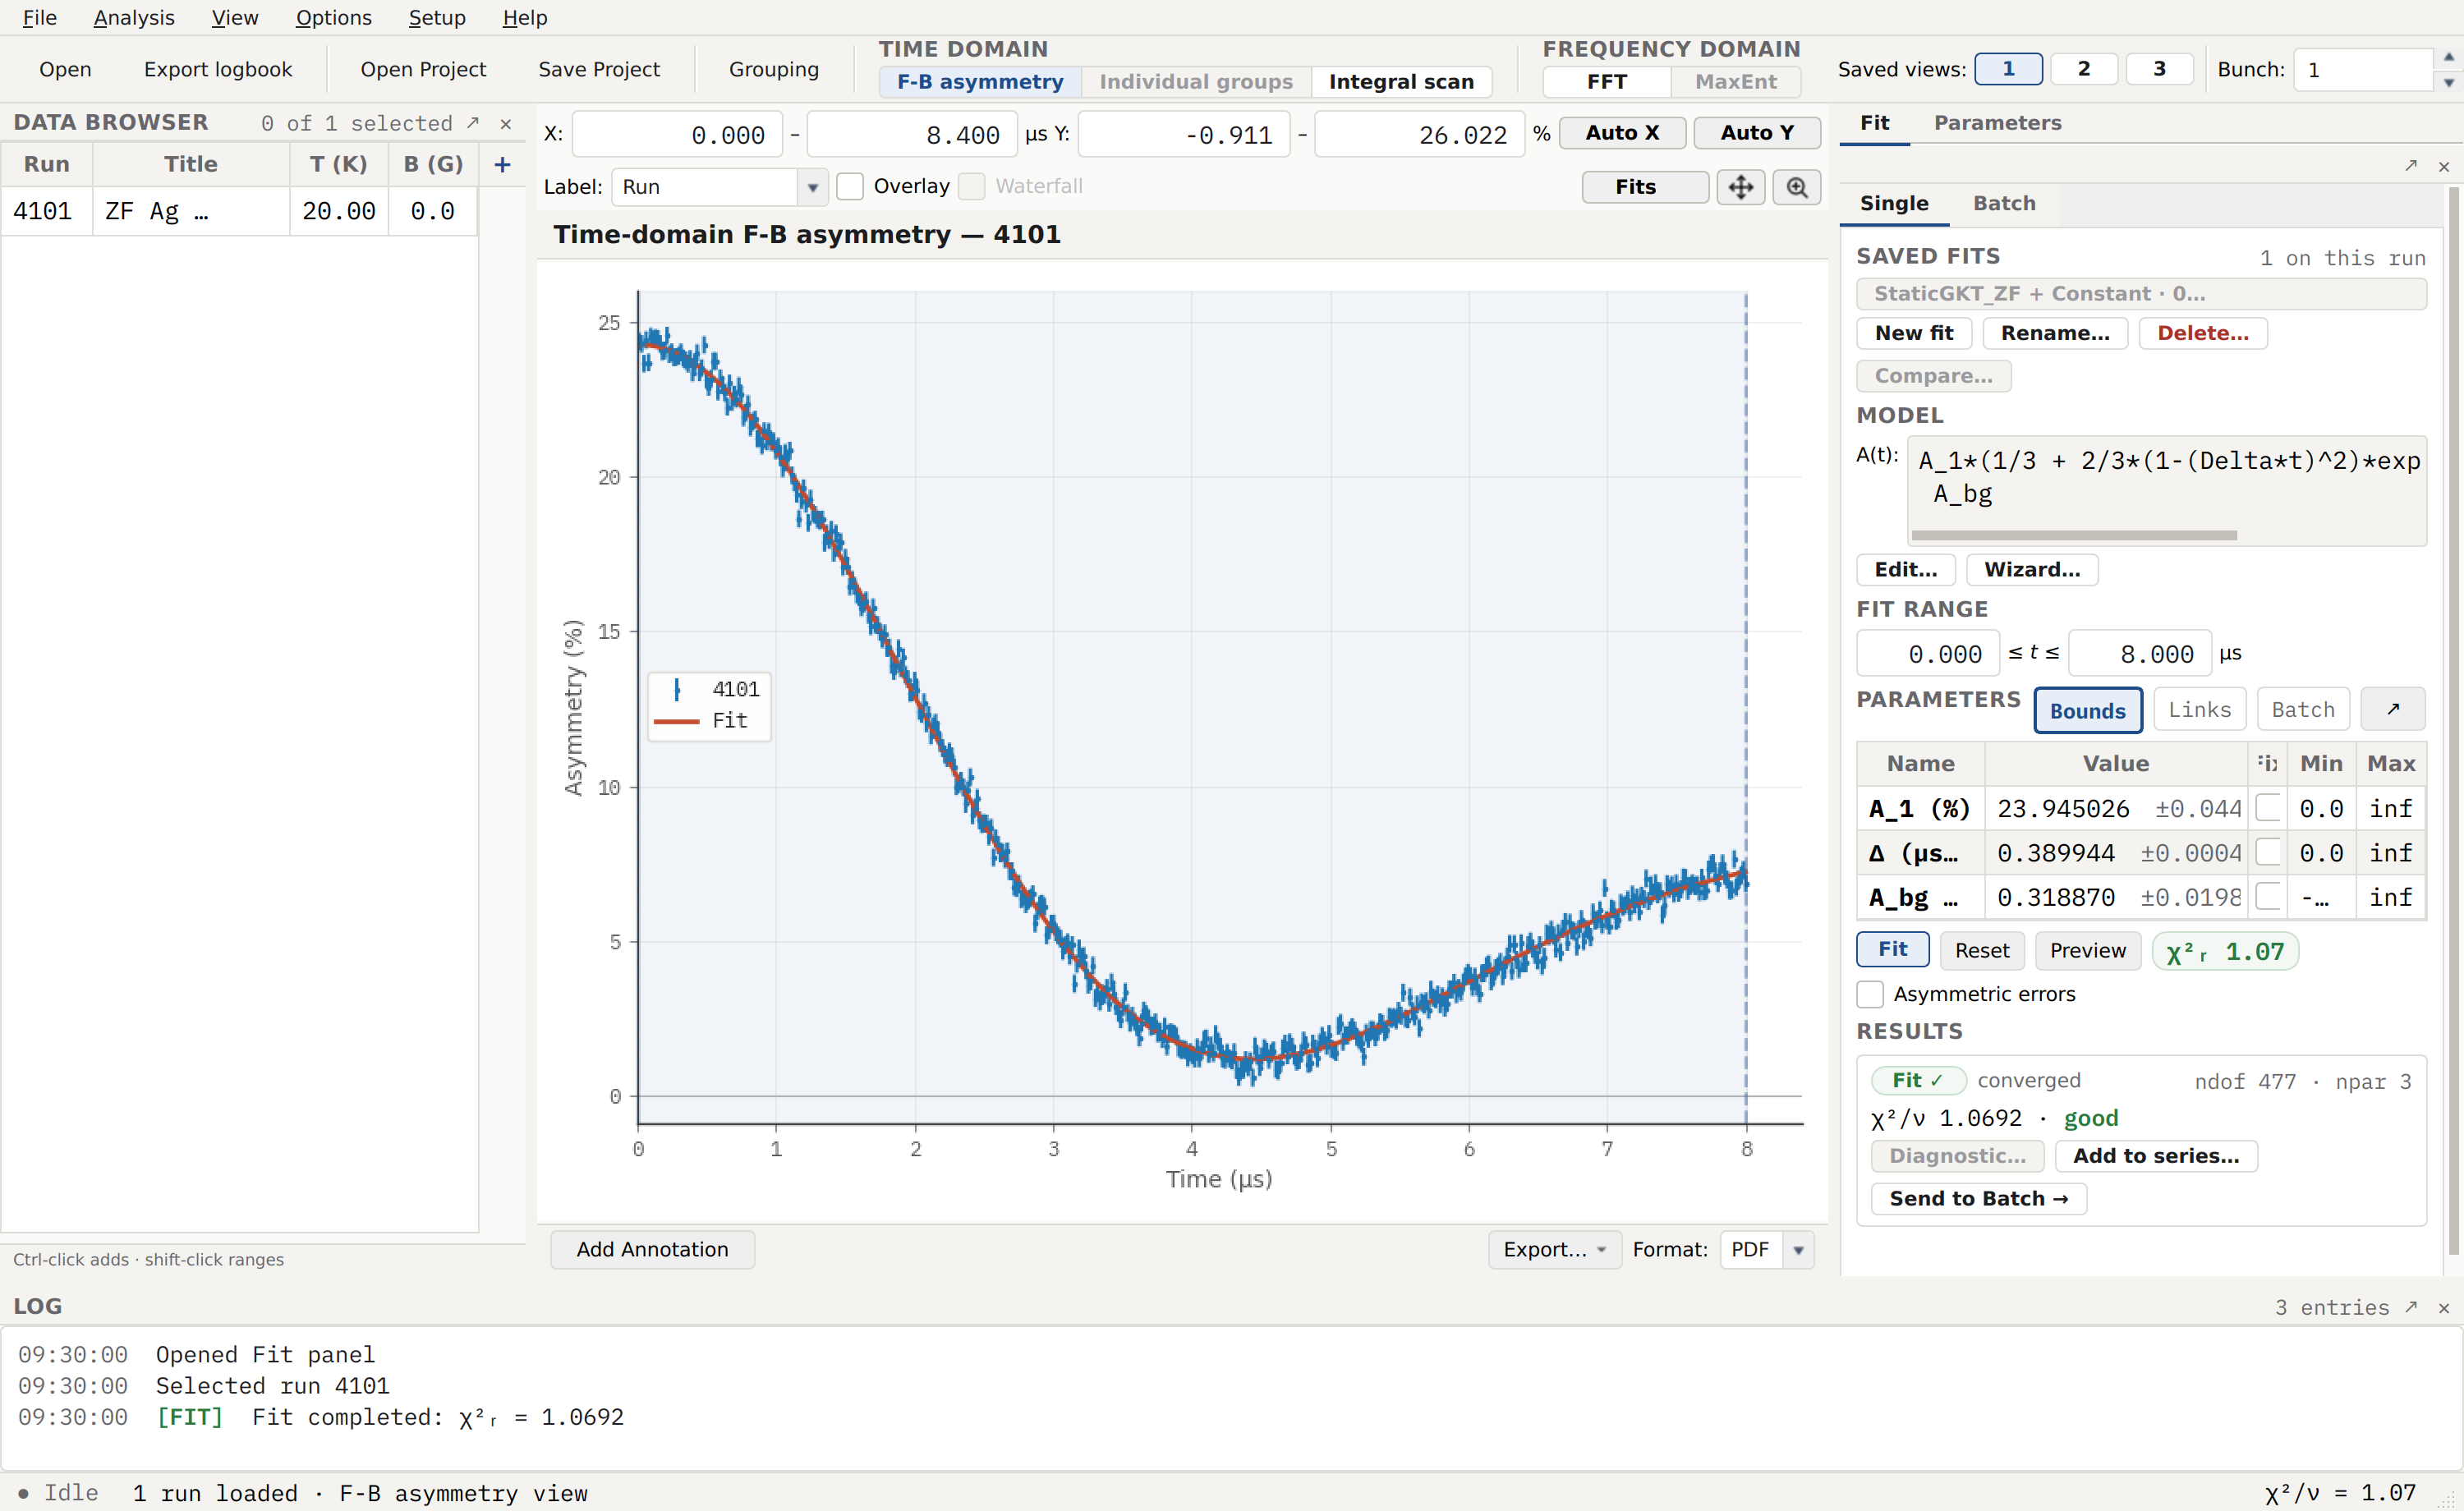
Converged static Gaussian Kubo–Toyabe fit on a synthetic ZF Ag polycrystal dataset (Δ ≈ 0.39 μs⁻¹). Ag is the canonical nuclear-dipolar reference sample at every μSR facility; the GKT function (Kubo & Toyabe, 1966) is derived in Blundell et al. Ch 5.2.
The fitting panel provides an interactive interface for fitting models to your data. It is located in the right dock area next to the plot panel, with a Single tab for one dataset and a Batch tab for several — both built from the same model row, Parameters rail, run row and Results card described below.
The fit function is shown as \(A(t)\) and is built from components using the Edit… button beside it. A Wizard… button opens the model-recommendation wizard for the active tab — Fit wizard on the Single tab, the Global Fit Wizard (Global fit wizard) on the Batch tab.
Single dataset fitting
The “Single” tab fits one composite model to the currently selected dataset. By default, the function is:
where A_bg is an explicit constant background term. A free background
absorbs part of the initial asymmetry on a run where it should not be there
to absorb — for example a light-OFF \(A_0\) calibration run — splitting
the fitted amplitude between the background and the relaxation term; remove
A_bg in the function editor (delete the Constant component) to fit
the full \(A_0\) with a single relaxation term instead.
To edit the model:
Click Edit…
Add/remove components and choose operators (
+,-,*,/)Confirm with OK
Available components in the builder:
Exponential: \(A e^{-\lambda t}\)
Gaussian: \(A e^{-(\sigma t)^2}\)
Oscillatory: \(A\cos(2\pi f t + \phi)\) — frequency \(f\) in MHz
OscillatoryField: \(A\cos(2\pi \gamma_\mu B t + \phi)\) — field \(B\) in Gauss; frequency is derived automatically from \(\gamma_\mu = 13.554\,\text{MHz/kG}\)
StretchedExponential: \(A e^{-(|\lambda|t)^\beta}\)
StaticGKT_ZF: Static Gaussian Kubo-Toyabe
LongitudinalFieldKT: Hayano LF-KT; \(B_L\) initialised from run field. See LongitudinalFieldKT.
Nuclear dipolar / MuF: Analytical single-
mu-FpolarisationNuclear dipolar / FmuF_Linear: Analytical collinear
F-mu-FpolarisationNuclear dipolar / FmuF_General: Numerical powder-averaged
F-mu-FpolarisationConstant: \(A_{\mathrm{bg}}\)
Note
The oscillatory component in the builder is pure cosine by default. If you want damping, multiply it by an exponential component.
Parameter naming rules in the table:
Additive terms get their own amplitudes:
A_1,A_2, …Every product — components chained with
*or/— carries exactly one amplitude, on the first factor that has one, soExponential * GaussianusesA_1rather thanA_1andA_2. Parentheses never change this:(Exponential) * (Gaussian)still names onlyA_1, and wrapping a multiplet’sOscillatory * Exponentialpairs in parentheses for readability does not add a second amplitude per pair.A product multiplied into a sum, such as
(Gaussian + Constant) *
Constant
, takes the sum’s amplitudes instead of its own — every leaf factor of that product is suppressed.A_bgis present by default from the constant componentOther symbols (for example
Lambda,sigma,frequency) are only indexed when duplicates exist in the same expression (for exampleLambda_1,Lambda_2)
Editing the function keeps your values
Adding, removing, moving, or duplicating a component in the builder does not
throw away the table you have already filled in. Every parameter belonging to
a component that is still in the function afterwards keeps its value, Fix
state, bounds, links, and ties — whatever the parameter happens to be called
once you confirm the edit. Inserting a component before an existing
Exponential renames its Lambda to Lambda_1, but the value you set
for it survives, because the table follows the component, not the name it
is currently spelled with. A component that is genuinely new to the function
starts from seeded defaults instead. Confirming the dialog with OK when
you have not changed the structure is therefore a no-op on the table — every
value, bound, and role is exactly as it was. Click Reset on the “Single”
tab to discard the current values instead and put every parameter back to its
default.
Typing the expression directly (Edit as text) matches the components you type against the ones already in the function by name, preserving order, so a retyped expression carries values the same way — a component whose name is unchanged keeps its values, one that is renamed, reordered past a name match, or newly introduced is treated as new and reseeded.
This carrying-forward is not specific to the Single tab: the same rule holds wherever a function-builder edit rebuilds a parameter table — the Batch tab’s run table and its grouped physics tables, the Individual Groups tables, the parameter-trend model editor, and the Simulate dialog.
Fitting workflow:
Select a dataset in the data browser (it will be plotted)
Adjust parameters in the table, below the Parameters section header. Three chips beside the header show or hide a pair of columns each: Bounds (Min/Max, on by default), Links (Link/ Tie, the equality-group selector and the affine-tie editor described in Fitting engine) and Batch (a read-only role a piped-back batch fit classified this parameter as). Hiding a column never loses what it says — a linked or tied parameter still paints a small
⇄2/ƒbadge in its Value cell. The ↗ button beside the chips pops the whole eight-column table out into its own window, with Copy TSV to copy it to the clipboard and Close to bring the table back.Column widths behave as they do in a spreadsheet: drag any column’s right edge to resize it, and the columns to its right move along (the table scrolls sideways once they run past its edge). Whatever width the other columns leave over goes to Value, so the table never ends in a band of empty grid — narrow Name and Value grows by the same amount.
Value: Initial guess for the parameter. Every value starts as a seed read off the data you are fitting — an amplitude and background from the record’s own scale,
fieldandB_Lfrom the run’s applied field, and a frequency-domain peak’s position, height and width from the displayed spectrum. A seed follows the data: select another run, or change a batch’s members, and it is derived again for what you are now fitting. As soon as you type a value, or a fit writes one back, it is yours and stays put until you Reset.Fix: Check to hold the parameter constant during fit
Min/Max: Set bounds (leave empty for no bounds) — shown when Bounds is checked
Click “Fit” to execute the fitting
The fit uses the dataset currently shown in the plot panel. Grouping and bunching are configured from the Grouping dialog and applied before fitting. Fits run asynchronously — Fit becomes Stop while one is running, and stopping it records nothing.
Review results:
Fit curve appears on the plot in red
A χ²ᵣ verdict chip appears beside Fit, coloured by the fit’s quality band; click it to open a window with the full parameter read-out for this fit
The Results card below carries the same outcome as a tag — Fit ✓ for a clean convergence, Fit ⚠ for a converged-but-flagged fit, Error on failure — plus \(\chi^2/\nu\), an
ndof/nparread-out, and any advisory warningsLog panel shows summary message
The Results card’s footer holds this run’s hand-offs as buttons: Diagnostic… opens the pull-distribution diagnostic (Conditional simulation: the pull distribution) for the last converged fit; Add to series… adds this run’s fit to an existing trend series; Send to Batch → copies the current model, its seed values and bounds into the Batch tab to start a batch fit over the selected runs. Send to Batch → copies the function rather than a result, so it needs no fit and is always enabled; the other two need a completed fit for the run currently shown.
Tips for Good Fits:
Start with reasonable initial parameter values
Use bounds to prevent unphysical values (e.g., negative amplitudes)
Fix parameters you know precisely
Look for χ²ᵣ ≈ 1 (good fit); >> 1 (poor fit); << 1 (overestimated errors)
If fit fails to converge, try different initial values or tighter bounds
Saving and comparing single fits
Deciding between two descriptions of one run — a simple exponential against a stretched one, one oscillating component against two, a fit from 0.1 μs against one that skips the first half-microsecond — means having both fits in hand at once. The Single tab therefore keeps every distinct fit you run on a run, in the same way a batch keeps every distinct series, and lets you overlay and rank them.
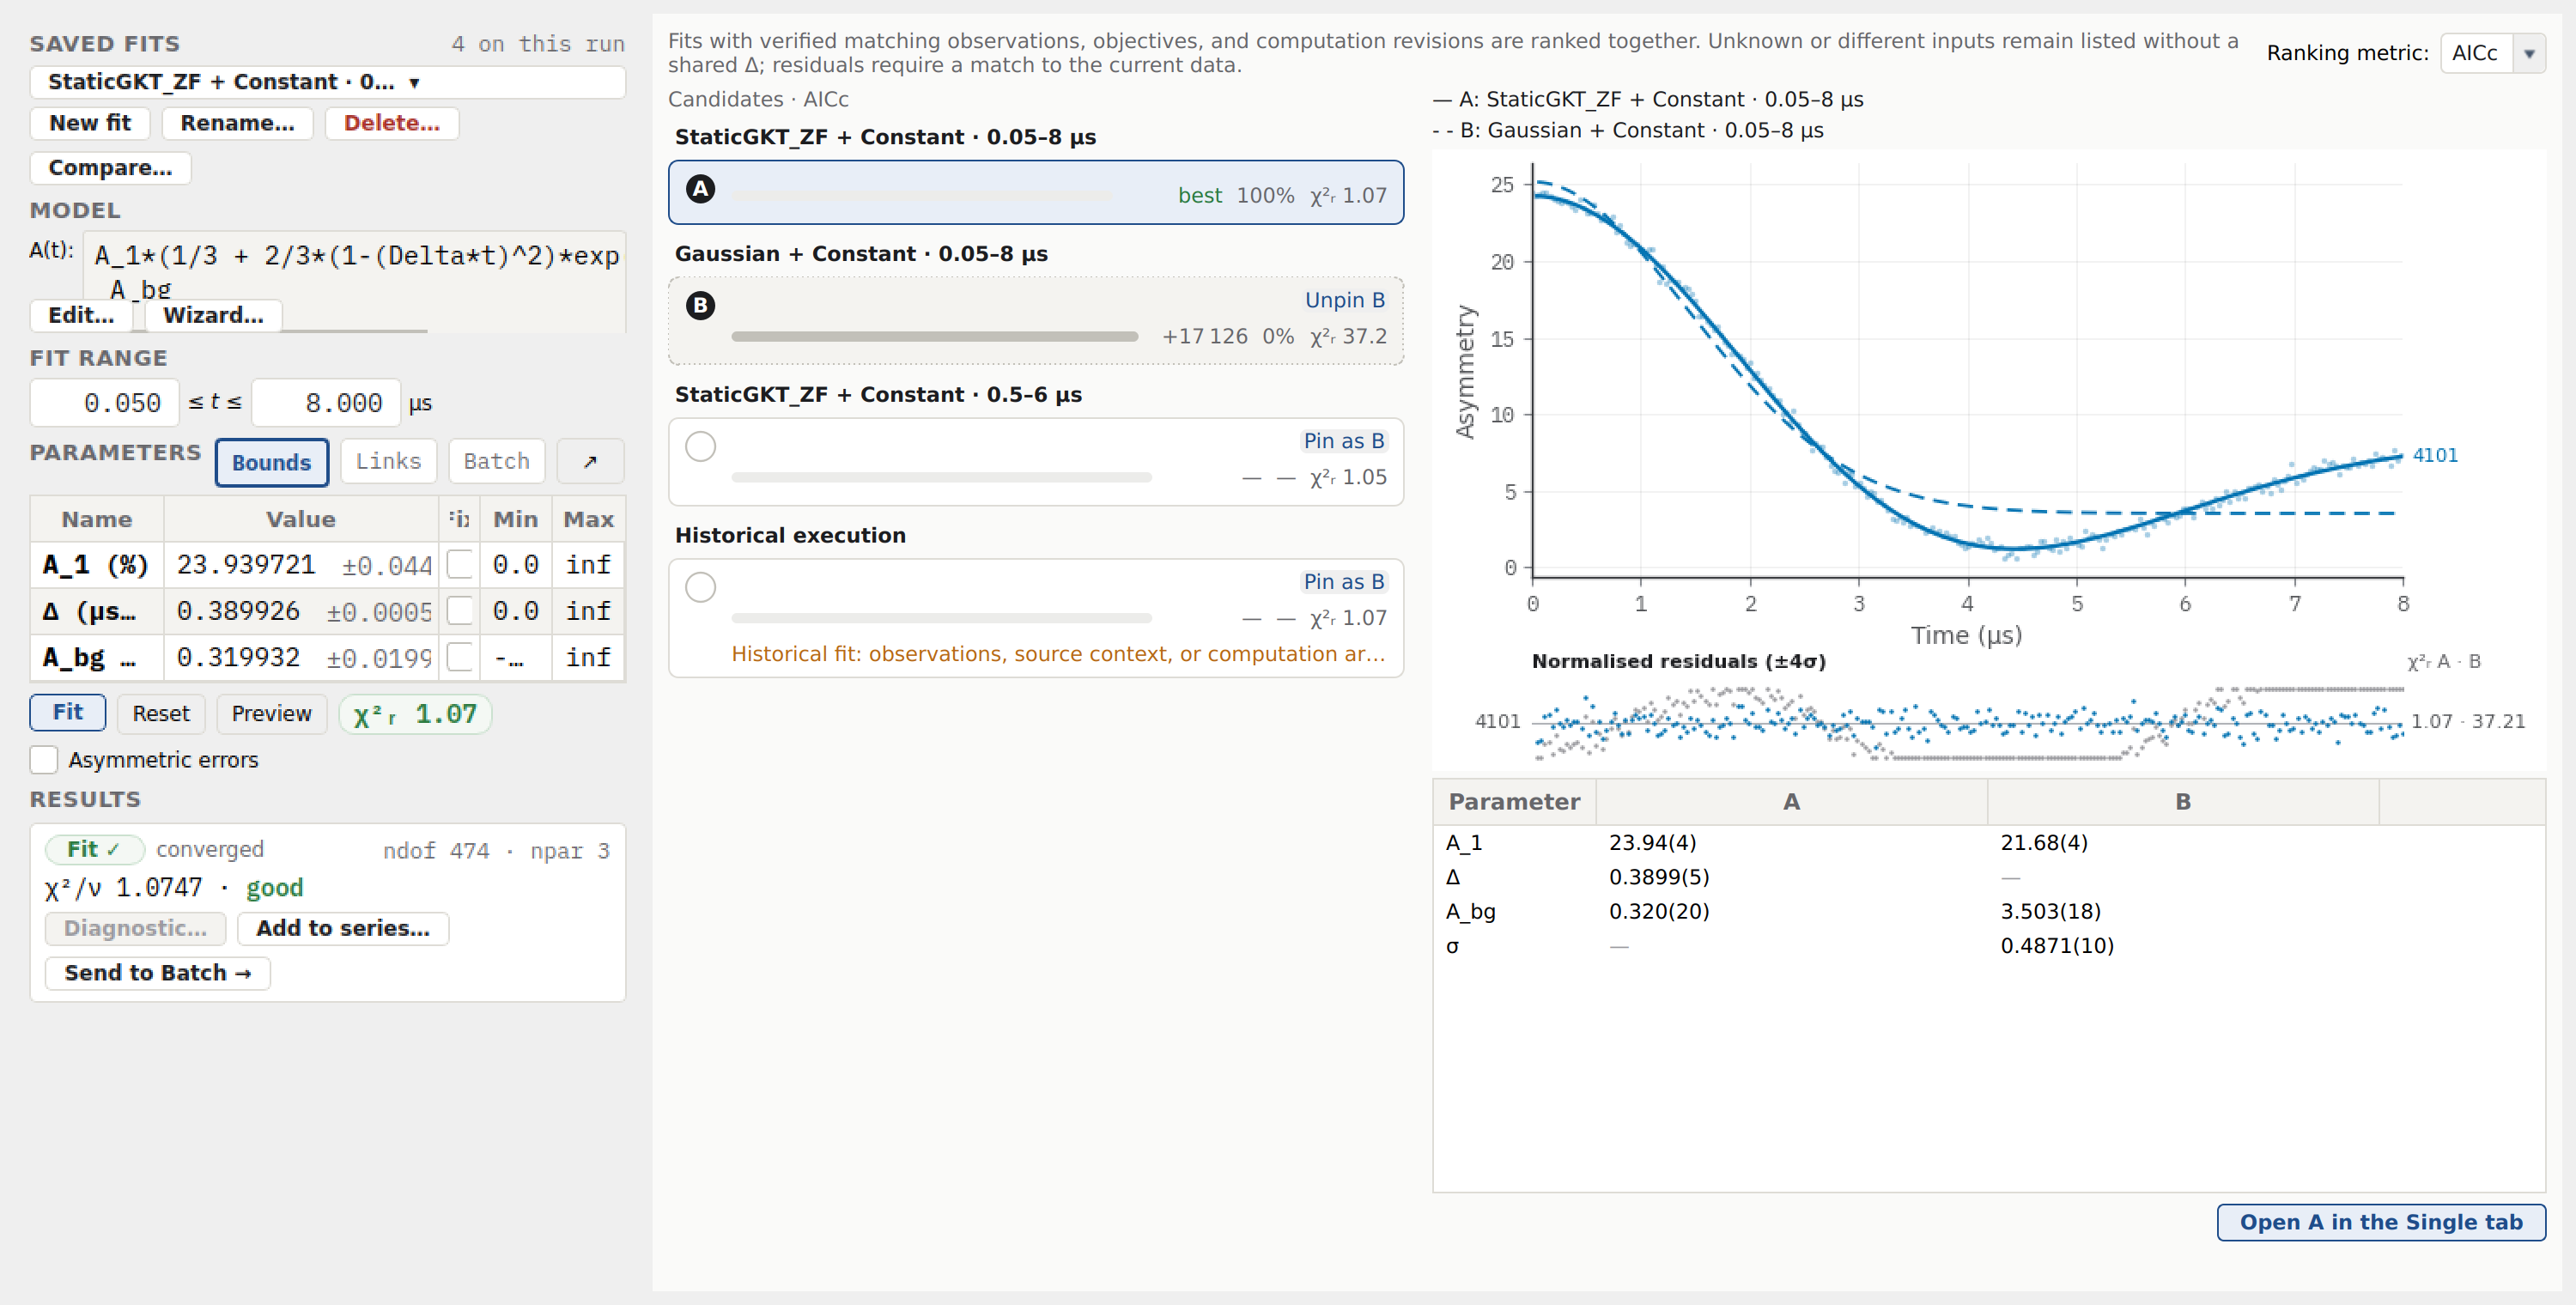
Three saved fits of one synthetic ZF Ag run (Δ ≈ 0.39 μs⁻¹). Left: the Single tab’s Saved fits row, naming the open fit. Right: the Compare window, which ranks the two fits over 0.05–8 μs against each other and lists the Kubo–Toyabe fit over 0.5–6 μs without a Δ, because it saw different data. The static Gaussian Kubo–Toyabe fit (A) is set against a Gaussian relaxation (B): the Gaussian cannot recover towards 1/3 after the dip near t = √3/Δ ≈ 4.4 μs, which its residuals show as structure and its Δ AICc of more than 17 000 rules out.
Recording is automatic. Every Fit on the Single tab is saved on the run it fitted, for the view and projection it was taken in. What happens to the fits already there depends on what the form describes:
Fitting again on verified matching observations with the same function, fit range, fixed values, links, and ties replaces the open fit, keeping its name. Seed values and bounds do not count, so iterating on starting guesses or tightening a bound refines one fit instead of growing the list.
Anything else saves a new fit beside the others, and it becomes the open one. Returning to a setup replaces its fit only when captured observations also match; changed or unknown input histories stay separate.
The Saved fits row. The Saved fits section above Model names the
open fit after its function and window (for example
Exponential + Constant · 0.1–10 µs), with the number of fits in the header
(“2 on this run”). A second fit that would read exactly like the first is
named with a (2) suffix. Once the form no longer describes the open fit, a
line under the name says what Fit will do: “Edited: the next Fit is saved
as a new fit.”, or “Edited: the next Fit replaces “name”.” when the form
matches another saved fit. The buttons below act on the run’s fits:
Click the name to open another fit; its menu lists every fit on the run with its χ²ᵣ and the time it was fitted (
χ²ᵣ 1.024 · 14:32), the open one ticked. Opening a fit restores its function, parameter table and results card, sets the fit range to its window, and draws its curve.New fit keeps the open fit and saves the next Fit beside it even when nothing has changed (“New fit: the next Fit is saved beside this run’s other fits.”) — the way to keep a second minimum of the same function found from different starting values.
Rename… names the open fit; clearing the name restores the default.
Delete… asks first (“Removes this saved fit from the run. The run’s other fits and every series are kept.”) and then opens the newest remaining fit.
Compare… opens the comparison window described below. It needs two fits on the run.
On the plot, the open fit is the run’s single fit as before. Each other saved
fit is listed in the toolbar’s Fits menu as Single fit · name, after
any series covering the run (see Batch fitting); tick it to overlay its
curve in a trace colour with its name in the legend.
Comparing saved fits. Compare… opens the Compare saved fits window
for the run. It uses the comparison panel the Fit Wizard uses for its
candidates (see Comparing candidates and applying a fit): saved fits are listed best first
on a Ranking metric — AICc by default, or AIC or BIC — each
with a bar for its difference Δ from the best fit, its evidence weight
\(w_i \propto \exp(-\Delta_i/2)\), and its χ²ᵣ. The criteria are computed
from each fit’s stored χ², counting \(k\) as its free parameters and
\(n\) as the points it fitted, with the definitions given in
the Fit Wizard’s ranking metrics. Click a row to make it A and Pin as
B on another to set it beside A: the run’s data are drawn with A solid and B
dashed above their normalised residuals, and a table sets A’s parameter values
beside B’s. Open A in the Single tab opens A as the run’s open fit.
An information criterion compares descriptions of the same data. Asymmetry also checks captured sampled coordinates, values, retained errors, usable support, interpretation, and objective before pooling rankings. Equal dimensions, run labels, or recipe identities alone do not establish that match. Δ and weights are calculated within each verified group, with the open fit’s group first. Unknown historical inputs and fits without a matching partner remain listed with Δ “—” and no weight. Historical parameter values and model curves remain available; residuals are drawn only against verified matching current data. The caption explains: “Fits with verified matching observations, objectives, and computation revisions are ranked together.” A changed or unverified input also receives a historical-fit hint in the Saved fits row; re-fitting keeps the historical result separately.
Saved fits are written into the project file, and Analysis ▸ Export fit report…
lists every saved fit by name. A fit of a rotated projection (P′_x,
P′_y) records the rotating frame it was fitted in; once that frame changes,
its menu entry carries ⚠ and the line under its name reads “Fitted in a
different rotating frame — re-run the fit to update it.” (see
Rotating-frame projection).
Carrying a model forward between runs
Selecting a different run in the Data Browser does not always blank the Single tab’s form. A run that already carries a recorded fit result — its own open saved fit (see Saving and comparing single fits), or, lacking that, the result the representation’s active series recorded for it — is protected: selecting it always restores exactly that fitted state, so it is never silently overwritten. A single fit never joins or alters a series (batch and global fits stopped writing to a member’s own fit slot); it is only ever a fallback read, so fitting the run yourself on the Single tab afterwards is what actually becomes its own protected result. Every other run is refreshable: selecting it loads the composite model and parameter setup of the most recently fitted function in the session (superseding anything it was showing before, including a hand-edited form you never fitted — the protection trigger is “did you commit by fitting”, not “did you touch the form”).
The values that described the run the form came from are re-derived for the
run it lands on: field and B_L from the newly-selected run’s applied
field, and a frequency-domain peak’s position, height and width from that
run’s spectrum. Everything else is a starting guess about the physics rather
than about a particular run, so a rate, an amplitude or a phase you typed —
or that a fit wrote back — is carried across unchanged and kept until you
click Reset. While a refreshed or carried form is showing, the Results
card carries a seeds from N tag in place of a fit outcome — hover it
for the full explanation, “Model carried from run N — not fitted for this
run” — so it is never mistaken for an actual fit of the displayed run. Only
when nothing has been fitted anywhere in the session yet does the form fall
back to carrying forward whatever was last displayed, tagged carried
seeds instead of naming a run.
Batch fitting
The Batch tab fits multiple datasets simultaneously with shared and
per-dataset parameters. It is also a series editor: it always has one
recorded series or draft open, and everything below the Series
section — model, parameter table, fit range, seeding, co-add — is that
series’ recipe. The Series section sits above Model, with a selector
button naming what is open (<group or Standalone> · <model> · <range>,
or Draft before the first run) and a status tag beside the Series
heading (Fitted n/n · HH:MM, Edited · results show last run once you
change something, or Draft). Clicking the selector opens a menu of every
series on the active representation, sectioned by owning data group, plus
New series from browser selection; New series ▾ offers the same
From browser selection, a From data group… submenu, and Copy of
current (an untouched duplicate of what is open); Duplicate,
Rename… and Delete… act on the open series itself. Selecting a
different run or group in the Data Browser never rewrites an open series —
it raises a hint instead: “You selected runs <range>, but this tab is
editing <series>. The series keeps its members until you say otherwise.”,
with New series from selection, Open a series for these runs ▾ and
Keep editing. The fit range fields edit the open series’ own window
(the plot’s range guides follow it while the Batch tab is visible); the
Single tab keeps the plot-owned, project-wide range, since a single fit is
exploration and a batch is production. A fresh draft with no prior series
inherits the project’s current range once.
A draft fits what the plot’s fit target shows. On a grouping with several
projections, clicking another subplot moves the draft’s members to that
projection — including the rotated P′_x and P′_y of the
rotating-frame projection, where runs
without a frame are listed disabled. A recorded series keeps the projection it
was fitted on.
Select multiple datasets in the data browser (Ctrl+Click or Shift+Click)
Switch to the Batch tab in the fit panel
Optionally click Edit… to customise the composite \(A(t)\)
Set parameter type in the table for each parameter:
Global: shared value across all selected datasets
Local: separate value per dataset
Fixed: held constant at the specified value
File: fixed at the per-dataset value read from the run metadata (for example
B_Lis set to the applied field in Gauss from the loaded file). Behaves like Fixed for the fit itself, but the value differs automatically for each selected dataset.
The ⓘ button beside the Parameter Classification title (“What Global, Local, Fixed and File mean”) opens a small window naming the same four roles at a glance: “Global — one value shared by every run”, “Local — fitted separately for each run”, “Fixed — held at its seed value”, “File — taken from each run’s metadata (field, temperature)”. Clicking anywhere else closes it again. A Bounds chip beside it (off by default) shows the same Min/Max pair the Single tab has; the ↗ button pops the table out with every column shown.
Set each run’s starting values under Seeding: the combo chooses how a run is seeded — independent seeds for every run, or each run chained from the previous one’s converged fit, which suits an ordered temperature or field scan — and Per-run seeds… opens a dialog to edit individual runs’ values directly.
Click “Run series”
Batch/global fitting follows the same rule: current grouped/bunched dataset settings are applied to each selected dataset before fitting. Once a run completes, the run row’s outcome chip reads the count of runs that converged cleanly beside the count that failed or converged with a warning — for example
3 ✓ 1 ⚠— with the full sentence on its tooltip.
After a batch or global fit completes:
Fit curves appear on the plot for all datasets. A run that already carried another fit — its own single fit, or its place in a different series — is covered by the plot toolbar’s Fits button, which reads
Fits · 2for a run holding two fits and opens a menu listing them all — active series first (marked●), the run’s own Single fit last. Tick an entry to draw its curve, untick it to hide it (Tick = show · ● = active series). The menu never changes which series is active: that is chosen on the Batch tab or by pressing a chip in the Parameters panel. The button reads plain Fits for a run holding one fit, and is hidden while the run has none, so an empty plot row is no wider than before.The Results card carries a Batch ✓/Batch ⚠ tag, an “N of M converged” headline, and one verdict chip per run (for example
3001 ✓ 0.98, coloured by that run’s own fit quality); click a run’s chip to open its fitted-parameter windowThe tab’s own notice says what the run did to the record: “Re-ran <name> — results replaced.” for an identical re-run, or “Saved as a new series: <name>.” otherwise (see Group-bound series and staleness in Parameter trending)
Use as seeds — enabled when the batch’s own diagnostics find a cleaner descending-frequency ordering across the runs that fitted well — fills the per-run seed table with values interpolated from that ordering and re-runs the series; Trends → brings the Parameters panel to the front with this series already selected
The Global Parameter Fit window opens automatically when the fit has at least one Global parameter (see below)
The log panel shows a summary with average χ²ᵣ
The results are recorded onto the open series — the one named in the Series selector — and that series becomes the active one for this representation, so its overlay is what the plot draws by default on every run it covers (see Data groups above and Group-bound series and staleness in Parameter trending)
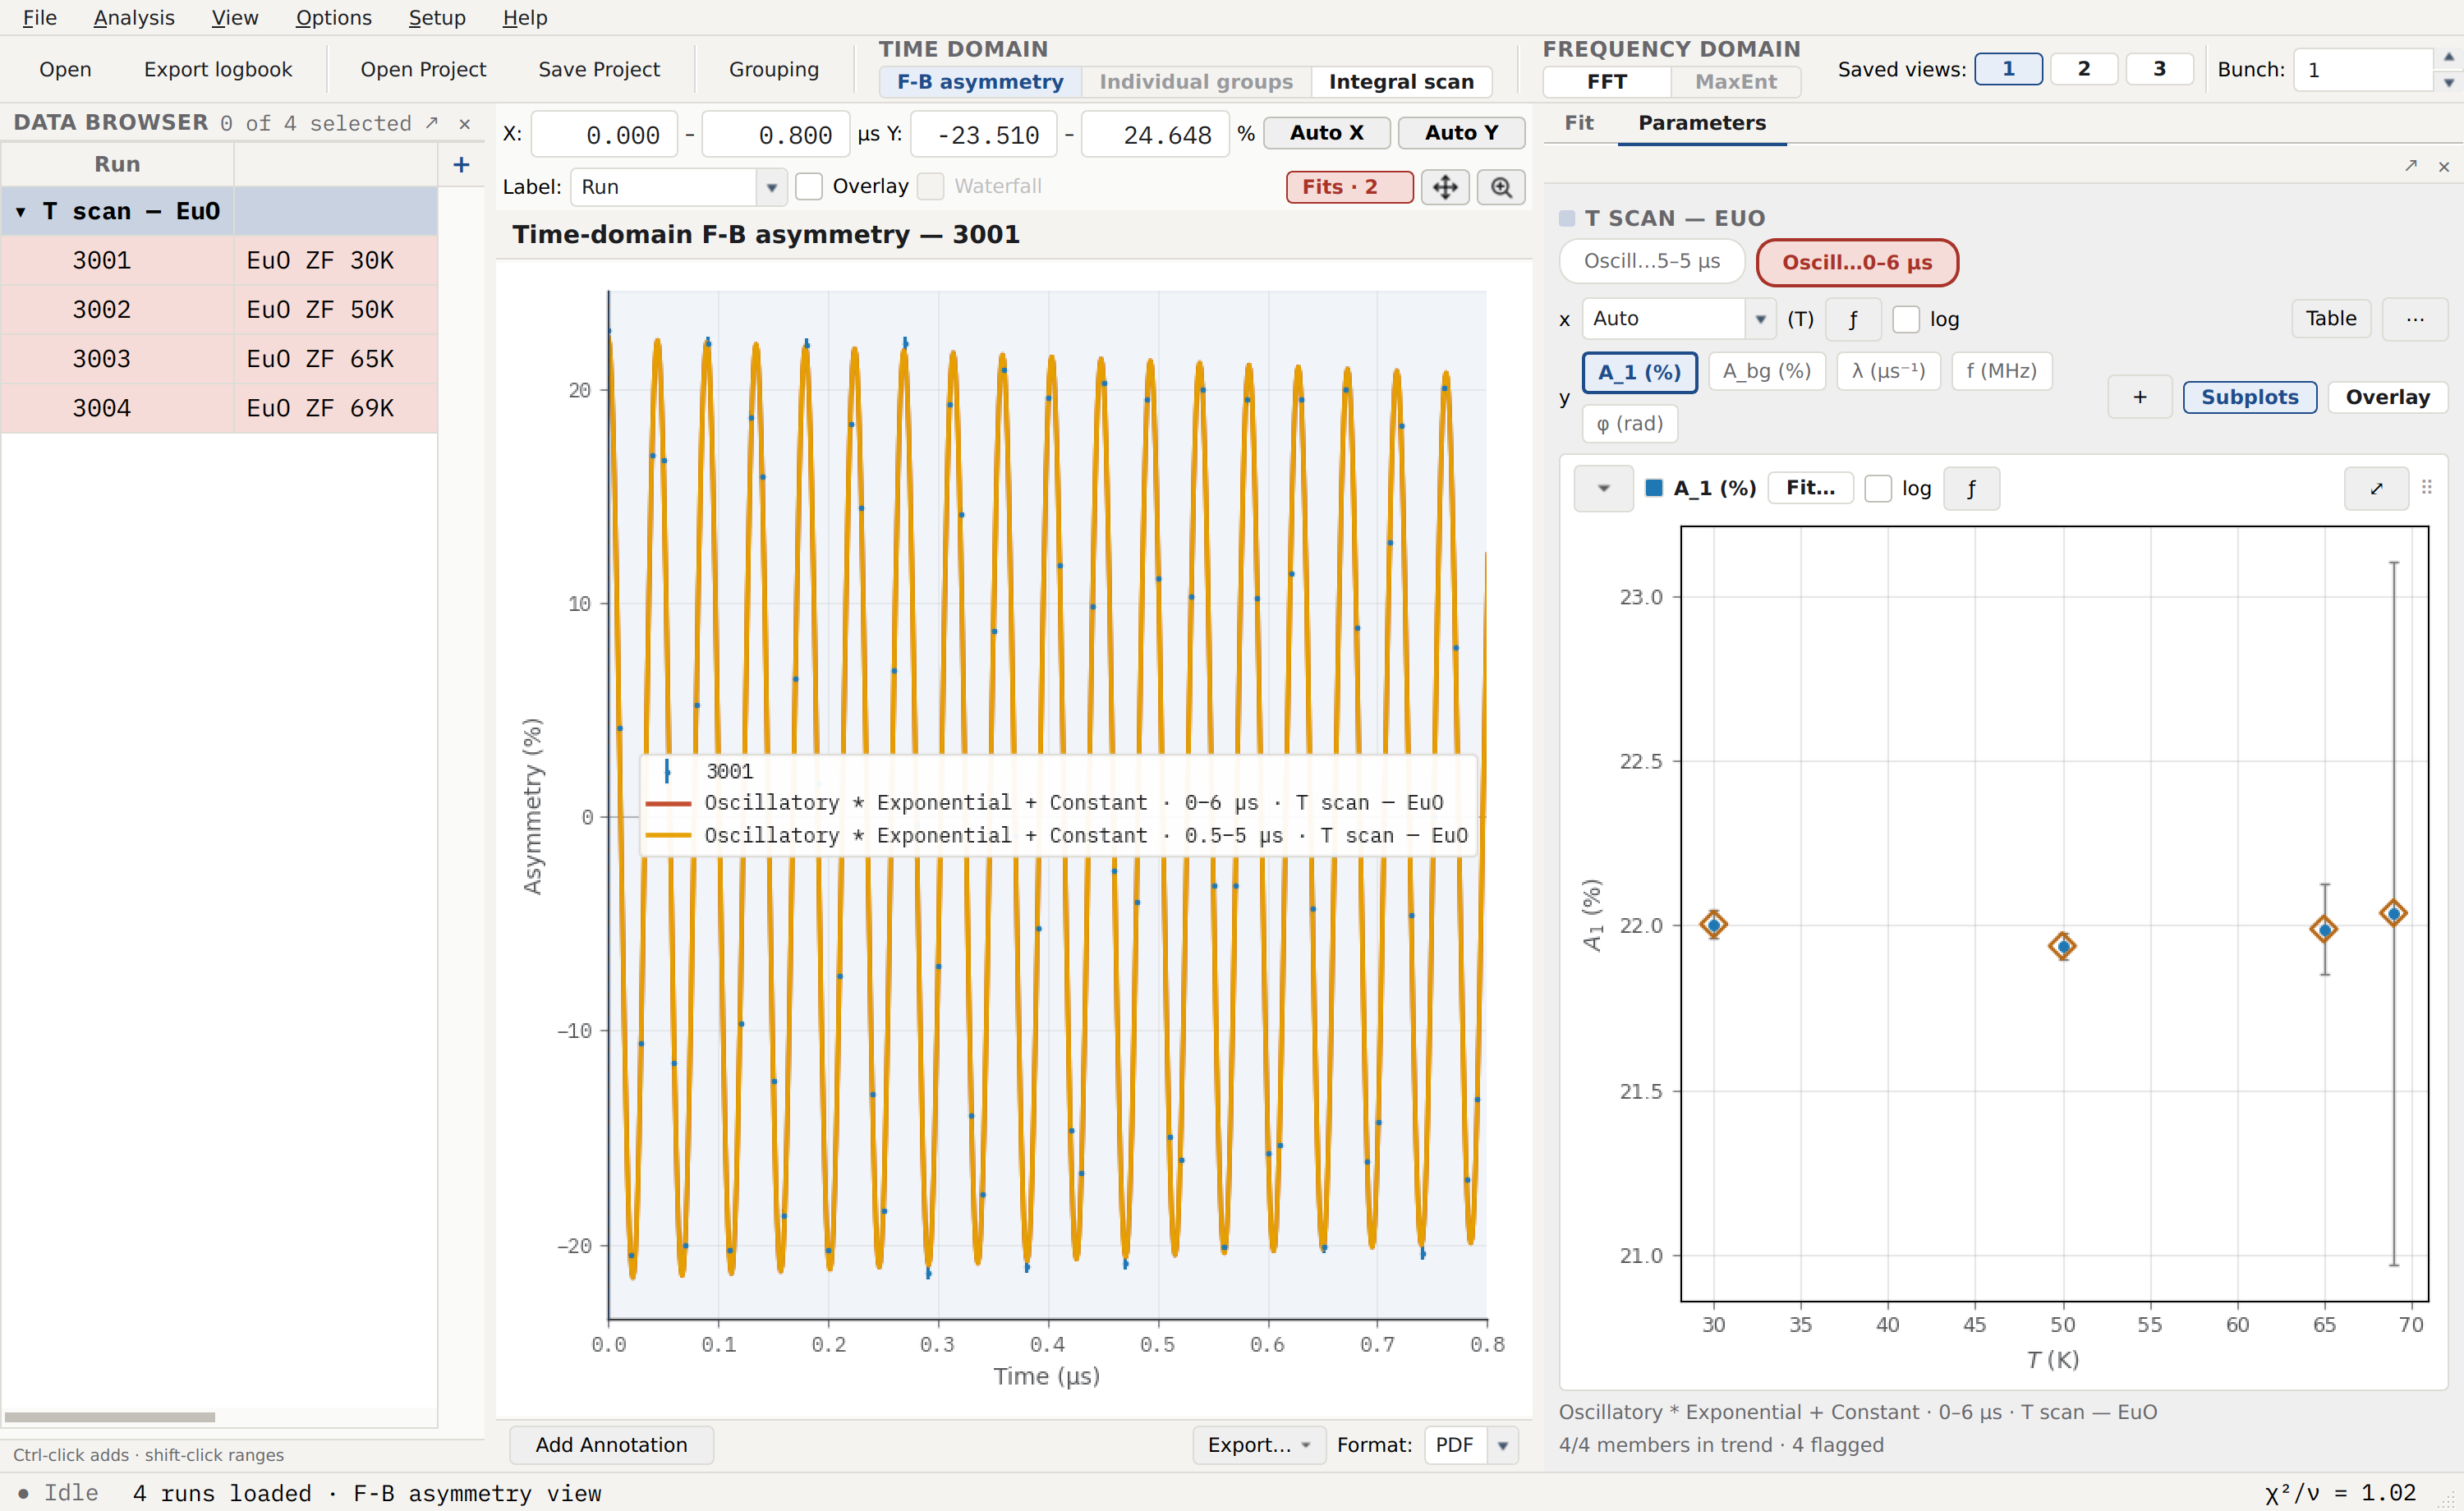
A run belonging to two series — a real 0.5–5 µs and 0–6 µs batch fit over the same EuO group, zoomed to resolve the ~22 MHz precession — with the toolbar’s Fits · 2 button flagging both and both curves drawn. The active series (the wider window, opened most recently) draws in the fit accent colour; the other takes a trace colour, though the two agree closely enough over their shared window that one mostly hides the other — a fitted curve is never extrapolated past its own recorded range, so only the wider series draws before 0.5 µs, the one visible difference at this zoom. The button’s menu would untick either curve to hide it without discarding it.
Fitting a group directly
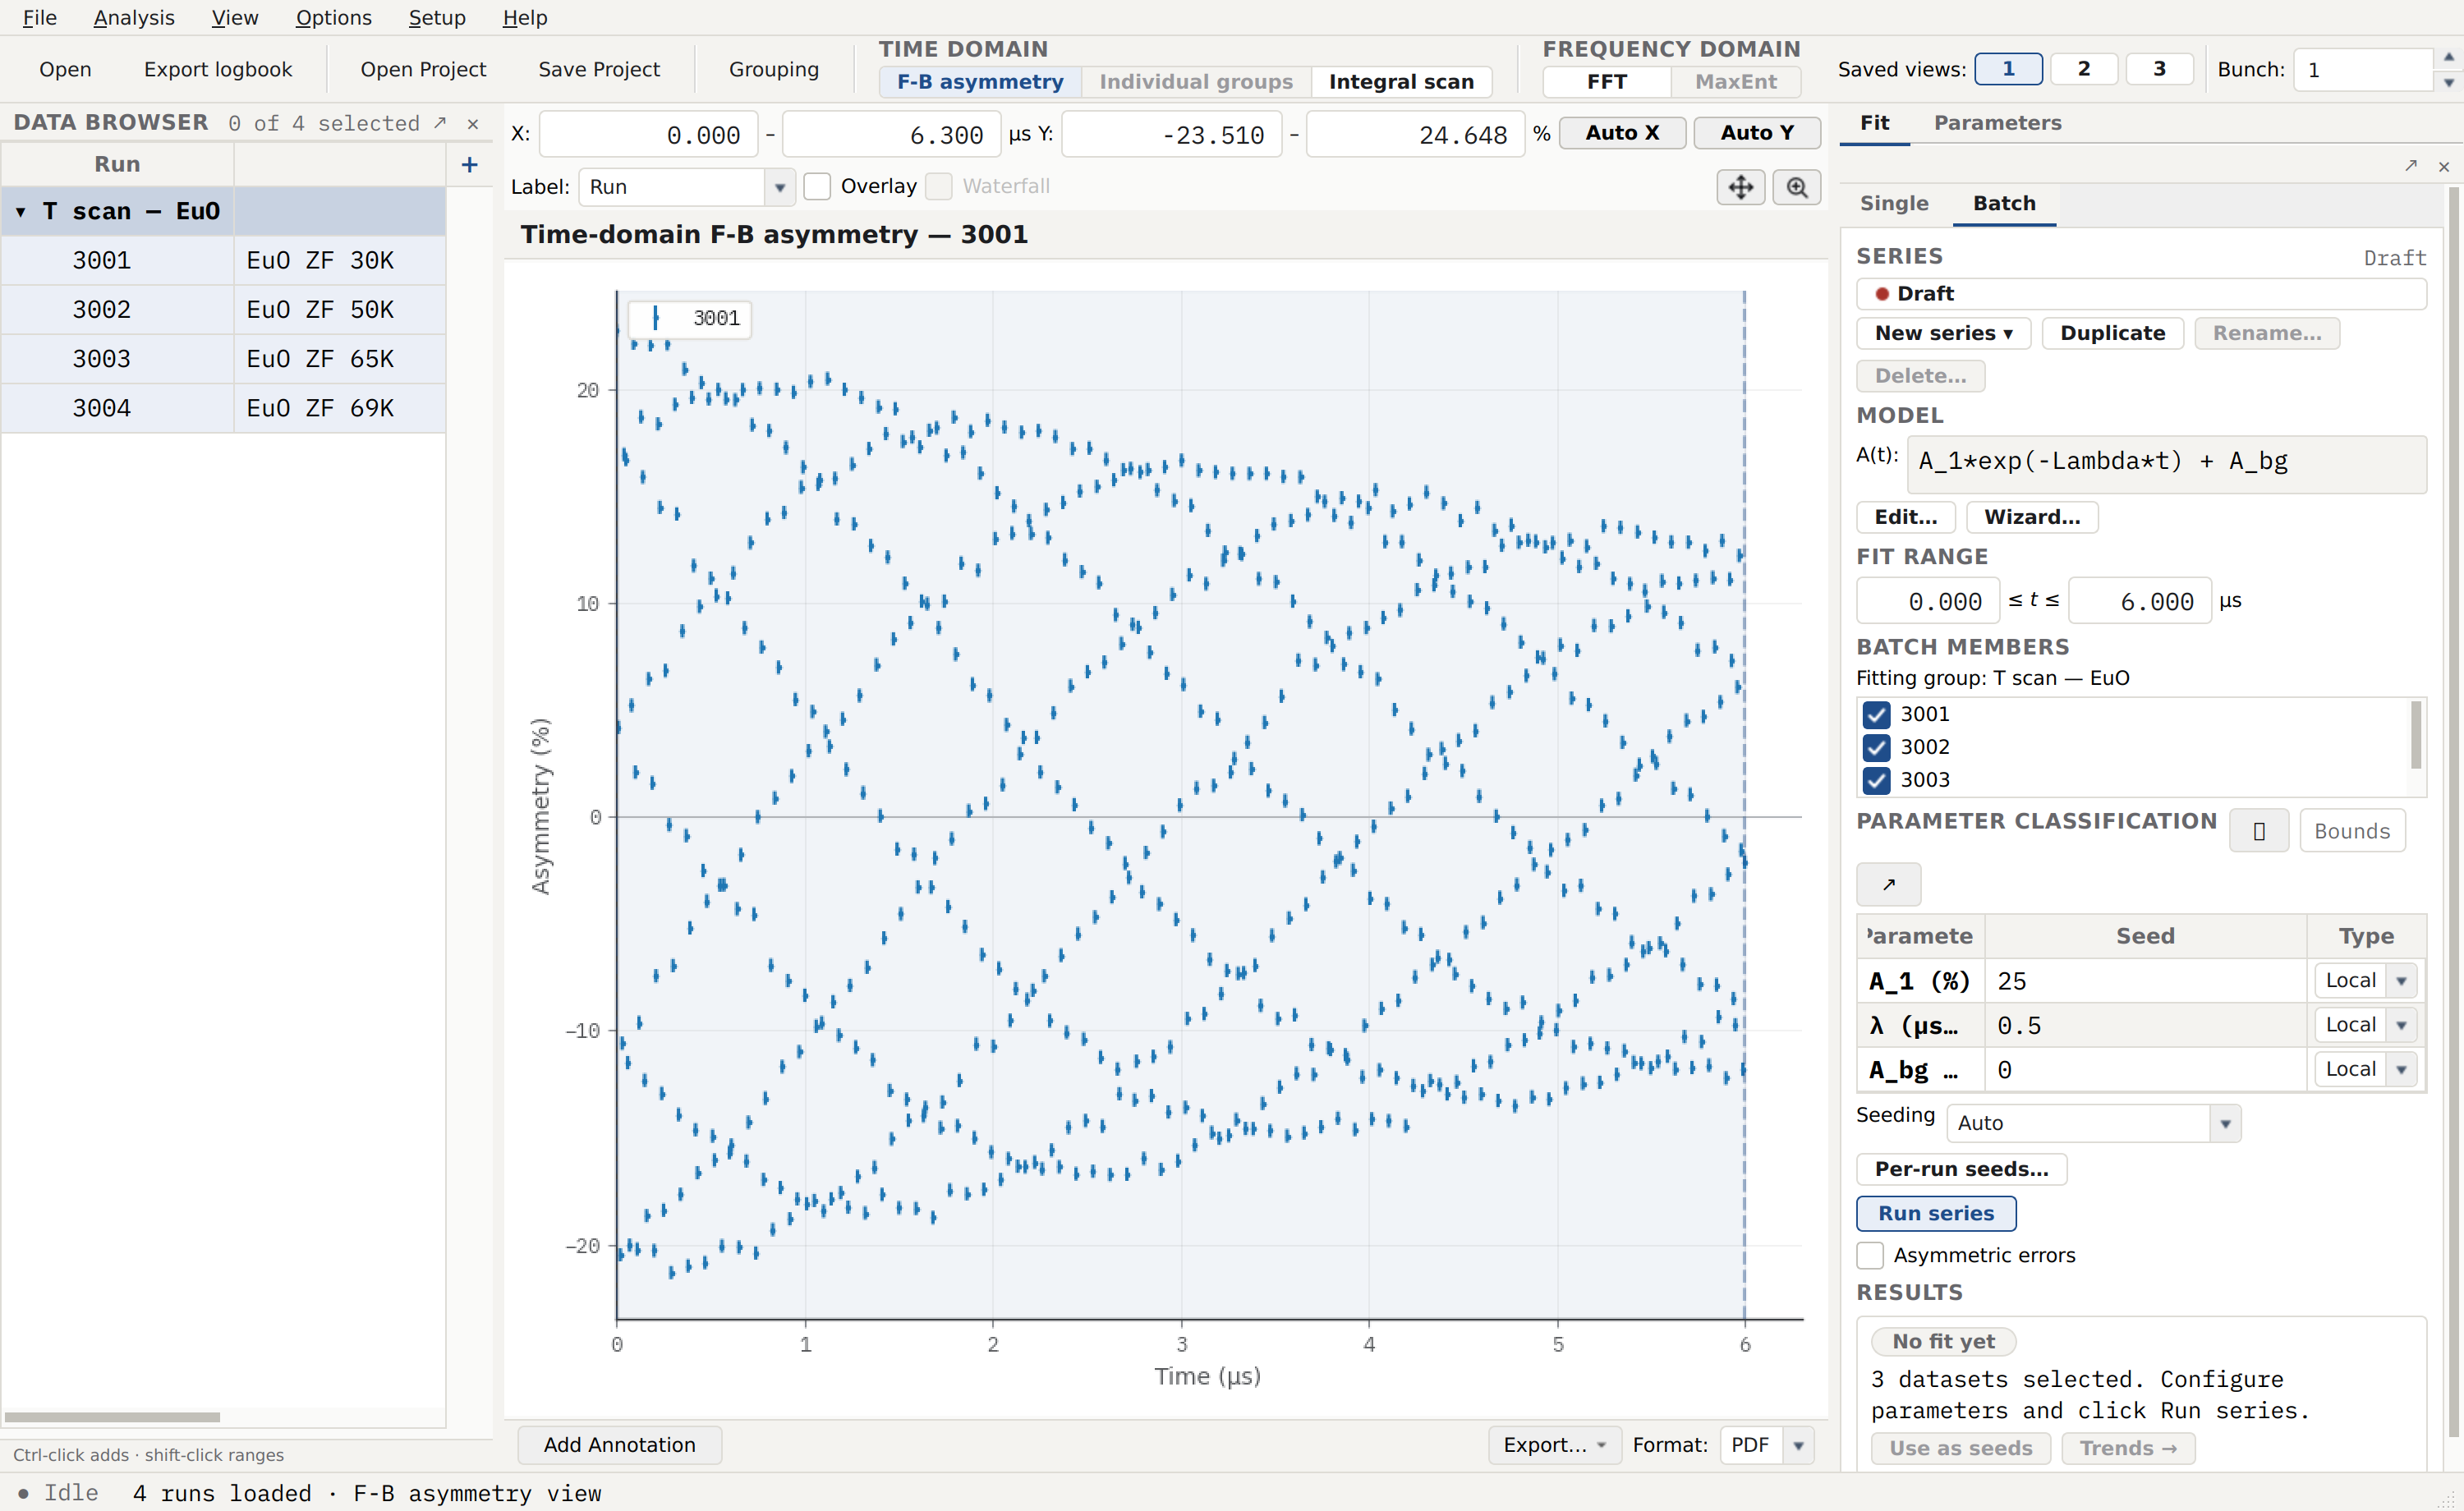
The Batch tab bound to the “T scan — EuO” group via Fit this group…*,* before its first run: the Series section reads Draft (no series recorded yet), and the Batch members checklist has the 69 K run unticked — excluded from this analysis without leaving the group.
Choosing Fit this group… from a data group’s context menu (rather than just selecting its runs) binds the Batch tab to that group: a Fitting group: <name> banner appears above a new Batch members section listing every member run with a checkbox (three at a time, scrolling for a longer batch). Untick a run to exclude it from this analysis without removing it from the group — the exclusion is recorded on the fit series, not the group, so the same group can still be fit a second time with a different model over its full membership. When the group already owns a series, the draft is seeded from its newest one’s recipe, so the natural next run is either an identical re-run or a deliberate variation; a group with none falls back to the tab’s own defaults, as above. An ordinary run selection (rather than Fit this group…) never touches an open series — it raises the “selection differs” hint described above instead.
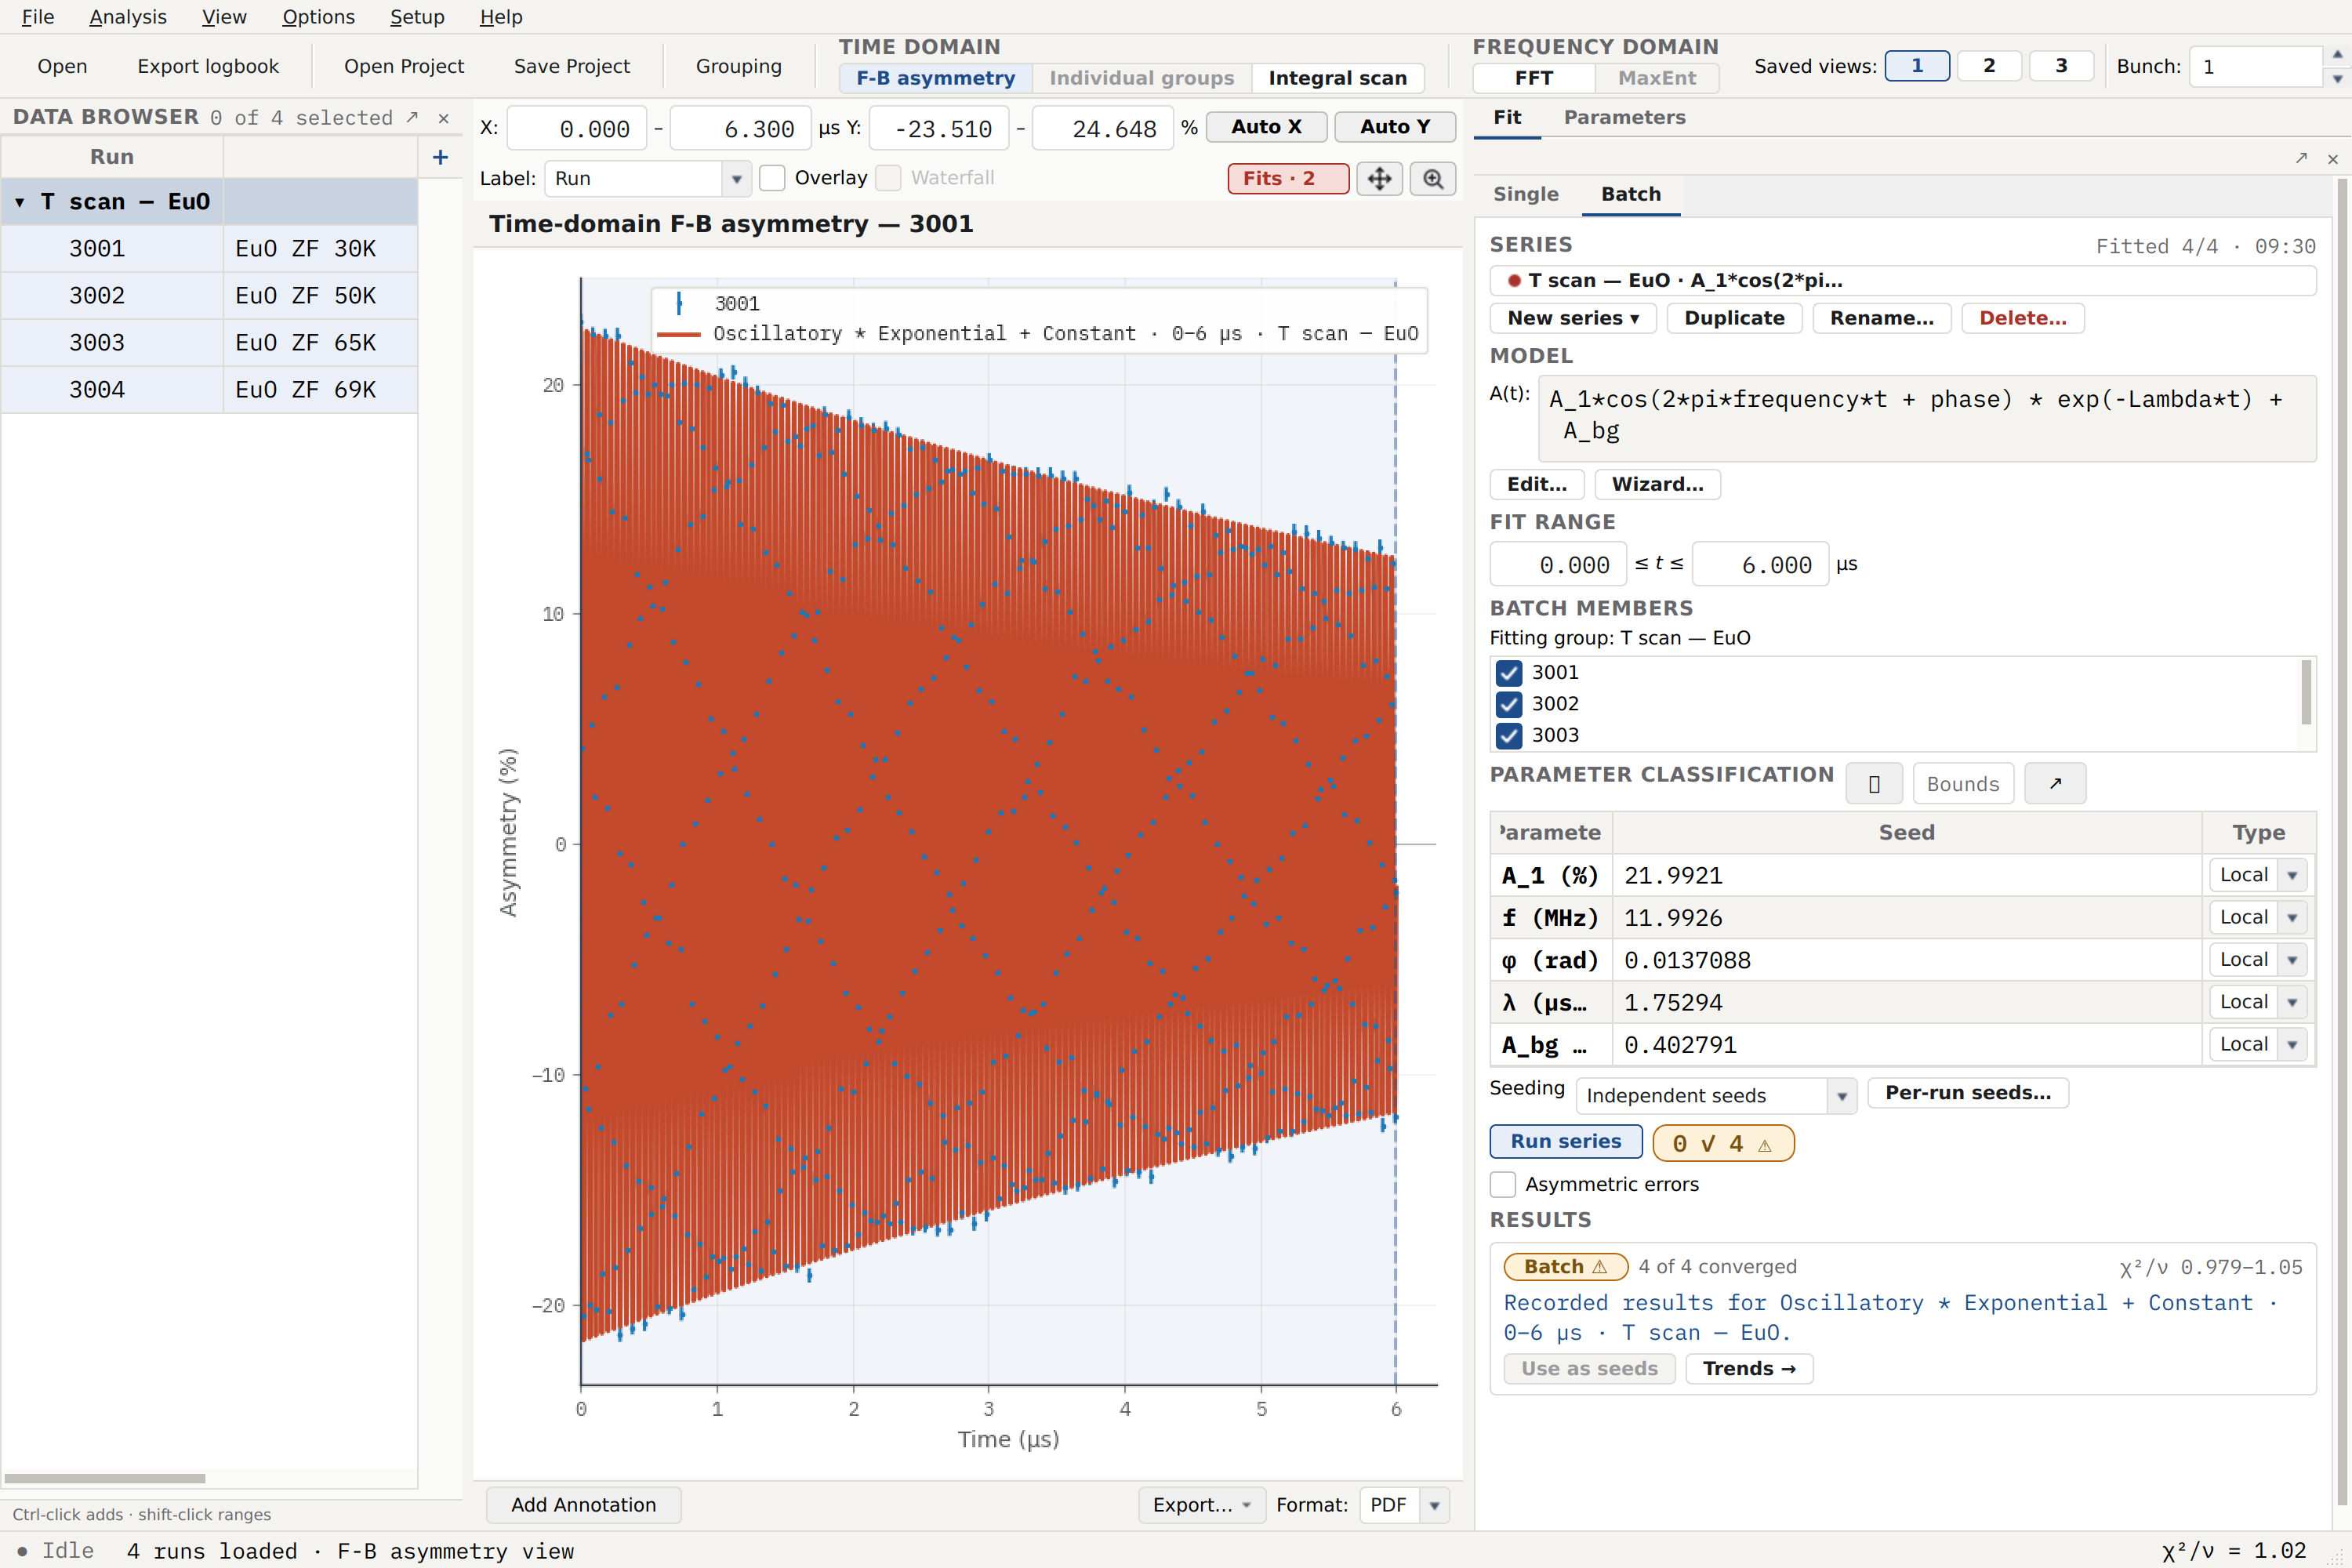
The same group after two real batch fits, both converging on the same
injected precession (χ²ᵣ ≈ 1 for all four runs): widening the fit range
from 0.5–5 µs to 0–6 µs before the second run is a recipe
change, so it records a second series rather than replacing the
first — the group now owns two, and the newer (wider) one is open, its
Series status tag reading Fitted 4/4 and its Results card
replaying the recorded outcome. Re-running this same setup unchanged
would instead replace it in place; see Group-bound series and staleness
in Parameter trending.
Grouped time-domain fitting
Asymmetry also supports WiMDA-style grouped count fitting inside one selected run.
Use this mode when you want one shared physical function across several group traces from the same dataset rather than one simultaneous fit across several different runs.
The main plot workspace now has three top-level tabs:
FB Asymmetry
Individual Groups
Frequency Domain
To launch grouped fitting:
switch the central workspace to Individual Groups
click Fit to replace the normal fit dock with the Multi-Group Fit controls
In that workflow:
the plot switches to stacked grouped time-domain subplots for the active dataset
the grouping definitions come from the current Grouping dialog payload
the fit UI splits into Per-Group Parameters and Fit-Function Parameters blocks
grouped runs are fitted in count space using lifetime-corrected grouped traces
switching the central workspace back to FB Asymmetry restores the regular fit dock
The Multi-Group Fit window’s Single and Batch tabs use the same model row, Parameters rail and Results card as the main fit dock. The single-group tab’s card offers Send to Batch → to copy its model and seeds into the grouped Batch tab; the grouped Batch tab’s card offers Use as seeds and Trends → exactly as the plain Batch tab’s does, with one verdict chip per fitted group series member.
See Grouped time-domain fitting for the detailed workflow and current limitations of this first implementation slice.
Global parameter fit window
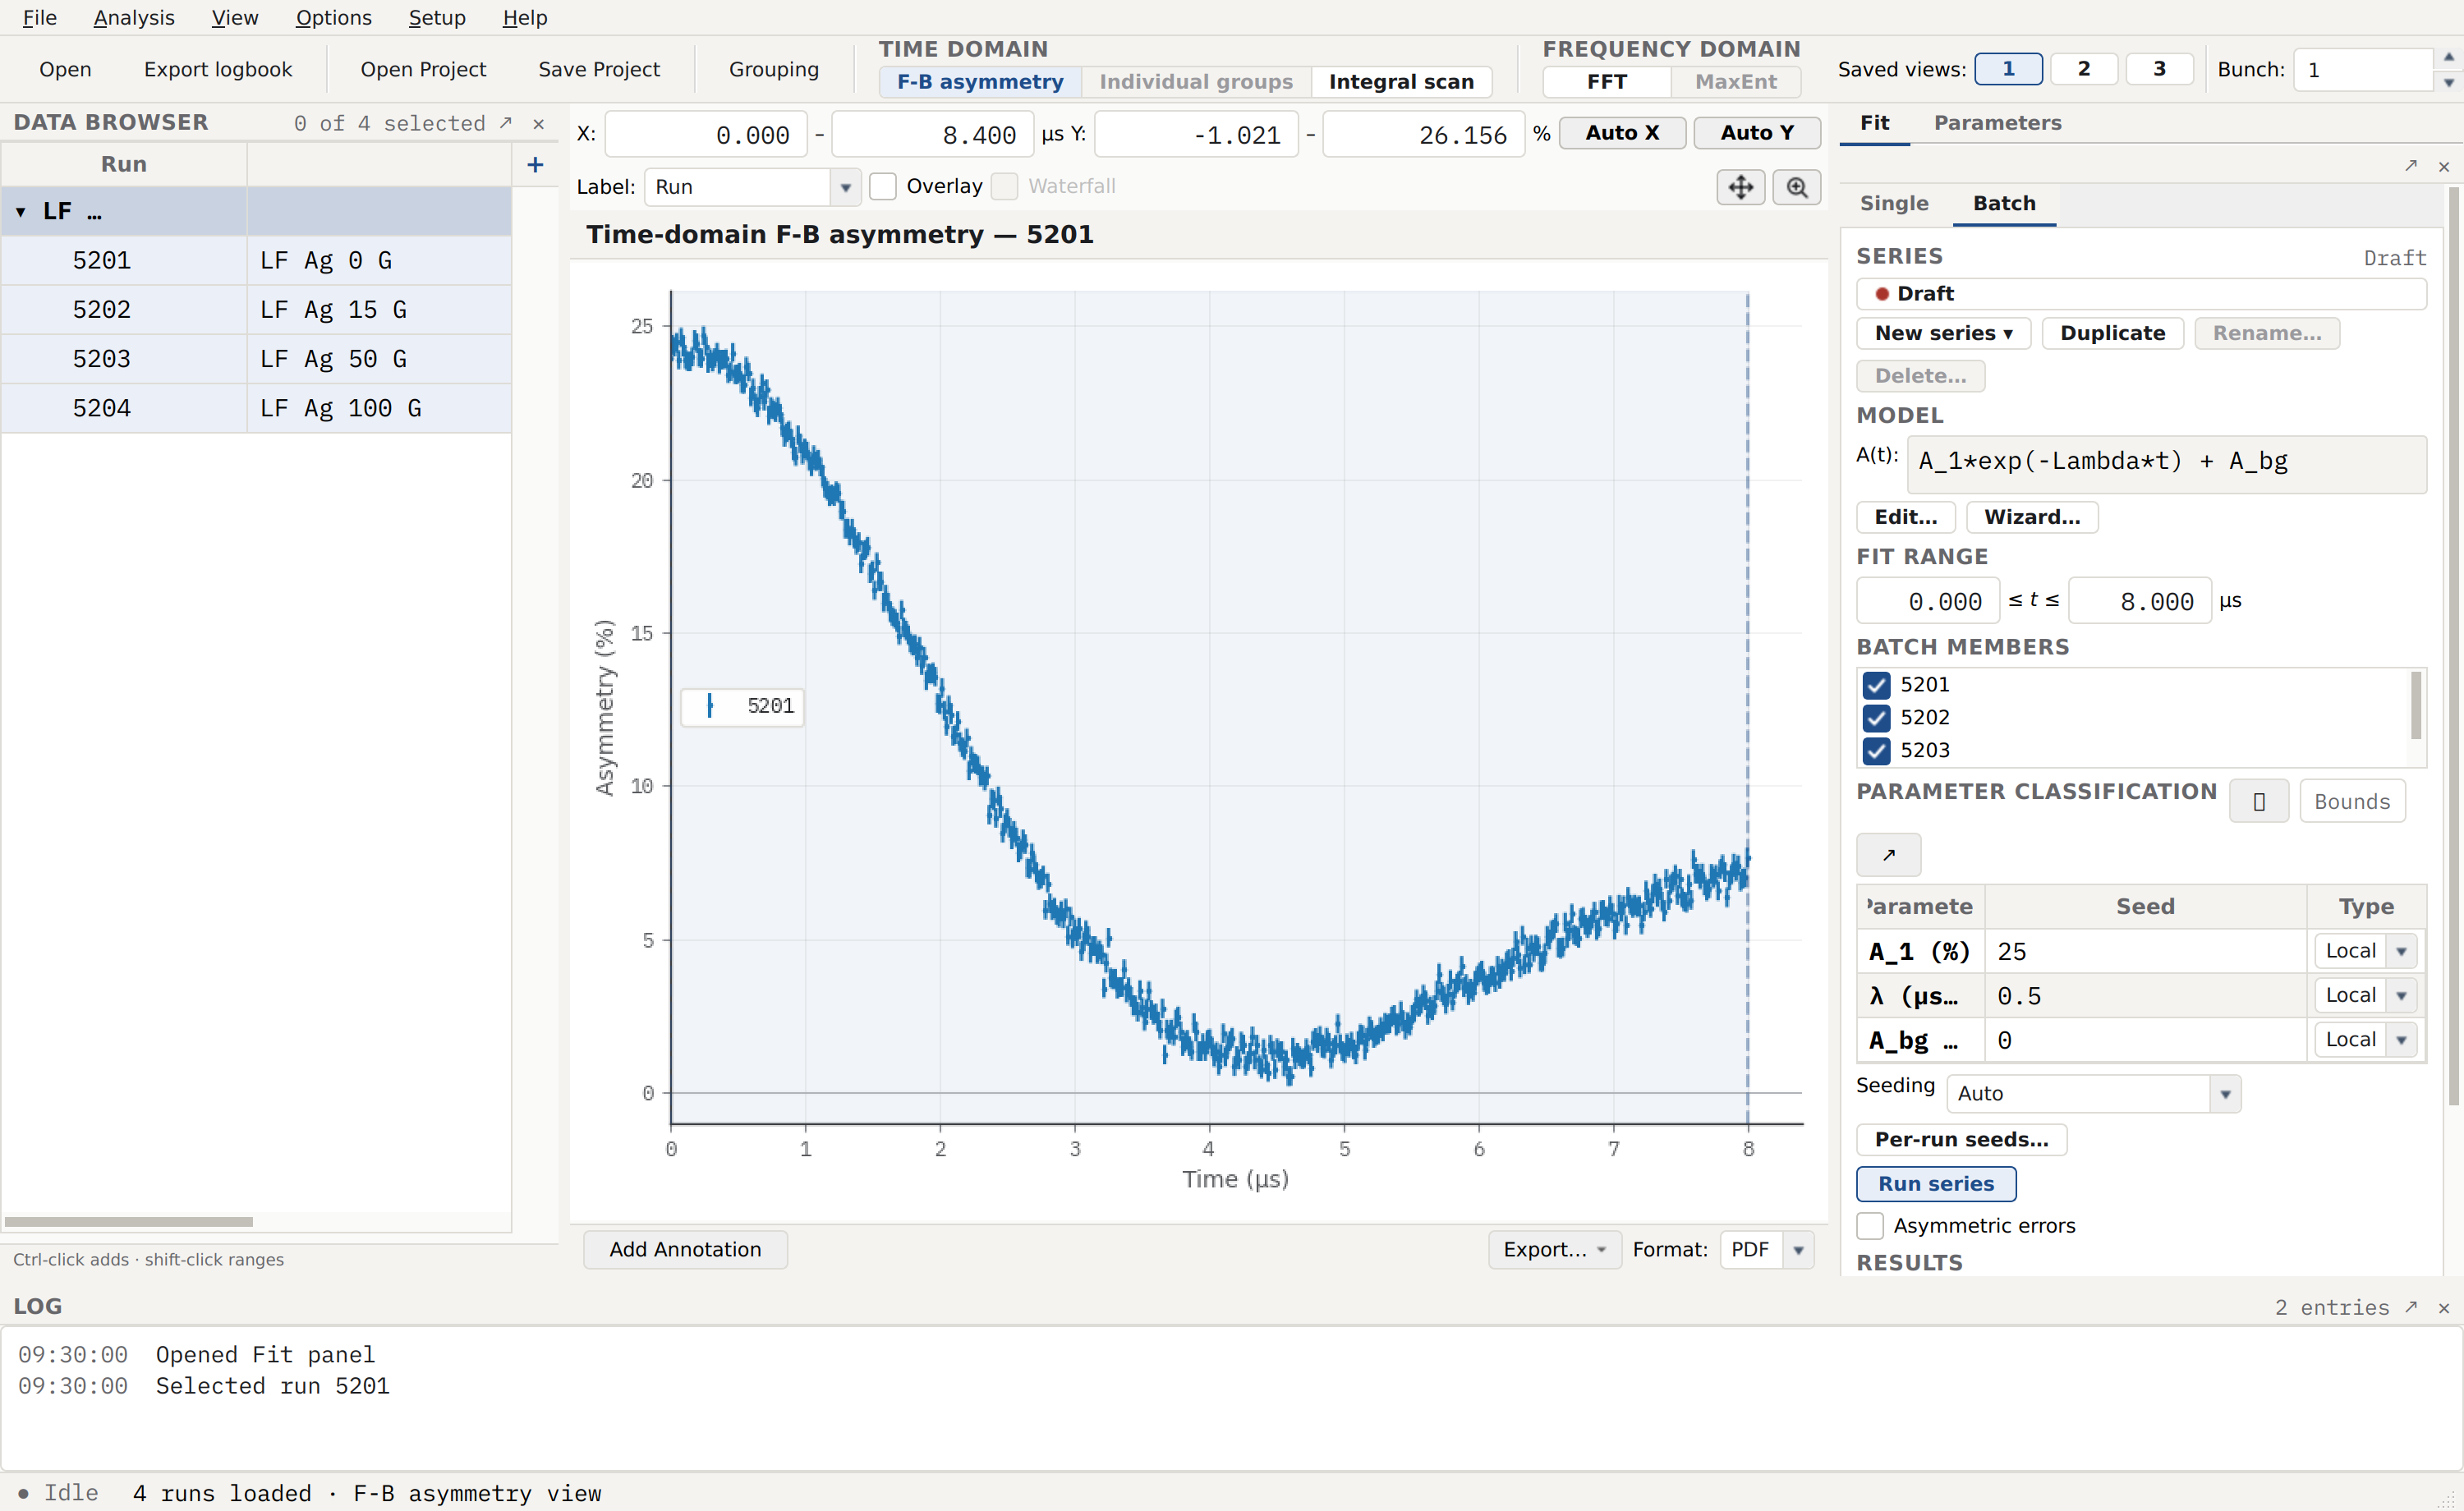
Global-fit setup on a synthetic Ag LF-KT decoupling series, B_L = 0, 15, 50, and 100 G with shared Δ ≈ 0.39 μs⁻¹. The longitudinal field decouples the nuclear dipolar broadening as γ_μB_L/Δ grows past unity (Hayano et al., Phys. Rev. B 20, 850 (1979); cf. Blundell et al. 2022, Fig. 5.6).
The global-fit result window is split into two synchronised views:
Left: fit overlays per selected dataset
Right: local-parameter trends vs the complementary sweep axis
Left pane controls
Show components: stack additive fit components under the total fit curve
Log X / Log Y: toggle axis scaling for dataset fit overlays
Share X Axis: render one aligned x-axis across all group subplots
Add Label: place draggable text labels directly on the plot
Right pane controls
Single Axes / Subplots: choose one combined axis or one axis per local parameter
Log X: log scaling for the local-parameter x-axis
Per-parameter Log Y: enable from the selector table for individual local parameters
Add Label: place draggable labels on local-parameter plots
Plot labels and annotations
Left-click and drag to reposition labels
Double-click an existing label to edit text
Right-click a label to remove it
Automatic group labels can be hidden per subplot by right-clicking them
All label positions and text are saved in the project file and restored when the project is reopened.
Joint fits
Analysis ▸ New joint fit… opens an undocked window that couples several already-recorded series — potentially carrying different models — by holding named parameters equal across them. Analysis ▸ Joint fits is a submenu listing every recorded joint fit (a stale one suffixed “ (stale)”); picking one reopens it in the same window. See Joint fits for the full walk-through — setting up the shared table, reading the results, staleness, and deleting.
Fit Parameters panel
After a global fit, the Fit Parameters panel shows how the varying
(per-dataset) parameters change across runs. See Parameter trending
for the full anatomy (series strip, x/y rails, parameter cards, the
Fitted parameters pop-out); the essentials:
Parameter table
The rail’s Table button opens a non-modal Fitted parameters window
holding a tabular view of every fitted varying parameter, with columns for:
Run number
\(B\) (G) — applied magnetic field
\(T\) (K) — sample temperature
Each varying parameter with its uncertainty
Parameter trend plot
Subplots mode (the default) gives each checked y-rail chip its own ParameterCard; Overlay draws every checked parameter on one shared canvas. Controls include:
x: Choose between Auto (inferred from data), \(B\) (G), \(T\) (K), or Run number. Auto mode detects whether field or temperature varies across the datasets.
y chips: Check a chip to open (or close) that parameter’s card
Scale: Check the x rail’s log and/or a card’s own log for logarithmic axes — useful for power-law behaviour or data spanning several orders of magnitude
Model components: Enable ⋯ → Show components to stack additive parameter-model components under fitted overlays (for visual decomposition)
Plot labels: Right-click any parameter plot — a card’s figure or the Overlay canvas — for Add label here…, Edit label… / Remove label over an existing label, and Clear labels; drag a label to move it, or double-click it to change its text
When Show components is enabled, y-axes are forced to linear scale with a zero baseline so stacked component areas remain physically interpretable.
Exporting data
The rail’s ⋯ menu offers:
Export TSV…: Save the parameter table to a tab-separated (.tsv) file for
use in spreadsheets or other analysis software. A comment header records the
fitted model and the shared global-parameter values, and per-run reduced χ² and
χ² columns are appended after the parameter columns.
Export GLE (PDF)… / Export GLE (EPS)…: Generate a publication-quality
figure using the GLE Graphics Layout Engine
via the gleplot Python library:
Click “Export GLE (PDF)…” or “Export GLE (EPS)…” for the format you want
Choose a name for the
.gleplotexport folderThe export creates the named
.gleplotfolder and writes:A
<name>.glescript for the selected plotA
.datdata file with column headers and the globally shared parameters recorded as comments at the top of the fileAny optional
.fitsidecars needed for active model overlays
If GLE is installed, the script is compiled and shown in GLE Plot Preview. EPS exports also write a PDF companion for previewing.
Without GLE, the script and data are saved for later compilation with
gle -d pdf <name>.gleinside the export folder.
Note
Install GLE from source or from http://glx.sourceforge.io/ to enable
automatic compilation. The gleplot Python package is required for
script generation (pip install gleplot).
Global-fit GLE exports
The Global Parameter Fit window provides two dedicated GLE export buttons:
Export fits to GLE (left pane): exports the per-dataset fit overlays
Export plot(s) to GLE (right pane): exports local-parameter trend plots
Both buttons show the compiled figure in GLE Plot Preview.
For local-parameter exports, Asymmetry also writes:
A
*_local_parameters.dattable with units and an explicit column mapOptional
*_local_<parameter>.fitfiles for any active local model fit overlays
Both global-fit export buttons use the same foldered layout, so the exported
.gle file, compiled output, and sidecars stay together in one bundle.
Both global and local export dialogs remember the last export directory and use it as the default location next time.
Analysis workflows
Basic analysis
Load data files
Sort by field or temperature
Select and view different runs
Adjust plot limits for detailed inspection
Apply bunching to reduce noise if needed
Comparing runs
Filter by temperature or field
Click through filtered runs to compare
Use co-adding to average similar runs
Temperature series
Sort by temperature column
Step through runs in order
Filter by field to isolate specific conditions
Field series
Sort by field column
Step through runs in order
Filter by temperature for isothermal scans
UI scale
The interface density can be adjusted from View → UI Scale. Five preset scales are available: 80 %, 90 %, 100 %, 110 %, and 120 %. The selection is persisted between sessions. The default is 90 %.
The scale is font-driven: it multiplies the application font (and the derived chrome font sizes) rather than resizing whole widgets. Everything sized from the font metrics then follows automatically, so a scale change adjusts:
base font size across panels and dialogs;
table row heights and character-based column widths;
dock minimum widths, keeping the fit table’s columns readable at every scale.
Keyboard shortcuts
Ctrl+Shift+O: Open data file(s)
Ctrl+N: New project
Ctrl+O: Open project
Ctrl+S: Save project
Ctrl+Shift+S: Save project as
Ctrl+Return: Run the fit
Ctrl+W: Close the current project tab
Ctrl+Q: Quit Asymmetry
Tips and tricks
Double-click column borders to auto-resize
Use “All” filter with partial text to find specific runs
Co-add replicate measurements to improve statistics
Bunch data before Fourier analysis to reduce computation time
Right-click on plot to save figure (via matplotlib toolbar)
Saving and reopening projects
A project file (.asymp) saves the complete state of your analysis
session. You can close Asymmetry and resume exactly where you left off, or
maintain several independent analyses side-by-side.
Creating and saving
- File → New Project (
Ctrl+N) always opens a new, empty project tab; existing tabs are left exactly as they were.
- File → New Project (
- File → Save Project (
Ctrl+S) saves the active tab to its project file. If no project file is open yet, you will be prompted to choose a location.
- File → Save Project (
- File → Save Project As… (
Ctrl+Shift+S) always asks for a new filename for the active tab.
- File → Save Project As… (
Unsaved-changes guard
Hours of grouping, fitting, and trend work live in memory until you save, so
Asymmetry tracks whether each project tab holds unsaved work and refuses to
drop it silently. A * on the tab label, and in the window title for the
active tab, marks a modified project. Closing that tab — via File → Close
Project, its ×, or File → Exit — first raises a Save / Discard /
Cancel prompt for it. Choosing Cancel aborts the action — for Exit,
this aborts the whole quit and leaves every tab open, including any already
confirmed; Save writes the project (choosing a location if none is set
yet) before proceeding. The flag is set by every mutating action — data load
and removal, grouping edits, each fit completion, trend-series rename or
delete, ALC scan builds, and custom-column edits — and cleared on a successful
save. New Project, Open Project…, and Recent Projects never raise
this prompt: they open a new tab (or reuse an untouched, empty one) instead of
discarding the current project, so opening or starting a project always
begins from a clean tab without disturbing your other work — see Working
with several projects below.
Opening a project
- File → Open Project… opens a file dialog so you can locate an
.asympfile.
- File → Recent Projects lists up to the 10 most recently opened projects
for one-click access.
Both open the project into the current tab when that tab is an untouched, empty project — no datasets loaded, no unsaved changes, never saved — and otherwise open it in a new tab, leaving the current tab exactly as it was.
On open, every source data file referenced by the project is reloaded from disk. Asymmetry tries paths in this order:
The absolute path stored in the project file
A path relative to the
.asympfile itself (useful when the whole analysis folder is moved together)If files are still missing, a dialog offers to locate a directory — choose the folder where the data files now live, and Asymmetry will match each missing file by filename
This means you can move an entire analysis folder, or just redirect to a new data location, without losing your session state.
If a source file cannot be found even after the search, Asymmetry logs a warning and skips that dataset — the rest of the session is restored normally.
Working with several projects
Several .asymp projects can be open at once in the same window, switched
with a tab strip that sits on the menu-bar row, to the right of the menus.
Each tab is a fully independent project: its own data browser, plot, fit panel, Fit Parameters panel, grouping profiles, saved views, and unsaved-changes state. Projects share nothing with each other — there is no cross-project import of series or grouping profiles, and no shared loaded runs — so comparing two projects means viewing them side-by-side or exporting tables from each.
A tab’s label is the project file’s stem (Untitled for a new, unsaved
project), with a trailing * while that project has unsaved changes;
hovering over a tab shows its full path. The window title continues to show
the active project, as it does today.
- New Project always opens another tab, so you never lose an
in-progress analysis by starting a new one.
- Open Project… and Recent Projects reuse the current tab only when
it is untouched and empty; otherwise they open a new tab. Because of this, opening a project never raises the unsaved-changes prompt.
Save Project and Save Project As… act on the active tab only.
- Close Project (
Ctrl+W) and a tab’s×close that project, running its Save / Discard / Cancel prompt if it has unsaved changes. Closing the last remaining tab leaves one empty
Untitledtab open rather than quitting.
- Close Project (
- Exit (
Ctrl+Q) and the window’s close button walk the open tabs in order, running each modified project’s Save / Discard / Cancel prompt in turn; the first Cancel aborts the whole quit and nothing closes.
- Exit (
- View → UI Scale is process-wide: a change applies to every open tab,
not just the active one.
- Only one bulk file load can run at a time across the whole window. Starting
a load in a second tab while another is still loading is refused, with the status bar reporting “Another project is loading files — wait for it to finish.”
- A dialog opened from a project — grouping, simulate, run info, global fit
setup — blocks the whole window while it is open, exactly as it does today.
- A fit started in one tab keeps running when you switch to another tab, and
reports its result back into the tab it was started from.
What is saved
All loaded datasets (stored as file paths, not raw arrays)
Co-added (“combined”) dataset groups
- Data Browser sort column, sort order, column filters, selected rows, and
dynamic metadata columns (including Run Info selections)
- Plot axis limits (X/Y), fit range, current run, overlay mode, and the
waterfall stacking setting (on/off and manual Δ, or automatic)
- Grouping settings per run (groups, forward/backward selection, alpha,
good-bin range, bunching, deadtime toggle)
Most-recently-displayed fit overlay curve(s)
Main plot labels/annotations
- Single-fit and global-fit model selection, parameter values, fixed/free
flags, and bounds
Fit results text (χ², χ²ᵣ, best-fit values with uncertainties)
Active fit panel tab (Single or Global)
- Fit Parameters panel rows, axis settings, plot mode, component-display
toggle, and plot labels
Fourier panel state, including apodisation settings, phase mode, per-run group phase tables, included groups, and phase-estimation settings
What is not saved
Raw data arrays (always reloaded from the original files)
Fourier transform output arrays
Log panel messages
Schema versioning
The .asymp format uses an integer schema version that is independent of
the Asymmetry package version. Project files from older releases will be
migrated automatically when opened in a newer release. If a project file
requires a schema version that the installed Asymmetry version does not
understand, an error dialog is shown and the file is not loaded.