Parameter trending
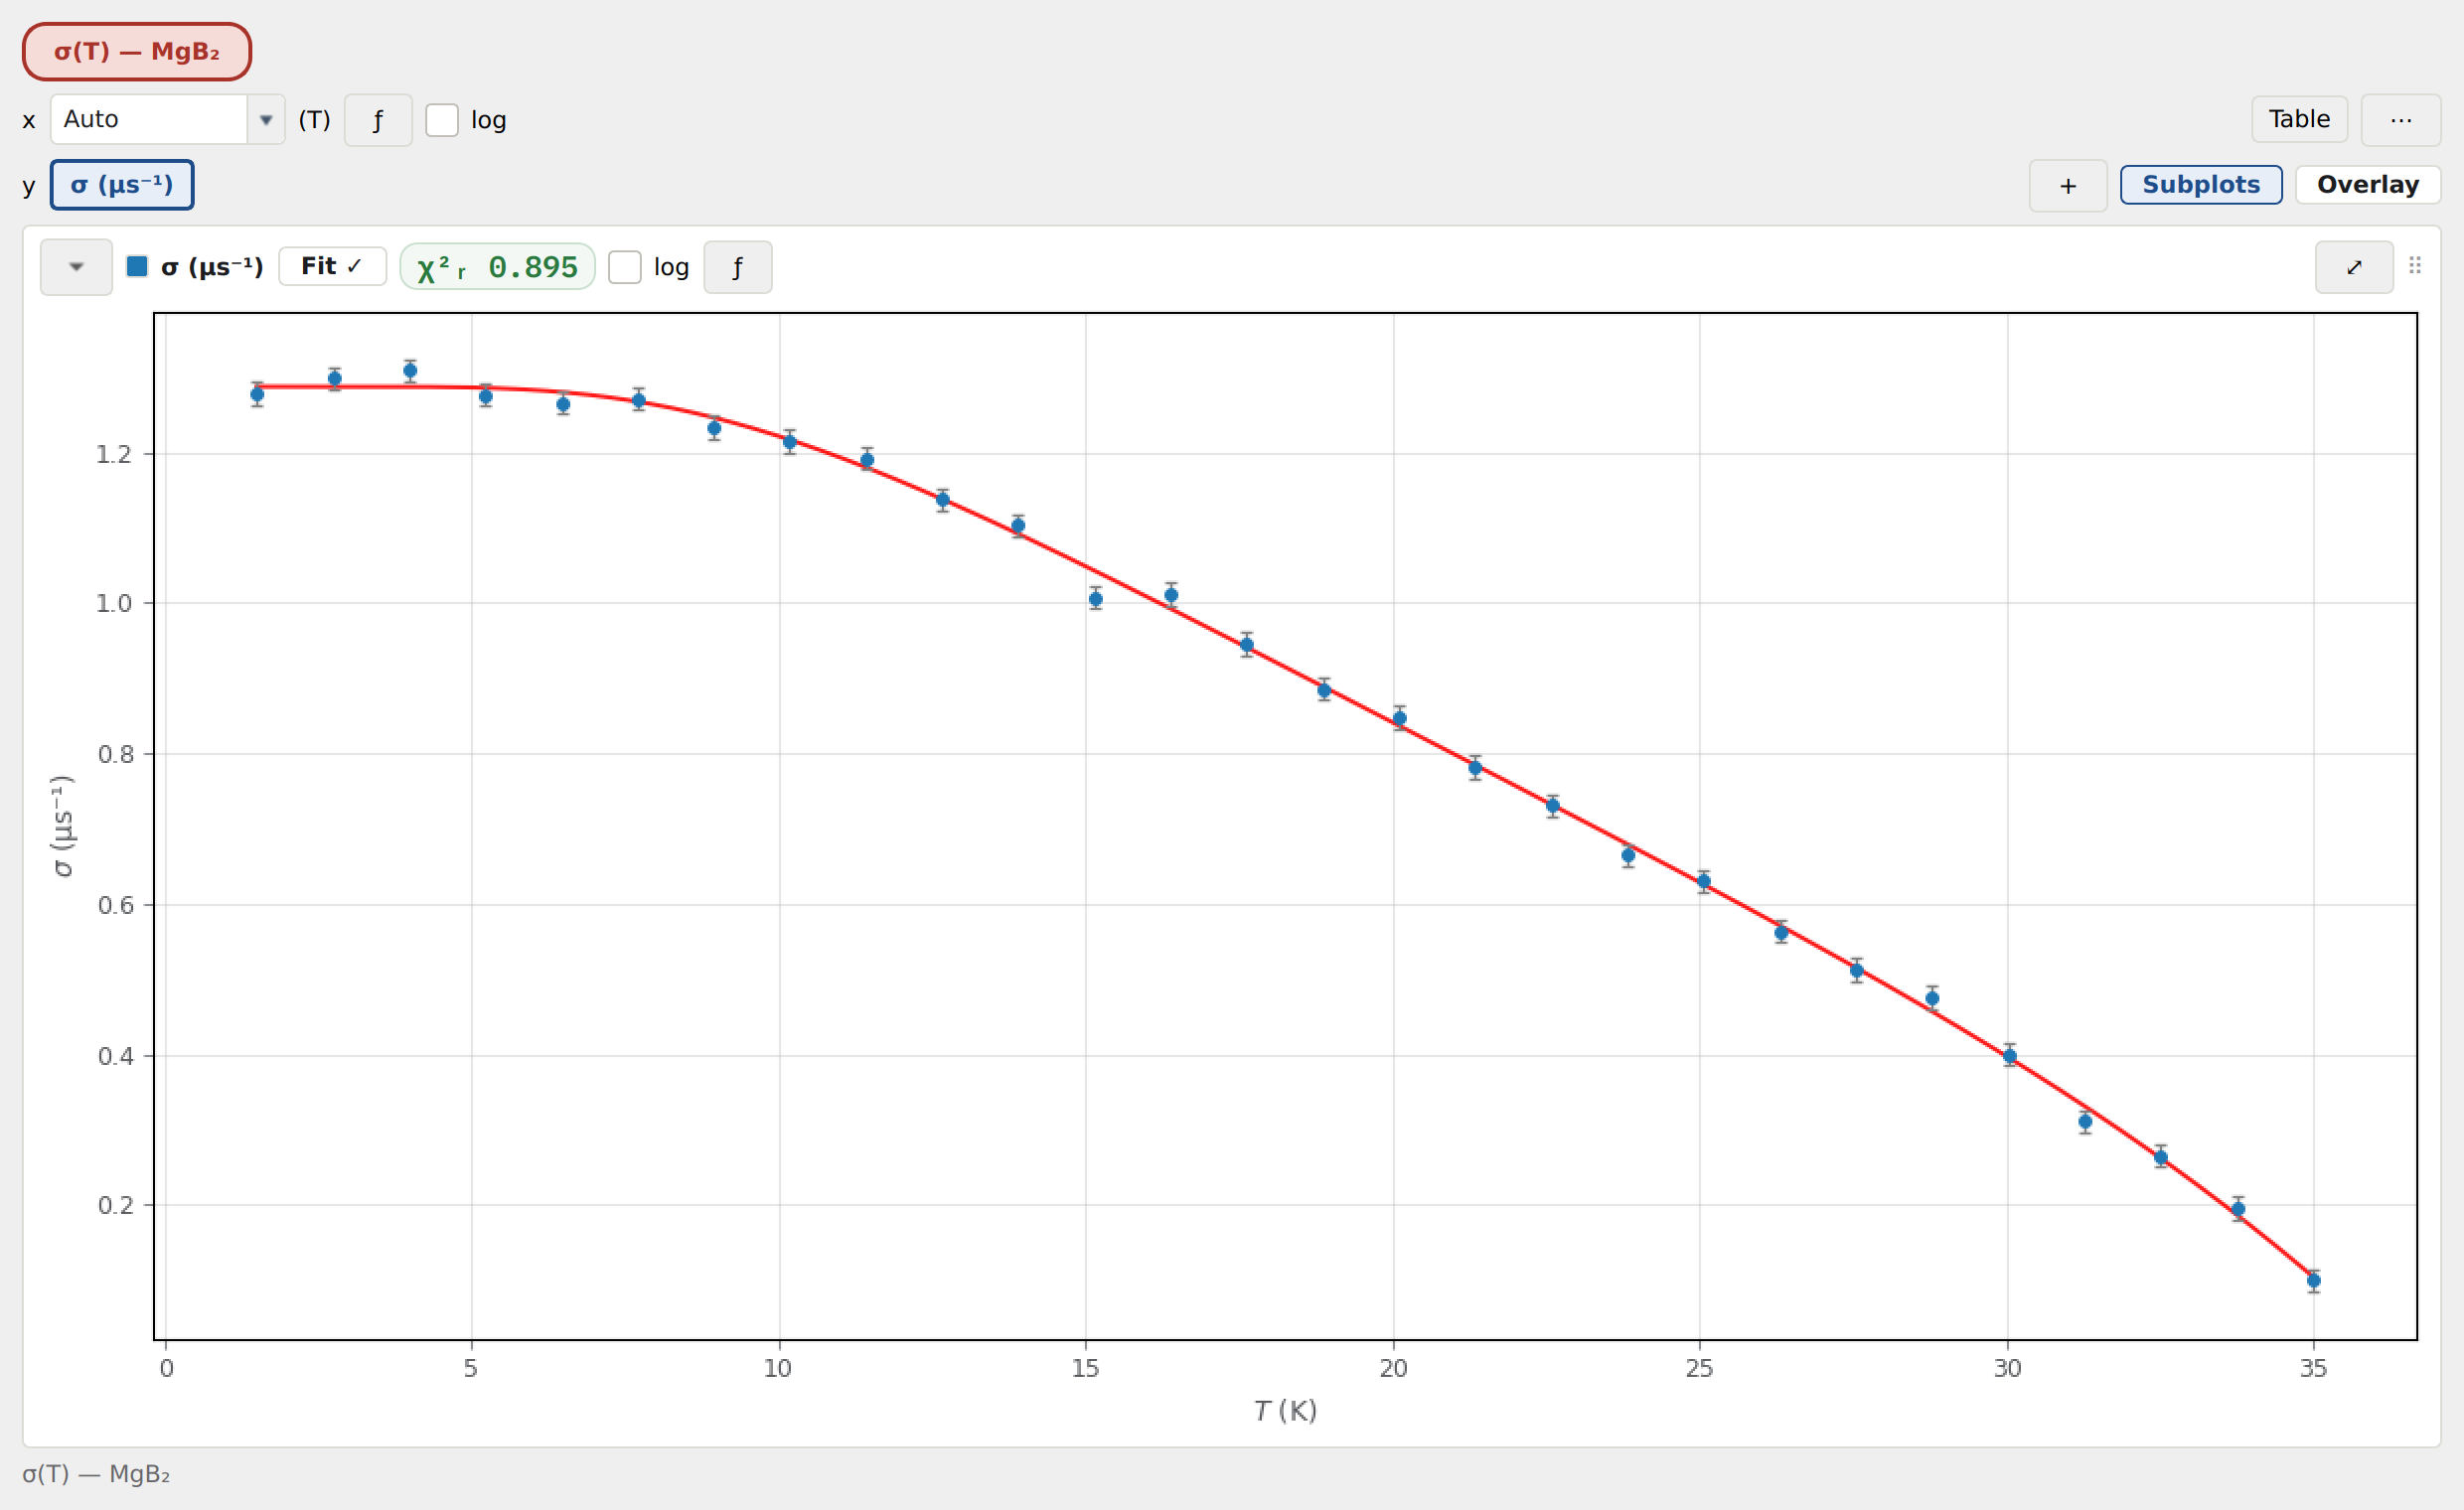
The Fit Parameters panel with synthetic MgB₂ σ(T) data (Tc = 36 K) loaded as
the σ(T) — MgB₂ series and the σ (µs⁻¹) chip checked on the y
rail, opening its card. The smooth trend curve is a SC_TwoGap_SS two-gap
fit (the card’s Fit ✓ button), an MgB₂ alpha-model decomposition (small
and large gap ratios; Niedermayer et al. Phys. Rev. B 65, 094512, 2002),
recovering σ₀ ≈ 1.24 µs⁻¹ and Tc ≈ 35.8 K; the card’s χ²ᵣ chip grades
it and opens the full results. The σ(T) → λ(T) inversion that follows from
this fit is discussed in Superconducting penetration depth models.
Parameter trending is the second stage of any temperature or field scan analysis. Once a series of runs has been individually (or globally) fitted in the time domain, the extracted parameters themselves carry the physically interesting information: an order parameter as a function of temperature, a relaxation rate as a function of field, a precession frequency tracking magnetic ordering. The parameter-trending framework fits those derived curves with parametric models — power laws, Arrhenius expressions, Redfield denominators, superconducting gap models, transport forms — and reports the resulting physical quantities (critical temperature, activation energy, gap ratios, dimensionality of motion) with uncertainties.
Frequency-domain global fits use the same panel. Peak centres and widths from
Fourier spectra appear as nu0 and fwhm in MHz, with derived field
equivalents B0 and Bwid for plotting or fitting spectral shifts and
broadening directly against field, temperature, or run number.
Gaussian widths at second-moment consumers
Asymmetry also checks the captured source of widths passed to
SC_Brandt_VortexLattice and SC_Brandt_VortexLattice_Powder, including
cross-group fits and composite branches connected to the output by addition,
subtraction, or quadrature. A bare Brandt term beside a product background is
still checked. A component inside an arbitrary product or ratio has no declared
absolute output-width contract, so that branch remains unclassified. A known Gaussian component uses
\(\exp(-\sigma_G^2t^2)\); these field laws require the second-moment
width in \(\exp(-\sigma_2^2t^2/2)\). An unconverted sigma column
therefore produces this explanation:
Column 'sigma' contains Gaussian-component width in exp(-sigma^2*t^2); SC_Brandt_VortexLattice expects second-moment width in exp(-sigma^2*t^2/2). Apply Custom Y transform sqrt(2)*x to Gaussian-component values and errors before fitting; mixed conventions require separate conversion.
Choose ƒ → Custom… on that parameter’s card, then enter
sqrt(2)*x in Custom Y transform, beside Expression in x:.
The real fit receives transformed values and errors. Parentheses and whitespace
are immaterial; x*sqrt(2) is also recognised. A rounded numerical multiplier
or an arbitrary nonlinear expression does not declare a physical width
conversion. Known second-moment input uses None (or Custom x), and
must not receive another factor. Mixed known conventions need separate
conversion before combination.
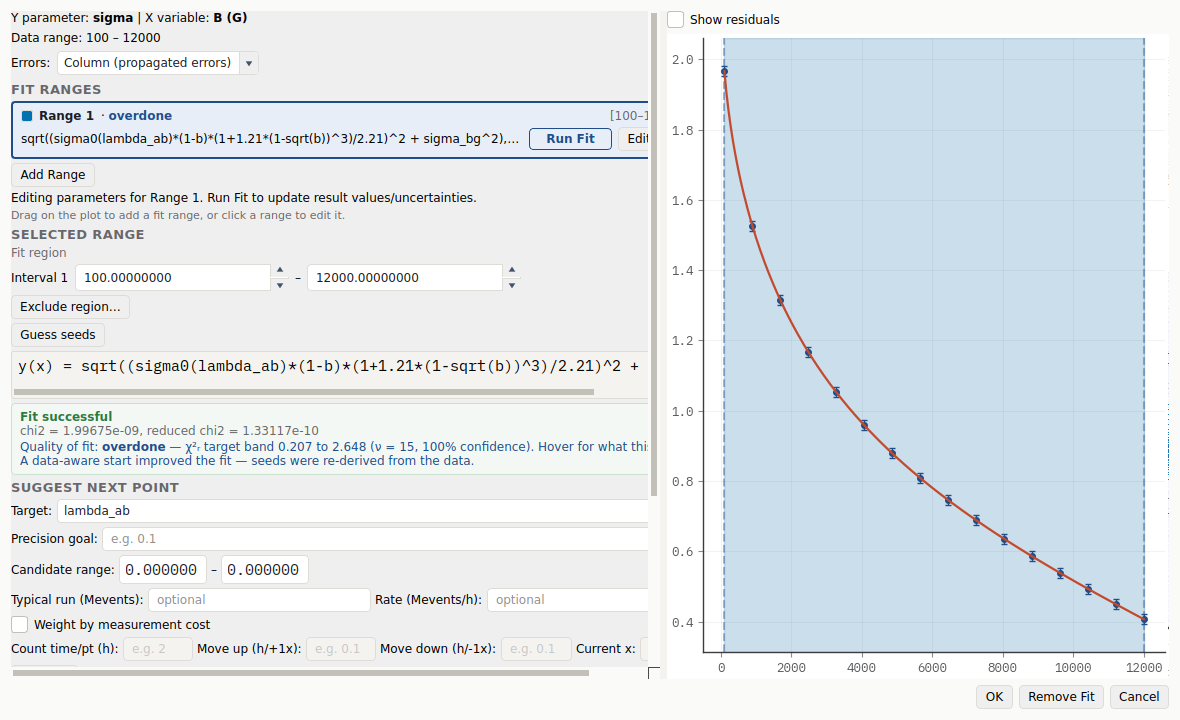
Synthetic single-crystal widths after explicit conversion, fitted with
SC_Brandt_VortexLattice at fixed Bc2 and sigma_bg.
Source identity follows each captured component parameter, including repeated
components and aliases; display labels do not establish it. A literal derived
copy retains its source; sqrt(2)*parameter (or reversed operands) records an
explicit conversion through the existing Derived parameter… expression
boundary. Other derived expressions remain unclassified rather than being
certified as physical widths.
Temperature-dependent SC_* laws, and the same-Y-unit Constant.c and
Linear.b outputs, inherit the input convention in additive models. Their width outputs retain the known
conventions of the observations that actually entered the fit. Other derived
quantities do not acquire a certified width convention. Width outputs from an
unverified transform of a known width retain that origin; a later factor cannot
certify it. For example:
Column 'sigma_0' has an unverified transform of a known width (x*x); a second-moment fit requires an explicitly established width conversion.
For already second-moment input, applying another transform produces:
Column 'sigma_0' already has second-moment width; use untransformed values and errors for a second-moment model.
A saved Gaussian model supplies captured source identity even when a separate convention field is absent. Generic/manual tables and historical records without captured source attribution remain usable with convention not recorded. Inspect their provenance and choose the conversion explicitly. Unknown provenance is not treated as a known mismatch. Unknown convention alone does not prevent a new fit; existing execution and source-availability checks still apply. Loading preserves saved numbers and never fits or rescales them. Plotting and exporting apply selected transforms without rewriting the recorded source values. Saved fit context retains its execution transform; changing the displayed Y transform hides an incompatible historical fit overlay and fit export. See Gaussian width convention for background, covariance, and geometry limits.
Panel layout
The panel reads top to bottom, nothing scrolling at rest. A chip rail
lists the active representation’s recorded series as coloured pills,
sectioned by the data group that owns them: a swatch-and-name header per
group, an un-headered “Standalone” section for group-less series, and no
header at all when every series is standalone. A chip under a group heading
names only its model and fit window (Exponential + Constant · 0–6 µs —
the header already says which group); a Standalone chip, with no heading to
lean on, keeps its member run range too. Either way the chip is a short
handle elided in the middle, so the window at the end — what usually tells
two otherwise-identical series apart — survives the elision, and the full
name is always on the tooltip. Click a chip to make it the active series;
Shift+click a second to overlay it (Overlaying Several Series);
double-click to jump straight to Open in Batch tab, the same action a
right-click’s chip menu leads with: Open in Batch tab, Duplicate…,
Rename…, Select members in browser, Show fit overlay (the
menu’s way to make a series active without pressing its chip — ticked and
disabled when it already is), and Delete series…, which removes only
that series and its trend — other series and single fits on the same runs
are untouched. The rail wraps onto
further rows rather than widening the panel.
The x rail carries the abscissa: the x picker (temperature, field,
run number, angle, a fitted parameter, or a custom logbook column), the ƒ
transform button (Axis Transforms), a log axis-scale checkbox,
Fold: (Angle x only), and, on the right, Table (opens the pop-out
below) and ⋯ (Export TSV…, Export GLE (PDF)…,
Export GLE (EPS)…, checkable Show components, and the unconditional
Knight shift window…).
The y rail carries one checkable chip per trendable parameter — checking
one opens that parameter’s card — the + menu (Derived parameter…;
Knight shift window… too, once the active series has a Knight-convertible
component), and the Subplots │ Overlay toggle. The chip row wraps as it
overflows.
Subplots (the default) stacks one card per checked chip. A card’s
header carries a disclosure arrow, a colour swatch, the parameter’s name, its
Fit button (Fitting a Trend Model), a log checkbox, its own ƒ
transform button (Axis Transforms), a focus button (⤢, grows the card
to fill the stack — the rest collapse beneath it and are restored on exit)
and a drag grip (⠿, reorders the stack). Collapsing a card (its
disclosure arrow, or a click anywhere on the header) replaces the figure with
a small sparkline. A derived parameter’s card carries a derived tag;
right-click its header for Edit derived… (composite parameters only) and
Remove. Overlay instead draws every checked parameter on one shared
canvas (a twin y-axis for exactly two — see Overlaying Several Series).
Once a parameter carries a converged model fit, a χ²ᵣ chip (χ²ᵣ 0.89)
appears in its card header beside the Fit button, coloured by the same
quality verdict the Model Fit window reports — green for good, red for
poor, blue for overdone, and neutral grey where χ²ᵣ carries no goodness
information (unit or scatter-estimated errors, or fewer points than
parameters; see assessing a fit). Hovering it names
the verdict, its target band and confidence, and each fitted parameter in the
parenthesised-uncertainty convention (T꜀ = 35.8(5) K is 35.8 ± 0.5 K).
Clicking the chip opens that parameter’s Fit results window (titled, for
example, Fit results — λ (µs⁻¹)): the model and verdict chips over a
read-only Parameter / Value / Unit table — one row per fitted
parameter, with any parameters held fixed listed after them — the trend
provenance, the x axis, fitted range and error mode, and Copy (the table
as tab-separated text), Edit model fit… (reopens the Model Fit window)
and Close. The window is non-modal, updates itself whenever the fit
changes, and a fit with several ranges gets one section per range.
Every plot — each card’s figure and the Overlay canvas alike — carries the same right-click menu for text labels. Over bare axes it offers Add label here…, which prompts for the text and drops the label where you clicked; over an existing label it offers Edit label… and Remove label; and Clear labels appears whenever the plot holds any. Drag a label to move it, or double-click it to change its text. Right-clicking near a trend point adds that point’s Exclude from trend / Include in trend action (and its quality flags) to the same menu.
The footer has two rows. The first names the series on screen in full — the
long name the pills no longer carry, or 2 series (the names on its
tooltip) while an overlay is selected. The second reports trend provenance on
the left (4/4 members in trend) and, on the right, notes any Global
(shared) parameter held constant and so excluded from the y rail, with the fix
in its tooltip.
Table opens a non-modal Fitted parameters window holding the live parameter table (a Trend checkbox and a χ²ᵣ flag per row — see assessing a fit), the shared Global parameter values above it, and Copy TSV / Export… below. Reading a row and finding it on the plot is otherwise a matter of counting points, so resting the pointer on a row rings that run’s point on every plot — on each expanded card in Subplots, and on both axes of a twin-axis Overlay.
The trending data model
Everything trendable is a FitSeries. Whatever produced the numbers — a batch of single-run fits, a grouped multi-detector fit, a global cross-fit, a frequency-domain peak fit — the result lands in one container type, stored in the project’s batch collection. A FitSeries holds the per-run fit summaries (Assessing a Fit: success, χ², reduced χ², parameter values and uncertainties) keyed by run, and that is exactly the structure the parameter-trending tools consume. There is no separate “trend object”: to trend a quantity is to read a parameter out of a FitSeries across its runs.
Two distinct paths write into this one container, by design:
Results recursion records the per-group rows of a model fit — each fitted group’s parameters become a row, so the series carries a parameter-versus-run (or versus-group) curve ready to trend.
The global summary accumulates one row per fit from a cross-group or global fit — the shared (global) parameters of each fit, gathered across a run series.
Both write FitSeries instances into the same collection; they differ only in what each row represents (per-group values versus per-fit global values), not in the container. This is why a grouped fit and a global fit both appear as selectable series in the panel and trend through identical machinery.
The Global Parameter Fit window is a view onto persisted studies, not a
third container. Each cross-group fit is a named study (a
GlobalFitStudy) kept in a project-level registry, so several can sit side by
side — rename, duplicate, or delete them from the window’s studies sidebar, and
select one to display it. A study records the group snapshot it was fit against
and detects when the live trend data has drifted from it (a stale badge, with
a Refit action). The window’s decorations (the per-parameter local model
fits and free-floating plot annotations you add in the window) are stored inside
the FitSeries it is viewing — keyed by batch id, in the series’ extra —
rather than under a separate project key. They
therefore travel with the data they annotate and reappear whenever the window
shows that fit again, including across a project save/reload, and can no longer
be orphaned when the fit is re-run. View preferences (log axes, plot mode,
show-components) are not decorations: they are remembered per window, not per
fit. Legacy projects that stored decorations under the old window-state key
still load, and migrate to the new home on the next save.
Group-bound series and staleness
A run-membered FitSeries produced by a batch or global fit belongs to a Data Browser group: either the group the fit was launched from (via Fit this group…), or a group auto-created from the ad-hoc run selection. The group is the batch vehicle — its membership drives the series, not the other way round. A series’ effective membership is derived live as the owning group’s members minus any runs the series itself has excluded (untick a run in the Batch tab’s member list without removing it from the group), so the same group can carry more than one analysis — a field scan fit with one model and, separately, a subset of it re-fit with another — without duplicating the run collection.
Because membership is live-derived, adding a run to the group or excluding one from the series does not retroactively change already-recorded results: those stay a snapshot of what was actually fit. When the group’s current effective membership no longer matches that snapshot, the series is stale, and its chip grows a ⚠ with the tooltip “Membership changed since last fit — re-run to refresh.”; opening it in the Batch tab (Batch fitting in GUI usage) and clicking Run series refreshes the snapshot and clears the marker.
The Batch tab is a series editor: it always has one series open, and a run
either replaces that series’ results or records a new one, never both at
once. An identical re-run — the same model, parameters, fit range, seeding
and effective members as what is already recorded — replaces the series’
results in place, under its existing name; changing anything first, a wider
window, a different model, a run ticked back in, records the run as a
new series instead and leaves the one you opened alone. The check looks
at the series open in the Batch tab first, then the representation’s active
series, then the newest series already describing the same analysis, so a
truly identical re-run replaces its series wherever it lives — which also
keeps the Global Fit Wizard’s per-phase re-applies from stacking a fresh
series on every pass. A series with no owning group (a legacy analysis, or
one kept as a standalone record after its group was deleted) is never
stale — its membership is a fixed snapshot, exactly as before this
distinction existed. See Project files for the persisted recipe,
group_id / excluded_run_numbers / last_fitted_members fields and
GUI usage for the Data Browser and Batch tab controls that drive them.
How the T / B abscissa is sourced
When a series is recorded, each member run’s temperature and field are stamped into its summary so the trend plots every point at the right coordinate even after the dataset leaves the browser or the project is saved and reopened. That coordinate is the value the Data Browser displays for the run — not, in general, the raw header scalar.
For a co-added row the first ordered input supplies the condition labels, including its displayed log value. A missing master condition stays off that axis; other constituents do not supply a replacement or a weighted mean. The active constituent range is provenance rather than an x-error bar. Saved fit coordinates retain their recorded meaning when sources are rebuilt.
This matters for parked-setpoint series. If a scan was run with the cryostat setpoint left at a single value (e.g. every run logged as 1 K) while the true sample temperature drifted, the header temperature is identical for every run and a temperature trend would collapse onto one abscissa point. Enabling Options → Use temperature from log switches the T column to the logged sample temperature, and the trend X-axis and TSV export now follow: each point is placed at its logged temperature, so a \(T\)-trend (or Arrhenius fit) becomes possible. The field axis behaves the same way under the analogous use field from log option, and per-dataset overrides (set from a single run’s Get Info) are honoured too.
With both toggles off (the default) the abscissa is the header setpoint exactly as before. A run with no recorded temperature or field stays off that axis (plotted as NaN), never planted at 0. Series recorded before this behaviour existed re-plot against the browser’s currently displayed value when their runs are still loaded.
Beyond temperature, field, and run number, the x rail’s abscissa picker also offers any fitted parameter (parameter-vs-parameter trending) and any custom data-browser column (Columns: metadata and custom). Custom columns hold free-form text, so when one is the x-axis each value is coerced to a number and runs whose value is empty or non-numeric are dropped, with a note reporting how many were skipped.
Axis transforms
Some of the most common µSR presentations are linearisations of a curved trend: the Redfield analysis plots \(1/\lambda\) against \((\mu_0 H)^2\) so a straight line’s slope and intercept give the fluctuation rate and field width; the Arrhenius analysis plots \(\ln\lambda\) against \(1/T\) so the slope is an activation energy. The ƒ button applies such a transform to an axis: one sits on the x rail, beside the abscissa picker, and one sits on every parameter card’s header. The x lens is shared — one abscissa carries every trace — while the y lens belongs to each card’s own parameter, so \(1/\lambda\) and a raw \(\beta\) can sit in cards side by side without one parameter’s linearisation distorting the other.
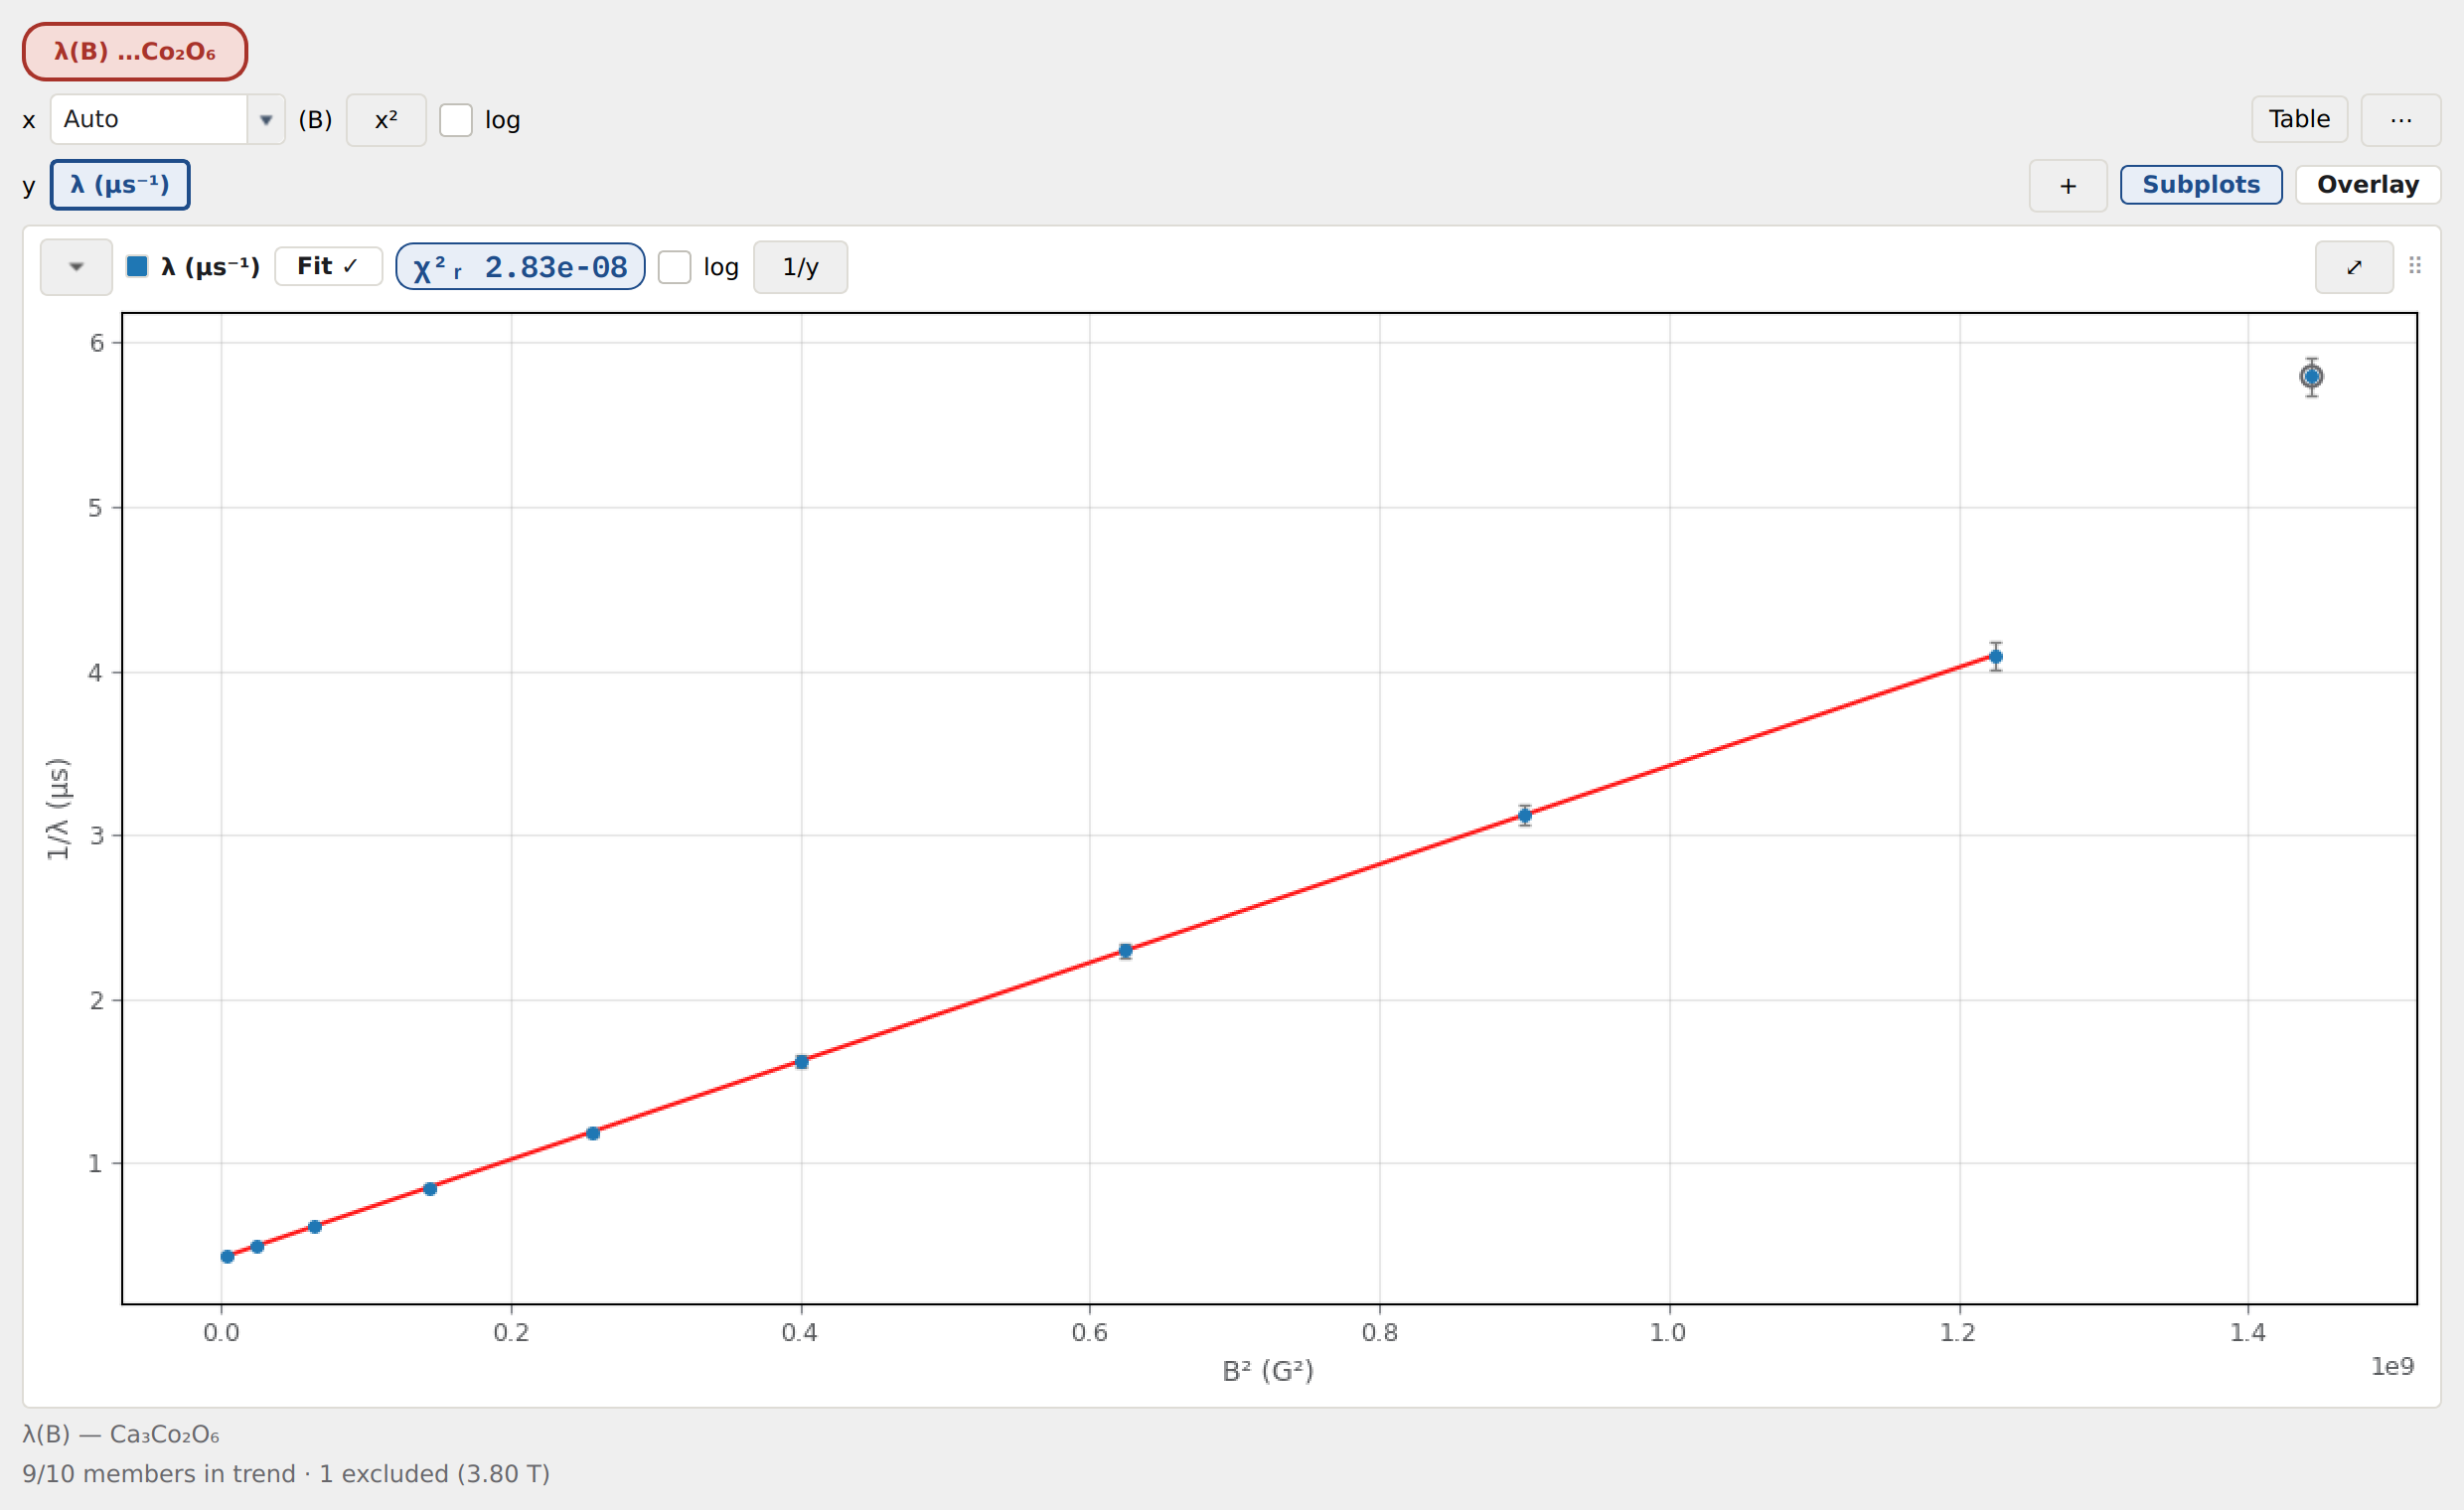
A Redfield linearisation of a longitudinal-field \(\lambda(B)\) scan:
\(\lambda\)‘s card ƒ button set to 1/y (reciprocal) (reading
1/y) and the x rail’s ƒ button set to x² (square) (reading
x²) turn the three-regime \(\lambda(B)\) falloff into a straight
line, and a Linear model fit on the transformed plateau gives the
Redfield slope and intercept. The high-field saturated point is excluded
from the trend, so it sits off the line.
Clicking ƒ pops a menu of presets — None, 1/x (reciprocal),
x² (square), ln x, log₁₀ x, √x and Custom… — named in
y on a card (1/y (reciprocal), y² (square), ln y, …) with the
active choice ticked. The button itself shows the result: ƒ at rest
(identity, no transform), or the transform’s own notation once one is set
(1/x, x², ln y, …). The x rail’s button sets the shared abscissa
lens; a card’s button sets that one parameter’s own lens and nothing else’s.
Choosing Custom… opens a small Custom X transform / Custom Y
transform dialog with one field, Expression in x: (placeholder
e.g. 1000/x); the expression is validated live and previewed on a
representative data value. The accepted expression then labels the ƒ button
itself, and the last-used custom expression is remembered separately for the
abscissa and for each y parameter.
The transform is applied at the point where the panel assembles its data, so it
governs the plotted points, the propagated error bars and the trend fit:
fitting a Linear model with the axes transformed to \(1/\lambda\)
versus \((\mu_0 H)^2\) is the Redfield line, and its slope/intercept are
read straight from the model-fit dialog. A point
whose transform is undefined (1/0, ln of a non-positive value) is dropped,
and the count surfaces on the trend-provenance line beneath the plot
(”⚠ 1 dropped by transform”). Changing a transform strands an existing trend fit
in the previous coordinate: its curve is hidden and its card’s Fit button
changes to Fit ⚠ until you re-fit under the new axes. Only the fits
actually affected are stranded — a new lens on \(\lambda\) leaves
\(\beta\)’s fit alone, while a change of x axis reaches every parameter.
In Overlay mode with three or more parameters on one axis, the axis reads
Parameter value and each legend entry names that parameter’s lens
(1/λ (µs) beside a raw β), in the plot and in the GLE export alike.
The field axis is labelled in gauss (the loaders’ native field unit), so a
transform squares or inverts that unit accordingly (B² (G²)); a dataset held
in tesla should be trended via a custom column carrying its own unit.
A transform is distinct from the log axis-scale checkbox next to the x
rail’s abscissa picker (and each card’s own log checkbox): those change
the axis tick spacing while leaving the numbers alone, whereas the transform
changes the plotted values (which is what a straight-line Arrhenius fit
needs). To keep the two from compounding, selecting ln x / log₁₀ x
disables the matching log checkbox — the x rail’s, or that card’s own —
until the transform is cleared.
Note
Arrhenius on a plateau needs the baseline subtracted first. A rate that
plateaus at low \(T\) and only activates above some threshold — e.g. a
hop rate \(\nu(T) = \nu_0\,e^{-E_a/k_BT} + c\) with a residual \(c\)
— is not linearised by the plain ln preset, because
\(\ln(\nu_0 e^{-E_a/k_BT}+c)\) is not linear in \(1/T\); fitting it
returns an activation energy biased low. Subtract the plateau first with a
Custom… expression, e.g. log(x - 0.274) with the plateau value read
off the low-\(T\) end, so \(\ln(\nu-c)\) is straight. (The plainer
route is to skip the linearisation and fit an Arrhenius model in raw
coordinates directly.)
Note
Error bars in transformed space are propagated to first order
(\(\sigma_{f(x)} \approx |f'(x)|\,\sigma_x\)) and drawn symmetric. This is
standard and accurate when the relative error is small; where it is large
(a low-signal point under ln or 1/x) the true interval is
asymmetric, so read such error bars as indicative.
Exports under a transform. The rail’s ⋯ menu’s Export TSV… keeps
every raw column (the durable record) and appends the transformed columns
that match the on-screen axes, with a # X transform provenance comment and
one # Y transform [<parameter>] comment per transformed parameter; with
several series overlaid it gains a leading Series column and writes every
selected series. Export GLE (PDF)… / Export GLE (EPS)… likewise append
transformed columns (and point the plot and fitted curve at them, so the
figure matches the screen), but currently write only the active series —
they warn and name that series; export the others separately, or use TSV.
Overlaying several series
The series buttons above the plot are multi-select: Shift+click a second
series to overlay it on the first (the same selection also arms a joint
Cross-Group Fitting). Overlaid series are
distinguished by colour, with a legend of their names — the natural way to
compare, say, \(\sigma(T)\) measured at two applied fields, or the same
observable across two samples. When more than one parameter is also selected,
each parameter takes a distinct marker shape so colour stays free to encode the
series; the twin-axis layout is used only for a single series. Model-fit trend
curves are drawn for the active (last-clicked) series — flagged (active) in
the legend — which retains ownership of the parameter table, composites, and the
model-fit controls.
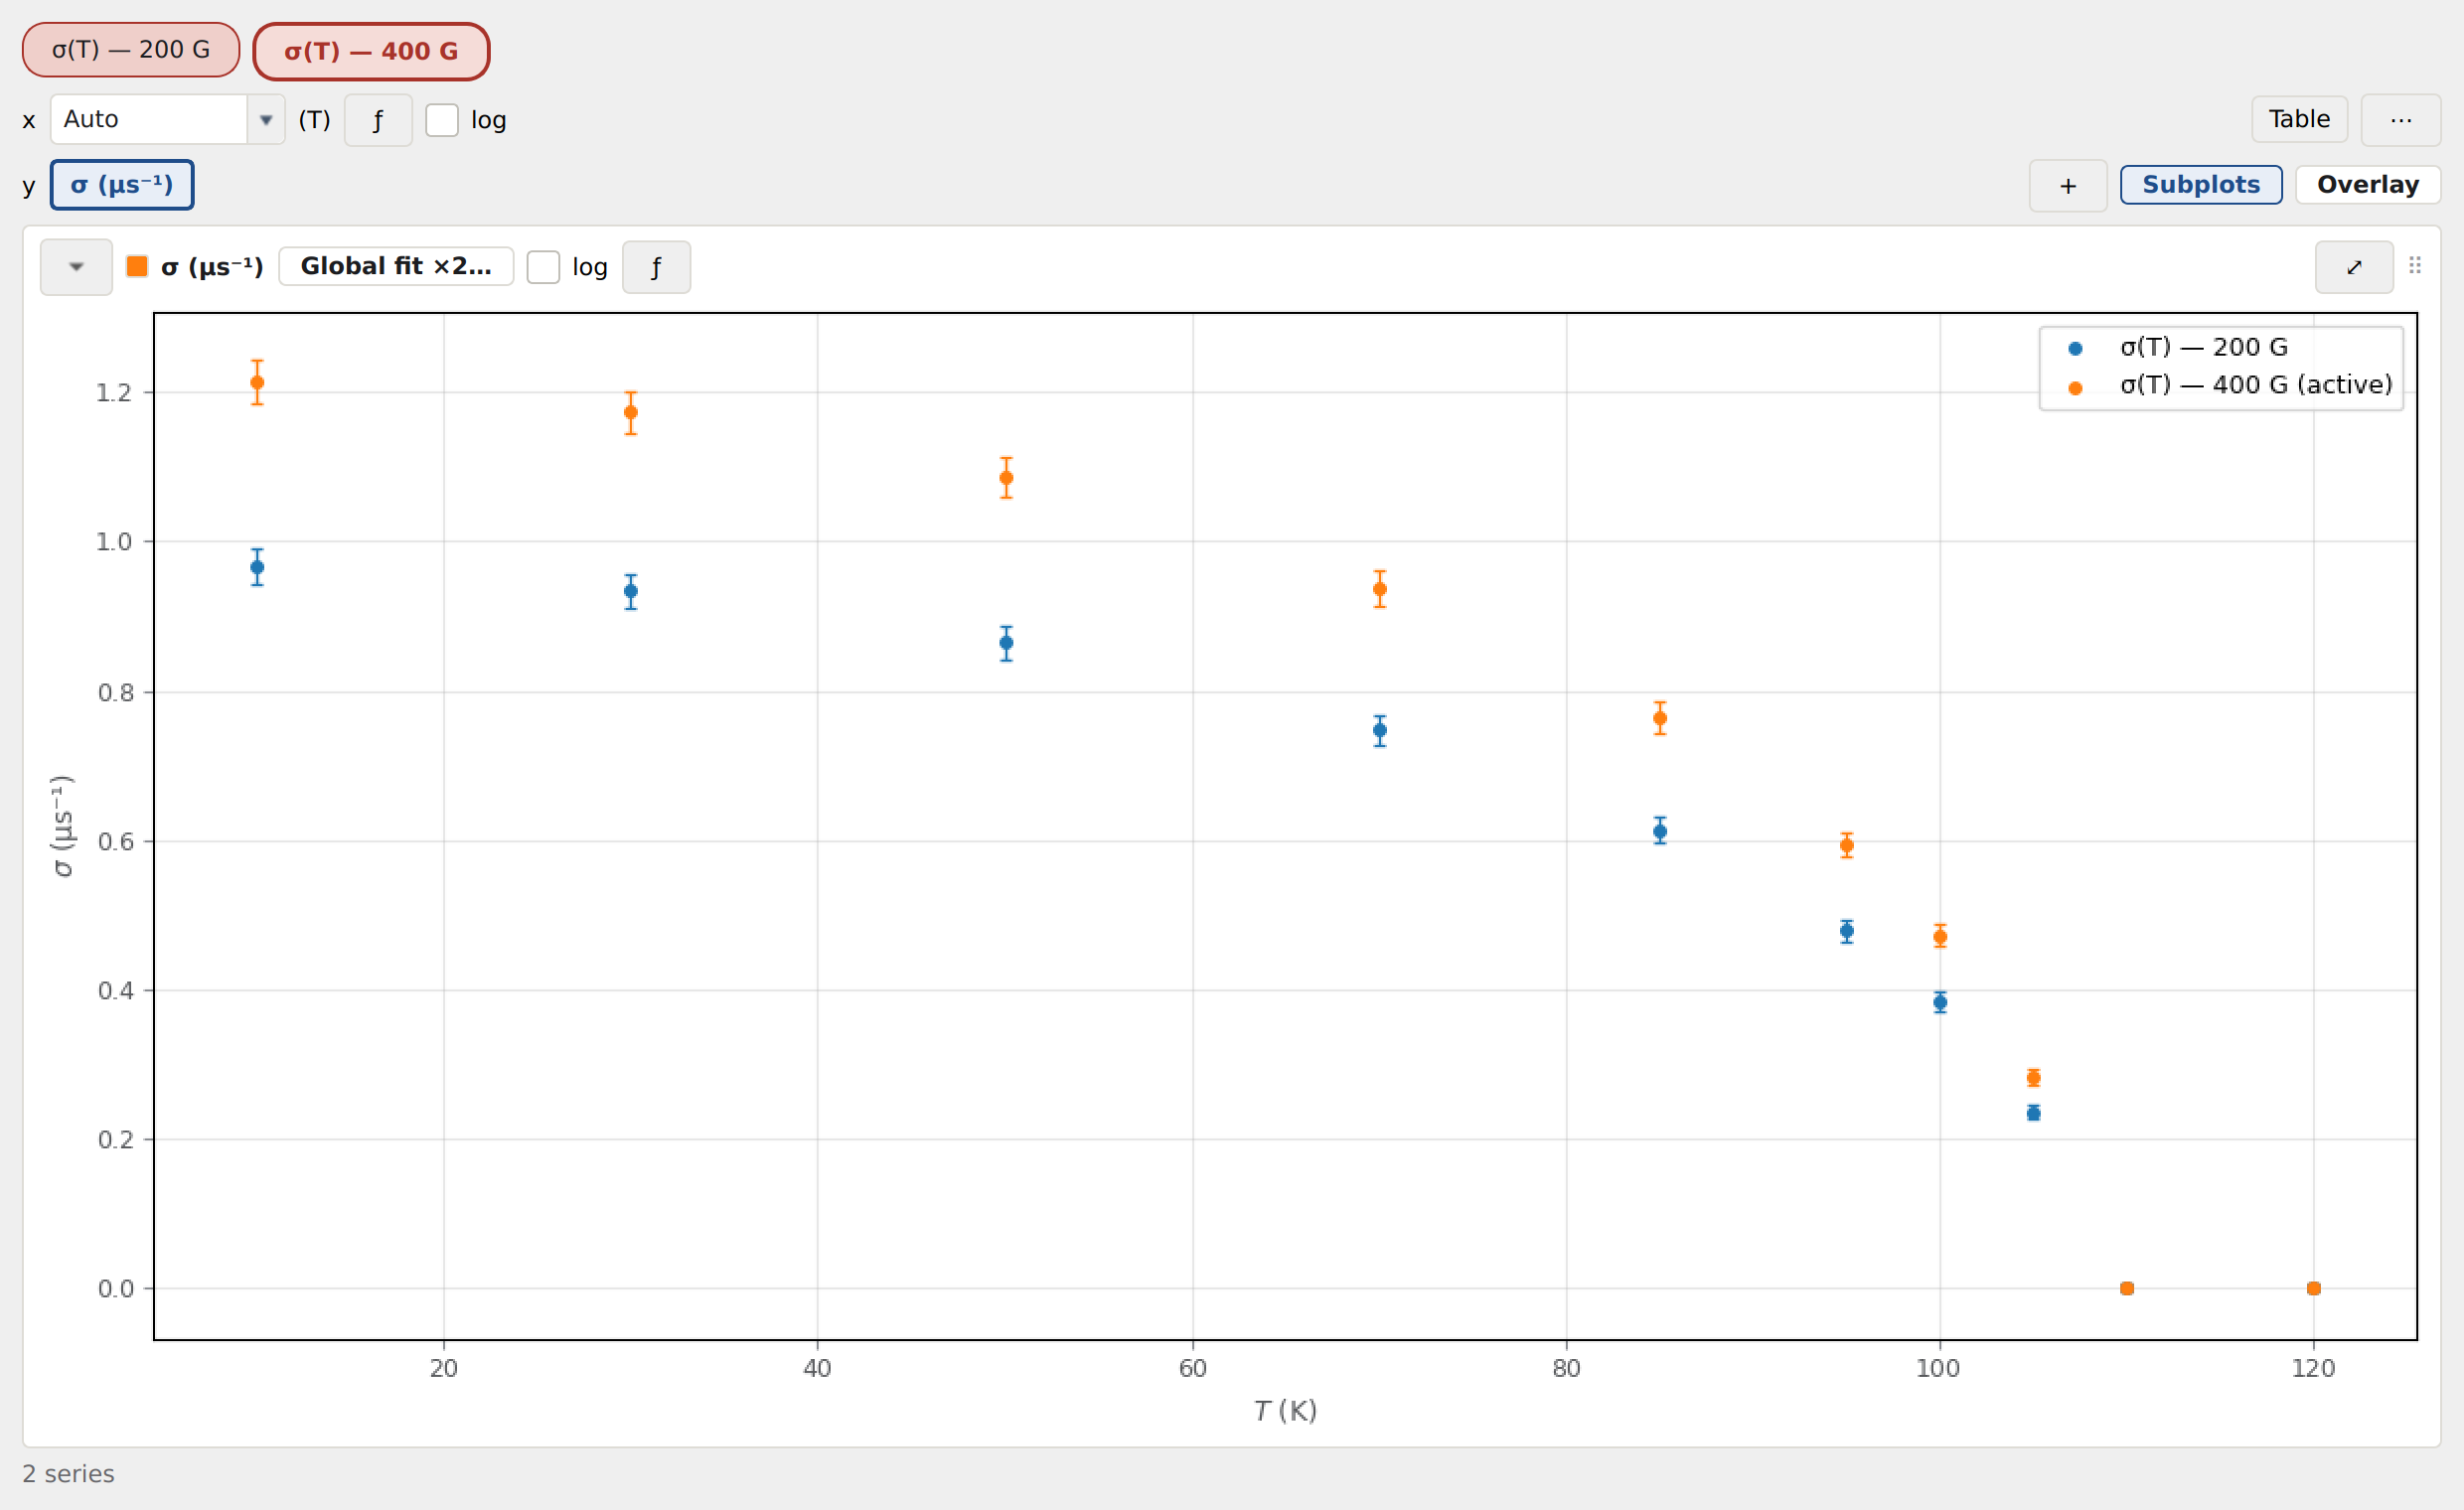
Two \(\sigma(T)\) series — a 400 G and a 200 G transverse-field scan —
overlaid on the σ (µs⁻¹) card. Colour encodes the series (legend
top-right, the active series flagged); with two series pills selected, the
footer reads 2 series and the card’s Fit button reads
Global fit ×2… — see Cross-Group Fitting
below. The 200 G plateau sitting below the 400 G one is the pancake-vortex
field dependence of the London second moment.
Phase-owned series
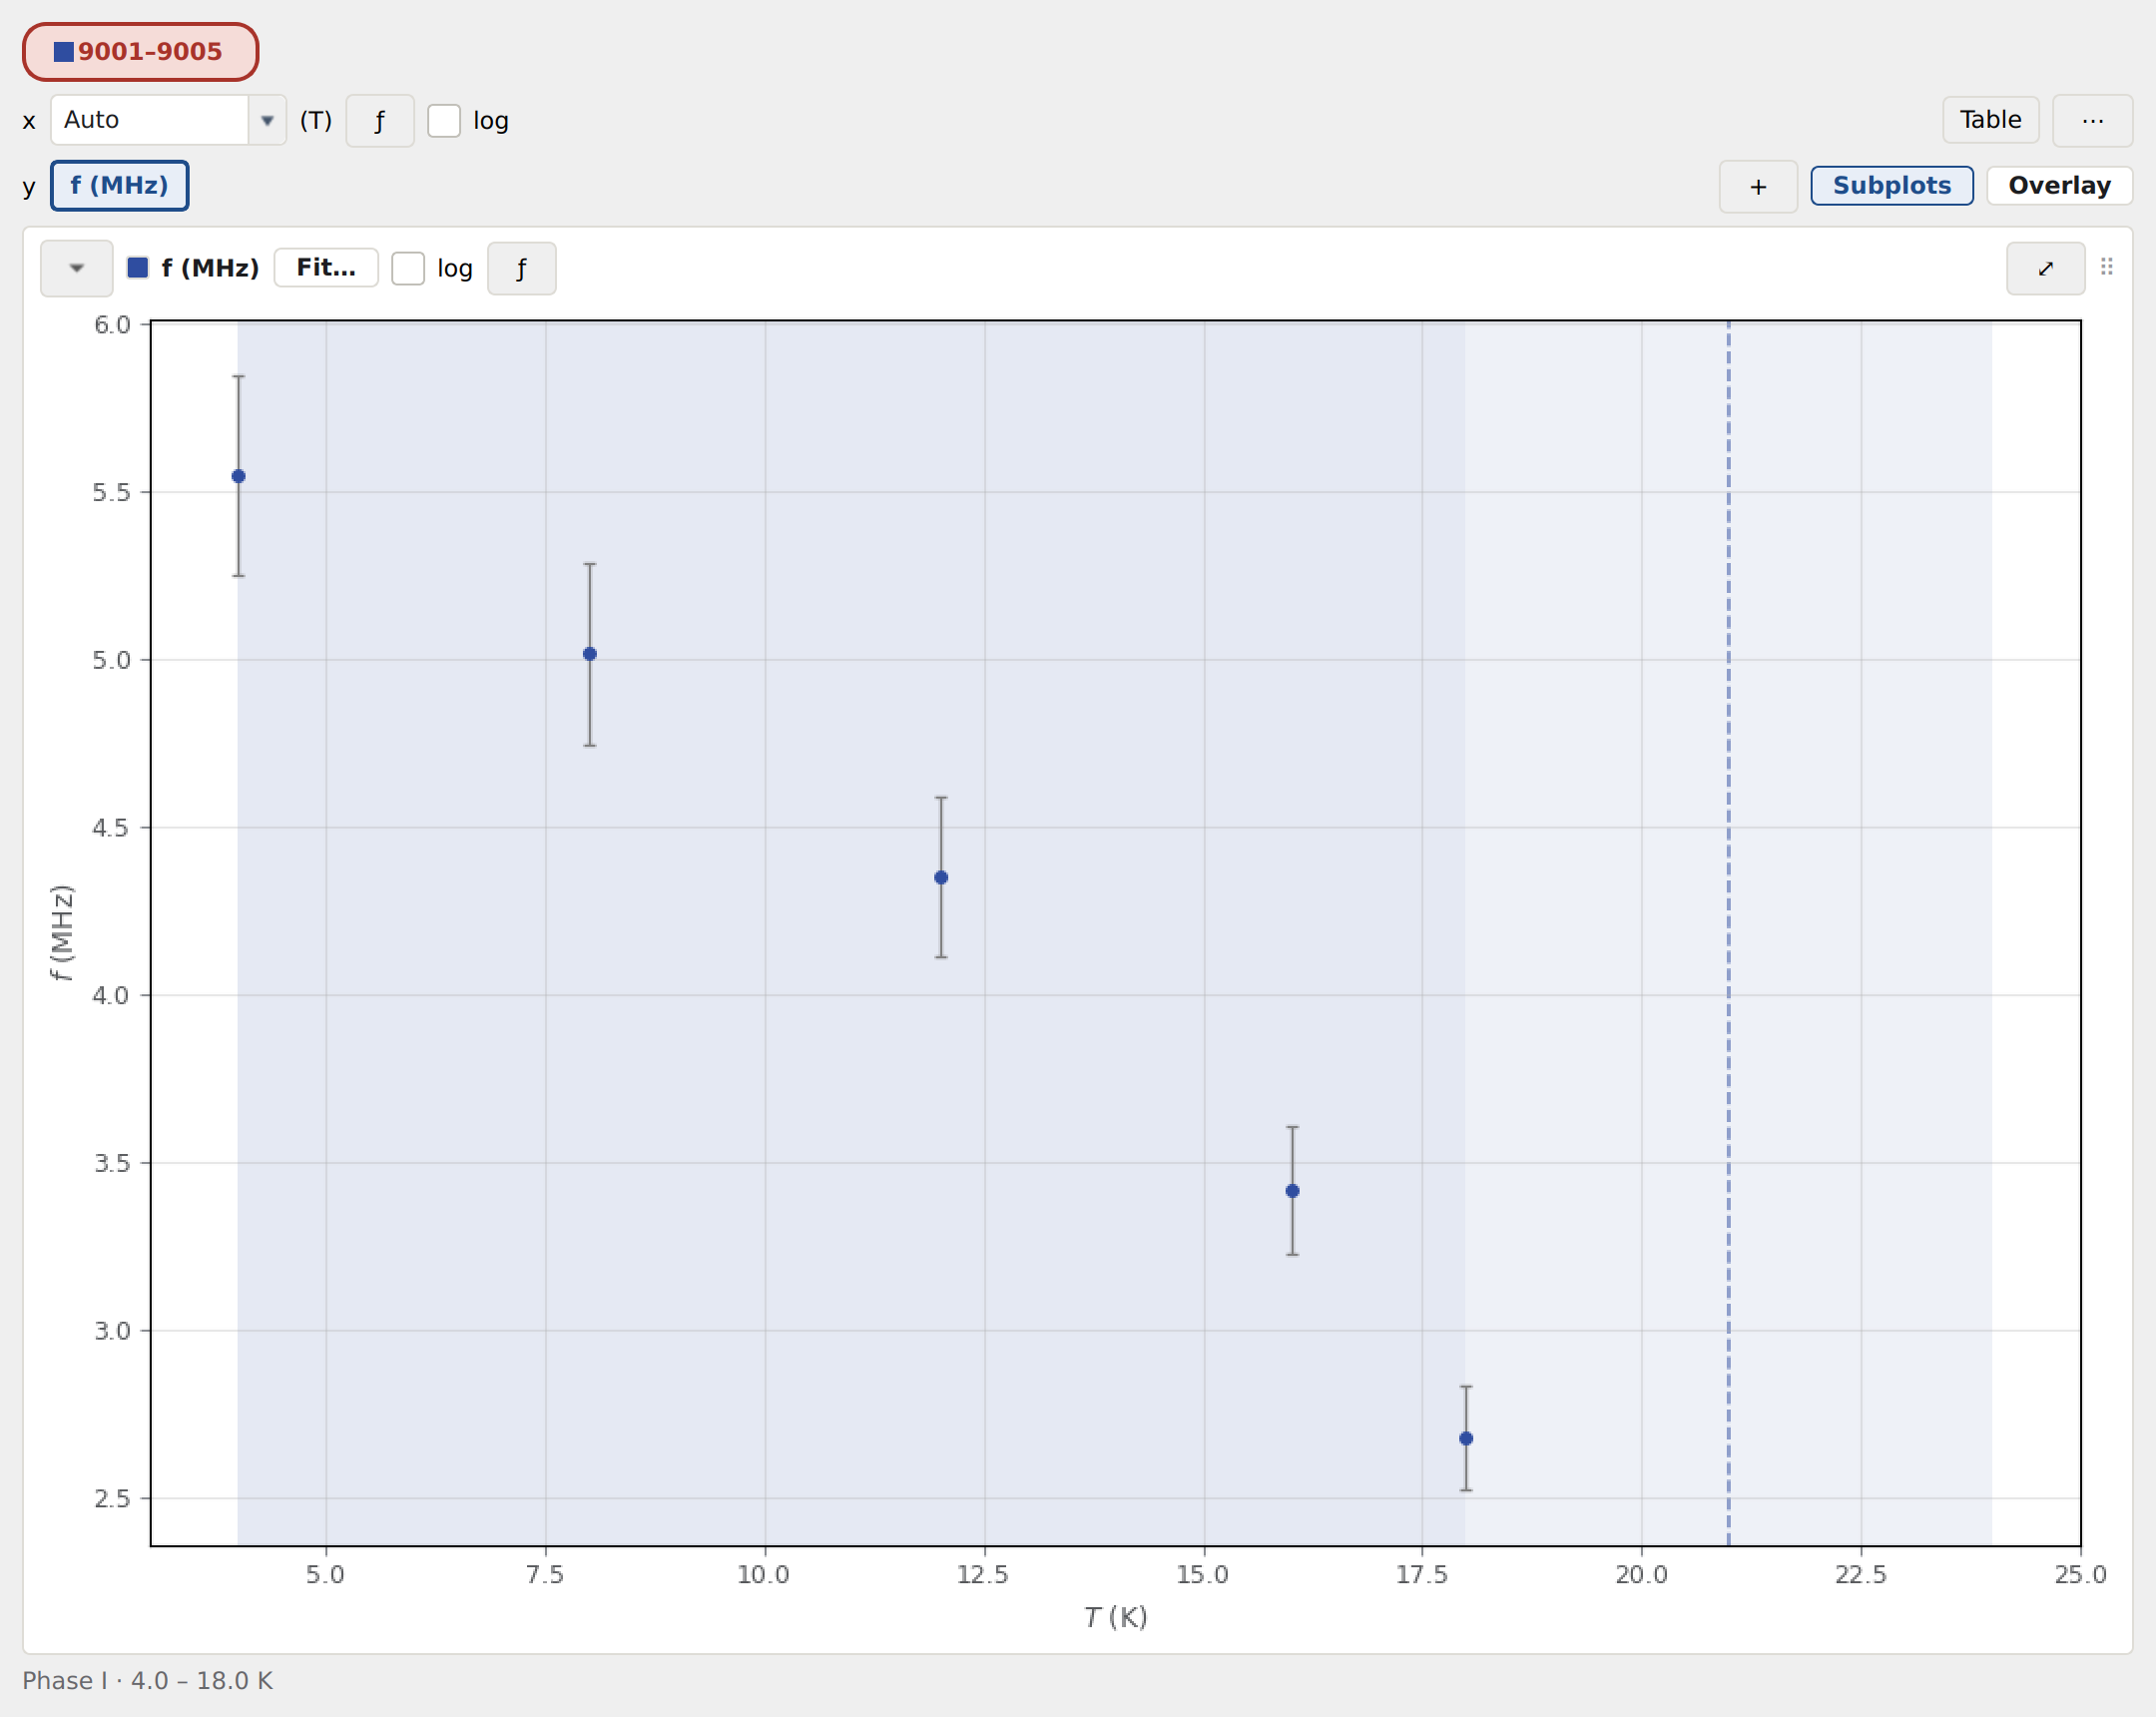
A phase-owned series: the swatch on the short series pill (its run range; the footer names the series in full) matches the plotted curve’s colour, the phase’s own run range is shaded beneath the points, and its upper boundary is drawn as a dashed line with a fainter uncertainty band.
A series recorded for one phase of a Global Fit Wizard partition (see Phases: transitions and the penalty path in Global fit wizard and Phases within a group in GUI usage) carries its phase’s identity into the trending panel. Its series button carries a small colour swatch, and when it is the active series its plotted curve uses the phase’s own colour instead of the ordinary series cycle — the same colour the Data Browser’s phase stripe and the wizard’s per-phase strip use, so a phase reads identically everywhere it appears.
When the active series belongs to a phase and the plotted X axis is that
phase’s own sweep axis, in its raw (untransformed, linear) form, the plot adds
two further decorations: the phase’s run range is shaded beneath the data
(a soft tint of the phase colour), and each boundary the wizard estimated for
it is drawn as a dashed vertical line at the estimate with a fainter shaded
band spanning its ± half_gap uncertainty — a series end with no boundary
on that side simply draws none. Switching to a log X axis, or applying an
axis transform (Redfield, Arrhenius, a custom
expression), moves the axis away from the coordinates the range and boundaries
were computed in, so the shading and lines are withheld until you switch back
— the swatch stays either way, since it is only an identity marker.
Export to GLE mirrors both the range shading and the boundary lines and
bands on the exported plot; the plain TSV export is unaffected, since the
decoration is a plot annotation rather than a data column.
Joint-fit series
A series stamped as a member of a joint fit is pulled out of its data-group section in the chip rail and grouped instead under its own section, titled with the joint fit’s label — a joint fit can compose series that carry different models or belong to different data groups, so it earns a section of its own rather than sitting under either member’s group. The section header’s tooltip lists every member’s full name, one per line — the joint fit’s own label is built from short member names (see Joint fits), so the full picture is one hover away.
A parameter the joint fit shares across members is, in every contributing series, still a Global one: it gets no chip and no card, and is never plotted as a per-run trend, exactly like any other Global parameter. It is still named by the footer’s “held constant” note, and for a shared parameter that note’s entry gains a suffix naming the joint fit: “<name> — shared across joint fit “<label>””. Joining a joint fit does not change a parameter’s Global-role behaviour; it only adds that one clause to the hint for the column the joint fit actually shares.
Representation-aware trending
The Fit Parameters panel automatically tracks which representation is active
in the central workspace. The Showing: row at the top of the panel
indicates the current representation — F-B Asymmetry, Detector Groups,
FFT, or MaxEnt — and the panel’s series buttons below show only the fit
series that belong to that representation.
Switching the central workspace view (e.g. from F-B asymmetry to Individual Groups) refreshes the panel instantly to show the grouped-fit series instead of the asymmetry ones. Switching back restores the asymmetry series. Each representation maintains its own independent set of series, x-axis selection, and derived composite parameters, so there is no risk of cross- contamination between a time-domain and a frequency-domain analysis.
When a series button is selected, the Data Browser highlights (in amber) the runs that belong to that series, making it easy to trace which runs contributed to the current trend.
Typical use cases include extracting the ordering temperature \(T_c\) and
the critical exponent \(\beta\) of a magnetic order parameter by fitting a
spontaneous precession frequency \(\nu(T)\) (or internal field) from a
zero-field (ZF) series with an OrderParameter form (see Magnetic Order Parameter below
and Temperature scan through a magnetic transition); locating a critical
temperature where a relaxation rate diverges with a CriticalDivergence
form; inverting the transverse-field (TF)
second-moment \(\sigma(T)\) into a London penetration depth using one
of the SC_* gap models (Superconductor penetration depth from σ(T)
and Superconducting penetration depth models); fitting an Arrhenius form to
\(\lambda(T)\) across a temperature scan for motional narrowing;
and field sweeps in either longitudinal-field (LF) or TF geometry, where the trending panel
handles parameter-vs-\(B\) identically to parameter-vs-\(T\). The
GUI panel is the right tool for interactive exploration and quick model
selection; exporting to a Python script (the snippets below) is the right
tool for reproducible, publication-grade analyses and for unusual
parametric models that are not in the built-in registry.
Fitting a trend model
Selecting a model, seeding it sensibly, and deciding which points it should see is the slow, error-prone part of trend analysis: a power law seeded far from the data walks into a bad minimum, and a critical divergence contaminated by the very region it cannot describe reports a meaningless \(T_c\). The model-fit dialog exists to make those decisions visible while you make them. It fits one parametric model through the selected “parameter versus X” points and shows the candidate curve against the data as you set it up, so a converging fit is apparent before you commit to it.
Open it from the Fit Parameters panel: choose the abscissa on the x rail (temperature, field, run number, angle, a fitted parameter, or a custom logbook column), check the trended quantity’s chip on the y rail, and click Fit… on its card. The button’s label tracks the card’s fit state:
State |
Button text |
|---|---|
No active fit |
|
Active fit with a successful curve |
|
Fit computed under an axis transform since changed (curve hidden) |
|
Two or more series pills selected |
|
Each state’s tooltip carries the longer explanation. The panel hands the dialog the included trend points for that parameter — a point excluded from the trend (via its context menu or the include checkbox) stays visible on the plot but does not pull the fit — together with their propagated errors and, when the abscissa is a fitted parameter, its per-point x-uncertainty.
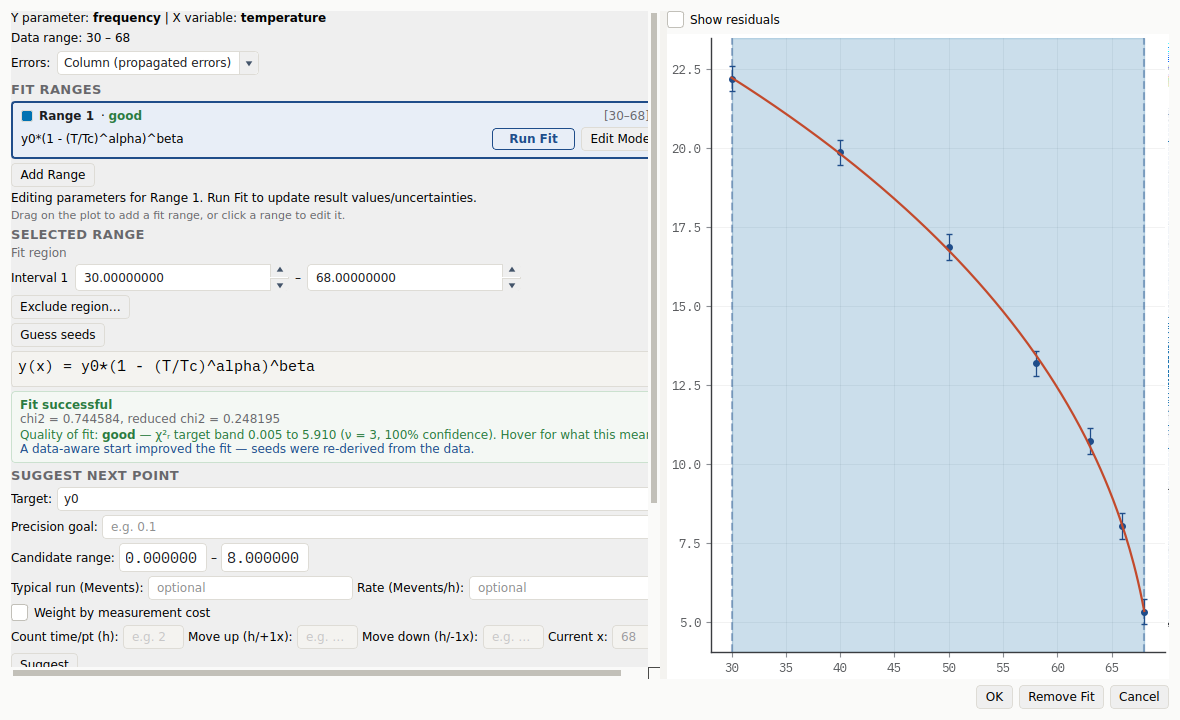
The model-fit dialog fitting the OrderParameter form to a synthetic EuO
spontaneous-precession-frequency trend \(\nu(T)\) through the Curie point.
The left pane carries the controls — error mode, the range card, the fit-region
editor, the seed table and the fit result; the right pane is the live preview,
with the candidate curve tracing the in-range points. The converged fit returns
\(T_c = 69.2(6)\) K and \(\beta = 0.41(8)\), with a good χ² verdict.
The model catalogue
The dialog offers only the basis models that make sense for the current
abscissa: the pool is drawn from component_names_for_x and filtered by each
component’s declared scope, so a temperature axis never lists a field-only form
and vice versa. The registry (grouped by the context that offers them) is:
Any axis (
common) —Constant,Linear,Quadratic(\(c_0 + c_1 x + c_2 x^2\), the plain parabola — e.g. a steering-curve minimum), and the general fifth-orderPolynomial;PowerLawand its quadrature-background variantPowerLawQuadBG; andExponentialDecay.Temperature axis —
Arrhenius(thermal activation),OrderParameter(a magnetic order parameter vanishing at \(T_c\)),CriticalDivergence(a rate diverging at \(T_c\)),FermiStep(a smooth step between two plateaus, such as the weak-transverse-field asymmetry through an ordering transition; see Transition step), and the superconducting gap modelsSC_SWave,SC_DWave, the anisotropic and non-monotonic forms (SC_AnisotropicS_Cos4,SC_NonmonotonicD,SC_PWaveAxial,SC_ExtendedS,SC_SPlusG), the phenomenologicalSC_AlphaModel, the two-gapSC_TwoGap_SS/SC_TwoGap_SD, and their \(q\)-weighted_Qcounterparts. These feed the \(\sigma(T) \to \lambda(T)\) inversion of Superconducting penetration depth models.Field axis — degree-fixed baselines
Cubic/Quartic/Quintic/Sextic(each a fixed-order restriction ofPolynomial, for resonance backgrounds of increasing curvature);Redfield; the resonance lineshapesLorentzian,GaussianLCR,LorentzianLCR, and the differential (red/green) pairLorentzianLCRPair(Integral scan mode (avoided-level-crossing field scans)); the muonium repolarisation curveMuRepolarisationand the exact-diagonalisation RF resonanceRFResonanceMuP; the longitudinal-field diffusion and ballistic transport formsDiffusionLF_1D/2D/3DandBallisticLF_1D/2D/3Dwith theLambda_bgbackground (Field-dependent transport models (DiffusionLF / BallisticLF)); and the Brandt vortex-lattice second-moment modelsSC_Brandt_VortexLatticeand its powder average.Angle axis —
KnightAnisotropy,AngularCos2, andAngularFourier2for a Knight shift mapped out by rotating a single crystal (Knight shift).
Any of these can be combined into a composite via Edit Model, which opens the
same two-panel builder used for time-domain functions (see Build a Parameter
Composite Model and the quadrature combinator ⊕). The dialog picks a
sensible default for a fresh range — Linear in general, but
OrderParameter automatically when the trended quantity is a magnetic
order-parameter observable (a precession frequency or internal field) versus
temperature, so the common critical-behaviour fit converges out of the box.
The live preview
The right-hand pane redraws as you edit: the data points (with error bars scaled to the current error mode), the in-range points against the greyed-out excluded ones, and the candidate model curve. The curve is sampled off the GUI thread — debounced, with stale results discarded — so dragging an edge or retyping a seed never freezes the dialog. The Show residuals toggle adds a \((\text{data} - \text{model})/\sigma\) strip with a \(\pm 1\sigma\) guide band beneath the plot. On a narrow window the preview auto-collapses behind a Show preview toggle so the controls stay usable.
The interactive fit region
Every fit is restricted to a fit region — the set of x-intervals a point must
fall inside to enter the fit. A range is defined by a range card (a colour
swatch matching its span on the plot, a χ²ᵣ status chip, and its compact bounds)
with Run Fit and Edit Model actions; Add Range adds another. The
region is sculpted, not assembled: it starts as one interval spanning the data
and you carve gaps out of it with Exclude region… (or by right-dragging
across the plot), leaving a list of included intervals shown in the Selected
range editor. This is the natural way to exclude a contaminated critical region
— fit CriticalDivergence on both sides of a transition while dropping the
points nearest \(T_c\) — while keeping one consistent model across the gap
(the fitted curve is drawn continuously through it). Directly on the preview you
can drag an interval edge, drag on empty space to add a new range, click a span
to select it, and right-drag to exclude a region.
Adding a second range is different from excluding a gap: separate ranges fit independent models to different parts of the abscissa (piecewise modelling), whereas the intervals of one range OR-combine into the mask of a single fit. Internally the two-or-more-interval case is stored as fit windows and the single-interval case as a plain range, so a fit region that carves down to one interval collapses back automatically and saved projects are unaffected.
Seeding and running
The seed (starting-value) table lists each model parameter with its start value,
bounds and a Fixed toggle; you can also type bounds to constrain the fit.
Starting values are chosen data-aware where it matters: the critical-temperature
components take \(T_c\) and amplitude seeds derived from the actual x/y data,
so an OrderParameter default lands close to the transition rather than at a
generic guess. Guess seeds re-derives data-aware starts for the selected
range’s free parameters on demand (fixed parameters are never touched), running
off the GUI thread. The fit itself is a bounded least-squares minimisation via
iminuit, and the dialog runs it from four extra deterministic starts in addition
to your own seed, keeping the run reproducible while making a bad local minimum
much less likely; when a parameter converges hard against a bound, or a
data-aware restart beats your seed, the dialog says so inline.
The Errors selector (Weighting and Error Modes) controls how each point is weighted, and after a successful fit the result box tints green and reports \(\chi^2\), \(\chi^2_r\), and the two-sided quality verdict (χ² Quality Verdict); the same verdict appears as the range card’s status chip.
Where the fit lands
Accepting the dialog with OK writes the fit back into the panel: the fitted
curve overlays the trend plot (and any GLE/TSV export of it), the fitted
parameters and uncertainties become readable, and the whole fit is stored with
the project’s trend series — the dialog remembers the last-used model per
(parameter, x-axis) within that project, so reopening it restores your
choice. The fit’s own outputs are also recorded as a new, trendable results
series (Model fit (single) · <parameter> vs <x>): each fit range
contributes one row of its fitted parameters and \(\chi^2_r\), indexed by the
centre of its fitted x-window, so a multi-range fit is immediately trendable in
turn (see Recursive Trending (Model-Fit Results as a Series)). Remove Fit
discards the fit and drops that series.
For jointly fitting several detector groups or samples with shared and local parameters, the panel routes two or more selected group series to a cross-group variant of the same dialog — same catalogue, live preview, error modes, and fit region, described under Cross-Group Fitting.
Trending one parameter against another
The x-axis need not be a run-level quantity. Below the fixed Auto / B /
T / Run entries, the x rail’s abscissa picker lists every fitted
parameter in the active series, so any parameter can be trended against any
other — for example a relaxation rate \(\lambda\) against a precession frequency
\(\nu\), both extracted per run. Internally the choice is the key
param:<name>; the core fit functions are x-agnostic, so no API change is
needed — pass the chosen parameter’s values as x:
result = fit_parameter_model(nu_values, lambda_values, lambda_errors,
                             model, params)
When the x-axis is a fitted parameter the field/temperature scope no longer applies (the abscissa is no longer a sample condition), so the component picker degrades to the common basis set — the same components offered for a run-index x. Field- and temperature-specific forms (penetration-depth gap models, order parameters) are hidden, because they describe a dependence on a physical control variable, not on another fitted quantity.
When to use this. Reach for parameter-vs-parameter trending when you suspect
a relationship between two fitted quantities rather than a dependence on the
external control — correlating a rate with an amplitude across a series, or
plotting an internal field against a measured frequency to check a linear
gyromagnetic relation. For the ordinary “property versus temperature or field”
analysis, keep the B / T axes.
Accounting for x uncertainty
When the abscissa is a fitted parameter it carries its own per-point uncertainty, which an ordinary least-squares fit (x exact) ignores. Tick Account for x uncertainty in the model-fit dialog — offered only for a parameter-vs-parameter x — to weight the fit by the effective variance
the first-order errors-in-variables treatment of Orear and York. The slope is
evaluated by a central finite difference, so it needs no analytic derivative,
and because the minimiser re-evaluates the weighting at every step it is
self-consistent at the minimum with no outer iteration. With
\(\sigma_x = 0\) it reduces exactly to ordinary least squares, so the
toggle is off by default and never changes a field/temperature/run fit.
Programmatically, pass xerr:
result = fit_parameter_model(nu_values, lambda_values, lambda_errors,
                             model, params, xerr=nu_errors)
The trend plot draws horizontal error bars from \(\sigma_x\) whenever the x-axis is a fitted parameter, independent of the toggle, so the spread is visible even when the fit treats x as exact.
When to use this. Switch it on when the x-parameter’s relative error is not small compared with the y-error divided by the local slope; otherwise the correction is negligible and the simpler exact-x fit suffices. The estimator is a first-order approximation: it inflates the parameter errors (correctly) and shifts the estimates slightly — the intended errors-in-variables behaviour.
Note
WiMDA’s Model layer treats the x-column as exact and has no x-error concept; the effective-variance option is an Asymmetry addition for physical correctness in parameter-vs-parameter fits. Total least squares (orthogonal distance regression) was considered and rejected: it offers no box constraints, and Asymmetry’s parameter models rely on bounds.
Available basis components
from asymmetry.core.fitting import component_names_for_x

print(component_names_for_x("field"))
print(component_names_for_x("temperature"))
Build a parameter composite model
In the GUI parameter-trending workflow, the Edit Model action opens the
same two-panel builder used for time-domain composite functions: a searchable
basis-model library on the left and the model as structured, reorderable rows
on the right. Each basis model becomes a single row, joined by +, -,
*, /, or the quadrature combinator ⊕ (below); parentheses group
sub-expressions. The library’s ⓘ Info button reports the documentation
for the currently selected basis model, including superconducting gap-model
details when relevant. Fraction groups are a time-domain-only concept and are
not offered here — ⊕ is the parameter-grammar’s dedicated combinator for
sharing a width-like budget between terms.
The builder validates the expression in real time, and the Model Fit dialog
shows the expanded y(x) preview above the parameter table as you edit.
from asymmetry.core.fitting import ParameterCompositeModel

model = ParameterCompositeModel(
    component_names=["DiffusionLF_2D", "Redfield", "Lambda_bg"],
    operators=["+", "+"],
)
print(model.formula_string())
Grouped expressions are also supported programmatically and in the GUI, for
example Linear + (Arrhenius * Constant).
Quadrature combinator (⊕)
The parameter-vs-x builder adds one operator beyond ordinary arithmetic: the quadrature combinator
which composes two components as the square root of the sum of their squares.
It is the natural composition rule for width-like quantities — relaxation
rates, linewidths, second moments — where independent broadening channels add
in quadrature rather than linearly. ⊕ is binary, commutative, and
associative (a ⊕ b ⊕ c \(= \sqrt{a^2 + b^2 + c^2}\)); it binds at the
same precedence as + and -, so a ⊕ b * c evaluates the product
first and a ⊕ b + c reads as \(\sqrt{a^2 + b^2} + c\). Use parentheses
to override the default grouping.
from asymmetry.core.fitting import ParameterCompositeModel

model = ParameterCompositeModel.from_expression("PowerLaw ⊕ Constant")
print(model.formula_string())
The identity PowerLaw ⊕ Constant \(\equiv\) PowerLawQuadBG is exact —
the operator generalises the fixed
quadrature-background component to any pair of
basis models. The parameter mapping is direct: the composite’s dedicated
parameters are a, n, c_1 (the power law’s own additive constant) and
c_2 (the constant term), so the monolith’s BG maps to c_2 while
c_1 must be fixed at 0 for the equivalence to hold — the
PowerLawQuadBG inner term carries no additive offset.
When to use this. Reach for ⊕ whenever a fitted quantity is the quadrature
sum of two contributions — most often a signal of interest riding on an
incoherent background floor (a residual linewidth, an instrumental second
moment). When the background is instead a genuine additive offset of the
observable, use + with a Constant.
Note
⊕ is a parameter-grammar operator only; the time-domain composite
function builder does not offer it (quadrature of two time-domain muon
components has no established meaning). In displayed formulae and GLE exports
the operator is shown as the ⊕ glyph rather than expanded to a square
root. WiMDA has no general quadrature operator — only the fixed
PowerLawQuadBG-style model — so this is an Asymmetry generalisation.
Single-Series Fit
import numpy as np
from asymmetry.core.fitting import Parameter, ParameterSet, fit_parameter_model

field = np.array([20.0, 50.0, 100.0, 200.0, 400.0, 800.0])
values = np.array([2.7, 2.2, 1.6, 1.1, 0.7, 0.5])
errors = np.full_like(values, 0.1)

params = ParameterSet([
    Parameter("A", value=3.0, min=0.0),
    Parameter("D_2D", value=0.7, min=0.0),
    Parameter("D_perp", value=0.0, min=0.0),
    Parameter("D", value=10.0, min=0.0),
    Parameter("nu", value=10.0, min=0.0),
    Parameter("m", value=2.0, min=0.0),
    Parameter("lambda_BG", value=0.0, min=0.0),
])

result = fit_parameter_model(field, values, errors, model, params)
print(result.success, result.reduced_chi_squared)
Weighting and error modes
By default a model fit weights each point by the propagated error of the
trended parameter (Column mode). The Errors selector in the model-fit
dialog (and the error_mode argument of fit_parameter_model) offers
four alternatives for when those errors are absent or untrustworthy:
Percent of y — \(\sigma_i = (p/100)\,|y_i|\). Points with \(y_i = 0\) carry no error information and are excluded from the fit.
Absolute — one constant \(\sigma\) for every point.
None — unit weights. The fitted parameters are the unweighted least-squares solution; \(\chi^2\) loses its absolute meaning.
Estimate from scatter — an unweighted fit whose parameter uncertainties are rescaled by \(\sqrt{\chi^2/\nu}\) afterwards. This is the standard way to quote errors when the only information about the noise is the scatter of the points themselves. It is exactly the converged limit of WiMDA’s Estimate mode (which rescales its constant \(\sigma\) by \(\sqrt{\chi^2_r}\) after each fit until \(\chi^2_r = 1\)): because a uniform error rescale never moves the minimum, the iteration lands on the same answer in one step.
In Column mode (only), errors are floored at half the median positive error before fitting, so a single near-zero propagated error cannot dominate the fit; explicit Percent/Absolute choices are honoured verbatim. With unit weights or scatter-estimated errors, \(\chi^2_r\) is forced toward 1 by construction and carries no goodness-of-fit information — the quality verdict (below) is suppressed in those modes.
result = fit_parameter_model(
    field, values, None, model, params, error_mode="scatter"
)
Fit windows (union multi-range)
A fit range may be restricted to a union of (min, max) windows: a point
enters the fit if it falls in any window, and a single model is fitted
across all of them. Use + Window on a range row in the model-fit dialog,
or pass windows to fit_parameter_model. The fitted curve is drawn
continuously through the excluded gaps.
The canonical use is excluding a critical region: a relaxation rate
\(\lambda(T)\) diverging at \(T_c\) is well described by
CriticalDivergence on both sides of the transition, but the points
nearest \(T_c\) are dominated by physics the power law does not capture
(and by the singularity itself). Fitting the union
\([T_{\min}, T_c - \delta] \cup [T_c + \delta, T_{\max}]\) keeps one
consistent model with the contaminated region excluded:
result = fit_parameter_model(
    temperature, rate, rate_errors, model, params,
    windows=[(40.0, 64.0), (74.0, 100.0)],
)
This differs from adding a second range in the dialog: separate ranges fit independent models (piecewise modelling), whereas windows OR-combine into the mask of one model.
χ² quality verdict
After a successful fit the dialog reports a quality verdict alongside \(\chi^2_r\). For a correct model with correct error bars, \(\chi^2\) follows the chi-squared distribution with \(\nu = N - N_{\mathrm{free}}\) degrees of freedom, so at 95 % confidence a good fit’s \(\chi^2_r\) falls inside a band around 1 that tightens as \(\nu\) grows (for \(\nu = 10\) the band is 0.32–2.05; for \(\nu = 50\), 0.65–1.43). The verdict is two-sided:
good — \(\chi^2_r\) inside the band.
poor — above the band: the model misses real structure, or the errors are underestimated.
overdone — below the band: the fit reproduces the data better than the errors allow, which usually means overestimated errors or too many free parameters soaking up noise.
The verdict assumes real (Column-mode) errors and is suppressed for
unit-weight and scatter-estimated fits. Programmatic access is via
asymmetry.core.fitting.assess_fit_quality(chi_squared, dof), which
returns the verdict and the band.
Cross-group fitting
For jointly fitting multiple groups with shared and local parameters, use
global_fit_parameter_model with ParameterGroupData entries.
from asymmetry.core.fitting.parameter_models import (
    ParameterGroupData,
    global_fit_parameter_model,
)

groups = [
    ParameterGroupData(
        group_id="g1",
        group_name="Sample A",
        x=field,
        y=values,
        yerr=errors,
        group_variable_value=5.0,
    ),
    ParameterGroupData(
        group_id="g2",
        group_name="Sample B",
        x=field,
        y=values * 1.1,
        yerr=errors,
        group_variable_value=15.0,
    ),
]

result = global_fit_parameter_model(
    groups=groups,
    model=model,
    global_params=["D_2D", "D", "nu", "m"],
    local_params=["A", "lambda_BG"],
    fixed_params={"D_perp": 0.0},
)
print(result.success)
The cross-group fit honours the same error modes and fit windows as a
single-series fit. The cross-group dialog now shows the Errors selector and
+ Window controls, and global_fit_parameter_model accepts the matching
error_mode, error_value, and windows arguments; the chosen mode and
window union apply to every group. In Estimate from scatter mode the
\(\sqrt{\chi^2/\nu}\) rescale is applied to both the shared global
uncertainties and every group’s local uncertainties.
result = global_fit_parameter_model(
    groups=groups, model=model,
    global_params=["m"], local_params=["b"], fixed_params={},
    error_mode="scatter", windows=[(0.0, 40.0), (60.0, 100.0)],
)
When the cross-group abscissa is itself a fitted parameter, the same
effective-variance x-uncertainty treatment used for single-series fits
(Accounting for x Uncertainty) is available here too. Tick Account for x
uncertainty in the cross-group dialog, or pass per-group \(\sigma_x\)
arrays as xerr (keyed by group_id); each group’s points are weighted by
\(\sigma_{y}^2 + (\partial f/\partial x)^2\,\sigma_x^2\) with the same
estimator as the single-series path. It is off by default, reduces exactly to
ordinary least squares when \(\sigma_x = 0\), and is ignored under the
None / Estimate from scatter modes (whose unit weights carry no scale to
combine with \(\sigma_x\)).
result = global_fit_parameter_model(
    groups=groups, model=model,
    global_params=["m"], local_params=["b"], fixed_params={},
    xerr={"g1": nu_errors_g1, "g2": nu_errors_g2},
)
Recursive trending (model-fit results as a series)
A successful cross-group fit is itself recorded as a new trend series, named
Model fit: <parameter> vs <x>, alongside the original fit series in the Fit
Parameters panel. Each selected group contributes one row carrying that group’s
local parameters (with the shared global parameters as constant columns),
indexed by the group’s orthogonal coordinate — temperature for a field fit, and
vice versa; a final globals row carries the shared parameters and
\(\chi^2_r\). Because this results series is an ordinary trend series, it
can be trended again — fit the per-group local rate against temperature, for
instance — so the analysis recurses naturally. This supersedes WiMDA’s separate
second-level Model Fit Table, which only stored the rows for inspection.
Re-running the same cross-group fit (same parameter, x-axis, and group set) replaces its results series rather than accumulating duplicates.
Single-fit ranges. A single-series fit is recorded the same way: each fit
range contributes one row to a Model fit (single): <parameter> vs <x>
series, carrying that range’s fitted parameters and \(\chi^2_r\), indexed by
the centre of the range’s fitted x-window (in the trend’s own x-units, also kept
as a range_center column). A multi-range fit — for example one model below a
transition and another above — is therefore immediately trendable: plot a fitted
coefficient against the window centre to see how it drifts across the data.
Trending shared globals across fits. Every successful cross-group fit also
appends one row to a persistent Global summary series, carrying that fit’s
shared global parameters, \(\chi^2_r\), and a monotonic fit_index.
Because the globals from successive fits accumulate in one series, they can be
trended against each other or against fit_index — the natural way to follow a
shared parameter as you sweep a model choice, a fixed value, or a group set
across a sequence of joint fits. Re-running a given fit updates its row in place
(keyed by the same parameter / x-axis / group set), so the series records one row
per distinct fit. These rows sit off the physical field/temperature axes;
select fit_index or a global parameter as the x-axis (see
Trending One Parameter Against Another) to trend them.
Magnetic order parameter
For a second-order magnetic transition, the spontaneous muon precession
frequency, the internal field, or an ordered-moment-like asymmetry follows an
order-parameter temperature dependence that rises continuously from zero at the
ordering temperature \(T_c\) to a saturated value \(y_0\) at
\(T = 0\). The OrderParameter basis model captures this with a
generalised two-exponent form:
Here \(y_0\) carries the unit of the trended observable (MHz for
\(\nu(T)\), G or T for an internal field, % for an asymmetry), \(\beta\)
is the critical exponent that dominates the near-\(T_c\) shape (typically
0.33–0.37 for 3D Heisenberg/Ising magnets, 0.5 for mean field), and the shape
exponent \(\alpha\) controls the departure from a pure power law away from
\(T_c\). Fixing \(\alpha = 1\) recovers the simple near-\(T_c\)
power law \(y_0 (1 - T/T_c)^{\beta}\). The model is exactly zero above
\(T_c\), so include the ordered-phase points and let \(T_c\) fall inside
the fitted range. Use CriticalDivergence instead for quantities that
diverge at \(T_c\) (such as a relaxation rate), not for an order
parameter that vanishes there.
import numpy as np
from asymmetry.core.fitting import (
    Parameter,
    ParameterSet,
    ParameterCompositeModel,
    fit_parameter_model,
)

# Spontaneous precession frequency nu(T) through Tc.
temperature = np.array([1.5, 20.0, 40.0, 55.0, 62.0, 66.0, 68.0])
nu = np.array([29.9, 29.1, 26.0, 20.6, 15.4, 9.6, 5.7])
errors = np.full_like(nu, 0.3)

model = ParameterCompositeModel(["OrderParameter"], operators=[])
params = ParameterSet([
    Parameter("y0", value=30.0, min=0.0),
    Parameter("Tc", value=69.0, min=0.0),
    Parameter("beta", value=0.36, min=0.0),
    Parameter("alpha", value=1.0, min=0.0),  # fix to fit the near-Tc power law
])

result = fit_parameter_model(temperature, nu, errors, model, params)
print(result.success, result.reduced_chi_squared)
for p in result.parameters:
    print(p.name, p.value, result.uncertainties.get(p.name))
Transition step
Not every observable across a magnetic transition behaves like an order
parameter. In a weak transverse field (wTF), only muons in paramagnetic regions
precess coherently in the applied field; muons in ordered regions are dephased by
the large, broadly distributed internal field. The wTF oscillation amplitude
therefore falls on cooling from the full paramagnetic asymmetry to the
background, and the size of the drop measures the magnetic volume fraction. In
zero field, a polycrystalline magnet loses the rapidly dephased 2/3 of its
sample asymmetry below the ordering temperature, leaving the 1/3 tail. Both
trends are steps between two plateaus rather than a power law, and the
μSR literature models them with a Fermi-function (logistic) step. The
FermiStep basis model is
\(A_1\) and \(A_2\) are the low- and high-temperature plateaus, in the unit of the trended observable. Either may be the larger, so the same form fits the rising wTF asymmetry and a falling zero-field tail without a sign change. \(T_c\) is the midpoint, where \(y\) lies halfway between the plateaus, and \(\Delta T\) is the width: the 10–90 % rise spans \(2\ln 9\,\Delta T \approx 4.4\,\Delta T\). When the low-temperature plateau is pure background, the magnetic volume fraction follows as \(f_\mathrm{m}(T) = [A_2 - y(T)]/(A_2 - A_1)\); for a zero-field tail, scale the lost asymmetry by 3/2 to account for the unobserved 2/3 component [3].
A broad \(\Delta T\) is best read as a distribution of local transition temperatures across the sample, not as critical behaviour. The logistic step corresponds to a logistic distribution with standard deviation \(\pi\Delta T/\sqrt{3} \approx 1.8\,\Delta T\); a Gaussian distribution gives the closely similar error-function step, which differs mainly in the tails. The midpoint need not coincide with the ordering temperature: Steele et al. place \(T_N\) near \(T_c - \Delta T\) because the relaxation rate peaks just above the transition [2]. The fit seeds itself from the data — the plateaus from the coldest and warmest fifth of the points, \(T_c\) from the half-step crossing, and \(\Delta T\) from the 10–90 % crossings — so it converges without a hand reseed. \(\Delta T\) has a small positive lower bound (\(10^{-6}\) K), because a zero width is undefined at \(T = T_c\).
Published forms of the same step use different names and sign conventions:
Published form |
|
|---|---|
\(A_s(0)/(1 + e^{(T_N - T)/\Delta T_N}) + A_\mathrm{bg}(0)\) [1] |
\(A_1 = A_\mathrm{bg}(0)\), \(A_2 = A_s(0) + A_\mathrm{bg}(0)\), \(T_c = T_N\), \(\Delta T = \Delta T_N\). |
\(A_2 + (A_1 - A_2)/(e^{(T - T_\mathrm{mid})/w} + 1)\) [2] |
Identical, with \(T_c = T_\mathrm{mid}\) and \(\Delta T = w\). |
Mantid |
|
\(A_H \tanh[k_H (T - T_0)] + c_H\) |
\(A_1 = c_H - A_H\), \(A_2 = c_H + A_H\), \(T_c = T_0\), \(\Delta T = 1/(2 k_H)\). |
import numpy as np
from asymmetry.core.fitting import (
    Parameter,
    ParameterSet,
    ParameterCompositeModel,
    fit_parameter_model,
)
from asymmetry.core.fitting.parameter_models import suggest_trend_seeds

# wTF initial asymmetry through a Néel transition at 50 K.
rng = np.random.default_rng(1)
temperature = np.arange(40.0, 61.0, 1.0)
a0 = 0.112 + 0.111 / (1.0 + np.exp((50.0 - temperature) / 0.8))
a0 += rng.normal(0.0, 0.002, temperature.size)
errors = np.full_like(a0, 0.002)

model = ParameterCompositeModel(["FermiStep"])
seeds = suggest_trend_seeds(model, temperature, a0)
params = ParameterSet([
    Parameter("A1", value=seeds["A1"]),
    Parameter("A2", value=seeds["A2"]),
    Parameter("Tc", value=seeds["Tc"], min=0.0),
    Parameter("dT", value=seeds["dT"], min=1e-6),
])

result = fit_parameter_model(temperature, a0, errors, model, params)
for p in result.parameters:
    print(p.name, p.value, result.uncertainties.get(p.name))
References
R. Khasanov, G. Simutis, Y. G. Pashkevich, T. Shevtsova, W. R. Meier, M. Xu, S. L. Bud’ko, V. G. Kogan, and P. C. Canfield, Phys. Rev. B 102, 094504 (2020).
A. J. Steele, T. Lancaster, S. J. Blundell, P. J. Baker, F. L. Pratt, C. Baines, M. M. Conner, H. I. Southerland, J. L. Manson, and J. A. Schlueter, Phys. Rev. B 84, 064412 (2011).
Frandsen et al., Nat. Commun. 7, 12519 (2016).
Polynomial trends
Polynomial fits an empirical trend or background up to fifth order,
with all six coefficients available as fit parameters. Fix the unused high-order coefficients at 0 to fit lower orders — for a quadratic background, free \(c_0\)–\(c_2\) and fix \(c_3\)–\(c_5\). Use it when no physical model is available, or as the smooth background under resonance lineshapes (see the LCR recipe below). Two cautions apply to any polynomial fit: the coefficients are only meaningful inside the fitted window (polynomials extrapolate badly), and the order should be the lowest the residuals support — a freed high-order term that the data does not constrain will soak up noise and inflate the uncertainties of every other coefficient.
Power law with quadrature background
PowerLawQuadBG combines a power law with a constant background in
quadrature,
which is the natural composition rule for width-like quantities —
relaxation rates, linewidths, second moments — where independent broadening
channels add as squares. At small \(x\) the curve saturates smoothly at
\(\mathrm{BG}\) instead of falling linearly onto an offset; at large
\(x\) it approaches the bare power law. Use the plain PowerLaw
(with its additive constant) when the background is a genuine offset of
the observable itself rather than an independent broadening channel.
This fixed component is the special case PowerLaw ⊕ Constant of the general
quadrature combinator (above); reach for ⊕ when either side of the
quadrature sum is a richer model than a bare power law or constant.
Muonium repolarisation
MuRepolarisation measures a muonium hyperfine constant from a
longitudinal-field scan, without resolving any precession. In an applied
field \(B\) along the initial muon polarisation, the only muonium
transition that mixes the muon spin states is suppressed as the field
decouples the muon and electron spins; time-averaging the unresolved fast
oscillation leaves the repolarisation curve
rising from half the muonium amplitude at \(B = 0\) (the other half is lost to the unobserved oscillation) to the full amplitude once \(B \gg B_0\), on top of a field-independent diamagnetic baseline \(a_{\mathrm{Dia}}\). The component is parameterised directly by the hyperfine constant \(A_{\mathrm{hf}}\) (MHz) — the quantity the experiment is designed to extract — with \(B_0\) derived internally from CODATA gyromagnetic ratios. For vacuum muonium (\(A_{\mathrm{hf}} = 4463\;\mathrm{MHz}\)), \(B_0 \approx 1585\) G, and the curve reaches three quarters of the muonium amplitude at exactly \(B = B_0\).
Fit it to an initial-asymmetry or integral-asymmetry LF scan (built with the integral-asymmetry observable, Integral scan mode (avoided-level-crossing field scans), x-axis in G). It is the standard method when the hyperfine coupling is too large for the precession to be resolved directly. The model assumes an isotropic (vacuum-like) hyperfine interaction observed in time average: anisotropic muonium, rapid chemical reaction, or spin exchange distort the curve, and any missing fraction appears as a reduced \(a_{\mathrm{Mu}}\).
A radical repolarisation curve that keeps rising past where one isotropic
term saturates is not evidence against this model, only against a single
term: a muoniated radical whose coupled nuclei each decouple at their own
field is fitted as a sum of MuRepolarisation terms, one per resolvable
half-rise, each contributing its own \(a_{\mathrm{Mu}}\) and
\(A_{\mathrm{hf}}\); only the lowest-\(B_0\) term’s
\(a_{\mathrm{Dia}}\) should be left free; the shared low-field
diamagnetic plateau the curve starts from cannot be resolved into a separate
baseline per term, and the model sums every term’s own. asymmetry
integral-scan --model (Scripting and AI-agent workflow) seeds each term from a
successive half-rise in the data — the field at which the curve has covered
half its rise is that term’s \(B_0\), by the identity above — the way
LorentzianLCR terms are seeded from successive resonances. A genuinely
anisotropic or multi-nucleus radical, where the transitions do not separate
into independent half-rises this way, needs a model this workflow does not
yet have.
import numpy as np
from asymmetry.core.fitting import (
    Parameter,
    ParameterSet,
    ParameterCompositeModel,
    fit_parameter_model,
)

field_G = np.array([0.0, 50.0, 150.0, 400.0, 1000.0, 2500.0, 6000.0, 15000.0])
asym = np.array([12.6, 12.7, 13.1, 14.2, 16.4, 19.0, 21.0, 21.9])
errors = np.full_like(asym, 0.2)

model = ParameterCompositeModel(["MuRepolarisation"])
params = ParameterSet([
    Parameter("a_Mu", value=10.0),
    Parameter("A_hf", value=4000.0, min=1.0),
    Parameter("a_Dia", value=5.0),
])

result = fit_parameter_model(field_G, asym, errors, model, params)
print({p.name: p.value for p in result.parameters})
References
S. J. Blundell, R. De Renzi, T. Lancaster, and F. L. Pratt, Muon Spectroscopy: An Introduction (Oxford University Press, Oxford, 2022).
Patterson, Rev. Mod. Phys. 60, 69 (1988).
Orear, Am. J. Phys. 50, 912 (1982).
D. York, N. M. Evensen, M. L. Martínez, and J. De Basabe Delgado, Am. J. Phys. 72, 367 (2004).
RF-μSR resonance (muon + electron + proton)
RFResonanceMuP fits a field-swept RF-μSR resonance scan of a muoniated
radical — muon plus electron plus one dominant proton, such as the
cyclohexadienyl radical C₆H₆Mu formed in benzene — and extracts the muon and
proton hyperfine couplings \(A_\mu\) and \(A_p\) simultaneously. This
is the Asymmetry counterpart of WiMDA’s RigiWorkshopFit exact-diagonalisation
RF model.
At a fixed applied RF frequency \(\nu_{\mathrm{RF}}\), the static field is swept and the (Red − Green) integral asymmetry shows two resonance features. A resonance occurs where an RF-driven muon-spin-flip transition of the three-spin Hamiltonian
matches \(\nu_{\mathrm{RF}}\). The two resonance fields \(B_1, B_2\) are found by exact diagonalisation of the 8×8 Hamiltonian (the high-field-limit linear relation \(B_\mathrm{res} = (\nu_{\mathrm{RF}} \pm \tfrac{1}{2}A_\mu)/\gamma_\mu\) is inaccurate at the few-hundred-G fields these scans use), and the model is two Lorentzians on a flat background:
The resonance mean tracks \(A_\mu\) and the splitting tracks \(A_p\). Set the amplitudes negative to fit resonance dips (the usual Red − Green observable); hold \(\nu_{\mathrm{RF}}\) fixed at the applied frequency and give \(A_\mu, A_p\) starting values near the expected couplings — the resonance condition is nonlinear, so the field-swept curve only constrains the fit once the trial resonances fall inside the scanned window. \(A_\mu\) (the mean) is well determined; \(A_p\) (the splitting) is the weaker axis and benefits from a complementary avoided-level-crossing (ALC) measurement.
import numpy as np
from asymmetry.core.fitting import (
    Parameter,
    ParameterSet,
    ParameterCompositeModel,
    fit_parameter_model,
)

field_G = np.array([580.0, 700.0, 780.0, 820.0, 870.0, 950.0, 1060.0])
asym = np.array([-1.6, -3.0, -16.0, -10.5, -17.0, -3.2, -1.5])  # Red-Green ×10⁻³
errors = np.full_like(asym, 0.3)

model = ParameterCompositeModel(["RFResonanceMuP"])
params = ParameterSet([
    Parameter("A_mu", value=515.0, min=300.0, max=700.0),
    Parameter("A_p", value=124.0, min=40.0, max=250.0),
    Parameter("nu_RF", value=218.5, fixed=True),
    Parameter("ampl1", value=-18.0), Parameter("wid1", value=25.0, min=1.0),
    Parameter("ampl2", value=-18.0), Parameter("wid2", value=25.0, min=1.0),
    Parameter("BG", value=-1.5),
])

result = fit_parameter_model(field_G, asym, errors, model, params)
print({p.name: p.value for p in result.parameters})
References
I. McKenzie, R. Scheuermann, S. P. Cottrell, J. S. Lord, and I. M. Tucker, J. Phys. Chem. B 117, 13614 (2013).
E. Roduner, The Positive Muon as a Probe in Free Radical Chemistry, Lecture Notes in Chemistry Vol. 40 (Springer, Berlin, 1988).
Compared with other programs
Closed-form identities, typed numerical anchors, and synthetic fit round-trips check the parameter-model equations and parameter conventions below. They are analytic checks, not recorded WiMDA execution. The bounded supplied-error constant control against Mantid 6.16.1 and musrfit 1.12.1 checks a separate three-point Gaussian objective; it does not certify the complete model library. See Asymmetry in the μSR software landscape for versions, settings, and limits.
Migrating WiMDA model functions
Every function in WiMDA’s Model-layer library (“Standard fit models”) has a direct counterpart or a composite recipe. Parameter names map as follows:
WiMDA function |
Asymmetry equivalent |
Notes |
|---|---|---|
Polynomial fit up to fifth order |
|
Identical (coefficients c₀–c₅). |
Power law |
|
Identical on \(x > 0\); Asymmetry evaluates \(|x|^n\) so negative-\(x\) points cannot fault the fit. |
Power law (BG quad) |
|
Identical. |
2 Lorentzians + cubic BG |
|
Peak terms map exactly (Ampl → f, Pos → B₀, Wid → B_wid; fix \(c_4, c_5\) at 0 for the cubic). Background coefficients do not transfer: WiMDA’s cubic is in powers of \((x - \mathrm{Pos}\,1)\), Asymmetry’s in absolute \(x\) — refit rather than copying values. |
Thermal activation (2 component) |
|
WiMDA uses eV, Asymmetry meV: \(E_a[\mathrm{meV}] = 1000 \times E_a[\mathrm{eV}]\). WiMDA’s hard-coded \(e/k_B\) is 0.089 % below the CODATA value, so refitted activation energies are expected to come out very slightly higher than WiMDA’s. |
Internal field vs T for ordered magnet |
|
Identical on the physical domain, including the clamp to the background value above \(T_c\) (B₀ → y₀, B_bg → the Constant). |
Divergence of relaxation rate |
|
Identical away from \(T = T_c\) (Tc → Tc, alpha → ν, Min rate → c, scaling → a). Exclude the critical region from the fit window rather than relying on the singular point. |
Repolarisation of isotropic Mu |
|
Same curve; WiMDA fits \(B_0\) in G, Asymmetry fits \(A_{\mathrm{hf}}\) in MHz with \(B_0 = A_{\mathrm{hf}}/(\gamma_e + \gamma_\mu)\) derived (\(A_{\mathrm{hf}}[\mathrm{MHz}] = 2.816 \times B_0[\mathrm{G}]\)). |
RF resonance Mu+p (exact diag.) |
|
Port of |
Composite parameters in the Fit Parameters panel
In the GUI Fit Parameters panel, you can define a derived parameter from existing fitted parameters via the y rail’s + menu → Derived parameter…, which opens the Create Composite Parameter expression builder.
A derived parameter’s chip and card carry a derived tag; right-click the
card’s header for Edit derived… (reopens the builder, retitled Edit
Composite Parameter) and Remove.
The expression builder supports:
Arithmetic:
+,-,*,/,^Parentheses and numeric constants
Built-in constants:
pi,eBuilt-in functions:
sin,cos,tan,asin,acos,atan,sinh,cosh,tanh,exp,log,log10,sqrt,abs
Expressions are parsed safely (no arbitrary code execution) and validated in real time against available fitted parameter names.
Derived parameters are integrated into the same workflow as ordinary fit parameters:
They appear as a chip on the y rail and a row in the fitted-parameter table.
They can be plotted and used with parameter-model fitting.
They are saved/restored with project state.
They are recomputed automatically when source fit parameters change.
Uncertainties are propagated using first-order error propagation:
where \(J\) is the gradient of the expression with respect to source parameters and \(\Sigma\) is the parameter covariance matrix when available (falling back to diagonal variances otherwise).
Knight shift
A muon in a metal or paramagnet precesses not at the bare Larmor frequency of the applied field but at a frequency shifted by the local hyperfine field — the field-induced polarisation of the conduction electrons (Fermi contact) together with the dipolar and RKKY-mediated contact fields of any local moments. That fractional shift is the muon Knight shift, the muon analogue of the NMR Knight shift and a direct, site-resolved probe of the local magnetic response. The panel converts a fitted precession frequency \(\nu\) to
against one of two references.
The Knight shift analysis window is the recommended way to set this up: it is a non-modal window dedicated to the conversion, so the reference, unit, and component choices, the resulting branches, and the scan’s crossings are all visible together while you edit them, and nothing is written back to the trend table until you ask for it. Analysis → Knight shift analysis… is the unconditional entry point, always available regardless of the active series; the Fit Parameters panel’s ⋯ menu carries the same unconditional Knight shift window… action. The + menu’s own Knight shift window… is narrower: it appears only when the active series’ fitted model has at least one Knight-convertible component (a local precession frequency or field, as opposed to an applied-field muonium term) — opening it on an unrelated fit would have nothing to convert. Its sidebar reads top to bottom as the pipeline:
Source — the fitted series supplying the frequencies (run count, component count, and scan axis), with a Refresh from trend button that rebuilds the snapshot from the trend panel’s current rows after a refit or a series change.
Conversion — the reference (Applied field (γ_µ·B) or Designated component, with a combo box for the chosen component when the latter is selected), the display Unit (Auto (ppm / %), ppm, percent, or fraction), a checkbox per convertible component to include or exclude it from the conversion, and the Lorentz/demag correction checkbox with its Shape combo, N field, and χ (SI) field (described below) that turns the measured shift into the intrinsic \(K_\mu\).
Branches — one converted \(K\) trace per included component, each named \(K_n\) and coloured to match its curve on the plot, together with a count of the crossings flagged along the scan (see Component identity and crossings below).
Model fit — the joint \(K(\theta)\) fit that resolves those crossings (see Component identity and crossings, below). The Info… button beside the model selector opens the shared component-information dialog for the selected \(K(\theta)\) model — its formula, parameters, and applicability. Fitted parameters are presented per branch in a table, each value quoted to the precision its uncertainty supports, with a Scale errors by √χ²ᵣ checkbox that inflates the quoted uncertainties when a fit’s reduced \(\chi^2\) exceeds one.
Suggest next angle — an optional section, collapsed by default, that plans the next scan angle from the fit above: see Suggest next angle, below.
The plot area has two view toggles, Fold 180° (overlay symmetry-equivalent orientations onto one period, for an angle scan — a display choice local to the window, independent of the trend panel’s own Fold control described below) and Crossing markers (draw a dashed vertical line at each flagged crossing; on by default). Every control change re-derives the branches and redraws immediately, so a bad reference choice or an accidentally excluded component is visible before anything is published. The footer’s Send K columns to trend table button writes the current configuration back to the trend panel as \(K[\ldots]\) columns so they can be plotted and exported alongside the fitted parameters. Until that button is pressed the trend table is untouched.
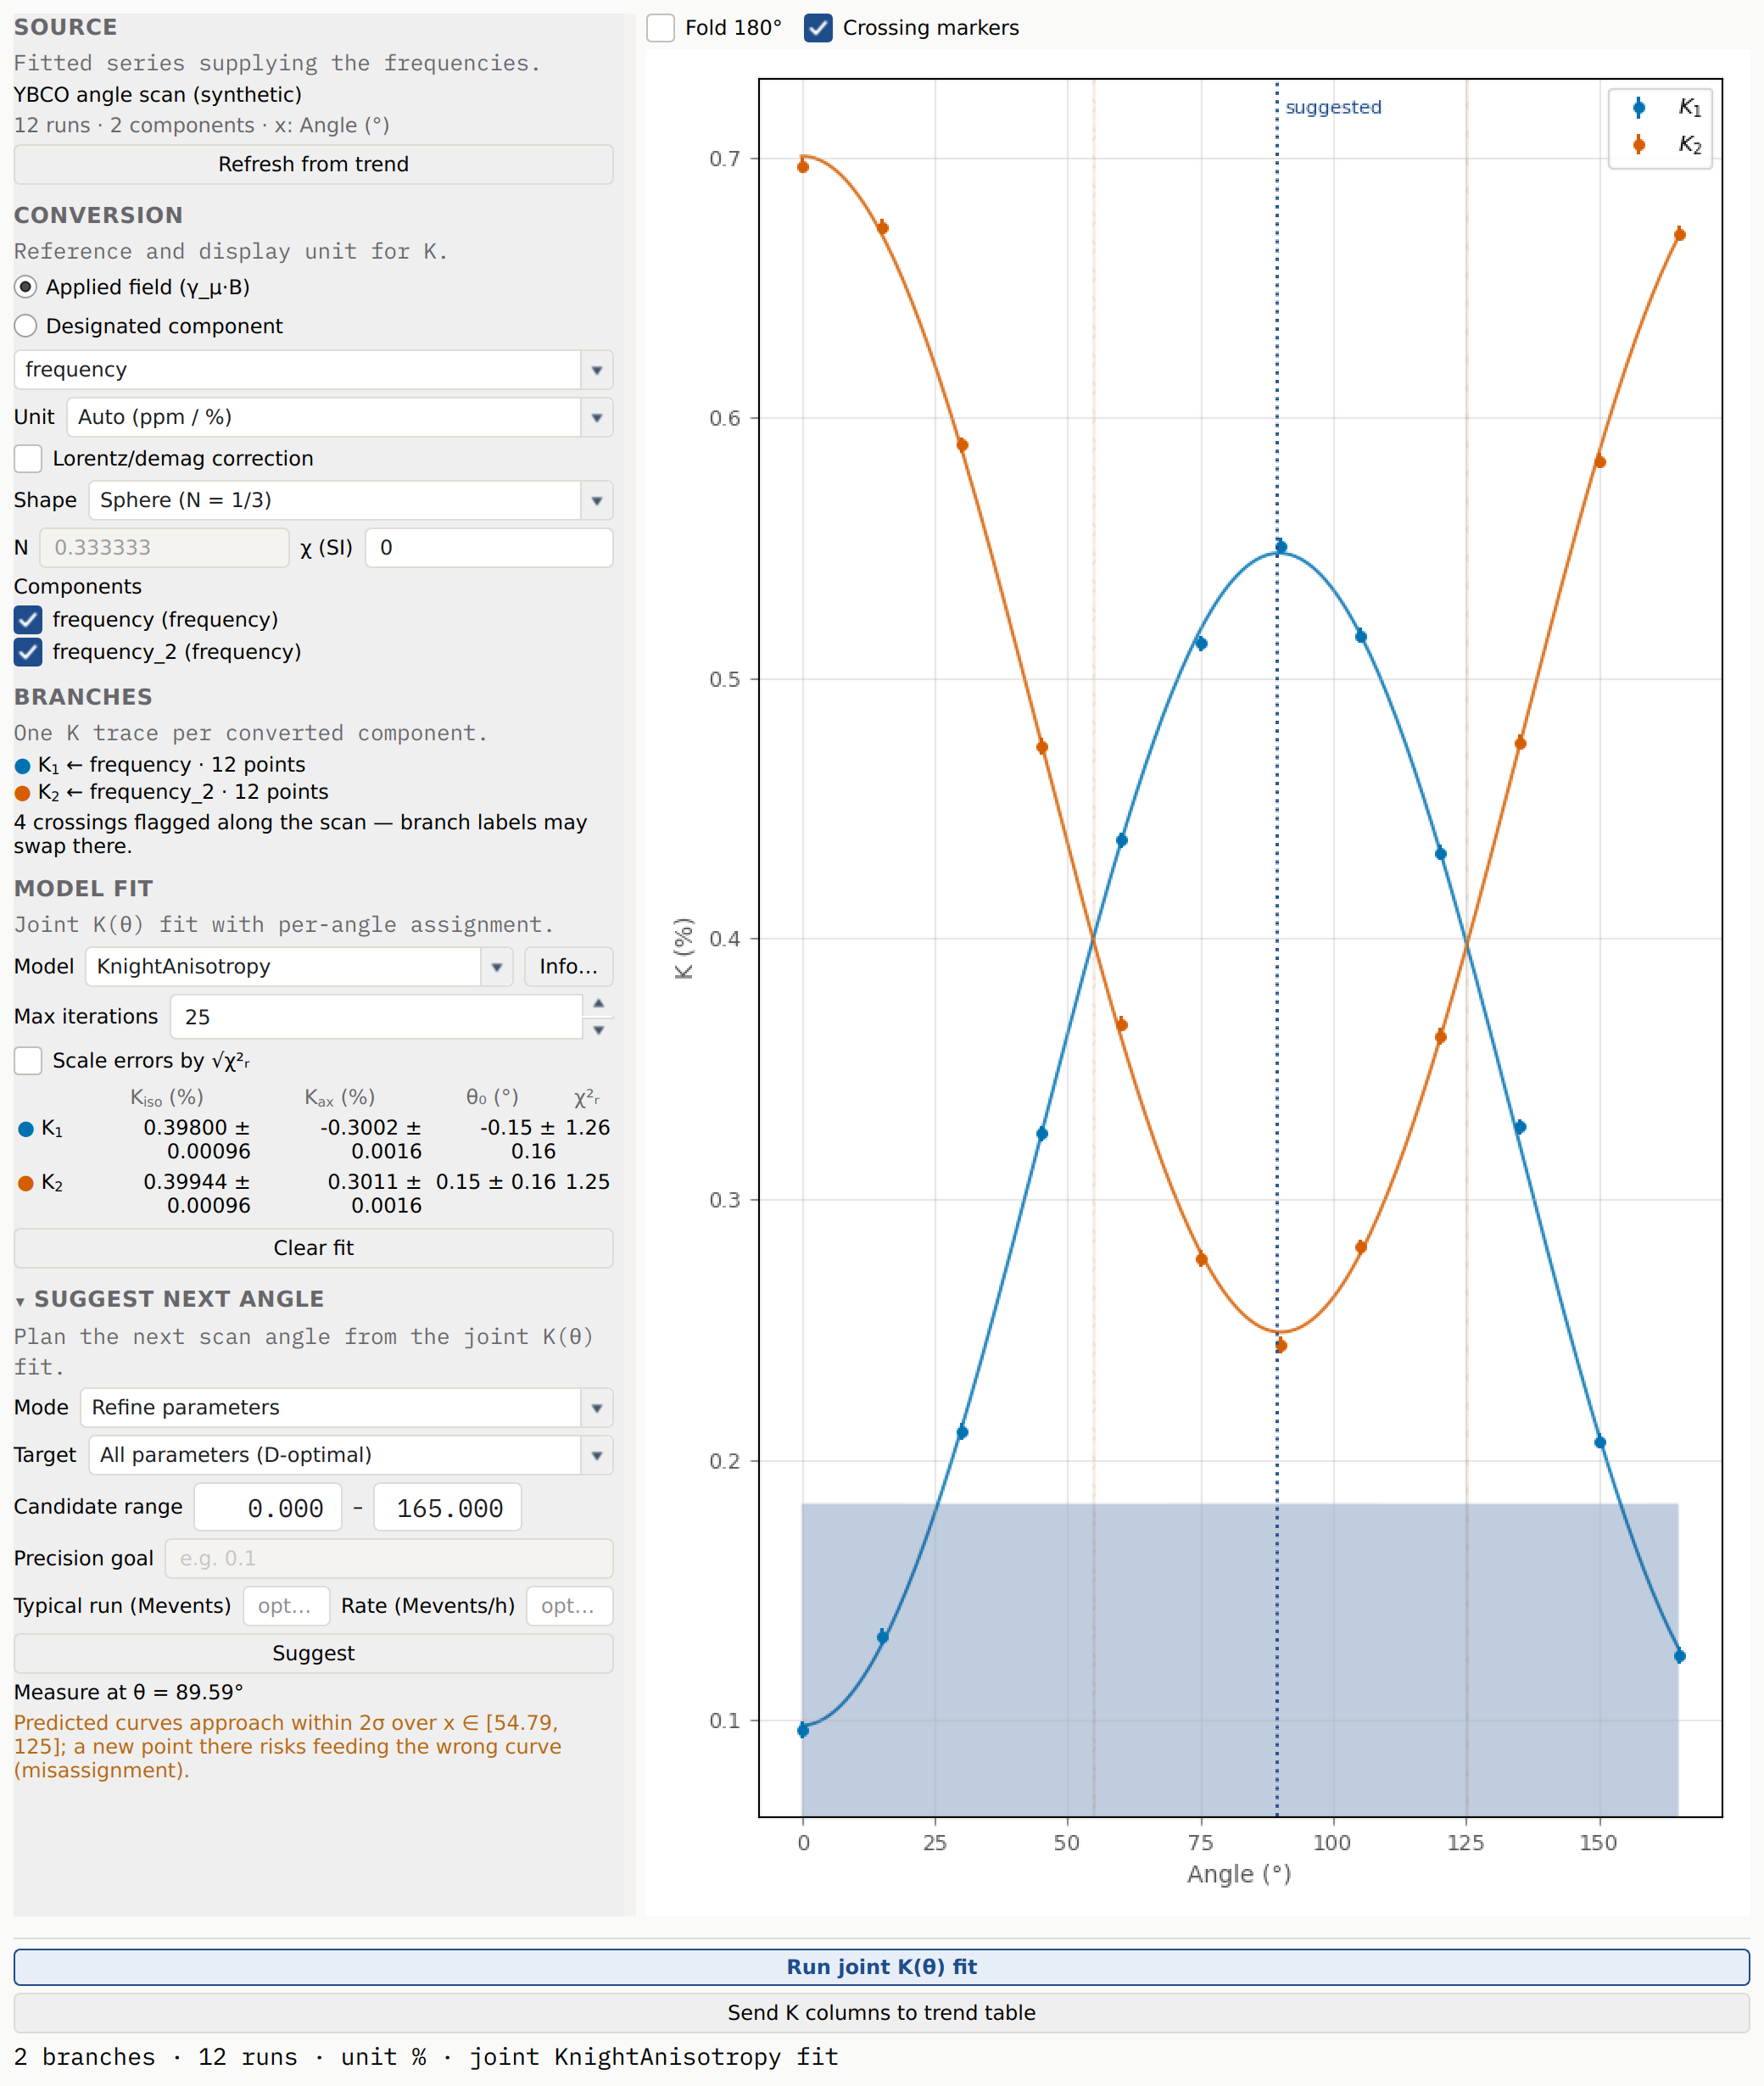
The Knight shift analysis window on a two-site angle scan: Source, Conversion, Branches, Model fit, and Suggest next angle in the sidebar — Model fit showing a completed joint \(K(\theta)\) fit and Suggest next angle a computed Refine parameters / All parameters (D-optimal) suggestion — and the converted branches with their fitted curves, Crossing markers, and the suggestion’s utility band overlaid in the plot area.
The window’s configuration and view-toggle state — including any joint fit —
persist with the project under the knight_shift_analysis_state key (the
point snapshot itself is always rebuilt from the source series on load, so a
saved project can never carry stale fitted values). Projects saved before the
window existed stored the conversion, and any joint fit, under the trend
panel’s own fit_parameters_state block; these migrate automatically the
first time the project is opened, so the window reopens already configured
and, where a legacy joint fit is present, with its run-keyed branch
assignment carried over (the migrated fit’s curves render as stale — “re-run
to refresh” — until the fit is re-run, since the unit they were originally
fitted in is not always recoverable).
Applied field — the precession is referenced to the bare applied field. For a frequency-parameterised component (MHz) the reference is the free-muon Larmor frequency \(\nu_{\mathrm{ref}} = \gamma_\mu B\) (\(\gamma_\mu/2\pi = 135.5\ \mathrm{MHz\,T^{-1}}\)); for a component parameterised directly by the local field \(B_\mu\) (Gauss, as in the
OscillatoryFieldfamily) the reference is the applied field itself, giving the most direct form \(K = (B_\mu - B)/B\). This needs no reference line and is the default; use it whenever a separate unshifted signal is absent (a low-background sample) and the applied field is known.Designated component — \(\nu_{\mathrm{ref}}\) is the fitted frequency of a chosen oscillation component, such as a co-measured diamagnetic line. Because \(\nu\) and \(\nu_{\mathrm{ref}}\) then come from the same fit, their covariance is carried through the error propagation; the applied-field reference treats \(B\) as exact.
K is dimensionless. It is stored internally as a fraction and shown in a unit you select, with an Auto mode that reads parts per million for a diamagnet (typically tens of ppm) and per cent for a paramagnet (up to a few per cent). The conversion itself yields the directly measured shift \(K_{\mathrm{exp}}\); the window’s Lorentz/demag correction (below) recovers the intrinsic \(K_\mu\) from it given the sample geometry and bulk susceptibility.
Lorentz/demagnetising correction. The measured shift \(K_{\mathrm{exp}}\) includes the Lorentz cavity field and the sample’s own demagnetising field, both of which depend on the sample shape rather than the local hyperfine coupling. The Lorentz/demag correction checkbox in the Conversion section removes them,
with \(N\) the demagnetisation factor along the applied field (SI convention, \(\sum N = 1\) over the three principal axes) and \(\chi\) the sample’s volume susceptibility, also SI dimensionless — multiply a CGS value in emu cm-3 by \(4\pi\) before entering it. The Shape combo sets \(N\) from the sample geometry — Sphere (N = 1/3), for which the correction vanishes exactly (the Lorentz and demagnetising fields cancel); Thin plate, B ∥ plane (N = 0); Thin plate, B ⊥ plane (N = 1); Long cylinder, B ∥ axis (N = 0); Long cylinder, B ⊥ axis (N = 1/2); or Custom N, which enables the N field for a value outside these standard shapes — and χ (SI) takes the volume susceptibility. The correction is a constant offset applied equally to every branch, so it shifts K but never reorders branches or moves a crossing. It is exact for an ellipsoidal sample whose orientation relative to the field is fixed; for a rotating non-spheroidal sample \(N\) itself varies with angle, which this scalar form does not capture — a caveat worth remembering for an angle-scan correction with a non-sphere shape. The K uncertainties reported by the window do not include a \(\chi\) uncertainty.
Angle dependence. Rotating a single crystal in the applied field maps out \(K(\theta)\). The contact term is isotropic, while the dipolar term carries the full angular dependence through the dipolar coupling tensor, so \(K(\theta)\) constrains the muon stopping site. Add an Angle (°) column (Columns: metadata and custom), fit each orientation, and select Angle (°) as the trend x-axis to plot each component’s shift against orientation. Because the dependence is periodic (the dipolar term goes as \(\cos^2\theta\), period 180°), the Fold control next to the x-axis selector folds the angle into one period (180° or 360°) so equivalent orientations from a wide or wrap-around scan overlay — doubling the effective angular sampling and exposing the periodic shape for a model fit. Folding is a display/analysis choice; the stored angles are untouched.
Component identity and crossings. Across an orientation (or temperature, or
field) scan, each oscillation component keeps its stable label (frequency,
frequency_2, …) and is converted independently, so the trend follows one
component through the scan. Where two component frequencies approach or cross, that
identification becomes ambiguous — the fit is free to interchange the two — and the
converted trace can jump. The panel detects these points (a frequency crossing, or
a relabelling that better preserves continuity than the raw label order) and marks
them on the trend; it does not silently reassign the components, leaving the
judgement to you. Seeding each fit from its neighbour (chained batch seeding) keeps
the labelling stable through an ordered scan and minimises such crossings in the
first place.
To resolve a crossing rather than just flag it, open the Knight shift
analysis window (with at least two branches and Angle as the scan axis)
and use the Model fit section of its sidebar: choose a Model
(KnightAnisotropy, AngularCos2, or AngularFourier2 — the same
angular basis models described below) and a Max iterations bound, then
press the footer’s
Run joint K(θ) fit button. The fit runs off-thread — the button reports
progress and re-enables when it finishes — and fits one K(θ) curve per
branch simultaneously, assigning each angle’s component points one-to-one to
the curve they best fit (a Hungarian matching) and iterating fit ↔
reassignment to convergence. The plotted branches are realigned so each
follows one physical curve continuously through the crossings, the fitted
model curves overlay in the branch colours, and dashed vertical markers flag
the angles where the assignment swaps (the crossings the fit actually
resolved, a firmer signal than the raw proximity flags). The sidebar reports
each curve’s fitted parameters and reduced \(\chi^2\) beneath the
controls; Clear fit discards the fit and returns the branches to their
raw component labels. Changing the display unit or the Lorentz/demag
correction only marks the fitted curves stale (their parameters shift with
either — the assignment does not, since a common offset or scale cannot
reorder branches) — re-run the fit to refresh them. The Scale errors by
√χ²ᵣ checkbox inflates every quoted parameter uncertainty by
\(\sqrt{\chi^2_r}\) when that curve’s reduced \(\chi^2\) exceeds one
(a fit that is already better than the noise is left alone); it is
display-only — the stored fit itself is unchanged, and toggling it appends or
removes an “(errors ×√χ²ᵣ)” note next to the affected curve. The fit
(assignment and per-curve parameters) is saved with the project and restored
on reload, and stays applicable across a Refresh from trend as long as
the branch count is unchanged; a different component selection invalidates
it.
In the trend panel, right-click a K[...] card’s header and choose
Remove to delete it: the backing component is dropped from the conversion
(via set_knight_shift_config, so the trace does not regenerate). Removing
every component turns the conversion off.
Fitting the anisotropy \(K(\theta)\). With Angle (°) as the trend x-axis, the model-fit builder offers three angle-only basis models alongside the usual ones:
for the axial dipolar form — the isotropic contact term \(K_{\mathrm{iso}}\) plus the traceless dipolar anisotropy \(K_{\mathrm{ax}}\) — the general two-fold modulation
for a crystal rotated in a plane — algebraically the same curve family as
KnightAnisotropy (\(K_{\mathrm{iso}} + K_{\mathrm{ax}}/4 =
K_{\mathrm{avg}}\), \(3K_{\mathrm{ax}}/4 = K_{\mathrm{amp}}\), sharing
\(\theta_0\)) — and a misalignment-sensitive extension
which adds a first-harmonic term to AngularCos2. A perfectly aligned
rotation axis gives a pure second harmonic; a tilted axis leaks a first
harmonic whose amplitude grows with the tilt, so a fitted \(K_1\)
significantly different from zero is fit-level evidence that the rotation
axis is not exactly where the goniometer says it is. This is a
phenomenological Fourier form — it does not itself solve for the physical
tilt angle from \(K_1\) and \(\theta_1\) — and, with five free
parameters, needs at least five shared angles per curve to fit. See Suggest
next angle, below, for using it to test for misalignment directly rather
than assuming an aligned axis.
KnightAnisotropy and AngularCos2 both carry a \(\theta_0\) term —
the goniometer/mount misalignment between the zero of the angle scale and the
crystal’s principal axis, since a real mount is never perfectly aligned;
without it, that misalignment would otherwise bias \(K_{\mathrm{iso}}\)
and \(K_{\mathrm{ax}}\) (or \(K_{\mathrm{avg}}\) and
\(K_{\mathrm{amp}}\)) directly. Both forms are invariant under a
\(90^\circ\) shift of \(\theta_0\) together with a sign flip of the
anisotropic amplitude, so the joint fit canonicalises the fitted
\(\theta_0\) into \((-45^\circ, 45^\circ]\) — folding to the
small-\(|\theta_0|\) representation so a mount that is nearly aligned
reads with a small offset and a physically sensible amplitude sign, rather
than an equally valid but larger-offset relabelling of the same curve.
AngularFourier2’s second-harmonic phase \(\theta_2\) folds the same
way; its first-harmonic phase \(\theta_1\) folds independently, over the
full \(360^\circ\) period a first harmonic repeats on, into
\((-90^\circ, 90^\circ]\) with a sign flip of \(K_1\). Every fold is
an exact linear reparameterisation, so the fitted covariance is carried
through it exactly (\(\Sigma' = J\Sigma J^{\mathsf{T}}\)) rather than
approximated — the quoted uncertainties, and anything downstream that
consumes the covariance (such as Suggest next angle, below), see the same
figure a refit started directly in the canonical branch would have produced.
All three models take \(\theta\) in degrees, so they fit directly against
the Angle axis (folded or not). The diagonal dipolar-tensor components
recovered for rotations about the crystal axes constrain the muon stopping
site. For a worked example end to end, see Angle-dependent Knight shift.
Clogston–Jaccarino (\(K\) vs \(\chi\)). Plotting the Knight shift against the bulk susceptibility with temperature as the implicit parameter gives a straight line whose slope \(\mathrm{d}K/\mathrm{d}\chi\) measures the muon hyperfine coupling and whose intercept is the \(\chi\)-independent shift. The muon experiment does not itself measure \(\chi\), so this is API-only — pair the exported Knight shift with an independent susceptibility:
from asymmetry.core.fitting.knight_shift import clogston_jaccarino_fit

result = clogston_jaccarino_fit(chi, knight, sigma_knight)  # χ, K, σ_K per T
print(result.slope, result.slope_err)   # dK/dχ ∝ hyperfine coupling
print(result.intercept)                 # χ-independent (orbital) shift
When to use this. Convert to the Knight shift whenever the quantity of interest is the shift of a precession frequency from the applied-field value — tracking a local susceptibility, determining a muon site from \(K(\theta)\), or building a Clogston–Jaccarino \(K\)–\(\chi\) plot. Keep the raw frequency trend when the absolute precession frequency itself is the observable (an internal field, a magnetic order parameter).
Suggest next angle
Once the joint \(K(\theta)\) fit above has converged, the collapsible Suggest next angle section beneath Model fit answers the question Suggest next point already answers for a scalar trend — where should the next measurement go? — with three angle-specific flavours, chosen from a Mode selector: Refine parameters, Test misalignment, and Resolve assignment. All three share one Candidate range (seeded from the measured angle span; widen it to allow an extrapolated suggestion) and one Suggest button, and reuse the Laplace/Fisher acquisition machinery described on that page rather than a separate derivation — what is genuinely new here is specific to a rotation scan: one new run yields a value for every curve at once, and which measured value belongs to which physical curve is itself something the joint fit had to work out.
The section stays inactive, with a muted hint explaining why, until every prerequisite is met: no joint fit (“Run the joint K(θ) fit first.”), one that no longer matches the branches or predates the current unit/correction (“Re-run the joint K(θ) fit — it no longer matches the branches.” / “…the display unit or correction changed.”), or — for a fit saved before this feature shipped — a missing stored covariance (“Re-run the joint K(θ) fit to store fit covariance.”): the run-keyed assignment of a legacy fit survives a project reload, but its per-curve covariance was never recorded, so a next-angle suggestion needs one re-run before it becomes available.
Refine parameters sums the expected information gain over every curve — one new run adds a datum to each of them, so their information gains add. Target chooses what to refine: All parameters (D-optimal) shrinks every curve’s whole parameter covariance at once, or pick one curve’s parameter from the list for a c-optimal solve, which enables Precision goal and the Typical run (Mevents) / Rate (Mevents/h) conversion — exactly as in Suggest next point, down to the result line’s phrasing:
Measure at θ = 48.2° × 0.6 of a typical run's statistics
→ σ ≈ 0.018 (approximate)
Test misalignment asks a different question: is the scan actually
consistent with a perfectly aligned rotation axis, or is there evidence of a
tilt? On Suggest it fits the AngularFourier2 alternative (above)
automatically, off-thread — cached against the joint fit’s model, unit, and
Lorentz/demag correction, so repeat clicks do not refit — and ranks candidate
angles by the disagreement between the current model and that alternative,
summed over every branch (the same model-discrimination utility
Suggest next point’s Compare against uses for a scalar trend). The
result line names the currently preferred model and its Akaike weight, e.g.
Measure at θ = 71.5°; prefers AngularFourier2 (Akaike weight 0.86, evidence ratio 6.1)
and when the two models already agree within noise everywhere in the candidate range, the section reports that instead of pointing at an arbitrary angle.
Resolve assignment targets the labelling itself rather than either model’s parameters. Near a crossing, the joint fit’s classification-EM step can settle on more than one near-equally-good assignment of which measured component belongs to which physical curve; this mode ranks candidate angles by how well a new, unlabelled run there would separate the winning assignment from its near-degenerate runners-up — a minimum-cost matching between the two labellings’ predicted value sets, zero exactly at a crossing (where the competing labellings coincide by construction) and largest where they imply genuinely different curves. The runners-up are kept only in memory from the last fit run, so if the stored fit came from a project load, Suggest re-runs the joint fit off-thread first to recover them; with none to compare against, the section reports “No near-degenerate assignments to discriminate.”
Overlay and risk shading. A computed suggestion draws the same utility band used by Suggest next point, anchored beneath the \(K(\theta)\) plot with the best angle marked and any extrapolated candidates shown at reduced opacity. Refine and Test-misalignment suggestions can additionally shade a candidate span with a muted hatched band where two curves’ predicted values sit close enough (within about \(2\sigma\) of each other) that a new, unlabelled run there risks being fitted onto the wrong curve — exactly the crossing risk the joint fit’s own Hungarian assignment exists to resolve. A suggested angle that falls inside a shaded span should be read with that caveat in mind rather than acted on blindly.
When to use this. Reach for Refine parameters while extending an otherwise routine scan; reach for Test misalignment once a fit already looks good but you want to actively rule out a tilted mount rather than assume alignment; reach for Resolve assignment specifically when a crossing has left two labellings within reach of each other and the next run should settle which is real.
References
A. Amato and E. Morenzoni, Introduction to Muon Spin Spectroscopy: Applications to Solid State and Material Sciences, Lecture Notes in Physics Vol. 961 (Springer, Cham, 2024).
S. J. Blundell, R. De Renzi, T. Lancaster, and F. L. Pratt, Muon Spectroscopy: An Introduction (Oxford University Press, Oxford, 2022).
Knight, Phys. Rev. 76, 1259 (1949).
Clogston, V. Jaccarino, and Y. Yafet, Phys. Rev. 134, A650 (1964).
Runnable example
See examples/parameter_trending.py for a complete executable script.
Downstream trend models
The trend framework feeds several physical models that consume a fitted parameter series: for TF-μSR superconducting penetration-depth analysis via a temperature-dependent \(\sigma(T)\), see Superconducting penetration depth models; for muonium reaction kinetics from relaxation rates linear in reactant concentration, see Muonium reaction kinetics at a pulsed source (scripting); and for the field-dependent transport models fitted to \(\lambda(B_\mathrm{LF})\), see Field-dependent transport models (DiffusionLF / BallisticLF).
Information criteria for role suggestions
Suggest roles… compares the Global/Local partitions on the same data and under the same weighting convention. Column, Absolute and Percent errors use \(\chi^2\) as \(-2\ln L\) up to a data-only constant. None and Scatter profile a common unknown variance, using \(n\ln(\mathrm{RSS}/n)\) and one additional fitted parameter for that variance. Scaling all ordinates by a common factor therefore preserves the criterion differences between models. A zero residual variance gives an unbounded unknown-variance likelihood and cannot be ranked by a finite criterion.
Effective-variance fits with x errors omit a parameter-dependent likelihood normalization term, so information criteria are unavailable for those fits. AICc is unavailable when \(n-k-1\leq0\); the role search excludes that partition under AICc and never substitutes AIC. See Fit wizard for the formulas, assumptions and primary references. If no converged candidate has a defined AICc, the message is “No candidate can be ranked by AICC; roles left unchanged.”
The rationale panel lists excluded partitions under “Not ranked (AICc):” (or the selected metric) with each reason. The two-study comparison uses the same likelihood calculation. Undefined criteria show “—” with a reason in the tooltip, and their differences also show “—”. Differences require the same fitted data snapshot, point count and error mode.