Project files
Ordinary fit models persist their optional fixed time response with the model payload. An absent setting restores Off; stored parameters, errors, and curves retain their recorded meaning. A restored re-fit consumes the authored response. See Fixed double-pulse prediction.
Good-window profiles retain their authored signed offsets and omitted endpoints. Recorded scalar bounds retain their effective-coordinate meaning; reopening does not relabel them as original detector file facts. The signed display offset is derived from the recorded first bound and effective t0. Cached-only period views remain selectable, with re-reduction limited by the acquired facts available.
The .asymp project file persists the analysis state of a session:
which datasets are loaded, how the Data Browser is sorted and filtered,
the per-run grouping (groups, alpha, bunching, deadtime, background),
the single- and global-fit model setups with their parameter tables and
bounds, separate frequency-domain fit state with spectral peak models,
the most recent fit overlays, the Fourier panel state including
per-run phase tables, any cached Fit Wizard or Global Fit Wizard
analyses, per-run representation saved single fits (the Single tab’s
fits alone — a batch, global, grouped or scan run never writes one), and the
batches (fit series, each carrying the recipe that produced it) that
drive the Fit Parameters trending panel and the plot’s overlays. Raw
detector arrays are not embedded — the file references source data by
path and reloads from disk on open. Fourier spectra are regenerated from
their stored recipe (window, padding, phase, group selection) rather
than embedded, so the file remains compact even after frequency-domain
work. This makes .asymp files small enough to share alongside the
raw data when sending an analysis to a collaborator, or to archive
alongside paper supplementary material so that readers can reproduce
every fit shown in the figures.
Opening safely
Asymmetry also checks owned project structure before replacing an active session: container types, unique run/profile/fit identities, saved-fit selection, applied calibration references, active-series links, and finite held plot bounds. These checks protect unsaved work from malformed project content; they do not validate raw acquisition files or establish source-content identity.
The Opening Project dialog displays Checking project… and offers
Cancel. Rejection shows Could Not Open Project, followed by
Failed to read project file: and the owning field, for example
project.datasets[0].source_file: expected str. The existing runs, profiles,
fit history, project path, and unsaved changes remain intact. Cancellation before
restoration displays Project opening cancelled — existing work retained.
A future schema shows Unsupported Project File.
Missing external files or user functions remain supported unavailable states. Saved historical constraints and uncertainty archives remain inspectable; stale series and joint-fit membership do not become malformed merely because a live member is absent. Optional blocks and custom metadata can remain absent.
After preparation succeeds, restoration reloads source acquisitions and applies items in order. Cancelling Restoring project retains completed items and marks the session as partially loaded. Its log states The project is PARTIALLY loaded — saving it now would drop the missing runs. Saving requires the existing incomplete-project confirmation. This deliberately partial restore does not roll back to the outgoing session.
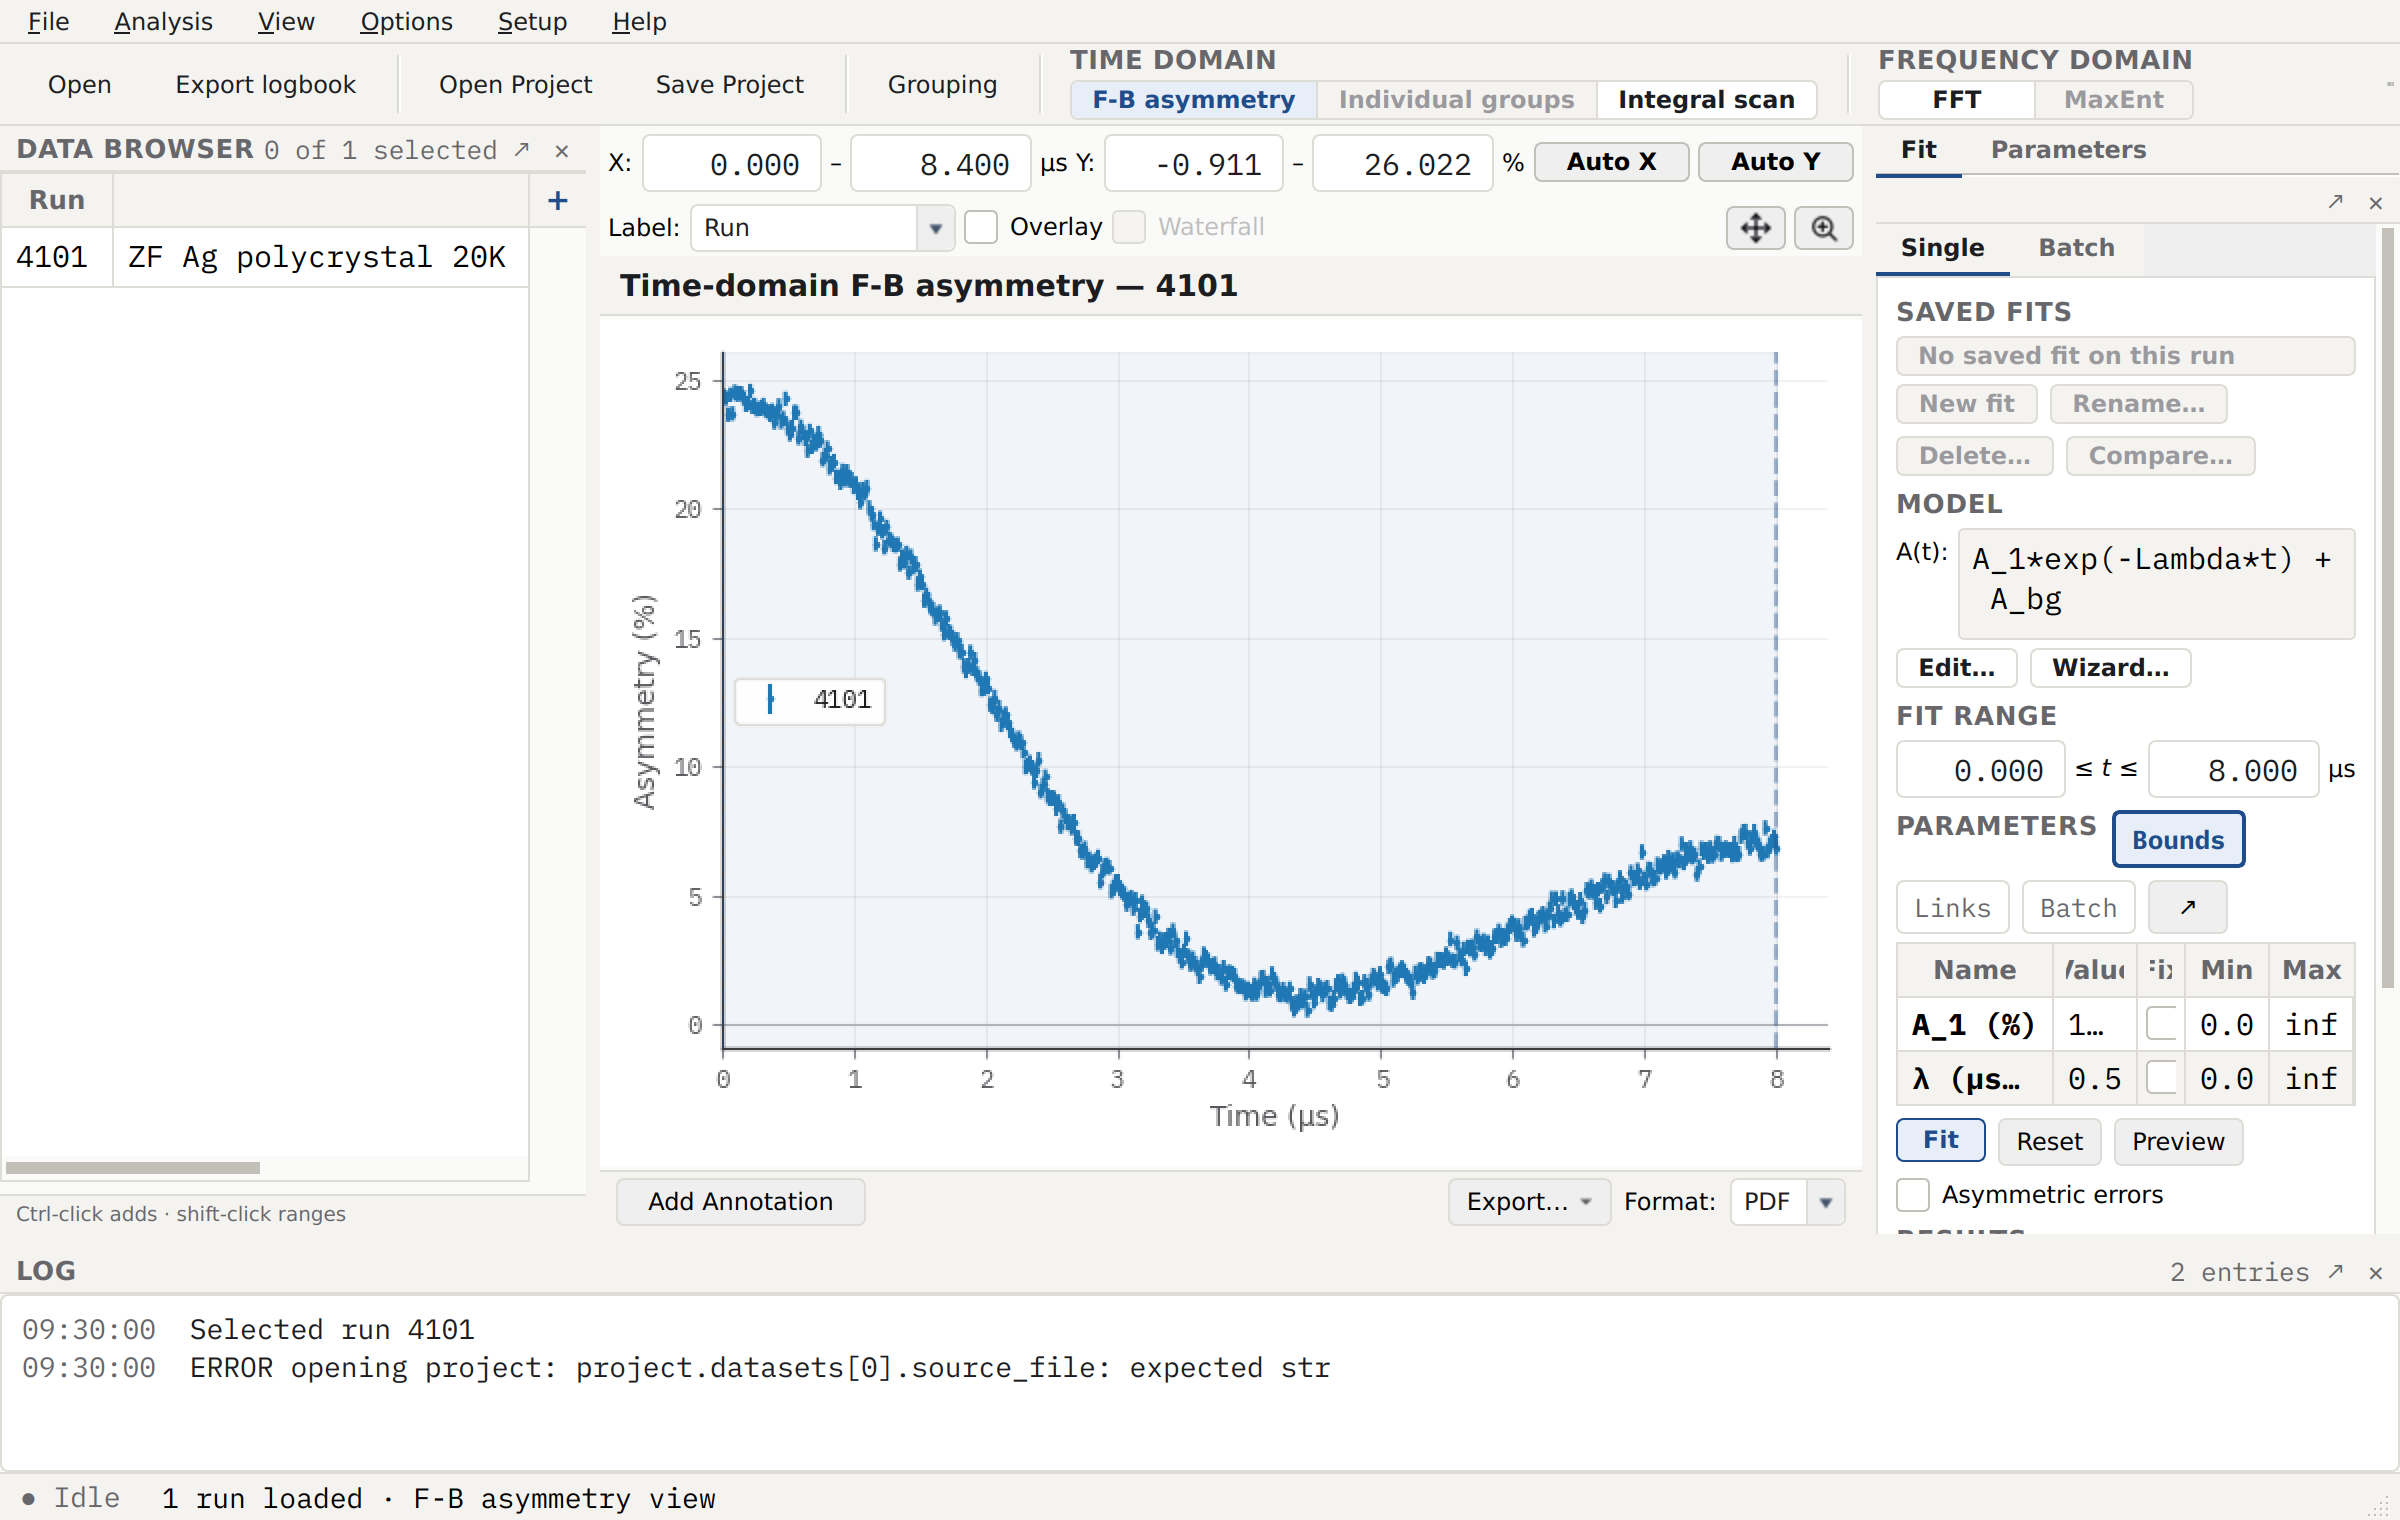
Saving is crash-safe: the new content is written to a temporary file
next to the target and only swapped into place once it is fully flushed
to disk, so a crash or a full disk mid-write leaves the previous save
untouched. The file it replaces is kept alongside it as <name>.asymp.bak
(one generation — a second save overwrites it). While a project has
unsaved changes, a background timer also writes a crash-recovery
snapshot to <name>.autosave.asymp (or, for a session that has never
been saved, a file under the platform’s application-data directory);
see Crash-safe save and autosave below.
A missing current input opens Data Files Not Found, offering Locate Data Directory. The selected directory supplies basename candidates, including Windows paths reopened on another operating system. Asymmetry verifies their contents before using them; a matching name alone does not establish identity. Saving records accepted current locations while historical recipe paths stay with their original results.
Source decisions before restoration
The Opening Project worker displays Verifying project sources… and remains cancellable. Byte-identical sources, including relocated files, continue normally. Legacy inputs without an expected digest open unverified without a mandatory replacement question. Missing or unreadable inputs retain their unavailable state.
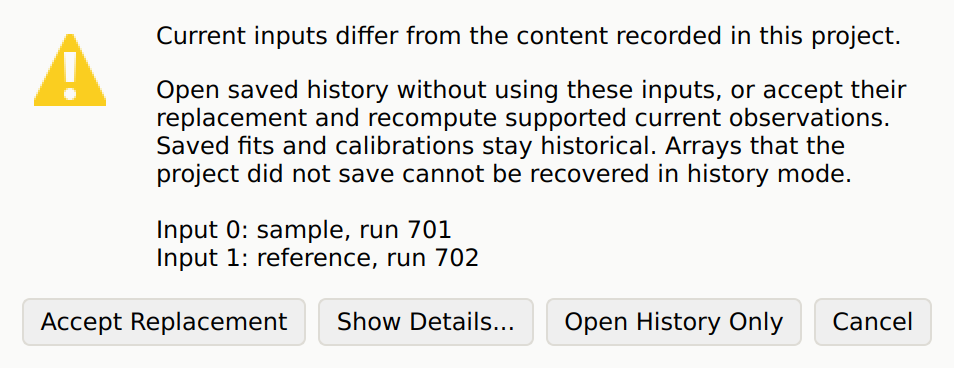
Known changed current inputs open Source Content Changed. Its listed owners identify the current sample, ordered nonzero combination terms, and requested reference inputs affected by the decision:
Open History Only retains saved records without consuming those changed inputs. A project does not store raw detector arrays or ordinary reduced arrays; a saved fit summary cannot reconstruct missing historical observations.
Accept Replacement updates the listed current input expectations to the observed bytes and recomputes supported current observations using the recorded requests. It does not refit models, rerun calibration, or disable a requested correction. Saved fits, series, constraints, calibration records, and effective recipes retain their original source context, even when sampled arrays coincide.
Cancel retains the outgoing session, unsaved work, project path, and tabs before restoration starts.
Differences confined to historical results, frozen calibrations, inactive reference settings, or zero-weight terms are informational in the log. They do not prompt for replacement of valid active data. After replacement, save and reopen verifies the new current expectation while preserving those historical differences.
Asymmetry also compares the actual acquisition capture with the accepted bytes. A second change, or unavailable capture for an accepted known input, prevents it from supplying current observations. An ordinary legacy input decoded without a capture remains usable and unverified; verification facts are never backfilled as its acquisition identity. Unknown capture also includes a built-in read whose stability could not be established; this does not certify a replay. A failure after deliberate application retains the completed items and the partial-project save guard; restoration is not a whole-session rollback. These are source-provenance safeguards, not a judgement of physical validity.
Saved fit parameters are interpreted at the project boundary, including released
fraction and product-amplitude names. Canonical snapshot values retain the saved
curve. If an old constraint cannot be expressed in the current parameterisation,
the original parameters, constraints, and captured results remain inspectable.
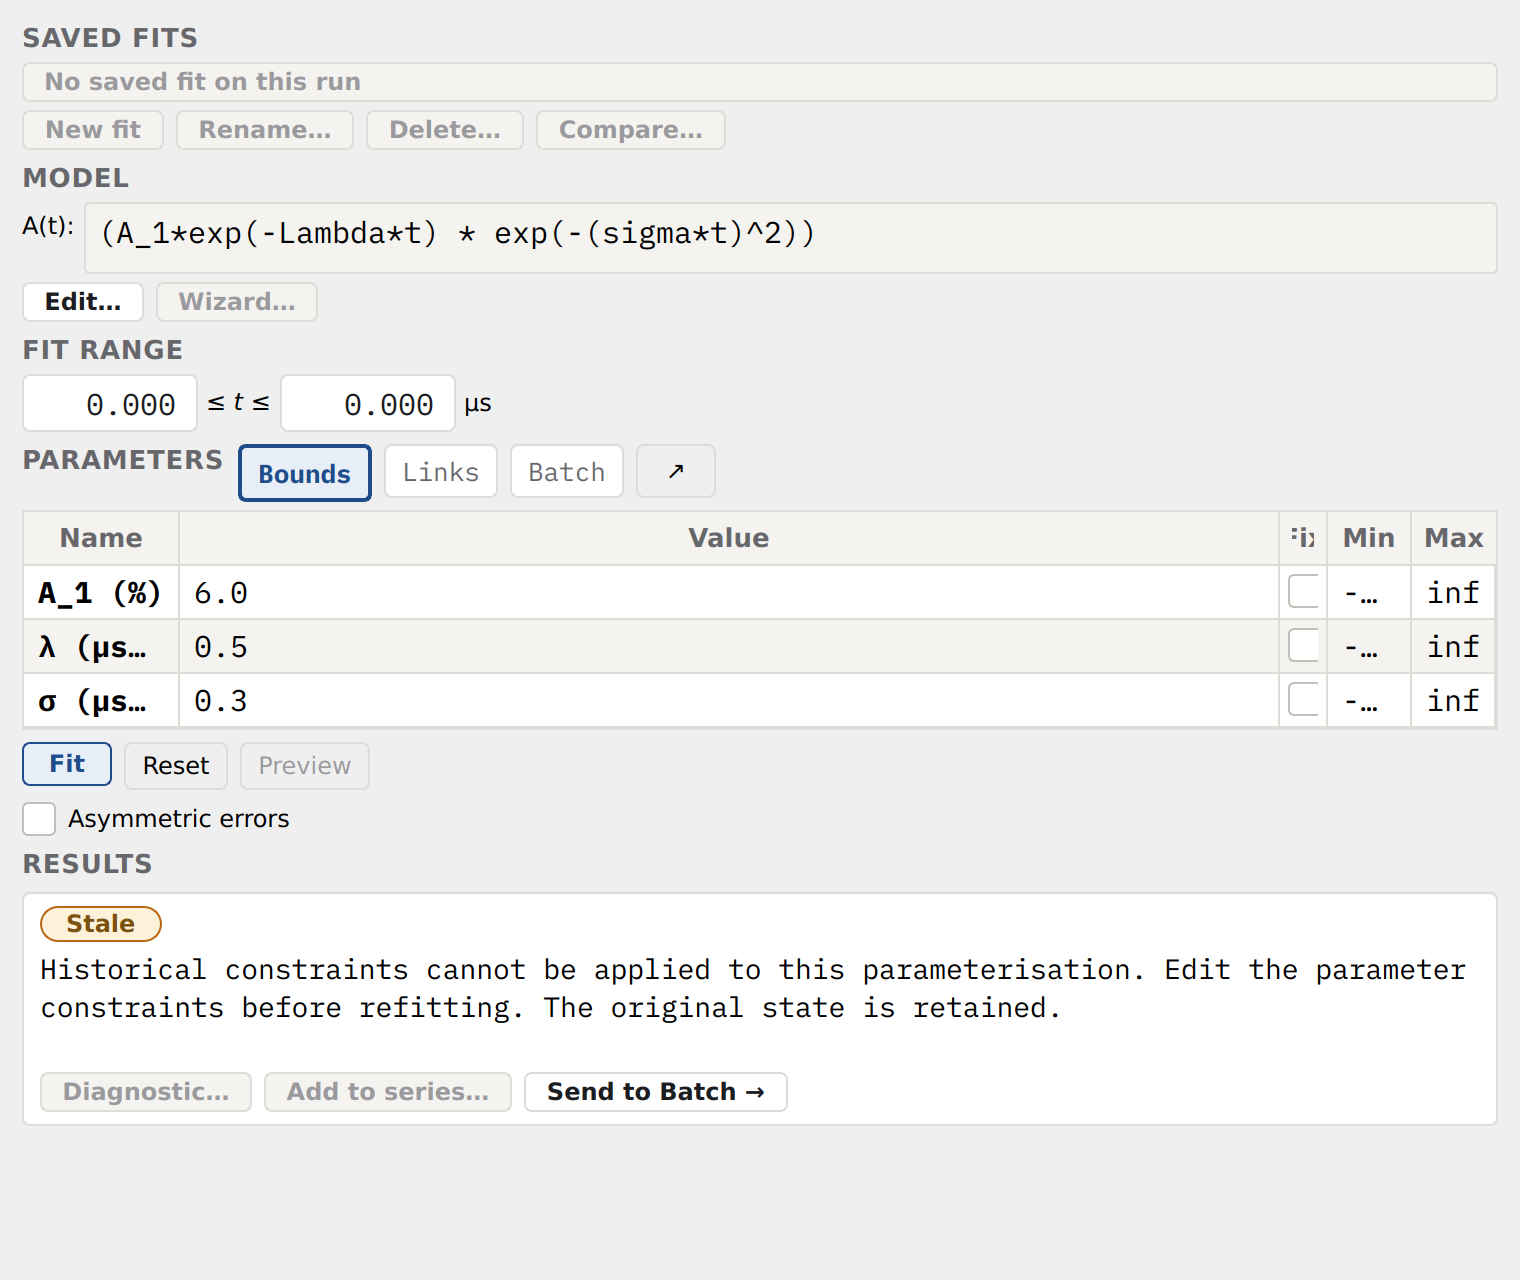
The fit form reports Stale with “Historical constraints cannot be applied to
this parameterisation.” Edit the parameter constraints (bounds, fixed status,
links, or ties) before refitting, including using a historical series as a joint-fit
member; changing only a seed value does not authorise a
new constrained fit. Saving and reopening retains that distinction and the
original content in the saved analysis_history record. Historical
recommendations cannot be applied automatically. Parameter conversion retains
reported statistics; it does not reconstruct missing covariance or certify
uncertainty equivalence under a changed parameterisation.
Asymmetry also checks stored model descriptions and numeric fraction/product scales at the project boundary. Invalid owned values cause a contextual load error; an unavailable user function remains a supported dependency state.
An unavailable user function retains its saved model and parameters. Register the function and reload the project to resolve its deferred parameter conversion. Loading, saving, or resolving a dependency never assigns a current computation revision to a historical result. Successful explicit computation publishes its own current result while retaining the superseded parameter archive.
Asymmetry’s project file is JSON with an integer schema version, which
is independent of the package version: opening a project written by an
older release triggers automatic schema migration, and the loader
refuses to silently accept a file written by a future schema it does
not understand. The format is therefore directly diffable in version
control, which is the main practical difference from musrfit’s
hand-editable .msr text format
whereas Mantid Workbench uses a .mantidproj project description referencing
saved NeXus workspaces (Mantid Project documentation).
Reference-background requests persist their declared source acquisition and acquired period through grouping overrides and profiles. Released declarations are restored using the source run number and available acquired periods; an encoded browser key is interpreted only when those facts establish its meaning. An unresolved request remains explicit and prevents a corrected result from being accepted. The raw acquisition remains available for inspection and repair. Reopening never substitutes another file merely because its run number matches.
Reference scale intent persists as Automatic or Manual, with the Manual coefficient, in both profiles and run overrides. Reopening resolves exposure from the selected acquisitions without turning whole-run deadtime normalisation into measured pulse exposure. Historical frame snapshots remain unverified provenance under Automatic. A valid bare numeric coefficient without frame-snapshot fields becomes Manual. Boolean coefficients remain unverified history under Automatic. A declaration containing both frames and a coefficient becomes Automatic and retains the coefficient as historical provenance. Cached applied coefficients do not become authored requests. Unknown-exposure unity and the applied coefficient remain visible in result provenance. Invalid inactive declarations remain editable and saveable.
Combination definitions retain ordered sources and the operation. An optional
metadata_overrides on a combined definition holds deliberate target condition
edits; source rebuilds retain them. Missing condition values remain JSON null.
When loaded source rows cannot be combined, reconstruction retains a
Combination unavailable row with its Corrections incomplete diagnosis,
definition, and history, while keeping the source rows available. Saved arrays, fit records, and recorded condition
coordinates retain their meaning without automatic refitting.
What is stored
Saved fit summaries record their likelihood as objective. Gaussian and
Poisson statistics keep their corresponding labels after loading. A grouped
result whose objective was not recorded has objective: null, no χ² quality
verdict, and the explanation “Fit objective was not recorded.” A known
Gaussian fit retains objective: gaussian. Poisson summaries carry the
minimum fitted expected count used by the quality-display policy; see
Assessing a Fit.
Project files store:
Loaded dataset references (source file paths)
Browser state (sorting, filters, selected runs, dynamic columns)
Plot state (ranges, selected run, bunch factor, overlay mode, waterfall stacking — see waterfall stacking — and the Lab | Rotating switch with the ν_RF unit, under
rotating_frame)Each run’s rotating frame, on its dataset entry (see Rotating frames (schema v26))
Fit-panel and Fourier-panel state
Separate frequency-fit state for displayed Fourier spectra
Per-run Fourier group-phase tables, included groups, and auto-estimated phase markers
Cached single-fit and global-fit wizard analysis payloads when present. Assessments retain fit statistics and
sample_count; information criteria are derived from those values.sample_count: nullmeans the count is unknown, so AICc and BIC are unavailable for that cached row. Reanalyse the run to record the fitted count.Per-dataset representations — for each analysis domain (F-B asymmetry, detector groups, FFT, MaxEnt) that the user has exercised, the stored representation records a recipe (for FFT: the generation config) and its
single_fits— the Single tab’s saved fits for that representation only, per projection, each a FitSlot: model, parameters, result summary, provenance ("none"/"single"/"wizard"), its window, name and id, and, when the single-fit GUI produced it, aui_stateblob that restores the form verbatim (see Saved single fits (schema v25)). Fourier spectra are re-generated from the recipe on load; time-domain asymmetry is re-computed from the raw data.Combined runs — each
combined_datasetsrow names its source runs and carries the combined run’srepresentationsandrotating_framelike a dataset entry. A combined run is rebuilt on load under its savedcombined_run_number, so every record keyed by it still names it. A combination rejected during reconstruction from loaded source rows retains aCombination unavailablerow, its definition, authored target conditions, and historical records, including fits, frame, series membership and results, exclusions, and data-group membership. Source rows remain available. Preserved history does not supply newly reconstructed numerical observations for the unavailable row. Later source rebuilds also check the saved terms before replacing the row: unsupported coefficients or selected periods retain the definition and history withSaved combination terms cannot be reconstructed by this operation.Fit series (batches) — each batch, global, grouped or scan fit over multiple runs (or multiple runs’ detector groups) is recorded as a
FitSeriesthat carries the member list, parameter roles, per-member result summaries, and the recipe that produced it (model, parameter rows, fit range, seeding, co-add) plus its owntrend_excluded_runs. The Fit Parameters trending panel reads directly from these series, organised by the active representation.Active series — the top-level
active_seriesmap names, per representation, the series the Batch tab, the Parameters chip rail and the plot’s default overlay all currently point at; see Fit series recipe and active series below.Data groups — the top-level
data_groupsregistry is the canonical store of named run collections (the Data Browser’s groups). A run-memberedFitSeriesthat was launched from a group (or auto-created for an ad-hoc batch selection) carries a structuralgroup_idback to its owning group; see Data groups and fit series below for the full field set this adds to bothdata_groupsentries andbatchesentries.
Data groups and fit series
A group owns zero or more series: the same run collection can be fit with
several models side by side, and a series’ effective membership is derived
live as the owning group’s members minus that series’ own exclusions, so
adding or removing a run from the group is reflected the next time the series
is re-run rather than requiring a fresh batch fit. Each top-level
data_groups entry stores:
kind"user"for a group the user named explicitly, or"auto"for one minted automatically the first time an ad-hoc run selection is batch- or global-fitted (so every batch fit has an explicit owning group). Renaming an"auto"group promotes it to"user".
A group is a phase when its parent_group_id names another
data_groups entry — the series group a transition partitions it out of
(see Phases within a group in GUI usage). Schema v19 adds six
additive phase fields to every data_groups entry, meaningless (and left at
their defaults) on an ordinary group:
parent_group_idThe id of the series group this phase belongs to, or
nullfor an ordinary group. A group is a phase exactly when this is set.phase_ordinal1-based position of this phase along the sweep axis (
1for the coldest/lowest-field phase), ornull. Drives both the phase’s display name (GUI usage’sPhase I,Phase II, …) and its identity colour, which cycle past five.phase_range[first, last]axis value spanned by this phase’s members, ornull.phase_boundaries{"lower": [estimate, half_gap] | null, "upper": [estimate, half_gap] | null}. Both keys are always present; anullside means this phase sits at a series end, where there is no break to estimate.phase_colorThe swatch colour (a hex string) assigned when the wizard created this phase, or
nullto fall back to the ordinal’s slot in the identity palette.phase_provenanceA plain, JSON-able record of how this phase was found and last fitted:
found_at(ISO timestamp),selected_breaks,gains,axis_key,model_title,confidence,shared_parameters,fit_state, andreduced_chi_squared— every key is genuinely optional, since a phase exists as soon as the partition is applied, which is before its own global fit has run. Defaults to{}.
Each run-membered (member_kind == "runs") entry in batches gains:
group_idThe id of the
data_groupsentry that owns this series, ornullfor a frozen series — a legacy analysis, or one whose owning group has since been deleted with its fits kept (rather than deleted with the group). A frozen series’ membership is a fixed snapshot, exactly the pre-v15 behaviour.excluded_run_numbersRun numbers the user has dropped from this series without removing them from the owning group — for example a member run whose data turned out to be unusable, kept in the group for record-keeping but excluded from the fit. Effective membership is the owning group’s
member_run_numbersminus this list.last_fitted_membersA snapshot of the members that were actually fit the last time this series ran. When the group’s live membership (minus exclusions) no longer matches this snapshot, the series is stale — the Fit Parameters panel marks its trend pill with a
⚠and a tooltip reading “Membership changed since last fit — re-run to refresh.”; re-running the series updates the snapshot and clears the marker. Detector-group series (member_kind == "groups") and frozen series are never stale.
The Data Browser’s browser_state.data_groups block is a separate, smaller
structure: it is view state (the panel’s own per-group collapsed flag)
rather than the group registry itself, and doubles as a self-contained
fallback for a standalone browser panel or a pre-registry project — the
top-level data_groups list is always the source of truth when both are
present. See GUI usage for the Data Browser’s grouping UI (multi-group
membership, the auto/user colour distinction, and the “Fit this group…”
binding) and Parameter trending for how a stale series surfaces in the
trending panel.
For two-period NeXus runs, grouping metadata persisted with each dataset also
includes red/green period configuration such as period_mode and per-period
histogram metadata used by RG recomputation.
Project files do not embed raw detector arrays or computed Fourier spectra.
Fit series recipe and active series
Every batches entry (schema v20) carries the setup that produced it as a
recipe dict, and its own trend gating:
recipe{"parameters": [...], "fit_range": {"min": ..., "max": ...}, "seeding": "auto"|..., "coadd": {"mode": "off"|..., "window": 2}}.parametersis the Batch tab’s table at record time — one entry per physics parameter withname,value,type(Global/Local/Fixed/File),boundsandseeded;fit_rangeis the window the series was cropped to, in the representation’s own unit, with either boundnullfor unbounded;seedingis the Batch tab’s per-run seeding mode;coaddis the co-add mode and window. This is the whole recipe a re-run compares for identity (below), and what the Batch tab restores when you reopen the series.trend_excluded_runsMember run numbers ticked out of this series’ trend without touching its fit — the per-series successor to the old per-slot
include_in_trendflag, toggled from the same Exclude from trend plot action.
Recording a series compares its recipe and effective member set against
what is already recorded — the series open in the Batch tab first, then the
representation’s active series (below), then the newest series already
describing the same analysis — as a single canonical identity string
(FitSeries.recipe_identity()). An identical match replaces that
series’ results in place, keeping its batch_id and label; any
difference — a wider window, a different model or classification, a
different member set — writes a new batches entry instead, with a
fresh id and a default label derived from the recipe
(<model> · <fit-range>[ · <group>], suffixed `` (2)`` on a collision).
Nothing is ever superseded or deduplicated at load time: two series that
differ only in fit range are two entries, kept side by side.
The top-level active_series object maps each representation’s value
("time_fb_asymmetry", "freq_fft", …) to the batch_id of its
active series — the one the Batch tab has open, the Parameters chip rail
highlights, and the plot draws by default on every run the series covers.
Deleting a series clears any active_series entry that pointed at it,
leaving that representation with none until another is opened or recorded.
Joint fits (schema v22)
The top-level joint_fits list holds one entry per recorded
joint fit, serialised from
JointFit:
joint_id,label,rep_typeThe record’s id, its user-assigned label (
nullwhen it still tracks the members’ own default name), and the representation type its members belong to.member_batch_idsThe member series’
batch_idvalues, in tick order — also the order a shared row’s seed is taken from (its first contributing member).sharedOne entry per shared-table row:
name,members({batch_id: that series' own parameter name}),value, andmin/max(nullfor an unbounded side).resultThe last run’s summary only — shared values, uncertainties, the shared covariance rows, combined and per-series χ², and a timestamp — never curves; the curves are each member’s own
results_by_run, already persisted there under its ownbatch_id.
A pre-v22 project has no joint fits: _migrate_v21_to_v22 is purely
additive (version bump plus an empty joint_fits list). A malformed
shared row is dropped individually on load rather than failing the whole
record, and a record naming fewer than two members is dropped entirely — a
joint fit of one series composes nothing.
Every entry in batches gains two optional, additive fields once a joint
run has recorded onto it: joint_fit_id (the owning record’s id, or
null for an unstamped series) and shared_params ({this series' own
parameter name: shared name}, empty when unstamped). Both are display
state read by the Parameters panel and the joint-fit window, never part of
what the series is — FitSeries.recipe_identity() ignores them, so
automatic replacement also requires known matching member observations. Changed
or unknown inputs retain separate histories. A solo Batch-tab run of a stamped
series clears both fields,
which is what makes staleness (see Staleness and detaching
in Joint fits) computable from live project state rather than stored.
Saved single fits (schema v25)
A representation’s single_fits maps each projection to the single fits
saved on it (Saving and comparing single fits): "" keys the default view, a label
such as "P_x" a projection of a vector grouping. Each entry is
{"open_id", "fits"}: the fits in the order they were saved, and the id of
the one the Single tab shows. An open_id that names no fit (a hand-edited
file) opens the newest. Each fit is a FitSlot holding a Single-tab fit alone:
model,parameters,resultThe composite model, its parameter table and the fit-result summary —
null/empty for a representation that has never been singly fitted.provenance"none","single"or"wizard"."batch"and"global"are recognised only while reading an older file — schema v19 and earlier wrote them for a run that belonged to a batch or global fit; the v19→v20 migration drops such a slot entirely, since its result already lives on the series that recorded it.ui_stateThe single-fit form payload (composite model, parameters, result HTML, wizard cache) needed to restore the editor verbatim; present only when the single-fit GUI itself produced the slot, omitted (not written) otherwise.
fit_id,label,fit_rangeA project-unique id (the plot draws a saved fit that is not open under
"single:<fit_id>"); a user rename or a disambiguating name,nullwhile the default<model> · <window>applies; and the window fitted,{"min", "max"}in the domain’s unit, withnullfor an open side (a frequency fit over the whole spectrum).
A saved fit without captured observation attribution remains inspectable but does not enter a verified same-data ranking. A missing window remains unknown.
A slot no longer carries batch_id, diverged or include_in_trend:
per-run state cannot diverge when it only ever holds one fit, and trend
gating moved to the series’ own trend_excluded_runs above. A run with no
single fit but a series result still shows fitted state on the Single tab —
reconstructed from the active series’ recorded result for that run, not
stored on the slot itself (GUI usage, “Carrying a model forward
between runs”).
Rotating frames (schema v26)
Schema v26 records the rotating-frame projection in three places, all optional and additive.
rotating_frameon a dataset entryThe run’s frame, serialised from
RotatingFrame:frequency_mhz(ν_RF in MHz),b1_axis("x"or"y"),rf_phase_deg(φ_RF in degrees),sense(1or-1),gain(a_y/a_x),baselines— one{"x", "y", "provenance"}per period, in per cent, red first — andprovenance, mapping each of the five scalar fields to"default","estimated"or"typed". A run never shown in the rotating frame has no key.frame_snapshoton a single fitA FitSlot fitted on
P′_xorP′_ystores the frame its data were rotated in:{"frame": <rotating_frame as above>, "weights": [...], "reduction": "<sha256 hex>"}. The weights say how the fitted curve combined the run’s periods ([1, 0]for red,[-1, 1]for green − red);reductionis a digest of the grouping settings that shape \(P_x\) and \(P_y\) (groups, α, binning, t0, deadtime and the like), leaving out which projection or period is displayed. A fit whose run now rotates differently, or whose pair is reduced differently, is shown as stale. The snapshot is the data’s provenance, not part of the fit’s identity, and every other fit omits it.projectionandmember_frameson abatchesentryprojectionis the rotated projection every member was fitted on ("P′_x"or"P′_y"), the lab axis of a vector-polarisation series ("P_x","P_y"or"P_z"), ornullfor a series without projections; it is part ofFitSeries.recipe_identity(), so a rotated series and a lab-frame one are never merged.member_framesmaps each member’s run number (as a string) to the snapshot it was fitted in, and is empty for every other series.
_migrate_v25_to_v26 only moves the version: a pre-v26 project has no
frames, no rotated fits and no rotated series, and each reader takes an absent
key as none.
Wizard cache state
The single-fit and global-fit panels may each include an optional
wizard_state block inside their saved UI state.
For single-fit runs this stores:
the cached recommendation payload for the run
the signature used to decide whether the cached result can be reused
the wizard log text shown in the analysis log window
For the global-fit tab this stores the cached global recommendation together with the run-set, parameter-role, value, and bounds signature that produced it.
These blocks are optional and backward-compatible. Older project files do not need them, but when present they allow wizard results to reopen immediately without rerunning the expensive analysis.
Each cache records the scope it was screened under (the model family picker’s
state; see Choosing which models to screen) in its signature, and a
single-fit recommendation also inside its build_signature string. Since
schema v23 a scope is {"version": 2, "physics", "include", "exclude",
"skip_slow"}: the physics classes looked for (an empty list means every
class), the models switched on and off by name, and the Leave out slow
models switch. Up to v22 a scope named a preset that fixed a geometry as
well as the physics; _migrate_v22_to_v23 rewrites each one to that
preset’s physics classes, keeps its include and exclude lists, and drops the
geometry, which now always comes from the runs.
Since schema v24 a stored Global Fit Wizard recommendation records its
objective ("trend" or "statistical"), and each candidate a rung:
null for a candidate of the statistical role search, otherwise what its
sharing-ladder fit cost in \(\sigma\), the trend quality of each local
parameter, and the runs exempt from a shared amplitude.
_migrate_v23_to_v24 marks every older recommendation "statistical" with
no rungs and drops the trace diagnostics its parameter roles used to carry.
A field direction the user answered in the picker, for a run whose file records
none, is saved in that dataset’s metadata_overrides as field_direction
("Zero field", "Longitudinal", or "Transverse") together with
field_direction_source: "user". On open it is re-applied only while the file
still records no direction. The keys are optional, so no migration is involved.
The stored recommendation is a compact form of the in-memory one. A live recommendation keeps, for every candidate it assessed, a fitted curve, its component curves and the fit residuals at the resolution of the analysed record — hundreds of megabytes on a fine-resolution run. What is written to the file instead is:
each curve sampled on a uniform stride down to at most 512 points (all the curves of one candidate share a stride, so they stay aligned), with each sample rounded to seven significant digits — these arrays are only ever drawn, and the wizard’s own plots decimate more aggressively than that;
no residual series — the numbers derived from it (residual RMS, runs z-score, autocorrelation, FFT peak SNR and the gate reasons) are stored on the assessment itself, so only the residual panel of a cached redisplay is affected: in the Fit Wizard it is blank until the wizard is re-run for that run, and the Global Fit Wizard recomputes its residual strips from the data and the stored curve, interpolated between the curve’s samples.
Everything else — the ranking, scores, fitted parameters, uncertainties, diagnostics, peak analysis and narrative — is stored in full, so a reopened project still shows the cached recommendation without re-running the analysis: the Fit Wizard’s comparison table and answer card, or the Global Fit Wizard’s Screen and Compare steps. Re-running the wizard always restores full-resolution curves and residuals.
Payloads written before this change (full-resolution curves, residuals included) still load unchanged; no schema bump is involved, since the block is optional and both shapes deserialise.
Grouping profiles and assignments
The project’s named grouping profiles (see Detector Grouping and Layout) are
stored in a top-level grouping_profiles list. Each entry is a serialized
profile — its name, fingerprint ({"instrument": ...,
"histogram_count": ...}), the grouping structure, and the alpha, deadtime,
background, and t0 policies. The active flag marks each fingerprint’s
default-for-new-runs profile (exactly one per fingerprint); several
profiles of the same fingerprint may be in concurrent use. An optional
color (a #rrggbb string, assigned from the GUI palette when a
non-default profile is first saved; the ★ default stays colourless) is the
profile’s identity colour, worn by its runs’ numbers in the Data Browser and
throughout the Grouping window; profiles saved before colours existed are
tolerated and recoloured on next save.
Each dataset entry records which profile it follows (schema v17):
profileThe name of the dataset’s assigned grouping profile. A dataset carrying only
profilefollows that profile — its grouping is re-resolved against the profile on load. A dataset carrying bothprofileandgrouping_overridesis released: the override payload below is authoritative for resolution, andprofilenames the base profile the run stays assigned to (the reattach target). A dataset with neither key follows its fingerprint’s default profile, as does one whose assigned name no longer resolves.
t0 policy (schema v21)
Each profile’s t0_policy block stores which of the three t0 modes
(Detector Grouping and Layout § Time-zero (t0) modes) it uses — it is always an
explicit, stored choice, never inferred from comparing values:
mode"from_file"(the default),"manual"or"auto_detect".offset_binsManual only — the signed offset, in bins, from each run’s own file t0 (not an absolute bin: one profile shifts every run in scope by the same amount, however their individual headers differ).
legacy_valueA pre-v21 absolute-bin manual t0, carried over unconverted from schema v20 and older. It is not itself resolvable: only project open, once the runs are loaded, can convert it into the equivalent
offset_binsagainst the run the value was originally typed against (source_runwhen recorded, else the first loaded run of the profile’s fingerprint). Resolving a policy that still carrieslegacy_valueraises. Schema v20’s absolutevalueis renamed tolegacy_valueon migration (_migrate_v20_to_v21); nothing is converted at that point.strategy/spread_bins/source_runAuto-detect only — provenance from the last resolution’s search (strategy name and detector spread), plus which run the values came from.
On project open, heal_t0_policies repairs two states that can only be
recognised once the runs are known: it converts any surviving
legacy_value (see above), and it heals a manual policy whose
offset_bins resolves to zero against every run in its scope back to
from_file — a leftover of the pre-v21 comparison-based inference that
mislabelled a plain From file profile as Manual. Each repair is logged (see
Detector Grouping and Layout); the project file itself is not rewritten until
the next save.
Good-window policy
Each profile’s good_window_policy block stores which of the two
good-window modes (Detector Grouping and Layout § Good-window modes) it uses —
an explicit, stored choice, never inferred from a run’s resolved values.
It is written only when the mode is not from_file, so a project without
a Manual good window round-trips with no trace of the key and needs no
schema bump.
mode"from_file"(the default, and the only value ever written before this feature) or"manual".first_offset_bins/last_offset_binsManual only — each end’s signed offset, in bins, from the run’s own effective t0 (the t0 the profile’s
t0_policyresolves to, not necessarily the file t0): one profile therefore gives every run it covers the same window relative to its own t0, and the window rides along automatically when a Manual or Auto-detect t0 shift moves that t0. An end left unset keeps the run’s file value for that end.
Grouping overrides
Each dataset entry in the project JSON may contain a grouping_overrides
block that stores the full custom grouping of a run released from its
profile (or of a run whose fingerprint has no profile). When present, it is
re-applied to the dataset on project load so that the exact detector grouping
is preserved without re-running the Grouping dialog.
grouping_overrides keys:
groupsMapping of group-slot index → list of detector channel indices.
group_namesMapping of group-slot index → display name string (e.g.
"Pz Forward").forward_groupGroup-slot index used as the forward detector sum.
backward_groupGroup-slot index used as the backward detector sum.
alphaCalibration constant α.
first_good_binInteger index of the first bin included in asymmetry computation.
last_good_binInteger index of the last bin included in asymmetry computation.
bunching_factorTime-bin rebunching factor applied to the dataset.
deadtime_correctionBoolean; whether per-detector deadtime correction is active.
deadtime_modeCorrection request:
"off","from_file","manual", or"estimate".deadtime_methodOptional coefficient or estimator provenance.
"file"means per-detector deadtime values from the data file were used.dead_time_usOptional per-detector deadtime values in microseconds, read from formats that provide NeXus-style deadtime metadata.
On restore, correction outcomes are recomputed from the saved request. A run
whose requested correction cannot be applied stays in the project with its
request intact and a “Corrections incomplete” badge. Missing or incomplete File
deadtimes instead produce a usable, warned skipped result. Source file
calibration is restored from the acquisition; saved zero values alone do not
establish historical file-table presence. Fits and data, plot and
fit-report exports refuse while the run is incomplete. A successful Apply
clears the error. The project stores the request, rather than a second copy of
the effective correction outcome.
deadtime_errors_usOptional per-detector standard errors in microseconds from a promoted calibration.
nullmeans unknown, including a nonzero applied base whose covariance with a count-fit increment is unavailable. The total table is saved as a run override, withdeadtime_reference_runnaming its source.background_correctionBoolean; whether grouped-count background subtraction is active.
background_methodOptional string set after grouping is applied.
"fixed"means explicit forward/backward background values were used."estimated"means the values were calculated from background bin ranges. Unavailable or failed corrections prevent Apply; invalid ranges raise an input error.
Authored background intervals remain explicit even when equal to an automatic suggestion. Default resolution does not write derived bounds into the policy. Correction outcomes record local and acquisition bounds and selection provenance; loading preserves authored bounds without requiring a new project schema.
background_rangesOptional inclusive background-bin ranges for forward and backward grouped histograms, stored as
[[forward_start, forward_end],
[backward_start, backward_end]]
. Sharedbackground_rangemetadata may also be used as input.background_valuesOptional forward/backward background values that were subtracted from the grouped histograms during the last grouping apply.
t0_binThe run’s common analysis time-zero: an absolute, 0-based bin index (the max of
detector_t0_binsover the forward/backward analysis groups, unless a t0 policy shifted it — see t0 policy (schema v21) below).t0_time_usOptional exact time-zero in microseconds, kept alongside
t0_binfor formats that record a continuous value (ISIStime_zero, MusrRoot’sDouble_tTime Zero Bin). Absent when the file carries only an integer bin; see Detector Grouping and Layout § Time-zero (t0) modes for the bin-centre time-stamp convention this feeds.t0_sourceHow the run’s t0 was determined:
"file"(the header value, the default),"conflict"(an ISIS file whosetime_zeroandt0_bindisagreed — the attribute won),"missing"(no usable header t0 at all, not yet resolved) or"detected"(a"missing"run resolved against the automatic search’s consensus). See Time-zero search.detector_t0_binsOptional per-detector time-zero bins, used by formats such as PSI BIN/MDU and MusrRoot/LEM ROOT where each detector can carry its own
t0. Grouping aligns detector histograms by these values before summing.effective_detector_t0_binsOptional per-detector t0 bins actually used for alignment, written only when a manual or auto-detect t0 policy resolves to a shift from the file values. Every alignment consumer in the app reads this (when present) in preference to
detector_t0_binsthrough one resolver,effective_detector_t0_bins()incore/transform/t0.py— the run’s loaded histograms and their file-deriveddetector_t0_binsare never mutated.t0_search_strategy/t0_search_spread_binsProvenance recorded when a t0 policy runs the automatic search (Auto-detect, or a From file run whose header t0 was missing): the strategy used (
"prompt_peak"or"pulse_edge") and the detector-to-detector spread of the estimates, in bins.t0_method/t0_reference_runProvenance written by Promote t₀ (Count-domain fitting (α calibration & single histograms)):
t0_methodis always"count_fit", andt0_reference_runis the run number the fitted offset came from — the same pattern asalpha_method/alpha_reference_run.bin_index_baseDisplay-only numbering base for the bin indices above (1 for ISIS, 0 otherwise). The internal, zero-based bin indices are unaffected; this only tells the GUI which number to add back when showing a bin index to the user.
root_histo_numbersOptional list of original ROOT
hDecayhistogram numbers. Present for MusrRoot/LEM ROOT files so grouped detector slots can be traced back to the source ROOT objects used by musrfit.grouping_presetName of the last applied preset (e.g.
"Vector Polarization").instrumentInstrument name set in the Detector Layout Editor (e.g.
"EMU"). Saved so the correct detector schematic is shown on reopen without re-running instrument detection.vector_axisActive polarisation axis at save time (
P_x,P_y,P_z, orALL).period_modeTwo-period RG mode (
Red,Green,G minus R,G plus R).
Crash-safe save and autosave
save_project never writes the target file directly: the new JSON is
serialised to a temporary file in the same directory, flushed and
fsynced, and only then swapped over the target with an atomic
os.replace. A crash, a full disk or a raised exception at any point up
to that swap leaves the previous file exactly as it was and simply drops
the temporary file, so a save can never leave a project half-written. The
file the swap replaces is kept alongside it as <name>.asymp.bak — one
generation, overwritten by the next save — as a manual fallback (open it by
renaming away the .bak); this is skipped for the autosave snapshot
below, which is itself a backup and keeps none of its own. The .bak is
copied from the existing project file rather than the file being renamed to
it, so the project file itself stays in place right up to the swap: there is
no moment at which a crash could leave no project file at all.
While a project has unsaved changes, a timer (default every 5 minutes,
0 disables it — the QSettings key project/autosave_interval_minutes)
writes a crash-recovery snapshot to <name>.autosave.asymp beside a saved
project, or to an untitled.autosave.asymp file under the platform’s
application-data directory for a session that has never been saved. Directory
creation runs with the snapshot write in the background. If creation or writing
fails, the snapshot is skipped and the log reports Autosave failed: ….
Closing an untouched window does not create an application-data directory.
If deleting a snapshot fails, closing continues and the log reports
Could not remove autosave: …. A successful save or a clean window close
attempts to remove the snapshot — including the
untitled snapshot a session wrote before its first Save As. If you
keep working while a save is writing, that work is not in the saved file:
the session stays marked as modified and its snapshot is kept. Opening a
project whose autosave sibling is newer than the file itself asks “An autosave from
<time> is newer than this project. Load the autosave instead?”, with
Load autosave (reads the snapshot but still treats the session as
unsaved against the original path), Open saved file (reads the project
normally and leaves the autosave in place) and Cancel.
Save and load
from asymmetry import __version__
from asymmetry.core.project.schema import CURRENT_SCHEMA_VERSION, load_project, save_project

state = {
    "schema_version": CURRENT_SCHEMA_VERSION,
    "created_with_app_version": __version__,
    "datasets": [{"run_number": 3077, "source_file": "run3077.nxs", "metadata_overrides": {}}],
    "data_groups": [
        {"group_id": "g1", "name": "B = 60 G", "member_run_numbers": [3077],
         "order_key": "run", "kind": "user"},
    ],
    "browser_state": {
        "sort_column": 0,
        "sort_order": "ascending",
        "filters": {},
        "selected_run_numbers": [3077],
        "selected_group_ids": [],
        "data_groups": [
            {"group_id": "g1", "name": "B = 60 G", "member_run_numbers": [3077],
             "collapsed": False, "kind": "user"},
        ],
        "extra_columns": [],
    },
}

save_project(state, "session.asymp")
restored = load_project("session.asymp")
print(restored["schema_version"])
Schema migration
Use migrate_to_current to normalise older project files in scripts or tests.
from asymmetry.core.project.schema import migrate_to_current

old_state = {
    "schema_version": 2,
    "datasets": [],
    "browser_state": {
        "filters": {},
        "selected_run_numbers": [],
        "selected_group_ids": [],
        "data_groups": [],
    },
}

migrated = migrate_to_current(old_state)
print(migrated["schema_version"])  # current schema
Runnable example
See examples/project_files.py for a complete executable script.
Timing provenance
Acquired timing status remains distinct from effective file, manual, estimated,
or unresolved timing. This distinction survives equal numerical anchors.
Resolved grouping payloads retain the timing policy and per-channel outcomes;
alignment metadata records the selected channels and search strategy.
A stored T0Policy.strategy is descriptive provenance, not an explicit
strategy override. Released projects retain their recorded scalar file facts
when no per-channel availability was recorded. Missing provenance alone does
not reclassify an old valid zero anchor as absent. See Time-zero search.
A selected cached-only period retains its cached curve and inspection fallback, but records that acquired histograms for that period are unavailable. That fallback cannot supply an automatic timing estimate. Reopening does not borrow another held period’s delay or reinterpret saved strategy text as an override.
Automatic-tail correction outcomes
An unusable automatic tail remains a tail_fit request after save and restore.
Its skipped outcome and reason accompany usable unsubtracted results;
valid detector deadtime correction remains recorded separately. Reapplying a
changed input or selection recomputes the outcome and clears stale fitted levels
and correction errors. Count-fit summaries retain their background preflight
separately from the joint model’s fitted background.
Applied TF calibration records
A grouping profile can retain frozen CalibrationRecord entries in
calibration_records. Applying a record with apply_calibration makes
its alpha and beta policies read-only views of the same candidate. The record
contains the actual single-model result or all four model-selection candidates;
selection uses the minimum finite total cost among usable candidates, with the
declared envelope order for ties. The applied views name a captured candidate,
so subsequent work does not silently replace an applied coefficient.
The saved request contains user overrides. The full fitted parameter table separately retains effective fixed/free values and search endpoints, including defaults and data-derived seeds. The record retains full nuisance covariance and its unique parameter order, signed MINOS offsets, fit and calibration verdicts, acquired period, source, native timing and raw-bin support, and correction/variance assumptions. Shared acquisition and domain facts are stored once per record. Unbounded endpoints use the project’s non-finite JSON codec.
A missing calibration source file does not prevent loading or using stored
coefficients. CalibrationRecord.require_source diagnoses an unavailable
input before an explicit rerun; opening a project performs no calibration fit
or model selection. Replacing a coefficient policy with a manual policy removes
its active fit link while retaining the frozen record in profile history.
Scalar records retain their recorded method, source, and error; absent model,
window, or covariance provenance remains unknown. Matching scalar values or
source run numbers do not establish a joint calibration.
Covariance errors are conditional on the fitted model, selected support, corrections, and fixed assumptions. Unavailable or unreliable covariance yields no fitted error, even for a usable alpha-only calibration. Fixed beta has no fitted error or alpha/beta correlation. These uncertainties do not include model selection or full propagation into reduced-data covariance. Historical quick errors remain recorded values with unverified uncertainty meaning.
Calibration records
The project format stores full TF candidate/history records and conditional covariance once, with coefficient policies referencing them. Quick calibration policies retain their source period or mapped-set recipe, timing/window, corrections, resolved F/B channel members, authored exclusions, and error meaning. TF domains retain their consumed bank members, with exclusions stored once per record. The captured tuples survive later regrouping and JSON save/open/resave; missing legacy membership or exclusion facts remain unknown. Vector policies identify the actual calibrated projection pair and keep beta fixed at one. Manual changes replace the applied policy while retained fit history stays available. Opening an existing project preserves its authored values and method identities and never starts a fit.
Pulse requests and recorded history
Pulse-response settings remain part of their Fourier or MaxEnt recipe.
An invalid active request remains editable and receives an input diagnosis when
computed; it does not prevent opening the project or inspecting stored arrays.
Historical fit parameters, errors, and curves retain their recorded meaning.
A historical fitted separation is not a new request to estimate separation.
Count fitting accepts only a fixed supplied dpsep for a new solve; a free
API request receives guidance rather than an automatic conversion to fixed intent.
Count-fit editor state does not author a separation-estimation recipe.
Fixed supplied TF calibration response
TF calibration records retain the consumed optional pulse_separation_us
in each candidate request and its fixed effective dpsep. Restoring a record
checks agreement between request and fit. Old absent/None requests remain
Off. Loading never refits; an explicit replay uses the captured request and
selected envelope on the source acquisition. Applying alpha/beta transfers the
frozen record and coefficients, preserving the target’s t0, good bounds, count
arrays, ordinary-fit response, and Fourier settings.
Effective result history
Projects retain captured effective recipes with representation results and each fitted-input summary, including separate projection and series-member histories. A recipe describes resolved grouping, timing, calibration, corrections, binning, and units; it does not contain raw observations or covariance operators. Ordinary and combined time results are recomputed from their saved source/settings requests on open. Their fresh recipe is kept separate from the saved historical account; saved fit parameters and recipes are never relabelled as a verified replay.
Scan-series percent values carry percent recipes with their native fractional recipe as the captured input. Restoring the internal fractional view uses that recorded input; it does not infer a recipe from current controls.
Workflow scan construction retains source-run coordinates separately from the acquired period selectors in the point recipes. Loading a record preserves its captured coordinates; saving does not reinterpret historical scan recipes.
Absent historical recipes and observation digests remain unknown. Frozen calibration references remain frozen, including the distinction between a saved pending preview and committed calibration history. Ordinary point errors stay conditional on calibration and fixed correction assumptions. Derivative scans remain for display/export, and known dependent scans retain their fit restrictions.
Asymmetry also checks actual sampled coordinates, values, errors, usable support, and recorded interpretation before pooling saved-fit rankings or drawing current residuals. Matching run labels, point counts, or recipe identities are insufficient. Unknown or different histories remain inspectable without a verified same-data ranking. An observation digest does not verify external acquisition files or scientific-computation compatibility.
Scientific result history
Integral/ALC baseline, peak, and RF fits retain completed numerical results and sampled overlays on their captured observations. Opening and saving restore these outputs without fitting, preserving old or unknown computation revisions. Baseline dependencies, conditional and baseline-propagated covariances, and available statistics remain distinct. Explicit fitting appends a new execution; input edits detach affected overlays without deleting captured history.
Scalar-scan background fits publish only when the captured project, series, observations, settings, and baseline dependency still apply. Stop, failure, and obsolete completion append no execution. A completed record keeps the request that ran; fitted peak seeds used for the next request remain separate applicability settings. Opening and resaving use retained predictions and readouts without evaluating a new model or optimiser.
Settings-only scan histories keep their settings and retained values, but no
numerical fit is reconstructed. The scan controls explain
Saved fit settings have no captured numerical result. Use Fit baseline, Fit peaks, or Fit RF resonance explicitly to obtain a new result.
See Integral scan mode (avoided-level-crossing field scans) for explicit fitting and uncertainty limits. Unavailable or
changed acquisition files do not replace captured scan observations or fits;
source replacement concerns the selected current acquisition owner.
Saved fit summaries, wizard assessments, scalar scans, and representation result snapshots retain their captured scientific-computation revision. Missing legacy revisions remain unknown when the project is opened and saved. Storage schema compatibility and numerical execution compatibility are separate checks.
Asymmetry also checks execution compatibility before treating a saved analysis as
current: incompatible single fits retain their values and models without a shared
verified ranking or current residuals; series and joint/global studies retain
history and report staleness. A series reports
Historical computation revision; refit to obtain current results.
Reanalyse or refit to obtain a new result. Opening a project does not refit
historical analyses or certify their original inputs; regenerated curves have
their own execution. Manual and explicitly applied historical coefficients
remain available, with their original attribution.
Expected and observed acquisition bytes
Dataset entries retain optional source_binding facts with separate
expected and observed whole-file SHA-256 identities. Fresh acquisition
reads record both from that read. Restoration preserves the saved expectation,
including a legacy unknown, alongside the identity observed with newly loaded
counts; explicit replacement establishes a new expectation for the selected
current owner. Saving does not hash files, promote a new observation to an old
expectation, or certify historical fits, recipes, or calibration records.
Combined entries retain ordered constituent_sources with their own bindings,
coefficients, and period selections. Reconstruction retains their historical
expectations independently of dataset-level expectations and fresh curve recipes,
including when a combination remains unavailable. Unresolved dataset declarations
remain with the existing project-model owner and survive collection without
acquisition reads or fabricated observed identities. Frozen calibration records and supported
result recipes retain the acquisition facts available to their calculation;
reference results describe the counts consumed, including retained cached inputs.
Reference requests may record an expected content_identity independently.
Absent identities remain unknown.
Structural project preparation performs no acquisition I/O. Its sources
inventory exposes sample, constituent, reference-request, calibration, and
recorded representation, saved-fit, and series-result declarations for explicit
core verification.
EffectiveReductionRecipe.sources() also exposes captured result inputs.
No persisted status is accepted as a fresh content comparison. File opening,
autosave recovery, and direct GUI restoration verify before deliberate application
and use the same explicit current-owner decisions as the core API and CLI. Byte verification and scientific-computation
compatibility are separate: identical bytes can match while a saved calculation
remains historical. Source mismatches do not invalidate a usable facility file.