Loading Data
For the operation order and calibration dependencies, see Count reduction and transformed signals.
Asymmetry reads the major muSR raw-data formats through a common
load() API and a uniform Grouping dialog: ISIS
muon NeXus (legacy V1 and V2), PSI BIN/MDU, and MusrRoot/LEM ROOT. The
practical consequence is that data from different facilities can be
compared in one session without manual format-by-format pre-processing.
The loaders preserve format-specific bin indices, per-detector \(t_0\)
offsets, multi-period ISIS files, and PSI temperature sidecars in the same
raw-run data model.
If you are loading a new dataset for the first time, the subsections below document the metadata each loader extracts and the common failure modes. Period-mode files (e.g. photo-μSR light-OFF/ON, RF on/off, avoided-level-crossing) can be navigated with the scriptable period-selection API — see Selecting periods (Red / Green) below.
For an end-to-end walk-through that starts with loading, see Temperature scan through a magnetic transition.
Acquisition shape and alignment
A detector’s acquired histogram is retained before grouping. PSI and ROOT
acquisition arrays must have equal one-dimensional shape; a mismatch raises
count arrays must have equal shape. PSI-MDU records use their declared
format extent, including padding of shorter records, before this check.
All three loaders align the effective selected detectors by their own time-zero
bins and retain only their common observed support, excluding leading and
trailing padding. The grouped_alignment metadata records the local common
anchor, first_bin removed at the front, detector offsets, group lengths,
retained length, and fractional timing residuals and spread in μs. Raw arrays
remain available for inspection. Selected grids must be compatible; an unused
detector cannot change selected timing or grid validity. An empty file-good
intersection makes the quick look unavailable, retaining the raw counts and
per-channel bounds for inspection and repair. See
Detector Grouping and Layout for the exact-reference and raw-bin mapping.
File bounds stay attached to acquired bins through timing edits. Manual endpoints are signed offsets from effective t0 and may override advisory file limits within observed support; omitted endpoints keep their mapped file limits. An invalid authored selection remains editable without changing file loading. See File bounds and authored relative windows.
Explicit temperature channels in scripts
A script can choose a thermometer explicitly with
select_logged_temperature(). Supply the exact full
channel path from dataset.metadata["nexus_time_series"]. Display names and
suffixes are not resolved, so two channels named sample require their full
paths. The Select a logged thermometer uses synthetic logs.
The representative value is the arithmetic mean of all readings whose timestamps
are at or after the run start (time >= 0). Each reading has equal weight;
unevenly spaced readings are not duration-weighted. The time and value arrays
must be non-empty, one-dimensional, and equally sized, and every timestamp must
be finite. Pre-run readings are excluded. At least one run-active reading is
required, and every included reading must be finite and strictly above 0 K after
conversion. Missing readings, NaN, infinity, and sensor dropouts raise
ValueError rather than being discarded or replaced by a header or summary.
Declared units must be K, mK, or °C (including degC), or their
spelled-out aliases: kelvin(s), millikelvin(s), celsius, degree(s) celsius, and
centigrade. Conversion follows the BIPM SI Brochure, ninth edition, sections 2.3.1 and 3,
with the same shared unit conversions as the raw-file loaders.
Missing, unknown, and incompatible units raise ValueError.
The returned copy exposes the chosen value in kelvin through both temperature
and sample_temperature_logged on the dataset and its Run, so scalar labels
and temperature scan coordinates agree. sample_temperature_log_source names
the selected path. temperature_selection records statistic
(arithmetic_mean), the sample policy, and original scalar fields
(temperature, sample_temperature_logged, and
sample_temperature_log_source where present). Selecting another channel retains
these original fields. Raw logs and the input dataset remain unchanged; analysis
arrays and histograms are shared. Loading without this operation retains the
loader’s default policy. A representative temperature does not establish thermal
equilibrium or supply a temperature uncertainty.
Supported formats
ISIS Muon NeXus (.nxs, .nexus)
Asymmetry supports ISIS muon NeXus files (legacy V1 and modern V2), including
multi-period runs. Multi-period files return a list of MuonDataset values.
Scalar sample temperature is read from the NeXus sample header. NXlog-style
temperature groups with time plus value/values datasets are also
summarised in Get Info; the Data Browser keeps the scalar header temperature
unless Options → Use temperature from log or the Temperature (K)
include checkbox is ticked, in which case the log mean is shown while that
selection remains active. The Options menu choice is global and resets all
loaded runs to the same behaviour. The Get Info checkbox affects only the
target run, making it useful for per-dataset overrides. Log-derived temperature
values are shown with red text in the Data Browser.
Separately from that display choice, the loader also derives
sample_temperature_logged — the mean of a sample-thermometer NXlog over
the run, distinct from the parked temperature setpoint (a sample can sit
several kelvin from where the cryostat is parked). Only a log whose path or
NXlog name names both “sample” and “temp” is a candidate — a controller,
cryostat or furnace readback (Temp_RBV, Temp_Cryostat, Temp_Set)
never is, so a run that logs only those reports no logged sample temperature
rather than a controller’s guess. Samples at or below 0 K are dropped before
the mean is taken: ISIS logs a disconnected sensor’s dropout as exactly 0 K,
which is a sensor fault, never a physical reading. A candidate log with no
sample above 0 K, or none of the required name, is recorded in
temperature_log_rejected with the reason, the same key the PSI loader
above uses.
The applied field is read from the sample/magnetic_field header and stored
in gauss, matching the convention the rest of Asymmetry (and the PSI and
MusrRoot loaders) uses. Most ISIS files store the value in gauss with no unit,
which is taken as-is. When the dataset carries a units attribute the loader
honours it: T / tesla is converted by a factor of 104 and
mT / millitesla by a factor of 10. An absent, blank, gauss, or
unrecognised unit is passed through unchanged — the loader never guesses a
conversion the file did not declare.
NeXus-v2 file deadtimes with explicit microsecond or nanosecond units are
converted to μs when loaded: 20 ns and 0.02 μs give the same coefficient.
The units belong to the selected detector dataset (dead_time, deadtime,
or deadtimes). Supported declarations include us, µs, μs, ns,
and the singular or plural words, including byte attributes. Missing and other
unit declarations retain the stored-value-as-μs behaviour. Legacy v1/HDF4
uses fixed μs coefficients regardless of the attribute. Saved project
coefficients are already in μs and are not converted again. Acquired counts,
timing, and counting variance are retained.
NeXus exports retain acquisition deadtime tables separately from authored Manual or Estimate calibration. Missing tables are omitted, short supplied tables retain their detector entries, and complete zero tables remain available identities. Authored coefficients do not become File calibration when an exported run is reopened.
NeXus exports declare units on every written physical quantity: sample
temperature uses kelvin, magnetic_field uses gauss,
corrected_time, time_zero, and dead_time use microseconds,
and resolution uses picoseconds. These declarations follow the
muon NeXus definition
(v1, pp. 9, 11, and 14). Per-detector time zero retains its sub-bin precision.
HiFi can sweep the field with its small Z coil on top of the main solenoid held
persistent, and such a run records only the Z offset (a title of F=50 with
the main at 20900 G). Both coils are logged, as Field_Main and Field_Z;
when the recorded field matches Field_Z rather than Field_Main, the
run’s field is their sum (20950.6 G for that run), and the offset and the main
field are kept beside it in the run’s metadata as field_sweep_gauss and
field_main_gauss, with field_source main+sweep. A run whose recorded
field is the main field itself is left as recorded.
Geometry from the logged coils
HiFi’s field-state stamp is not reliable evidence of the applied field’s
direction (see Measured transverse-field precession); the coils it logs are.
Where nexus_time_series carries active-run means for Field_Main,
Field_Z, Field_X and Field_Y, the survey’s coils geometry
source (Scripting and AI-agent workflow) compares the axial field
(Field_Main + Field_Z) against the transverse
(\(\sqrt{\mathrm{Field\_X}^2 + \mathrm{Field\_Z}^2}\), i.e.
\(\mathrm{hypot}(\mathrm{Field\_X}, \mathrm{Field\_Y})\)): an axial
reading more than ten times the transverse is longitudinal, and a
transverse reading more than ten times the axial left over after
discounting up to 12 G of Z-coil compensation is transverse. These are the
run’s own readbacks of the field it applied, not a name in the header, so
they outrank the file’s TF/LF stamp; a measured precession line
still outranks them, since a transverse field can precess too weakly to be
resolved.
Per-period Hall-probe offset (red/green ALC)
When compatible logs are present, the loader assigns each Field_Hall_Z
sample to the DAE period active at its time using Beamlog_Period_Num
(sample-and-hold), matched to the data periods recorded via period_type.
It records the red median minus the green median as period_hall_offset,
in the Hall probe’s own units, alongside the original logs and declared units.
This is a log summary, not evidence of a calibrated gauss step, RF switching,
or experimental geometry. Physical model choices need the acquisition context;
see Integral scan mode (avoided-level-crossing field scans) and Scripting and AI-agent workflow for explicit field-step/RF inputs.
For NeXus good-data windows, a supported integer counts attribute
(first_good_bin or last_good_bin) takes precedence independently for
each endpoint. V1 also retains the child-dataset spelling as a compatibility
fallback. V2 first_good_time and last_good_time supply a missing
endpoint in physical time, with explicit units converted to μs and missing
units interpreted as μs. These times reference the raw acquisition axis,
before subtracting t0. A zero time is a real bound; an omitted endpoint uses
the corresponding acquired extent. The V1 definition does not define these
physical good-time fields, so V1 uses its integer bounds.
Asymmetry selects whole bins whose raw centres (k + 0.5) * width lie
inside the inclusive physical interval. Stored representation precision is
allowed at a centre, using four storage ULPs for the bound and the nominal
width; this allowance describes representation, not timing uncertainty. This
centre-membership rule is Asymmetry’s explicit selection convention: the
NeXus definition specifies the raw coordinate but does not prescribe a
sub-bin rounding rule. For 32 bins of width 0.02 μs, physical limits
0.22–0.30 μs select raw indices 11–14. An exact t0 of 0.2074 μs stamps those
observations at 0.0226, 0.0426, 0.0626, and 0.0826 μs.
Physical limits accept a global scalar or a period-by-spectrum table; a single-period spectrum vector is also supported. They are resolved once into each acquired histogram’s zero-based inclusive bounds. Regrouping, exclusions, period selection, and project reopening use those same bounds through the shared grouping resolver; raw count arrays retain every acquired bin. Mapped period sums use the intersection of their contributors’ good intervals. An empty interval leaves the initial asymmetry unavailable and the raw histograms available for inspection or an edited request. If selected channels have valid alignment but no common good interval, their common integer anchor and available exact origin remain recorded; unused detectors cannot replace that timing. Mapped detector tables describe the summed histograms, including when period selection uses retained histograms because a held-period table is unavailable.
Asymmetry also checks that optional good bounds can be interpreted in the
supported units and detector/period shape. An unusable optional declaration
is diagnosed and a usable alternative, or the acquired extent for that
endpoint, is retained. This prevents assigning one detector’s limit to another
without rejecting an otherwise usable acquisition. The supplied fields stay
available in metadata["nexus_fields"].
NeXus uses a fixed-bin acquisition model: a usable positive scalar
resolution supplies the nominal width in μs. Explicit time units convert
s, ms, μs (us), ns, or ps, including spelled-out names. Missing resolution
units mean ps in V1 and ns in V2; exact time zero and axis-fallback units mean
μs. These conventions follow the
muon NeXus definition, version 2 revision 8 (including V1), pp. 14 and 49–51.
Field, temperature, and log compatibility are separate from timing decoding.
Supplied raw_time, time_of_flight, and corrected_time arrays and
attributes remain available in metadata["nexus_fields"]. With a usable
resolution they do not determine the grid, shift the acquisition origin, or
veto loading. Accumulated coordinate rounding, discrepant secondary axes, and
unusual terminal coordinates therefore retain every recorded count bin. The
chosen width source is recorded as metadata["nexus_timing_source"].
This nominal fixed-bin interpretation does not establish actual terminal-bin
exposure or physical t0 accuracy.
Without usable resolution, the loader tries raw_time, then
time_of_flight, then corrected_time. Missing fields are skipped. Unusable
numerical values or units are diagnosed and skipped. Empty or multi-token unit
arrays make that declaration unusable; a remaining timing alternative is still
tried. The first supported uniform axis supplies the width from its end-to-end
span, using N+1 edges or N centres. It supplies spacing only: acquisition bins
keep their zero-origin convention.
Asymmetry also checks that an axis used as the width fallback is finite,
increasing, and uniform, with the supported length and at least two points.
These checks protect the uniform-bin interpretation when resolution cannot
supply it; they do not apply to auxiliary axes when resolution is usable.
Uniformity allows four ULPs of the stored dtype at its declared scale. An unsupported
candidate is diagnosed and skipped. When no usable width remains, the error is no usable time axis or positive resolution.
The calibrated-load API cannot assign physical coordinates in that case, so
it does not invent a 1 μs width.
Internal Histogram and grouping indices are zero-based. The ISIS
counts attribute t0_bin is converted to attribute − 1; integer
first_good_bin and last_good_bin retain the supported ISIS
one-based, inclusive compatibility decoding: shared scalars in V1,
and scalars or single-period detector vectors in V2. The published definition alone does not establish an integer
base for every writer; V2 child good-bin datasets are retained as metadata
without adding a new conversion for that spelling. bin_index_base = 1 records the display convention. Good-time
fallback selection is described above.
Asymmetry also checks that timing values can be assigned to the acquired
channels: a scalar broadcasts, a detector vector covers every detector, and a
period-by-detector table covers every period. Nonfinite values, unsupported
time units, and unusable integer anchors are diagnosed; a usable remaining
integer or exact declaration still supplies calibrated timing. This prevents
silently resizing a detector calibration. If no t0 declaration can be
interpreted, raw loading remains available and
t0_source = "missing" invokes the existing automatic-search policy, just as
for absent or unavailable calibration; see Time-zero search.
Asymmetry also checks whether redundant exact time_zero falls inside the
bin identified by t0_bin, allowing stored representation precision at an
edge. This keeps coherent exact origins, including zero, without accepting a
materially displaced header as sub-bin calibration. Disagreement is advisory:
loading succeeds with integer anchors and drops exact origins only for the
conflicting detectors. Coherent detectors retain their exact calibration, so an
unused detector cannot change the selected pair’s timestamps. The run records
t0_source = "conflict" with the warning
NeXus t0_bin/time_zero declarations conflict; keeping integer anchors and dropping exact t0 only for conflicting detectors.
Integer-only timing is sufficient. Auxiliary corrected coordinates cannot
discard a valid exact origin. Loaded timestamps and re-reduction use the same
selected-channel alignment and leading-crop mapping; counts remain unchanged.
Two-period selection retains each period’s own file-timing status, including
header conflicts, alongside its histograms and default reduced arrays.
Compared with other programs
Asymmetry uses declared resolution for fixed-bin NeXus count analysis while
retaining its exact t0 and bin-centre stamps. musrfit 1.12.1 (708f777b, ROOT 6.40.04) exports
identical arrays for synthetic regular, cumulative-float32, and shortened-terminal
coordinate variants with the same counts and resolution. Mantid 6.16.1’s legacy
loader retains coordinate variations: the compared HDF4 inputs
retain their counts exactly. This is a scoped count/coordinate comparison, not
physical timing or exposure certification. See Asymmetry in the μSR software landscape
and the Mantid legacy loader reference.
For NeXus physical good times, the matched Mantid 6.16.1 crop and musrfit 1.12.1 explicit-channel checks, fractional-timing difference, and documented WiMDA timing controls are described in NeXus physical good-time selection. Equal defaults are not implied by agreement on matched raw observations.
For explicit NeXus-v2 deadtime units, Asymmetry converts supported μs/ns declarations to μs. This intentionally differs from musrfit 1.12.1’s compared stored-value-as-μs convention. Missing units and legacy v1 remain outside this conversion; see NeXus deadtime units for the comparison limits.
Asymmetry also checks that selected channels have compatible bin widths before integer alignment, because whole-bin count transport requires one common spacing. Failure affects the requested reduction; acquired histograms remain available for inspection and repair. This selected-operation requirement does not make redundant file coordinates a loading gate. See Detector Grouping and Layout.
HDF4 container (legacy .nxs)
The V1 /run muonTD schema is the format WiMDA reads natively, and ISIS
historically wrote it inside an HDF4 container (pre-~2015 runs) rather than
HDF5. Asymmetry detects the container from the file magic and reads HDF4 V1
files directly — no manual pre-conversion to HDF5 is required. The same schema
reader is used for both containers, so an HDF4 .nxs and its HDF5-converted
twin reduce to identical asymmetry, counts, grouping, and metadata.
HDF4 reading needs the optional pyhdf dependency, installed with the
hdf4 extra:
pip install asymmetry[hdf4]
On Linux the pyhdf wheel bundles the HDF4 C library. On macOS
(Apple Silicon) the PyPI wheel does too (Intel Macs: use conda-forge
pyhdf or build from source). On Windows, pyhdf’s wheel does not
bundle the HDF4 runtime: it also needs hdf.dll / mfhdf.dll (for
example from the conda-forge hdf4 package, as Mantid uses, or via
packaging/windows/fetch_hdf4_dlls.py). Point the ASYMMETRY_HDF4_DLL_DIR
environment variable at the directory holding those DLLs. The pre-built Windows
and Apple Silicon macOS desktop releases bundle HDF4. When pyhdf (or the
Windows runtime) is absent, opening an HDF4 .nxs raises a clear error
naming the hdf4 extra; HDF5 .nxs loading is unaffected.
PSI BIN/MDU (.bin, .mdu)
Asymmetry supports PSI raw histogram files in the classic PSI-BIN and PSI-MDU formats. These files are loaded into normal raw histogram runs, so they use the same full Grouping dialog as ISIS NeXus data.
ROOT and PSI header quantities
Text header quantities are converted to μs, G, and K using the declared unit
adjacent to the number, after an optional uncertainty. Symbols are
case-sensitive (mT and MT differ); spelled-out unit names are
case-insensitive. Both micro glyphs, µ and μ, are accepted.
Quantity |
Stored as |
Accepted units |
|---|---|---|
ROOT time resolution |
μs |
|
Magnetic field |
G |
|
Temperature |
K |
|
For example, 10mT is 100 G, 300mK is 0.3 K, and 20degC is
293.15 K. A PSI label of TF 100 has no unit following the number and uses
the PSI G convention; the T in the prefix is not a tesla declaration.
The SI temperature relation and prefixes follow the
BIPM SI Brochure.
Modern ROOT text headers require a declared unit for present numeric temperature
and field, and a finite, positive RunInfo/Time Resolution. Legacy
TLemRunHeader v4/v5 numeric members use their format units (ns, G, and K),
recorded as source = "format" in declared_units. Missing resolution
raises missing time value. rather than inventing a bin width. Incompatible
units raise an error naming the file, header field, token, and supported units,
for example example.root: RunInfo/Sample Magnetic Field: field unit 'Oe';
supported units: G, kG, T, mT, uT. Oersted describes H rather than B and is
not converted to gauss.
PSI text headers without a unit use K or G, recorded as an unverified format
convention pending instrument review. A declared file unit takes precedence.
MDU’s nonzero mean-temperature header takes precedence over the title’s
sample-temperature field. metadata["declared_units"] records each source
header’s unit, source (file or format), and convention reference;
it contains no duplicate measured values. ROOT sensor logs associated with a
header declaration are converted to the same canonical unit before their
means and primary thermometer are selected. Their unit_declaration retains
the original unit.
PSI format and acquisition details
PSI publishes a data-format overview
and a BIN layout description.
The BIN document does not specify the native MDU layout. Asymmetry accepts
MDU signatures M3, T4, and T5 and reads signed 32-bit histogram
samples and detector tags. All selected histograms share the largest eligible
extent, with zero padding for shorter histograms, so a longer later histogram
retains its samples. M3 retains its final-bin omission. Contradictory
settings and histogram records raise an error before count-array allocation;
selected records must agree in histogram eligibility and bin bounds.
The reader retains at most one histogram’s input samples alongside the
returned count arrays; ignored trailing bytes are not loaded into memory.
PSI filenames containing hifi (such as tdc_hifi_2014_00153.mdu)
identify HAL-9500 at piE3.
The raw metadata retains HIFI while the detector layout resolves to
HAL. This is distinct from both ISIS HiFi and PSI FLAME.
PSI files can store different t0 values per detector. Asymmetry preserves
those detector-specific offsets and aligns counts and supplied independent
variances with identical whole-bin shifts. Two 1000-bin detectors with t0 bins
100 and 110 have common observed aligned bins 10…999. The output retains 990
bins, with local anchor 100 and offsets 0 and −10. Raw bin 0 of the first
detector and raw bin 10 of the second therefore share output bin 0. No padded
bin is treated as an observation.
A reference background is aligned on the sample’s common t0 grid. It must
cover every sample bin: a shorter reference raises an error such as
reference run has 500 aligned bins; sample requires 1000. A longer
reference is cropped to the sample’s terminal bin. The grouped Fourier path
uses the same coverage rule and does not pad a missing reference tail.
PSI file fields, Asymmetry’s bounds, and a program’s analysis request are
distinct. For BIN, Asymmetry takes the supplied t0 and first-good fields
as zero-based raw-bin indices. It stores first/last-good bounds inclusively,
clipped to 0..N-1 for an N-bin histogram. An interior last-good value
60 stays 60; N-1 and N both become N-1. This is clipping,
not subtraction from every upper field. Zero remains a literal bound; it
does not request the full histogram. An empty aligned intersection leaves
the acquisition available with an unavailable quick-look diagnostic.
For PSI-MDU, timing markers use the settings’ resolution factor \(q\):
t0 = (stored_t0 + 1) * q - 1,
first_good = (stored_first_good + 1) * q - 1, and
last_good = stored_last_good * q. These converted indices are clipped
to the loaded histogram and stored inclusively, as for BIN. The marker scale
does not resample the counts. M3’s terminal-sample omission is a separate
format rule; T4/T5 retain that sample.
The default analysis intersects the selected detectors’ shifted inclusive file bounds with their common stored support. For example, 128-bin detectors with t0 4/7 and bounds 16..60 select forward raw bins 16..57 paired with backward raw bins 19..60: 42 observations. A last-good field of 128 instead selects raw 16..124 paired with 19..127: 109 observations. The last acquired bin is retained even when its count is zero. Unselected detectors do not restrict the interval. Loading and re-reduction use the same bounds; explicit grouping windows use inclusive uncropped aligned coordinates. Here forward and backward identify the acquisition channels; the initial analysis pair can swap their roles as described below.
musrfit 1.12.1 (708f777b, ROOT 6.40.04) uses an exclusive upper endpoint
for explicit RUN data intervals at packing one. Thus data 16 58 19 61
selects the same 42 paired observations as the first example. Omitting
data is different: the compared single-histogram workflow falls back to
t0 plus approximately 10 ns through histogram length, rather than applying
the file’s first/last-good fields. A header dump alone does not establish a
default analysis interval. See the musrfit RUN settings
and Asymmetry in the μSR software landscape for the comparison conditions and limits.
PSI label metadata is used to build initial grouping suggestions. BIN labels
such as Forw/Back and MDU positron labels such as F1/B1 become
group names and forward/backward defaults where possible. Users can then edit
the grouping in the same full Grouping dialog used for raw NeXus runs.
Repeated labels are not collapsed: each histogram remains visible as its own
group, with suffixes such as Forw 2 added where needed.
PSI labels define forward/backward along the beam direction, whereas Asymmetry’s pair-asymmetry controls use forward/backward relative to the initial muon spin. For PSI data, the analysis forward/backward selections are therefore initialised with the beam-forward and beam-backward detector groups swapped. The detector layout editor still displays the PSI detector convention.
If the explicit field entry is missing or zero but the PSI comment/title text
contains a recognisable field such as LF 32G or Bz=150 G, the GUI
offers to apply that comment-derived value as the run field. This prompt is
available for PSI BIN/MDU and MusrRoot/LEM ROOT files.
PSI temperature metadata has two sources. The scalar run temperature is read
from the BIN or MDU header. Optional temperature-log sidecars share channel
naming and metadata conventions with Mantid’s LoadPSIMuonBin, and are
read for both BIN and MDU runs: Asymmetry searches from the data file’s
directory, to three directory levels below it, for all .mon files whose
filename carries the run number. The comparison is numeric, so the zero-padded
names PSI actually writes (run_0534.mon for run 534) match, while
run_1554.mon does not; where a name has an explicit run token, only the
digits attached to it count, so variant suffixes such as run_0534_2nd.mon
and run_0534_variox0.mon are not mistaken for runs 2 and 0.
The .mon header date/title, equipment name, and backslash-delimited rows
are parsed into plottable nexus_time_series entries named like
psi_temperature/Temp_<channel> for classic logs or
psi_temperature/<equipment>/<channel> for FLAME tlog files. When FLAME
logs are present, flamesam0/SAM_ts is marked as the primary sample
temperature to match the MusrRoot slow-control convention; flamedil0/DIL_T_mix
and variox0/Variox are retained as secondary sample-temperature traces.
The Get Info window shows these logs in the summary/advanced tables and records
the sidecar paths plus Mantid LoadPSIMuonBin-compatible provenance in
psi_temperature_log metadata.
Because PSI run numbers restart every beam period, a tlog directory can
retain a sidecar whose run number, and whose own Start of Run header line,
match the run being loaded while belonging to an earlier experiment. Each
candidate sidecar’s start timestamp is therefore cross-checked against the
run’s started/stopped window, with a week of slack for clock skew. A sidecar
outside that window is not loaded; it is listed instead in
temperature_log_rejected metadata, with the reason, so a run without a
temperature log says why rather than silently carrying another experiment’s
temperatures. When either timestamp is missing or unparseable there is nothing
to check against and the sidecar is kept. (This is the same
temperature_log_rejected key the NeXus loader below records its own
rejections under, so a caller checks one key regardless of format.)
The header sensors and the logged sample temperature
Independently of any .mon sidecar, every PSI-BIN header carries four
unlabelled temperature sensor means (and their deviations over the run).
Asymmetry
records all four as psi_sensor_temperatures and
psi_sensor_temperature_deviations (in header order), and additionally
promotes sensor 1 to sample_temperature_logged — with
sample_temperature_log_source set to a string naming it as an inferred,
unlabelled header sensor rather than a genuine channel label — when it looks
like a reading of the sample rather than the setpoint or an unconnected
probe:
it must be steady: its deviation over the run under 5 % of its mean;
it must sit within a factor of two of the setpoint either way.
Sensor 0 consistently tracks the setpoint (the control sensor) rather than
the sample, on every GPS/GPD run checked, so it is never promoted; sensor 1
consistently tracks the sample. This is a reading of the numbers on the
files checked, not a manufacturer’s label, so treat
sample_temperature_logged from this source with the same caution as any
other inferred quantity — corroborate it against the run’s title or a
.mon log where one is available. A .mon sidecar is the run’s own
labelled log and always takes precedence: the header sensor is never
promoted beside one, only in its absence. A sensor that fails either gate is
recorded in temperature_log_rejected with the reason (how far from the
setpoint, or how much it scattered), so a PSI run with no logged temperature
says why instead of silently reporting nothing.
MusrRoot / LEM ROOT (.root)
Asymmetry supports ROOT files that follow the PSI/MusrRoot layout used by
musrfit. The loader reads the ROOT objects with uproot and maps the result
into the same raw Run/Histogram model as ISIS NeXus and PSI BIN/MDU
files, so ROOT runs use the full Grouping dialog.
The supported representations use the MusrRoot format and musrfit’s legacy ROOT calibration conventions:
MusrRoot files are detected from
RunHeaderandhDecay%03dhistograms. Both the documentedRunHeaderTFolderlayout and the newerTDirectorylayout are supported. Both use the same scientific reduction after decoding; the container does not select an observation model.Histogram search follows musrfit’s paths:
histos/hDecay%03dfor folder files andhistos/DecayAnaModule/hDecay%03dfor directory files.RunInfovalues such as run number, title, laboratory, instrument, sample, temperature, field, time resolution, number of histograms, and red/green offsets are read from the header when present. Instrument names are matched case-insensitively (FLAME writes the lowercaseflame).DetectorInfoentries provide detector labels, histogram numbers, per-detectort0bins, and detector-specific good-bin ranges when the file supplies them.In the
TDirectorylayout,RunHeaderand its subfolders (RunInfo,DetectorInfo/DetectorNNN,SampleEnvironmentInfo,MagneticFieldEnvironmentInfo,BeamlineInfo,RunSummary) are themselvesTDirectorys, and every leaf is aTObjStringencoding both its key name and its payload as"NNN - Label: Value -@type"(a physical-quantity value carries an optional error, unit, set-point, and free-text description, for exampleTime Resolution: 0.09765625 ns; SiPM). TheNNNprefix is a single counter shared across every subfolder, so numbering within one subfolder is not contiguous; Asymmetry parses these entries by label, never by number. The free-textRunSummaryblock is attached verbatim to the loaded run asmetadata["musrroot_run_summary"], so it is preserved as provenance rather than discarded.PSI GPS MusrRoot exports split each transverse plate into an upstream (
_B) and downstream (_F) half. The default grouping merges each pair into one analysis group per direction (Up,Down,Right,Left), matching the beam-named PSI-BIN export. A fifteen-histogram export additionally carries hardware-combinedUp/Down/Right/Leftcounters alongside the split halves — separate electronics roads that track the summed halves, plus the Mobile detector’s counts on the port it occupies — so grouping both views by default would double up the analysis. Those combined counters are left out of the default groups; they are still loaded and remain individually selectable in the Grouping window’s detector-grouping editor, for diagnostics against the split view or for building a custom grouping from the combined counters instead. This trigger is structural (whether a counter’s_Band_Flabels are both present), not based on the instrument name, so it applies uniformly across PSI ROOT exports that carry this layout.MusrRoot slow-control histograms in
histos/SCAnaModuleare imported as plottablenexus_time_serieslogs. In particular,hSampleTemperatureis summarised as an average temperature in Get Info while the scalarRunInfo/Sample Temperatureremains the default Data Browser value until Options → Use temperature from log or the Temperature (K) include checkbox is ticked. The Options menu choice applies to every loaded run, while the Get Info checkbox overrides only that run. Log-derived temperature values are shown with red text. FLAME ROOT files may use EPICS-style sensor names such asSAM_ts_valueinstead of a literalhSampleTemperaturehistogram; Asymmetry follows theSens=...pointer inRunInfo/Sample Temperatureso the Get Info temperature row still opens the corresponding log plot.
Legacy LEM ROOT files can carry a serialized TLemRunHeader version 4 or 5 in
RunInfo. Asymmetry reads its numeric resolution in ns and per-detector t0
in zero-based bins, then uses the same unit conversion, alignment, and reduction
as modern ROOT and PSI BIN. Histogram numbers (including hDecay00), titles,
and every stored count are retained. Display strings do not override numeric
calibration; histogram axes do not supply a missing physical width. Negative
unspecified and nonfinite t0 entries supply no file anchor for that detector. The legacy
header does not supply detector good-bin bounds, so the initial window uses
the existing t0-to-end defaults; an explicit analysis window remains editable.
Version 4’s supported four-channel layout maps header slots 0–3 to
hDecay00–03 and hDecay20–23, respectively. All eight stored
arrays remain separate; the active header count does not select or truncate
them. Other histogram numbers retain counts but have no assigned v4 timing.
Version 5 retains its direct zero-based mapping. Other legacy class versions
are outside these supported layouts. root_format records lem-root-v4
or lem-root-v5 and format-unit provenance names the actual class version.
The musrfit LEM format description identifies bank 00 as non-post-pileup (NPP) and bank 20 as post-pileup-corrected (PPC). Choose channels within one bank; the banks are alternative stored observations, not independent detectors to combine. Loading applies no further pileup correction. For the two tested v4 examples the initial pair is bank-00 left/right; other bank/default-layout behaviour and physical grouping require separate checking.
For the matched synthetic PSI comparison, musrfit 1.12.1 (708f777b, ROOT
6.40.04) reads BIN, legacy LEM ROOT, and modern MusrRoot TFolder with
identical selected count/time/error exports. Asymmetry preserves those raw
observations and reproduces F/B asymmetry and Poisson errors within the ASCII
export precision (relative tolerance \(5\times10^{-6}\)). Legacy decimal
ns versus BIN float32 width accounts for a relative timing difference below
\(3\times10^{-8}\). The generated TDirectory form uses a lower-case
decayAnaModule name that this musrfit reader does not accept; Asymmetry
reads it. No numerical agreement is claimed for that musrfit path, or for
WiMDA or Mantid reading this legacy class. This recorded cross-format native comparison uses synthetic files.
Selected-bin reductions are also tested on three acquired musrfit 1.12.1
example ROOT files (revision 708f777b): modern LEM terminal bounds and
FLAME/HiFi interior bounds. Default and matched explicit requests are compared
separately; matched counts agree exactly, with times and applicable errors
agreeing at ASCII export precision. The HiFi error comparison uses a populated
pair in addition to the initial pair containing an empty channel. See
Asymmetry in the μSR software landscape for uncertainty scope and remaining coverage
limits.
Two acquired legacy v4 examples from the same musrfit revision also load with all eight decay arrays and 66,601 stored bins per array retained. Matched NPP and PPC channels 1/3 select bank 00 and bank 20 respectively, using file t0 or an explicit override. Raw bins 3500–3539 give exact summed counts and F/B values, times, and counting errors agreeing within relative \(5\times10^{-6}\) ASCII precision (F/B absolute tolerance \(5\times10^{-7}\)). PPC comparisons treat the stored values as observations under the declared counting-error model; they do not validate pileup physics or corrected-count covariance. See PSI legacy ROOT calibration for the comparison and fixture limits.
Asymmetry also checks that the resolved physical width is finite and positive before calibrated loading, because its fixed-bin time axis requires it. Without usable header calibration, loading fails with the file and timing field named; no width is inferred from a convenient histogram axis. This does not impose agreement between optional display metadata and numeric calibration.
The optional uproot dependency is required for ROOT loading. Install with
the root extra if it is not already present.
Deadtime correction remains controlled by the Grouping dialog. File mode
uses per-detector deadtime values already supplied by a run file, while
Manual, Cal, and Estimate resolve their deadtime payload in the
Grouping dialog and then apply that same payload to all selected runs. The
resolved payload is also reused for future datasets loaded into the same
project, matching the existing grouping-template workflow.
PSI BIN/MDU and MusrRoot/LEM ROOT files do not normally contain NeXus-style
file deadtime constants. A requested File correction continues uncorrected
with a warning when required coefficients are absent or incomplete. Those
formats can still use manual per-detector values, Cal per-detector fits, or
Estimate. Cal/Estimate fit the rational decay mean separately for every
raw source detector; Estimate averages the coefficients, rather than fitting
a pooled spectrum. Their availability does not establish physical suitability
for continuous PSI acquisitions. The stored unity exposure convention is not
a measured pulsed frame count. Preprocessed ROOT banks are not automatically
raw Poisson observations. See Detector Grouping and Layout for source/window and
conditional-error assumptions; no different exposure is inferred at loading.
Reference subtraction exposure is separate from the deadtime denominator.
NeXus good-frame fields (good_frames, goodfrm, and
periods/good_frames), applicable frames_period_daq arrays, and
single-period frames_good retain their field origin. A scalar run total
cannot establish separate period exposures; an unverified DAE-period mapping
or generic frames alias also leaves subtraction exposure unknown. Invalid
exposure does not prevent raw loading. The established deadtime field precedence
and normalisation remain separate.
PSI BIN/MDU and ROOT whole-run normalisation one has unknown subtraction exposure. Automatic reference scaling applies one with the visible assumption “Exposure unknown; scale 1 assumed”; Manual uses its authored coefficient. No duration, integrated-event, monitor, or beam-current exposure is inferred. Asymmetry-written NeXus files retain the explicit exposure declaration separately from the deadtime field, including unknown origin. See Background correction for scale provenance and variance limits.
Background correction is a separate Grouping dialog toggle for PSI-style data
(.bin, .mdu, and PSI/LEM .root). It subtracts a count background
from grouped raw forward/backward histograms before asymmetry calculation.
The toggle is off by default and disabled
for ISIS/NeXus data, keeping the correction split explicit: ISIS uses
file-based deadtime correction when available, while PSI uses grouped
background correction.
Reference provenance
The format and correction behaviour is split by source so that the application does not invent format rules:
PSI BIN/MDU files preserve detector counts, labels, and timing markers. BIN offsets are described in the public PSI format document linked above.
MusrRoot/LEM ROOT parsing follows the MusrRoot documentation:
RunHeadermetadata plushDecayhistograms are mapped into Asymmetry’s raw run model.Per-detector
t0handling follows the PSI file metadata exposed by those readers; Asymmetry stores these asdetector_t0_binsand aligns detector histograms before grouping.Background correction groups forward/backward histograms, subtracts fixed values or mean background from inclusive bin ranges, then calculates asymmetry. If no ranges are supplied, the fallback range is
0.1 * t0to0.6 * t0. The corrected-count uncertainty retains independent count variance and shared background-level covariance as described in Background correction. Asymmetry appliesalphato the backward group.File-based deadtime correction uses the non-paralyzable formula:
N_corr = N / (1 - N * dead_time / (time_bin * good_frames)). Thegood_framesnormalisation is read from the file’s top-levelgood_frames/goodfrmwhen present; legacy ISIS HDF4 / NeXus-V1 files (e.g. HiFi runs) omit it, so Asymmetry falls back toinstrument/beam(frames_period_daqper data period, thenframes_period, then theframes_good/framesrun total).frames_period_daqcomes first becauseframes_periodcounts the DAE’s periods, and a HiFi red/green run cycles four of them — ramp up, field on, ramp down, field off, logged[0, 15000, 0, 15001]— into its two data periods. Without that fallback the count defaults to 1 and the correction over-normalises by orders of magnitude.The Grouping dialog exposes Manual values, per-detector
Calfits, andEstimatealongside file deadtimes. Estimate fits every raw detector of its selected source run, averages the fitted coefficients arithmetically, and broadcasts the result to runs following the profile. Cal uses the preview reference source and persists its individual coefficients through the manual editor. The documented WiMDA calibration workflow does not establish an identical pooling rule or estimator. See Deadtime calibration methods.Asymmetry preserves actual file-table availability: a supplied complete zero table is identity, while an absent table is not manufactured from zeros. The Mantid BIN loading control does not establish an identical deadtime-table policy. Short tables never cycle or borrow coefficients from another detector or period. Missing optional calibration does not block raw loading.
PSI
.montemperature sidecars share channel naming and provenance metadata with MantidLoadPSIMuonBin. Both BIN and MDU runs can load sidecars; a sidecar with an inconsistent start timestamp is rejected.
Grouping behaviour by format
In the GUI, supported raw data runs use the full Grouping dialog:
NeXus runs use the full Grouping dialog.
- PSI BIN/MDU runs use the full Grouping dialog, with PSI label-derived
forward/backward defaults when labels such as
Forw/BackorF1/B1are present.
- MusrRoot/LEM ROOT runs use the full Grouping dialog. Detector names from
DetectorInfoor ROOT histogram titles become the initial group names, and ROOT per-detectort0values are handled like PSI BIN/MDUt0metadata. PSI GPS split-half transverse counters (_B/_F) merge into one default group per direction; if the export also carries the hardware-combinedUp/Down/Right/Leftcounters, those are left ungrouped by default (still loaded and selectable) rather than duplicating the split-half groups.
Basic usage
Loading a single file
from asymmetry.core.io import load

dataset = load("path/to/data.nxs")
print(dataset.summary())
The same load API can be used with NeXus files:
dataset_or_periods = load("path/to/HIFI00206453.nxs")
if isinstance(dataset_or_periods, list):
   print(f"Loaded {len(dataset_or_periods)} periods")
And with PSI raw files:
dataset = load("deltat_pta_gps_3110.bin")
dataset = load("tdc_hifi_2014_00153.mdu")
And with MusrRoot/LEM ROOT files:
dataset = load("lem15_his_2994.root")
The returned MuonDataset contains:
time: Time axis in microsecondsasymmetry: Asymmetry valueserror: Error barsmetadata: Run metadata (temperature, field, etc.)run: Reference to the original Run object
Selecting periods (Red / Green)
Period-mode runs record several period histograms in one file — for example
light-OFF and light-ON in a photo-μSR experiment, RF on/off, or ALC
steps. Use the period-selection API to pull out a single period as an ordinary
MuonDataset with its own provenance (t0, good-bin window, grouping,
temperature, field, per-period good_frames and deadtime):
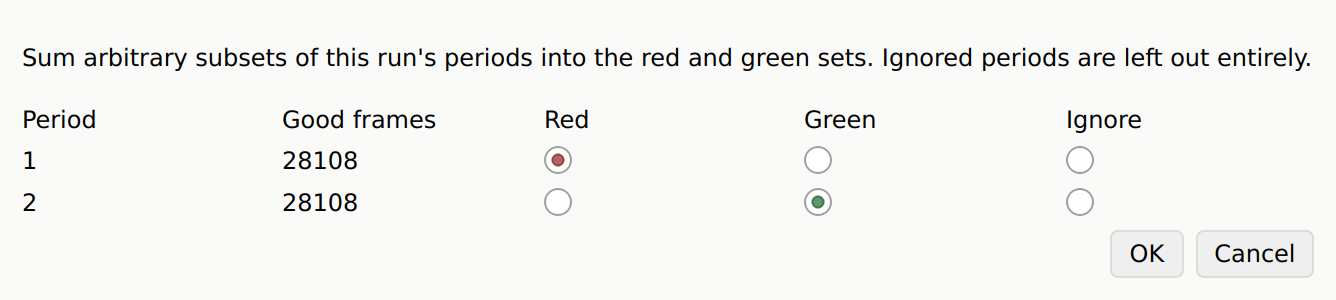
The Map Periods dialog (Grouping window ▸ Map periods…) assigns a multi-period run’s periods to the red and green sets; for two-period runs the RG Mode radios in the Grouping window select the period directly.
from asymmetry.core.io import load, select_period, period_count, period_labels

run = load("HIFI00103277.nxs")          # two-period photo-µSR run
print(period_count(run))                 # 2
print(period_labels(run))                # ['red', 'green']

light_on = select_period(run, "red")     # period 1
light_off = select_period(run, "green")  # period 2

# ...or select at load time:
light_off = load("HIFI00103277.nxs", period="green")
For the common two-period case the first period is labelled "red" and the
second "green" (the same convention as the GUI “RG box”). You can also pass
a 1-based integer period number, which is the way to address files with three
or more periods. In a photo-μSR experiment the convention is light-OFF =
Green (period 2) and light-ON = Red (period 1); confirm this against the
relaxation for your instrument. Out-of-range numbers and unknown labels raise a
clear error at the boundary. The GUI red/green selector calls this same core
API, so scripts and the desktop app agree on the per-period spectra.
The G±R combination aligns acquired observations in whole native bins on common observed support before binning and ratio formation. G+R pools prepared counts; G−R differences independently reduced sets. No fractional resampling or padding is applied. Empty support or incompatible widths make the requested combination unavailable while each period remains selectable.
Accessing metadata
dataset = load("data.nxs")

print(f"Run number: {dataset.run_number}")
print(f"Temperature: {dataset.metadata.get('temperature')} K")
print(f"Field: {dataset.metadata.get('field')} G")
print(f"Title: {dataset.metadata.get('title')}")
In the GUI the same preserved provenance is surfaced by right-clicking a run in the Data Browser and choosing Get Info, which opens the run-information dialog:
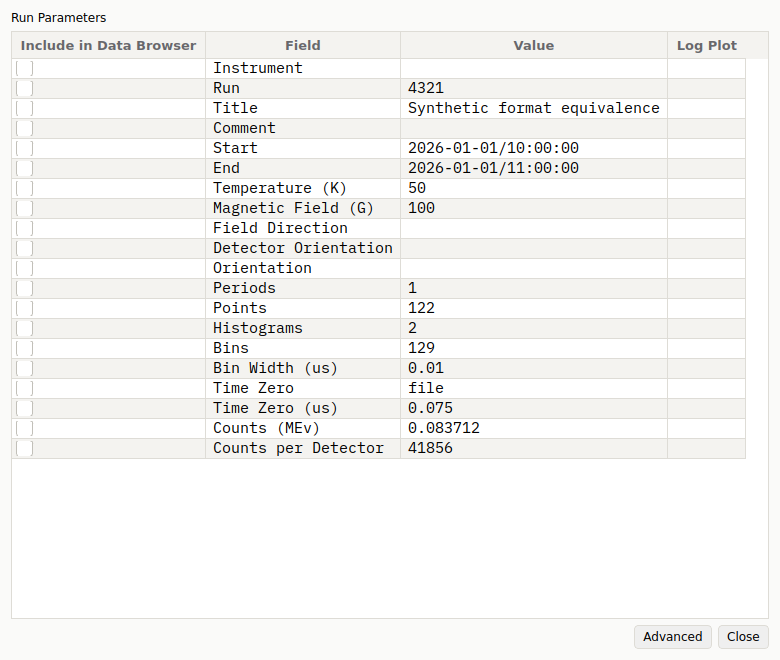
The Run Parameters table in the Get Info dialog for a loaded synthetic legacy LEM ROOT run. Each field is selectable for inclusion in the Data Browser via the Include in Data Browser column. The numeric header supplies the title, temperature, field, run timestamps, and file time zero. Two detector histograms retain 129 bins each, including the terminal zero, with a 0.01 μs bin width; the summed counts remain available alongside that calibration.
Loading multiple files
from pathlib import Path

data_dir = Path("data")
datasets = []

for nexus_file in data_dir.glob("*.nxs"):
    dataset = load(str(nexus_file))
    datasets.append(dataset)

print(f"Loaded {len(datasets)} datasets")
Loading a run range
A contiguous run series — a field or temperature scan such as BiSCCO 1276–1289 — can be loaded in one step from a folder plus a first/last run number, instead of selecting every file by hand.
Why this exists. The native Open dialog’s File name field holds only a bounded number of characters (~256), so a long quoted list of ~15 file names is silently truncated and the load has to be split into batches. The run-range path resolves the files itself and never passes them through that field, so a whole scan loads at once.
In the GUI. Choose File → Load Run Range…. Pick the folder that holds
the run files; the dialog prefills the run Prefix (e.g. MUSR) and the
first/last run numbers from the files it finds there. Adjust the range if you
want a subset, then click OK. The matching runs are loaded through the
ordinary multi-file path (duplicate prompts, auto-grouping, and the missing-run
gap warning all apply). The log records how many of the requested runs were
found, e.g. Loading run range 1276–1289: 14 of 14 runs found.
The prefill scan is capped at 20,000 directory entries so a huge facility folder (often on a slow network mount) cannot stall the dialog. When the cap is hit, a warning appears under the folder field — “This folder has too many files to scan in full — showing the first N run files found. Adjust the range by hand if runs are missing.” — and the prefilled first/last numbers may cover only part of the folder; type the range you want and the load proceeds normally.
In scripts. resolve_run_range() is the pure,
GUI-free resolver behind the dialog. It scans a folder and returns the existing
files for an inclusive run range, sorted by run number:
from asymmetry.core.io import load, resolve_run_range

files = resolve_run_range("data/BiSCCO", 1276, 1289, prefix="MUSR")
datasets = [load(str(path)) for path in files]
Resolver semantics:
Inclusive range. Both
firstandlastare included. The result is sorted ascending by run number.Padding-agnostic. The run number is parsed from the trailing digits of each file name, so any zero-pad width matches —
MUSR00001276.nxsresolves to run1276.Prefix.
prefix(the leading text before the run-number digits) is matched case-insensitively. When omitted it is auto-detected: if the files in range all share one prefix it is used, and if several prefixes are present aValueErrorlists them so you can pass an explicitprefix=.Extensions. Only files with a loader-registered extension are considered (so sidecar logs such as
.mon/.txtare ignored). Passext="nxs"to restrict the scan to a single format.Missing runs are skipped. Gaps in the range are not an error — the resolver returns the runs that exist and omits the rest. The GUI separately warns when the loaded runs are non-contiguous.
Errors. A missing or non-directory folder, or
first > last, raisesValueError. A valid folder with no matching runs in range returns an empty list (the GUI reports this as “no run files found”).
Direct file format access
For advanced users, you can access the low-level file loaders. For NeXus files:
from asymmetry.core.io.nexus import NexusLoader

loader = NexusLoader()
dataset_or_periods = loader.load("HIFI00206453.nxs")
For ROOT files:
from asymmetry.core.io.root import RootLoader

loader = RootLoader()
dataset = loader.load("lem15_his_2994.root")
Loader registry and custom formats
LoaderRegistry maps file extensions to loader classes.
from asymmetry.core.io.base import LoaderRegistry

print(LoaderRegistry.supported_extensions())
print(LoaderRegistry.file_dialog_filter())
You can register custom loader classes at runtime for additional formats.
Runnable examples
See the executable scripts:
examples/basic_dataset_loading.pyexamples/custom_loader.py
Selected automatic timing
Missing t0 does not reject an otherwise readable acquisition. A calibrated quick look requires usable timing for every selected acquired channel. Known-strategy fallback estimates only required missing anchors; usable file anchors remain intact. Unknown strategy or an unsuccessful required estimate leaves the quick look unavailable and retains raw histograms for repair. Integer-only and legitimate zero calibration remain sufficient. ROOT stores per-channel file availability separately from effective timing outcomes. See Time-zero search for source precedence and feature assumptions.
Acquisition content identity
Fresh reads through the built-in NeXus, PSI, and ROOT loaders capture a whole-file
SHA-256 identity with the acquired counts. Direct loader calls and the common
load entry point use the same capture boundary. Two complete hashes bracket
decoding; equal digests and unchanged filesystem change indicators establish an
ordinary stable read. This assumes concurrent writers do not defeat filesystem
change reporting. Period views share the captured fact; selecting another period
does not hash again. PSI monitor sidecars are outside the acquisition-file digest.
If hashing is unavailable or a change is detected during decoding, usable counts remain loadable with unknown content identity. Cancellation aborts the operation. Synthetic in-memory runs have unknown identity. Loader quick-look curves produced before capture may retain unknown recipe provenance; a subsequent supported core reduction records the acquisition fact available with its counts.
run.source_binding separates the saved expected identity from the
observed identity captured with the current counts. Content equality is
independent of filename, run number, timestamp, scientific-computation revision,
and statistical observation identity. It does not certify metadata interpretation
or physical validity. See Project files and Input/output for persistence
and explicit cancellable comparison.
Opening project sources
Project opening verifies caller-resolved input candidates before replacing the session. Identical relocation proceeds; legacy unknowns remain usable and unverified. Source Content Changed offers Open History Only, Accept Replacement, and Cancel for known changed current inputs. Historical-only differences are informational. See Project files for the preserved history, unavailable observations, and partial-restoration contract.