Background correction
Background handling involves three different quantities. An accidental count level is an uncorrelated rate in the detector histograms; Range average, Tail fit, and Fixed values estimate or declare a level to remove before forming asymmetry. A reference count spectrum is a separate acquisition whose shape and scale must represent counts present in the sample measurement; Background run subtracts that declared contribution. A physical holder signal comes from muons stopping in the holder or cryostat and carries its own polarisation. Model that signal with additive fit components appropriate to the field, reference frame, and relaxation [MusrfitTutorial]. An exposure ratio alone does not calibrate its contribution.
Subtracting a count-rate background matters because the asymmetry is a ratio: a flat rate \(\eta\) added to both groups pulls \(A(t)\) toward zero by a factor that grows as \(e^{t/\tau_\mu}\) relative to the muon signal. At a continuous source (PSI, TRIUMF) the uncorrelated rate is significant and limits useful data to roughly 8 μs; at a pulsed source (ISIS) the beam duty factor of about \(1.6\times10^{-3}\) suppresses it to nearly nothing — but “nearly nothing” can still matter when fitting weak relaxation out to 20–32 μs, which is exactly the regime pulsed sources exist for.
The grouping dialog’s Background selector chooses the mode per dataset; facility and instrument labels guide defaults and advice, rather than method access. The correction is applied to the grouped forward/backward counts before the asymmetry ratio, with the subtraction’s shared uncertainty propagated through the merged counts.
Regrouping reevaluates an enabled range, tail-fit or reference-run operation on the current counts and effective window. It retains the configured method, options and declared reference run. Fixed background levels stay fixed, and an off correction stays off. Per-run alpha uses these same corrected counts; fixed and one-shot calibrated alpha values remain stored choices.
Correction outcomes
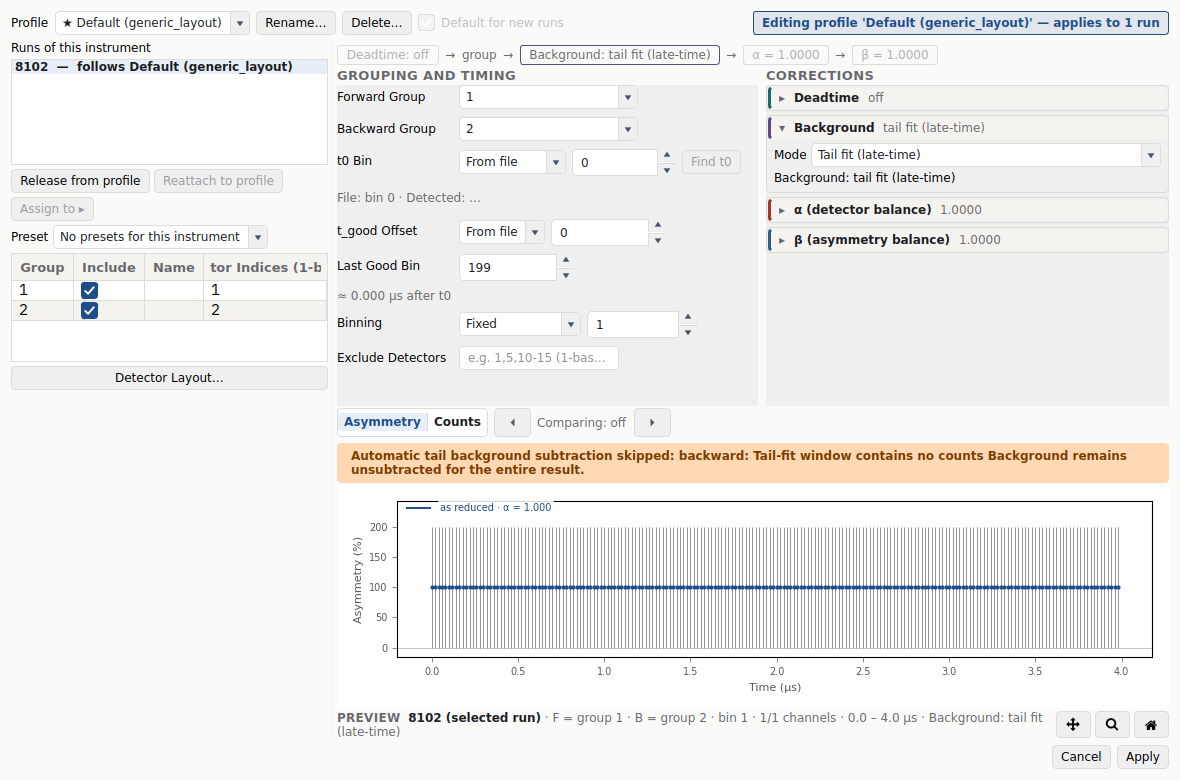
An unusable automatic Tail fit estimate produces a usable skipped
background outcome. Asymmetry preserves negative observations in the actual
selected tail; it never clips them into a Poisson estimate. If either F/B group
or any contributing period cannot support the estimate, background remains
unsubtracted for the entire requested result. Correctly applied detector
deadtime correction and supplied variances remain intact. The warning says
“Automatic tail background subtraction skipped:” followed by the attributed
reason and “Background remains unsubtracted for the entire result.”
A successful zero-background optimum remains applied. Negative observations
outside the actual fit window, or values made negative by successful subtraction,
do not trigger a skip. The configured mode stays tail_fit; a skipped result
has no effective fitted levels and is never labelled background-corrected.
Missing or incomplete File deadtime coefficients have their separate accepted
skip policy. Missing reference runs, absent fixed values, invalid manual
settings, unsupported authored ranges, and saturated required deadtime inverses
retain their errors. File loading does not depend on tail estimability.
The core API returns corrections on grouped counts and grouped asymmetry
results. Each CorrectionOutcome records its name, requested mode, status
(off, applied, skipped, unavailable, or failed), and any failure reason.
Applied outcomes carry the effective settings and uncertainty convention:
levels and errors, effective estimation ranges, tail-fit diagnostics, or the
reference identity, frame counts, scale, and detector alignment. Reference
scaling records whether it uses evidenced acquisition exposures, an authored
Manual coefficient, or a visible unity assumption when exposure is unknown. These records
are immutable; CorrectionOutcomes.to_dict() exports an independent JSON
snapshot. complete and require_complete() describe calculation acceptance,
including warned skipped File deadtime and automatic-tail outcomes. They reject unavailable
or failed corrections. Only applied carries effective coefficients.
A File request uses the sample and reference acquisitions’ own tables; if
either lacks a required detector coefficient, both remain uncorrected by deadtime while reference
background subtraction still proceeds. Manual coefficients remain the shared
authored table, with each acquisition’s own frame exposure.
For F/B reduction, correction dependencies include the output samples and the active estimator’s samples only. Range estimation uses the exact explicit interval or its resolved automatic default; tail fitting uses the late half of selected good-data support. Disjoint output and range windows leave an unused gap uncorrected and unchecked by the inverse. Reference samples use the sample output window through the reference’s own alignment, table, and exposure. Fixed levels add no acquisition samples. Inactive configured ranges do not participate. Required sample/reference coefficients are resolved together before any inverse is applied; grouping, timing, and background errors remain independent failures.
A preview may request allow_incomplete=True and inspect the outcome.
The grouping preview uses already-loaded reference runs without reading files.
If the reference is not loaded, it displays
“Incomplete preview — not applied: background (reference run is not loaded)”.
Apply is disabled until the preview is complete. A final apply refuses any
unavailable or failed correction and leaves that run’s arrays and grouping unchanged.
Red/green combinations require both period outcomes to be complete and retain
separate effective values for each period. Estimated default background ranges
are recomputed from the current time zero; they do not become explicit requests.
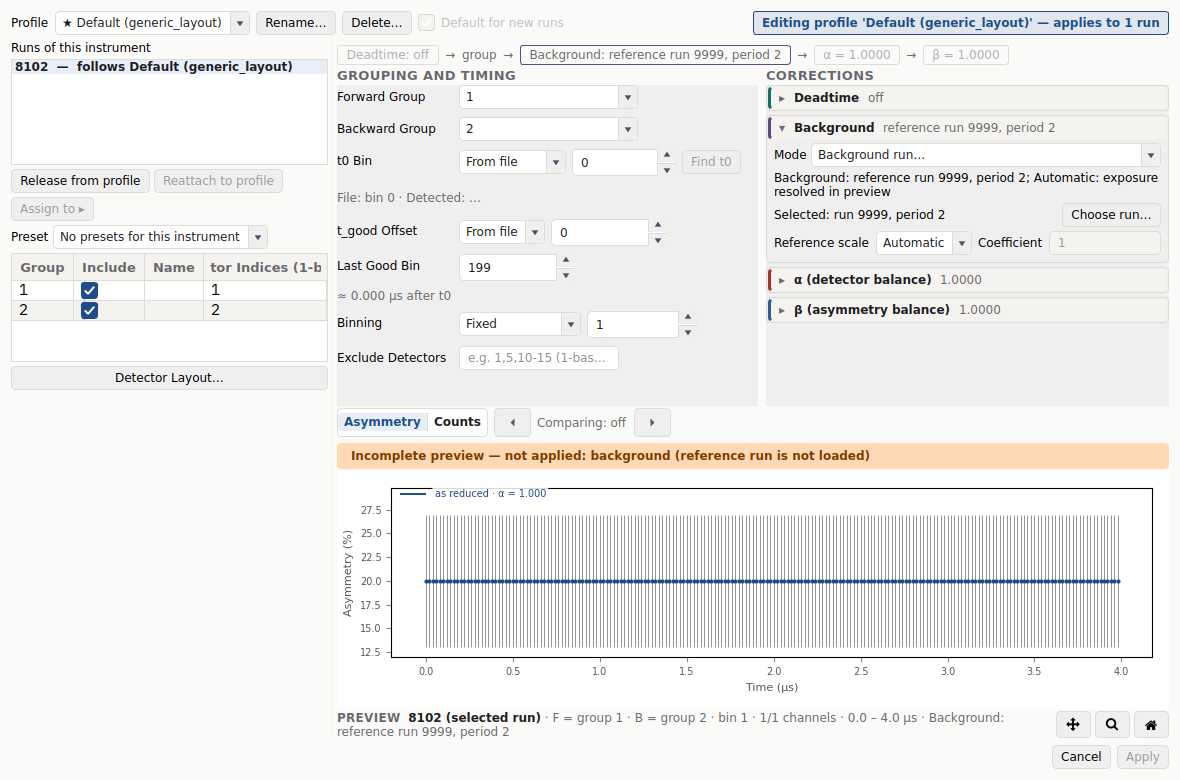
Such arrays are incomplete diagnostic results and must not be promoted as a corrected analysis. Final reduction requires complete outcomes by default.
An accepted tail skip keeps Apply enabled and displays “Correction warning” on the resulting dataset. Cached and restored results retain requested mode, status, and reason; changing the data or selection recomputes the decision and clears stale fitted levels. Grouped count displays compare the contents of count and supplied-variance arrays, including in-place edits. Large input checks show “Checking histogram data…” with Cancel while the interface remains responsive; a cancelled check does not populate the cache. Automatic alpha calibration uses the same contributing period decision; fixed and one-shot calibrated values remain authored.
Choosing a mode
Data in hand |
Mode |
|---|---|
Continuous-source data |
Range average — the pre-t0 bins measure the uncorrelated rate directly |
Pulsed-source data |
Tail fit — estimate a flat rate from the late-time spectrum |
Reference count spectrum |
Background run — compatible reference spectrum with a justified shape and scale |
Known constants |
Fixed values (from a stored grouping) |
For holder or cryostat polarisation, use the existing additive Composite models rather than choosing a subtraction mode solely because an empty-holder or silver run is available. Reference runs can constrain a physical model, but stopping populations and detector response must be applicable to the sample measurement. Laser-on minus laser-off data can instead define a difference observable; they need not recover an absolute sample polarisation. See Run arithmetic: co-add and co-subtract for that workflow.
Physical sample and holder signals
A simple asymmetry model is the sum
The amplitudes describe the measured sample and holder contributions; they are not an exposure ratio. A Constant component describes a non-relaxing signal only when it is stationary in the chosen frame. Use relaxing components or oscillations with the appropriate field and phase when the holder response requires them [MusrfitTutorial]. Fit these alongside the sample components in the Build Fit Function dialog, retaining independent amplitudes as appropriate.
For example, Exponential + Constant with A_1=20, Lambda=0.35
μs⁻¹, and A_bg=4 evaluates
\(20\exp(-0.35t)+4\) percent for time in μs. In fractional units the
same curve is \(0.2\exp(-0.35t)+0.04\); divide the percent output by 100
before comparing fraction-valued curves. See Asymmetry units across the API.
This illustrates units and model composition, not a holder calibration.
Even in an equal-response mixture with a known holder fraction \(0\leq f<1\), \(P_\mathrm{total}=(1-f)P_s+fP_h\). Subtracting \(fP_h\) leaves \((1-f)P_s\); recovering \(P_s\) also requires division by \(1-f\). Neither that fraction nor equal response follows from exposure. Count-reference subtraction remains useful when its declared contribution and scale actually describe the experiment.
Range average
The arithmetic mean of aligned grouped counts over a signal-free interval is subtracted from each group. Explicit intervals are available through the API, CLI, and GUI for any supported histogram acquisition, including files with blank facility metadata. A label or file extension cannot establish whether the chosen interval contains only background.
In the Background card choose Range average, then Edit intervals….
The Background intervals dialog accepts separate forward and backward bounds
as first,last; first,last, in inclusive, zero-based acquisition bins. For
example, 1,71; 2,63 selects 71 forward and 62 backward observations. The
preview shows the resulting subtraction; Apply retains the authored bounds.
Cancelling the editor or changing modes preserves them. The CLI accepts a shared
interval as --background range:1:71; API grouping accepts background_range
or separate background_ranges. Choose bounds that lie within the observed
aligned support; loading a file does not enable subtraction.
With no authored interval, the automatic suggestion is int(0.1 * t0) through
int(0.6 * t0). A usable pre-t0 interval is often available at continuous
sources. At t0=0 no such default exists: the preview asks
“Select an explicit background interval; no pre-t0 default is available.”
The method remains accessible and the file remains inspectable. Supply an interval
only when the acquisition provides a suitable signal-free region.
Every valid explicit interval is used exactly, including separate F/B bounds and
values equal to the automatic suggestion. Only automatic defaults use the
PSI/TRIUMF accelerator-period convention, rounded using native bin width before
output merging. Defaults shorter than one period are not shortened. Inclusive
endpoints and integer rounding do not imply exact whole-cycle exposure or removal
of periodic-background bias. Pass metadata=run.metadata to histogram-level
reduction APIs to resolve the facility; facility="" opts out of this default
adjustment and a nonempty value overrides the metadata.
Declared range endpoints are inclusive acquisition-bin integers. The window
must be ordered and contained in the aligned count record. For example,
[4, 1] raises good-bin window [4, 1] is reversed. and [0, 9]
on eight bins raises good-bin window [0, 9] is outside 8 bins. A malformed
pair raises background range requires two integer bin indices. The
same rules apply to grouped Fourier backgrounds. An absent range selects the
pre-t0 default; a declared invalid range raises an error.
Grouped Fourier and MaxEnt translate estimation windows from the forward/backward alignment grid to their common detector grid. An additional group with a later t0 therefore leaves the background’s acquisition bins and shared uncertainty unchanged.
Tail fit (late-time)
Fits the late half of the resolved selected good-data support on native bins.
For inclusive support \([a,b]\), the start is
\(a+\lfloor(b-a+1)/2\rfloor\), retaining the middle bin for odd lengths.
For example, selected [40,99] fits [70,99]; selected [40,98] fits
[69,98]. Alignment and detector timing map those same observations to raw
bins for deadtime correction, signed-input decisions, previews, and downstream
preparation. Output merging does not change the fit support.
The lower-level fit_tail_background API defaults an omitted first_good_bin
to time zero (clipped to observed support); explicit fit_start_bin overrides
the midpoint. Reduction callers supply both resolved good endpoints.
The fixed-lifetime muon decay plus flat-rate model is
where \(w\) is the bin width, \(t\) is the bin centre relative to time zero, and the bracketed factor averages the exponential across each bin. Both the amplitude \(p_1\) at time zero and flat rate \(p_2\) are nonnegative and expressed in counts/μs; subtraction removes \(w p_2\) counts per native bin. The fit maximises the Poisson histogram likelihood [BakerCousins1984], including zero-count bins. For deadtime-corrected observations this is an estimating objective; its uncertainty uses the supplied count variance through the estimator’s linearised influence. The fitted rate is reported with its uncertainty, e.g. 0.23(11) counts/μs, and flagged when it is consistent with zero.
This mode is useful for pulsed-source data analysed to long times. Persistent polarisation or another departure from the exponential-plus-flat model can change the estimated level even when the numerical optimum is well determined. Convergence does not detect that model error. Asymmetry requires a finite positive native bin width, at least five nonnegative observations, a positive total, identifiable expected information, and finite positive propagated uncertainty. A positive decay amplitude that cannot be represented at the declared time zero also fails, preserving the meaning of the returned physical parameters. The five-bin minimum is a conservative implementation rule, not a universal statistical requirement. These checks establish numerical estimability; they do not certify the physical model or interval coverage at a parameter boundary.
Stable likelihood optimisation
Write the expected counts as \(\mu_i=T p_i(f)\), where \(p_i(f)=f d_i+(1-f)/m\), \(d_i\) is the exponential shape normalised over the \(m\) selected bins, and \(0\leq f\leq1\). The total expected count has the analytic optimum \(\hat T=\sum_i n_i\). The remaining log likelihood is concave in \(f\); its monotone score determines either a bracketed root or a boundary optimum. Normalising the shape on the selected bins makes the fitted flat rate invariant under an equivalent time-origin/amplitude change on identical observations. Expected-information uncertainty is evaluated in anchored count coordinates before conversion to rate units. The reported amplitude retains its meaning at time zero.
Compared with other programs
Asymmetry selects the late half of resolved native good-data support and
honours authored shared/separate intervals exactly. The WiMDA original
manual, Sec. 5.8
describes decay-plus-background fitting and manual/file/region options;
that description does not establish identical observations or weights.
Mantid’s Corrections tab, version 6.11.0 documentation
describes a fixed-lifetime FlatBackground + ExpDecayMuon fit and a
chi-square threshold of 10 for skipping a correction. This documentation
edition is separate from the native 6.16.1 controls. Exact current sparse-bin,
constraint, and fit-status policies are not established by those method
pointers. Asymmetry retains its native-bin constrained Poisson estimating
objective and information checks, without adopting that chi-square threshold.
musrfit 1.12.1 (708f777b) averages a selected region in its asymmetry
preparation. A fitted background in a single-histogram count fit is part of a
joint model, rather than an equivalent automatic tail-subtraction step.
Asymmetry also retains the level shared by corrected bins and its covariance
with the estimating observations. Matching a central level does not establish
matching corrected errors. See Count-background estimates for the
comparison’s scope and uncertainty differences.
Background run
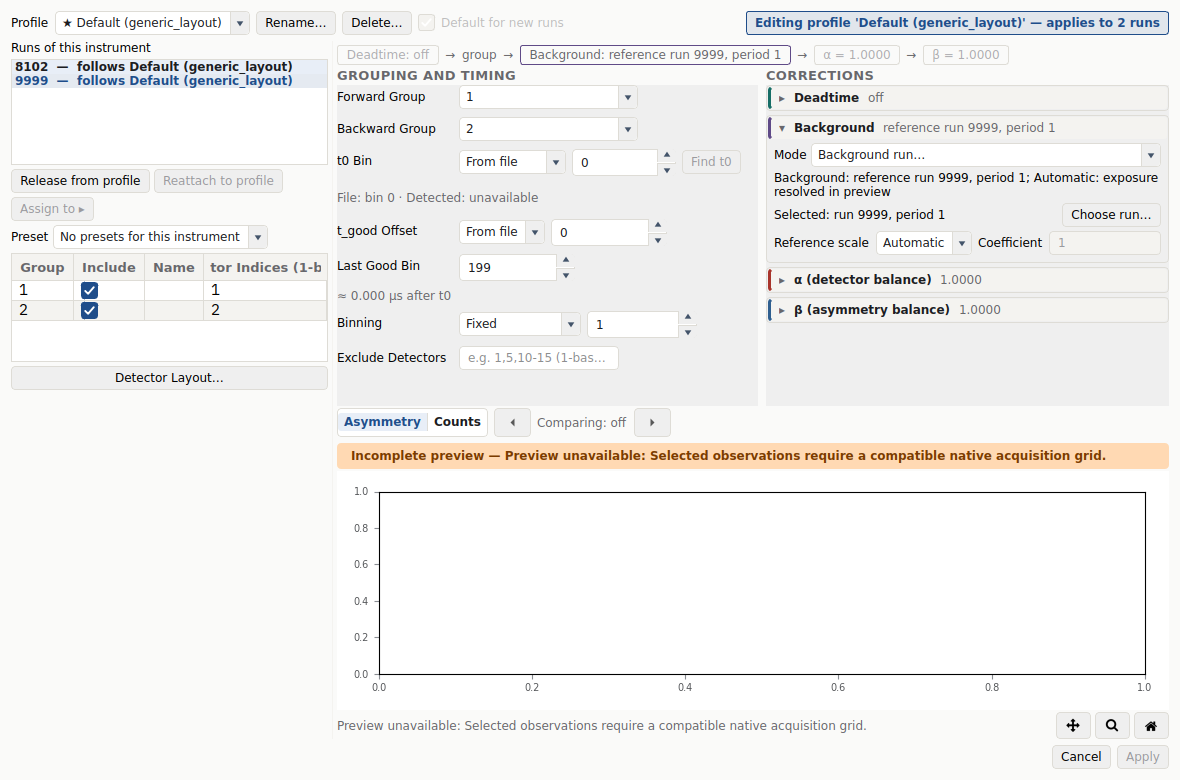
The Background run selection records the source acquisition and its acquired period. Choosing a loaded green period keeps its counts, calibration, and exposure when resolved from disk or reopened in a project. Browse for file… selects period 1; load the required period first to choose another period in the picker. The picker offers acquired periods. Nontrivial mapped selections cannot be replayed as one acquired reference period and remain explicitly unavailable; choose the original acquired period rows instead. A matching live loaded input takes precedence over a cached disk snapshot, including in-memory count edits. A declared file cannot be replaced by another file with the same run number. Number-only requests must identify a unique loaded acquisition and period. Applied provenance records the actual source, source run number, and acquired period rather than the browser’s encoded row key.
Asymmetry also checks that a reference does not contain the identical acquired
observations as the sample: the independent-input variance formula below would
be invalid for self-subtraction. Different acquired periods in one file remain
eligible. This checks the resolved acquisition/period and directly shared count
arrays; it does not establish arbitrary covariance or detector correspondence.
The picker excludes the selected sample acquisition/period. An invalid scripted
request raises an error before corrected arrays are returned. Missing references
retain the incomplete preview and final-reduction failure described above;
loading and inspecting the raw acquisition remains available.
Histogram-only scripted previews of a resolved reference must also supply the
sample Run. Without it, the preview reports
“Reference-background preview requires the sample Run to identify its observations”
and cannot be accepted. Run-based reduction and calibration paths use the run’s
source and number even when optional metadata omits those fields.
The reference controls do not establish identical same-acquisition validation in WiMDA, Mantid, or musrfit.
A declared count reference is subtracted using a fixed coefficient \(s\):
The supplied variances are retained, including for negative corrected counts. This expression assumes independent measurements and treats the chosen scale as exact. It does not include uncertainty in an estimated coefficient or covariance between results sharing one reference. Exposure alone does not calibrate the physical holder fraction or prove that the reference describes counts to remove.
In the Background section choose Background run…, then Choose run…. Reference scale offers Automatic and Manual:
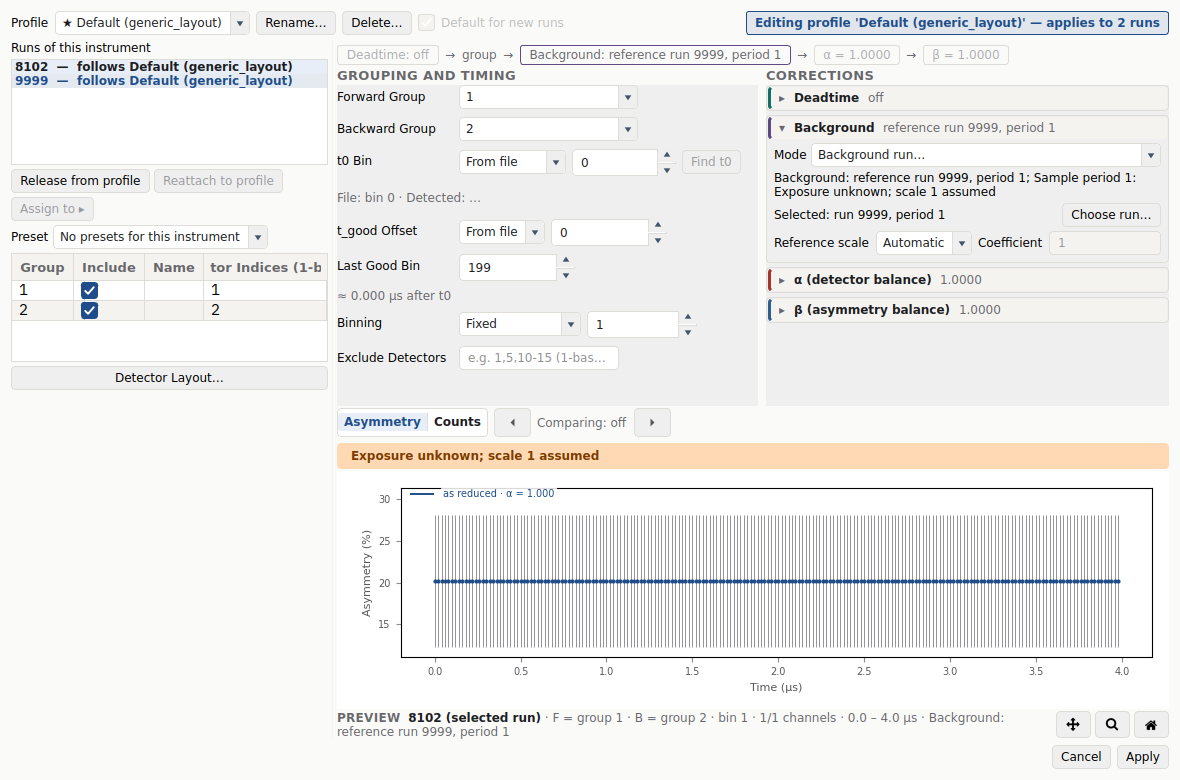
Automatic uses the sample/reference ratio of evidenced, compatible exposure counts from the selected acquired periods. For example, 200 and 100 measured good frames give \(s=2\). When either exposure is unknown or the units are incompatible, it applies \(s=1\) and displays “Exposure unknown; scale 1 assumed”. This is an applied correction with an explicit assumption, rather than a skipped correction.
Manual uses Coefficient, a finite positive multiplier of the reference counts. A coefficient of seven remains seven regardless of measured frames, saved snapshots, period selection, or a live reference timing edit. Invalid text remains editable; the preview explains “Manual reference coefficient must be finite and positive”.
PSI BIN/MDU and supported ROOT whole-run deadtime normalisation of one is not measured pulse exposure. A genuinely measured numeric good-frame count of one remains measured. JSON booleans are invalid as exposure evidence or Manual coefficients; they cannot stand for numeric one or zero. Untagged frame-like numbers, duration, event totals, monitor fields, beam-current metadata, and instrument labels cannot establish subtraction exposure. File exposure origin travels with selected periods. A scalar run total broadcast across several periods for deadtime cannot establish each period’s subtraction exposure. See Loading Data.
The same scale owner serves preview, final reduction, alpha calibration, and spectral preparation. Applied/API/export provenance records the request, actual coefficient, scale source, exposure facts, and fixed-scale uncertainty convention. Profiles and per-run overrides retain the authored choice through project reopen; per-run acquisition facts are not inherited from another sample.
For scripted reduction, set the reference declaration in the grouping:
grouping["background_run"] = {
    "source_file": "reference.nxs",
    "run_number": 42,
    "period_number": 1,
    "scale_request": {"mode": "manual", "coefficient": 7.0},
}
Use {"mode": "automatic"} for exposure scaling. Bare scale or
good_frames_* request fields are rejected; use scale_request to declare
intent. Project loading performs the historical conversion once. At the core resolver boundary,
sample_exposure=ReferenceExposure.from_grouping(sample.grouping) carries
exposure evidence; a bare deadtime denominator does not. Acquired facts are
reloaded from the selected source. Historical frame snapshots remain unverified
provenance and are never combined with one live side. Combined counts do not
inherit the first contributor’s measured exposure: only compatible evidenced unit
sums establish pooled exposure. Resampled or arbitrary signed/weighted datasets
use the visible unknown-exposure fallback under Automatic.
Run arithmetic prepares original sample acquisitions before pooling and applies one requested group background or shared reference afterwards. Manual background levels retain requested-observation count units. The reference’s noise is included once, independently of the number of sample contributors. Unit sums pool only compatible evidenced exposure; signed/weighted counts do not create measured exposure. See Run arithmetic: co-add and co-subtract.
File deadtime uses each acquisition’s own coefficient table and deadtime normaliser. Manual deadtime uses the shared authored coefficients with each acquisition’s own normaliser. These values remain separate from subtraction exposure and from Reference scale.
Sample and reference timing resolve independently using From file, Manual, or Auto-detect. A sample timing request never changes the reference anchors. Integer-bin alignment transports observed counts without interpolation. Exact file origins retain fractional residuals; applied reference alignment records those residuals relative to the sample’s selected exact anchor, along with the reference timing sources and search strategy. A Manual offset remains relative to the reference’s own file timing. A matching live reference’s timing takes precedence and updates the recorded source-bound request. Saving captures the live timing in both profile and run-override declarations, including unambiguous number-only references. Unavailable or ambiguous declarations remain editable and saveable. When only its file is available, the saved request is replayed against the selected acquisition. Manual and Auto-detect requests cannot silently become From file. Edit timing on the reference’s own row before selecting it with Choose run…; no second timing editor is required.
Asymmetry also checks compatible native bin widths for the selected observations at subtraction. Widths may differ by at most one float64 ULP, admitting scalar representation rounding rather than a different acquisition interval. Required reference support must cover the returned sample count grid, including preview context; selecting a narrower output window does not supply absent reference observations. No missing bins are padded, output silently shortened, or counts resampled. These checks apply to the requested operation and selected channels; they do not restrict loading or raw inspection. F/B reduction, alpha calibration, and grouped Fourier/MaxEnt preparation use the same reference alignment. Reference Auto and missing-file timing searches run on cancellable workers. Final preparation displays “Resolving reference timing…” with Cancel when a fresh search is needed; cancellation publishes no corrected result. Verified unchanged source/request inputs reuse the existing cache.
Reference subtraction removes a time-dependent count spectrum when its shape and chosen scale represent the actual contribution in the sample measurement. A holder polarisation can instead be represented by an additive fit component. For period differences, each acquired period retains its own exposure; those exposures need not be equal.
Compared with other programs
WiMDA 1.326 FileBG uses one active channel shift for both sample and reference arrays. Asymmetry keeps independently resolved timing. Reference loading can change WiMDA’s active timing; the matched tagged-spectrum comparison restores sample timing before export. See Reference timing and native coordinates for the numerical example, settings, and scope.
Mantid 6.16.1 generic Minus requires compatible X arrays, but does not infer this independent t0 alignment. It is not an equivalent automatic Muon reference GUI workflow. musrfit run addition is a distinct operation and does not establish external-reference subtraction behaviour.
WiMDA 1.326 FileBG provides the measured-frame ratio and whole-run normalisation precedent. Its bounded 200/100-frame, 200/30-count example gives 140 counts with deadtime off. Asymmetry’s explicit Manual choice overrides that ratio. Unknown-exposure labelling is an Asymmetry assumption; no equivalent WiMDA label is claimed. Mantid 6.16.1 Scale supplies an explicit authored factor before generic Minus, rather than an equivalent automatic Muon GUI reference workflow. No musrfit external-reference scale policy is established by these comparisons.
WiMDA’s matched FileBG check subtracts raw reference counts from a deadtime-corrected sample and retains the sample error bars. Asymmetry corrects both independent acquisitions first and retains measured or supplied independent counting variances. The reused 200/30-count example gives 152.186836518 counts and variance 320 for Asymmetry and explicit Mantid arithmetic, compared with WiMDA’s 153.333 counts and sample-only error 14.1421. See Reference subtraction: deadtime and counting errors for settings, tolerances, and limits.
musrfit models sample and holder signals additively [MusrfitTutorial]; this is a physical fit model, not an external FileBG operation. The reused musrfit 1.12.1 generic ASCII example and its percent/fraction convention are bounded in Additive physical signals and amplitude units.
Uncertainty of a subtracted background
An estimated constant level is one measurement shared by every corrected bin. Let \(v_j\) be the independent variance of raw count \(r_j\), \(\sigma_\theta^2\) the level-estimate variance, and \(\kappa_j=\operatorname{cov}(r_j,\hat\theta)\). The sensitivity of a corrected count to a subtracted level is \(g_j=-1\). A weighted sum has variance
For an output bin merging \(m\) raw bins this becomes \(\sum v_j+m^2\sigma_\theta^2-2m\sum\kappa_j\). The last term accounts for overlap with the background-estimation window; overlap is allowed. For a range mean the expression follows directly from the raw counts’ linear coefficients, including when the two windows coincide. The corrected sum over its own estimation window is identically zero with zero variance.
Mode |
Independent variance |
Shared level and raw-count covariance |
|---|---|---|
Fixed values |
Observed raw counts |
None; the declared level is exact. |
Range average |
Observed raw counts |
For estimation window \(W\) with \(n_W\) bins, \(\sigma_\theta^2=\sum_W r_j/n_W^2\) and \(\kappa_j=r_j/n_W\) on \(W\), zero elsewhere. |
Tail fit |
Fitted Poisson means inside the fit window; observed counts outside |
Expected-information variance and the linearised likelihood influence below; covariance is zero outside the fit window. |
Background run |
Supplied \(v_j+s^2V_j\) |
None; reference bins are independent and the fixed coefficient \(s\) is treated as known. |
For the tail fit, let \(\mu_j\) be its fitted expected count, \(J_j=\partial\mu_j/\partial(p_1,p_2)\) and \(I=\sum_j J_j^\mathsf{T}J_j/\mu_j\). Expected Fisher information [Fisher1922] and first-order score propagation give
The fitted \(\mu_j\) supplies the same Poisson variance basis as the
influence row. Combining model-based covariance with observed zero-bin
variances can produce an invalid joint covariance. Singular information
fails with Tail-fit information matrix is singular; it does not declare
zero uncertainty. A non-positive or non-finite propagated tail-fit variance
also fails. Shared count components are checked for a valid joint
covariance at construction.
Deadtime-prepared groups retain their measured counting variance \(v_j\) instead of replacing it with corrected counts or fitted means. Fixed levels leave that variance unchanged; reference subtraction adds \(v_j+s^2v_{R,j}\); a range mean uses \(\sigma_\theta^2=\sum_W v_j/n_W^2\) and \(\kappa_j=v_j/n_W\) on its estimation window. For a tail fit, let \(L_j=(J_j I^{-1})_2/\mu_j\) be the rate estimator’s influence. Then
This propagates the declared count variance through the same fitted estimator; it does not change the count-loss model or add calibration uncertainty.
Binning, count-integral asymmetry and count-ratio α use this same propagation. For a differential mean asymmetry the weights are the per-bin asymmetry derivatives divided by the number of averaged bins. Forward and backward detector groups are treated as independent. Zero variance stays zero in the count domain; asymmetry formation assigns the fractional error sentinel 1 when its denominator or propagated variance is zero.
These are marginal, first-order errors. A shared level also correlates output bins: its covariance contribution within one group has rank at most two. Fitters receive marginal error bars, not that full covariance. Tail-fit linearisation assumes interior, identifiable fit parameters; near a non-negative parameter bound its errors need not have calibrated coverage, and marginal variances are not guaranteed conservative. Deadtime-corrected counts use retained measured-count variance with fixed coefficients and exposure; physical deadtime-induced inter-bin covariance is excluded. Rebinning an already reduced curve treats its points as independent and does not carry these shared components.
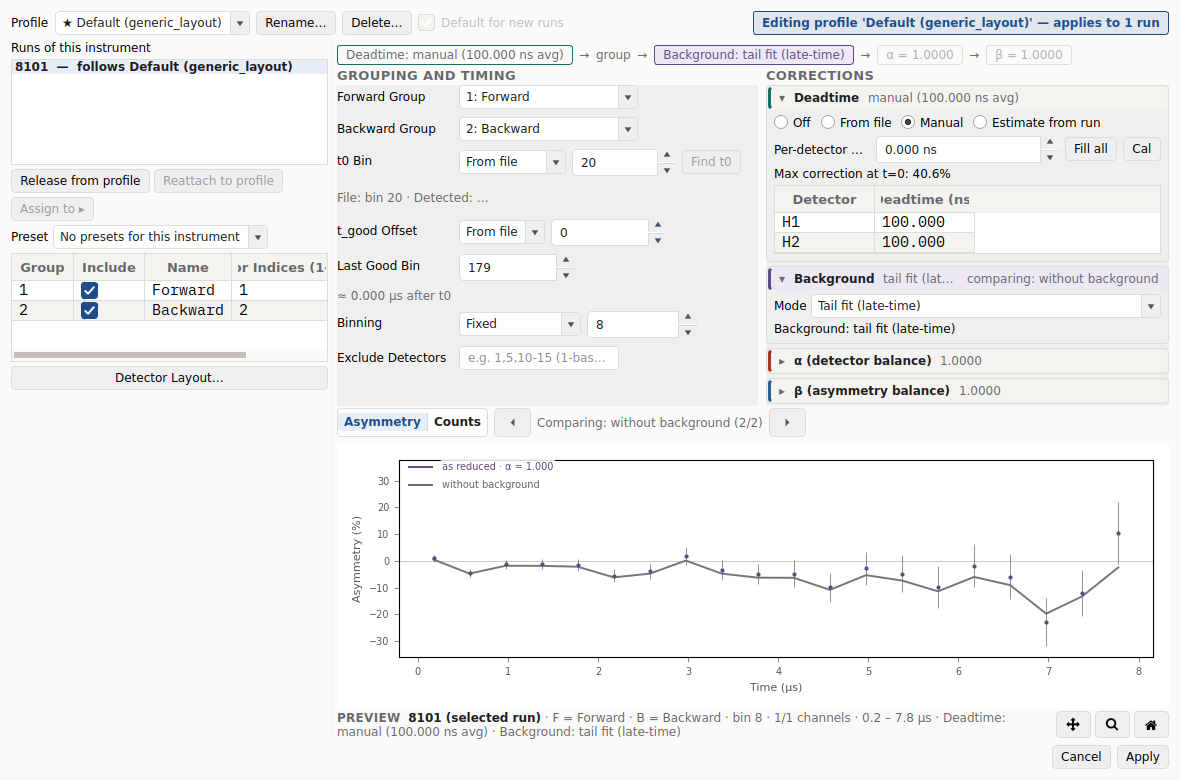
The asymmetry preview with manual deadtime coefficients of 0.1 µs, Tail fit background subtraction and fixed bunching. Error bars retain measured counting variance and include the level shared by each merged group of bins.
References
S. J. Blundell, R. De Renzi, T. Lancaster, and F. L. Pratt, Muon Spectroscopy: An Introduction (Oxford University Press, Oxford, 2022).
Suter and B. M. Wojek, Phys. Procedia 30, 69 (2012).
Pratt, Physica B 289–290, 710 (2000).
R. A. Fisher, Philos. Trans. R. Soc. A 222, 309–368 (1922). doi:10.1098/rsta.1922.0009.
S. Baker and R. D. Cousins, Nucl. Instrum. Methods 221, 437–442 (1984). doi:10.1016/0167-5087(84)90016-4.
musrfit tutorial: sample and holder signals, accompanying A. Suter and B. M. Wojek, Phys. Procedia 30, 69 (2012).