Data processing
F/B reduction and grouped count/spectral preparation resolve detector membership, alignment, and required output and active-background samples before deadtime availability and correction. Unused File coefficients and saturated observations outside that union do not affect the result. In scripted reduction, explicit time limits select final bin centres; only their contributing native bins enter correction, together with active estimator samples. Ordinary merging performs no spectral analysis. Grouped fits select merged-bin centres before resolving the contributing raw bins, including disjoint fit exclusions. Spectral preparation also retains active baseline, conditioning, phase, and background dependencies; a final display crop alone does not remove those observations. Shared preparation is bound to the requested cohort and actual sample/reference sources. See Required F/B deadtime observations for the workflow convention.
The processing tools in this chapter act on a loaded dataset before it reaches the fit engine: rebinning to trade time resolution for statistics, restricting the time range, applying the grouping defined in the Grouping dialog, estimating the calibration constant \(\alpha\), and the deadtime and background corrections for raw detector histograms. The order is deadtime, grouping, background subtraction, then asymmetry. The nonlinear deadtime inverse acts on each raw detector before any count subtraction.
The result’s captured effective recipe retains its resolved processing settings independently of later source edits. Export headers distinguish source settings captured for inspection from that result history; see Workflow conveniences and Count reduction and transformed signals.
Rebinning is the most common operation. Combining \(N\) adjacent bins reduces the per-bin uncertainty by \(\sqrt{N}\) at the cost of time resolution, so the new bin width should stay well below the period of any precession you intend to fit (rule of thumb: at least eight samples per cycle). ISIS NeXus files carry raw counts and may supply per-detector deadtime coefficients; enable File in the Grouping window to apply them. PSI BIN/MDU and ROOT can use separately calibrated coefficients in their whole-acquisition normalisation. See Detector Grouping and Layout for the correction’s domain and signed coefficients. Compare the raw and processed traces before fitting.
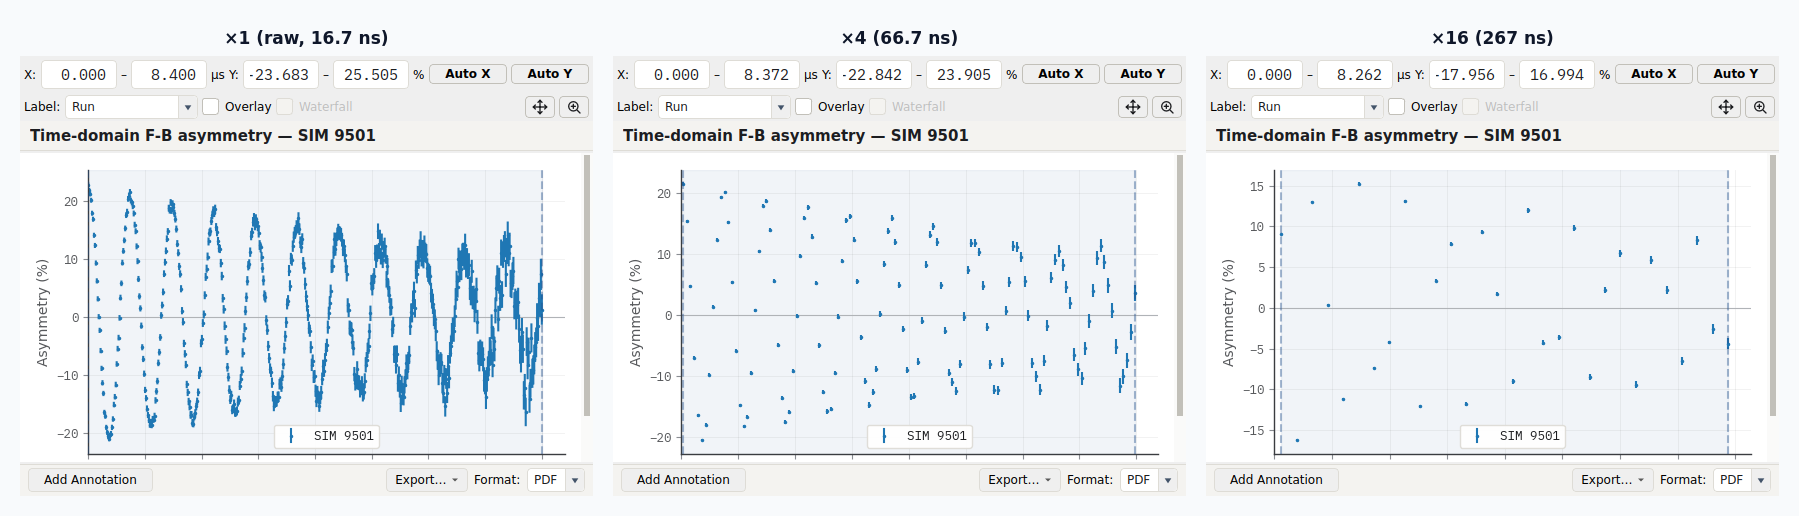
For an end-to-end example that exercises rebinning in context, see Temperature scan through a magnetic transition.
Rebinning
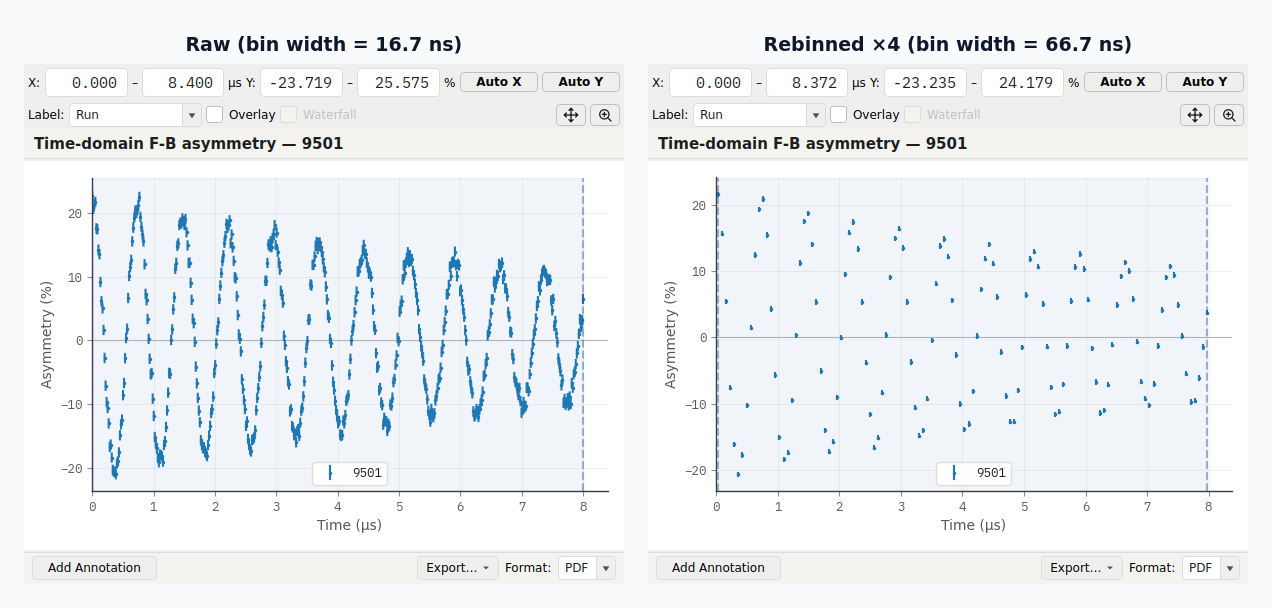
Same synthetic 100 G TF dataset before (left) and after (right) a ×4 bin merge. Combining N adjacent bins reduces the per-bin uncertainty by √N at the cost of time resolution — the precession is still clearly resolved at ×4 because the new bin width (~67 ns) is well below the precession period (~740 ns).
Reduce noise by combining adjacent time bins:
from asymmetry.core.transform.rebin import merge_curve_bins
import numpy as np

# Original data
time = np.linspace(0, 10, 1000)
asymmetry = np.random.randn(1000) * 0.01
error = np.ones(1000) * 0.01

# Rebin by factor of 10
t_rebinned, a_rebinned, e_rebinned = merge_curve_bins(time, asymmetry, error, factor=10)

print(f"Original: {len(time)} points")
print(f"Rebinned: {len(t_rebinned)} points")
# Errors are propagated: σ_new = √(Σσ²) / N
Time range selection
Extract a subset of the data:
dataset = load("data.nxs")

# Select data between 0.5 and 5.0 μs
subset = dataset.time_range(t_min=0.5, t_max=5.0)

print(f"Original: {dataset.n_points} points")
print(f"Subset: {subset.n_points} points")
Grouping histograms
Combine detector histograms into logical groups:
from asymmetry.core.data import Histogram
from asymmetry.core.transform import apply_grouping
import numpy as np

# Synthetic detector histograms for the example
histograms = [Histogram(counts=np.random.poisson(1000, 200), bin_width=0.01) for _ in range(8)]

# Define grouping: forward and backward detectors
grouping = {
    "forward": [0, 1, 2, 3],
    "backward": [4, 5, 6, 7]
}

forward_counts = apply_grouping(histograms, grouping["forward"])
backward_counts = apply_grouping(histograms, grouping["backward"])
In the GUI, grouping is configured from the Grouping dialog. For supported instrument layouts, including ISIS HiFi/MuSR/EMU and the PSI FLAME and HAL-9500 spectrometers, the Detector Layout… editor provides an interactive detector schematic, preset groupings, and named group slots that are saved with project state as grouping profiles.
For detector-by-detector instrument layouts and grouping workflows, see Detector Grouping and Layout.
Alpha estimation and asymmetry
Estimate alpha from a good-bin range, then compute asymmetry and errors.
from asymmetry.core.transform import compute_asymmetry, estimate_alpha

alpha = estimate_alpha(
    forward_counts,
    backward_counts,
    first_good_bin=5,
    last_good_bin=150,
)
asymmetry, error = compute_asymmetry(forward_counts, backward_counts, alpha=alpha)
Asymmetry definition and error model
Asymmetry uses the standard pair formula:
where \(F\) and \(B\) are grouped forward/backward counts. Asymmetry’s alpha convention applies \(\alpha\) to the backward group. This convention is retained consistently in the GUI, loaders, grouping tools, and fitting inputs, even when comparing against packages that place \(\alpha\) on the forward group.
In the asymmetry expression, Forward and Backward are defined relative to the initial muon spin direction. PSI detector labels and FLAME detector layout presets use the PSI instrument convention, where forward/backward are defined relative to the beam direction. For PSI data, the Grouping dialog therefore swaps the analysis dropdown defaults: the analysis Forward Group is the detector-layout Backward group, and the analysis Backward Group is the detector-layout Forward group. ISIS data keep the instrument forward/backward convention already used by their detector layouts.
Asymmetry and uncertainty handling uses the following convention:
If \(F + \alpha B = 0\), asymmetry is set to 0 for that bin.
The default uncertainty for that bin is 1.0 (fractional), i.e. 100% in the GUI percentage display.
For independent raw Poisson counts, a non-zero denominator and positive propagated variance, the uncertainty at β = 1 is:
In low-count late-time tails, this naturally produces large fluctuations and large uncertainties.
With independent count variances \(v_F\) and \(v_B\), the same ratio derivatives give
Deadtime correction changes the count values while retaining measured counting variance, or explicitly supplied independent variance. Coefficients and frame exposure are fixed; their uncertainty and physical deadtime-induced correlations are excluded. See Detector Grouping and Layout for the convention and limitations.
Background is subtracted from the grouped count histograms before the pair formula is evaluated. The value retains the same alpha convention. Error propagation uses raw independent count variances, the shared background-level variance and its covariance with any overlapping signal bins. A merged block of m bins carries the shared level variance multiplied by m². Fixed levels are exact by declaration, and independent background-run spectra add their frame-scaled variances. See Uncertainty of a subtracted background for the formula and the tail-fit approximation. Degenerate first-order asymmetry variance uses the unit error sentinel.
In vector-polarisation mode, axis-specific alpha values (alpha_x,
alpha_y, alpha_z) are used for P_x, P_y, and P_z
respectively. See Vector-polarisation mode for setup and UI behaviour.
Co-adding datasets
Average multiple datasets with proper error propagation:
import numpy as np
from asymmetry.core.io import load

# Load multiple datasets
datasets = [load(f"run_{i}.nxs") for i in range(1, 4)]

# Ensure same time grid (or interpolate if needed)
time_grid = datasets[0].time

asymmetries = [ds.asymmetry for ds in datasets]
errors = [ds.error for ds in datasets]

# Average
avg_asymmetry = np.mean(asymmetries, axis=0)

# Error propagation: σ_avg = √(Σσ²) / N
avg_error = np.sqrt(np.sum([e**2 for e in errors], axis=0)) / len(datasets)
The GUI provides automatic co-adding via the context menu: select 2+ datasets, right-click, and choose “Co-add Selected” to combine them with proper error propagation.
In the GUI, co-add is intentionally strict:
every selected dataset must already have equivalent grouping settings,
the resulting combined dataset mirrors that shared grouping state.
When you later edit grouping on a combined dataset, Asymmetry applies the change to the hidden source datasets and rebuilds the combined row from those updated sources. Separating the combined dataset restores those source runs with the same grouping that was active on the combined entry.
Windowing for Fourier analysis
Apply window functions before FFT:
from asymmetry.core.fourier.window import apply_window

dataset = load("data.nxs")

# Apply Hann window
windowed_data = apply_window(dataset.asymmetry, window_type="hann")

# Available windows: 'hann', 'hamming', 'blackman', 'bartlett'
Runnable example
See examples/transform_workflow.py for a complete executable script.