Histogram binning
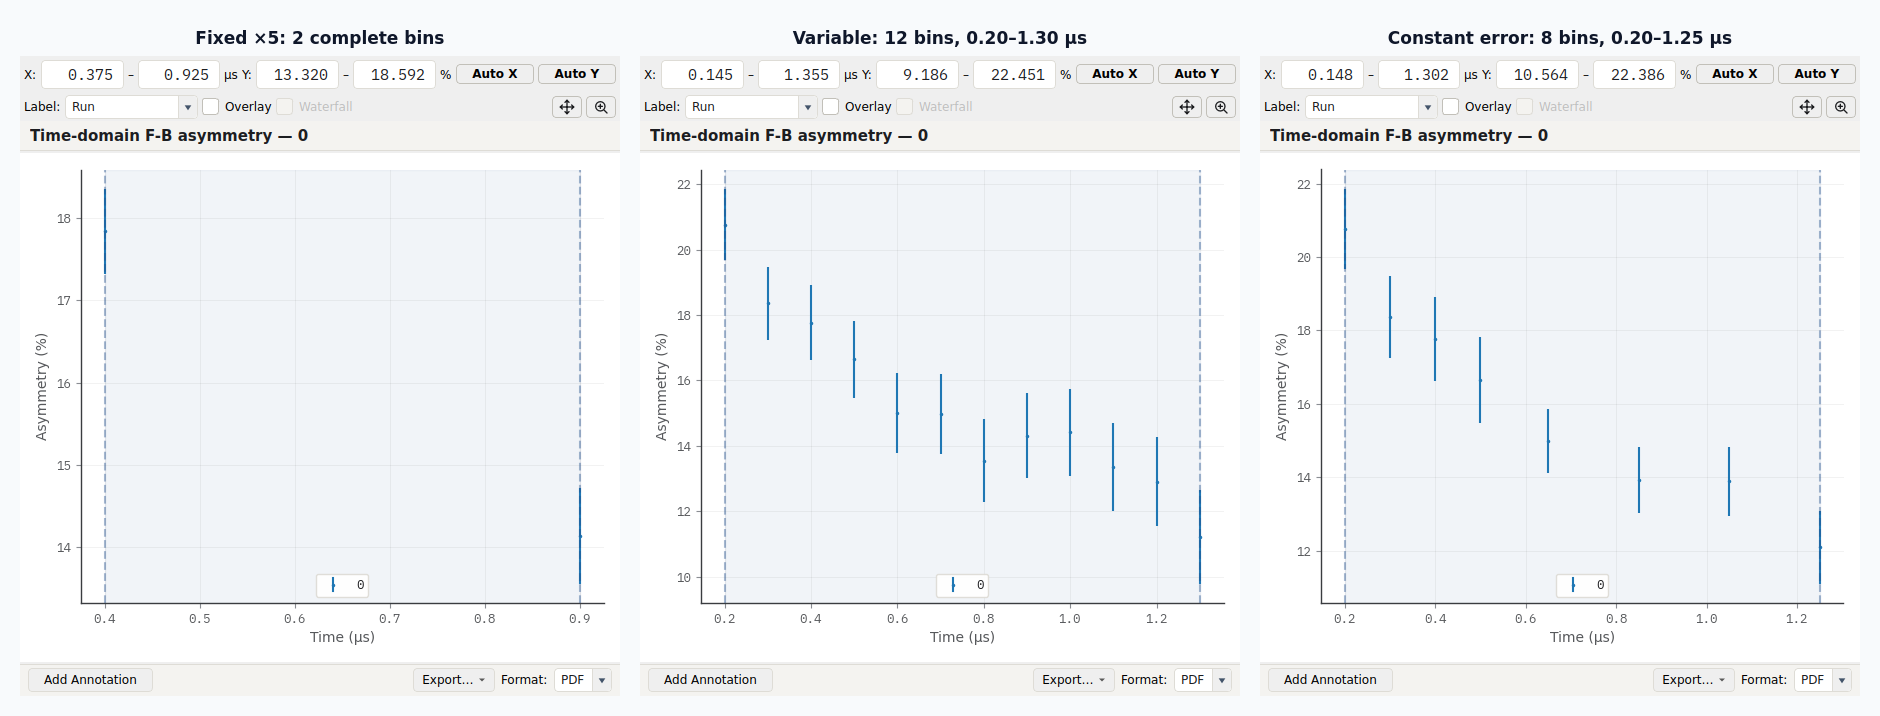
Counts arrive in bins of the TDC resolution (16 ns at ISIS, sub-ns at continuous sources), far finer than most physics requires. Because the muon ensemble decays as \(e^{-t/\tau_\mu}\), the Poisson error per raw bin grows as \(e^{t/2\tau_\mu}\) — the signal-to-noise halves roughly every 3 μs — so a single binning choice cannot serve both the densely-sampled early times and the count-starved tail. Three modes are offered in the grouping dialog’s Binning control:
Mode |
Output bin width |
|---|---|
Fixed |
bunching factor × raw width, everywhere |
Variable |
grows exponentially from Initial bin at t = 0 to Bin at 10 μs |
Constant error |
grows as \(e^{t/\tau_\mu}\) from Initial bin — approximately equal counts for slowly varying signals |
The Binning selector and fixed factor share one row. Variable and Constant error show Initial bin on an indented row below; Variable also shows Bin at 10 µs on the following indented row. The extra fields do not widen the settings column.
All three are display/fit-input transformations: the raw histograms are never modified, and changing mode (or any width) is always reversible. In all modes the counts are summed onto the output bins and the asymmetry formed per output bin — at late times the raw bins hold zero counts, where an asymmetry ratio per raw bin is undefined while summed raw independent counts have additive Poisson variance. Deadtime-corrected counts retain measured counting variance through the same bin sums; they are not treated as fresh Poisson observations. Shared-background covariance is propagated separately, including overlap with the estimation window.
Target widths and actual coordinates
Variable and Constant error evaluate their target width at the actual left edge of each output bin: the first contributing acquisition-bin centre minus half the native width. The time is relative to the selected exact t0, including its fractional-bin residual. Negative left-edge times use the width at zero. The target is rounded to the nearest positive whole number of native bins, with at least one bin. Half-integer targets round upward (half-up). The comparison uses the fractional part of the floating-point width ratio, without a tolerance that moves neighbouring representable values into a tie. This tie convention is an Asymmetry choice.
The realised width can therefore be smaller or larger than the target. For example, a 0.12 μs target on a 0.1 μs acquisition grid selects one observation; a 0.25 μs target selects three. No acquisition bin is split or interpolated. The timestamp is the midpoint of the actual first and last contributing native centres, never the midpoint of a nominal requested interval.
The selected good-bin window is inclusive. Base nonuniform binning retains all its observations, including a partial final bin. Fixed drops an incomplete raw group and retains every complete group. An additional Bunch: merge also drops its incomplete final group, even when its base mode is nonuniform.
Display bunching
Scripted TF calibration has its own CalibrationOptions.count_packing
request, independent of ReductionSettings.rebin and display merging.
Omission inherits the source’s fixed bunching factor; an explicit positive
integer replaces it, without composition. See Explicit workflow and CLI calibration
for the count-sum, trailing-bin, and time-window semantics and a scripting example.
The main toolbar’s Bunch: control merges that many recorded output bins.
Its tooltip is Merge this many recorded output bins. The grouping dialog
sets the base binning; the toolbar composes with it. Fixed factor 4 and
Bunch: 2 therefore combine eight acquisition bins per displayed point.
The display factor is stored independently in each saved view mode.
Large inputs show Recording histogram observation… with Cancel while
the resolved operation context is captured; Cancel stops that preparation.
For histogram-backed F–B asymmetry, Fixed, Variable and Constant error all merge counts and their shared-background uncertainty before forming the ratio. G+R pools prepared counts and variances before background, binning, and one ratio. G−R bins each separately prepared set on common native support, then subtracts their asymmetries with independent marginal variances added. The Groups and Raw counts views sum the corresponding count bins. A merge larger than the record leaves no complete output point. Curves without a resolved histogram observation and rotated projections use the curve-bin mean described below.
Direct reduction, the workflow, CLI, and histogram toolbar honour the same authored merge without a spectral peak veto. This permits deliberate averaging of a known fast line. Inspect native-resolution data when choosing the width; FFT and MaxEnt sampling checks apply when those operations are requested.
Good-bin window
The good-bin endpoints are inclusive, zero-based indices into the aligned
grouped counts. Both endpoints must be integers with
0 <= first_good_bin <= last_good_bin < number_of_bins. An absent first
endpoint selects bin 0; an absent last endpoint selects the final bin.
The selected window is applied before any binning mode.
A reversed window raises ValueError with, for example,
good-bin window [7, 3] is reversed. An endpoint beyond a ten-bin record
raises good-bin window [3, 100] is outside 10 bins. Invalid windows are
rejected rather than clamped or replaced by the full record. A saved project
containing such a window still loads; reduction of the affected run raises
the error so the window can be corrected.
Forward and backward arrays must have equal one-dimensional shape. A
mismatch raises count arrays must have equal shape. Supplied count
variances must match that shape and be finite and non-negative; the
acquisition-bin width must be finite and positive. File-derived profile
windows use these same checks. Projects retain saved invalid windows when
loaded; reducing an affected dataset raises the named window error.
Uncertainty of merged counts
An estimated background level is shared by every raw bin. Merging m bins therefore contributes m² times its level variance, together with the covariance term for overlap with its estimation window. All binning modes propagate these terms before forming the asymmetry ratio. Summing per-bin error squares alone loses the shared contribution. See Uncertainty of a subtracted background for the complete noise model.
Reduced-curve errors remain conditional on the applied alpha/beta, even when the calibration record carries errors and covariance. Shared correction terms in marginal point errors do not make an ordinary fit a correlated likelihood; see Calibration conditioning and Errors.
Fixed
The default. Every output bin merges the same number of raw bins.
When to use this. Oscillating (TF) data, Fourier analysis, and MaxEnt — anything that needs uniform time sampling. Keep the bunching factor small enough that the highest frequency of interest stays below the Nyquist limit \(f_c = 1/(2\Delta t)\); rebinning is a low-pass filter, which can also be used deliberately to suppress an unwanted high-frequency component.
Variable
Width grows smoothly as
set by the width at t = 0 and the width at 10 μs (WiMDA’s two-knob convention; defaults 0.08 μs and 0.25 μs).
When to use this. Relaxation data where the early-time shape matters (a fast front, a Kubo–Toyabe dip) but the tail evolves slowly — fine bins where the physics is fast, coarse bins where only the level matters. The growth is gentler than constant-error mode, so it preserves more late-time structure at the cost of growing error bars.
Constant error
Width grows at exactly the muon decay rate,
so short bins contain approximately equal expected counts under pure muon decay. Asymmetry errors are approximately flat when polarisation varies slowly; finite widths, rounding, background, and corrections can change that. One knob: the initial width sets the statistics level of every bin.
When to use this. Weak, slow relaxation followed to long times (20–32 μs pulsed-source work): the late-time statistics are easier to inspect. Two caveats: late output bins become microseconds wide, so any structure faster than the local width is averaged away — check with fixed binning first that nothing oscillates; and the final bin, truncated by the good-data window, carries fewer counts than the rest.
Rebinning programmatically
A BinningSpec selects the mode,
fixed factor and non-fixed widths. Its merge combines that many output
bins at the count level; a fixed factor of 4 with merge 2 equals factor 8.
An incomplete final group of output bins is dropped. Reduction records the
spec it used.
Cached reductions and wizard analyses carry the numerical binning identity. An analysis from a different policy is not reused as current. Saved fit and calibration results keep their recorded values; opening a project does not run a new fit.
from dataclasses import replace
from asymmetry.core.transform import binning_spec, reduce_grouped_asymmetry
from asymmetry.core.transform import correction_flags_from_grouping

grouping = run.grouping
bins = replace(binning_spec(grouping), merge=4)
flags = correction_flags_from_grouping(grouping)
result = reduce_grouped_asymmetry(
    histograms=run.histograms, grouping=grouping, binning=bins,
    forward_idx=[0], backward_idx=[1], alpha=grouping["alpha"],
    use_deadtime=flags.use_deadtime, deadtime_mode=flags.deadtime_mode,
    use_background=flags.use_background, metadata=run.metadata,
)
Choose the zero-based detector indices for the required pair. The returned
asymmetry and errors are in percent. The workflow and CLI reduce --rebin
use the same count-level merge. For period sums and differences,
reduce_period_asymmetry() prepares
common observed native support before binning. G+R forms one ratio from pooled
prepared counts with background once; G−R differences separately reduced sets.
Incompatible widths or empty common support make that combination unavailable.
To replay the selected pair, calibration, period operation, corrections, and
base binning from an explicitly prepared run, use
prepare_histogram_asymmetry():
from asymmetry.core.transform.preparation import prepare_histogram_asymmetry

result = prepare_histogram_asymmetry(
    run, merge=4, facility=None, reference=None,
)
Here facility=None uses the existing facility resolution from the run’s
metadata and grouping; an empty string explicitly disables facility-specific
conventions. reference=None supplies no reference acquisition.
For reference subtraction, supply a resolved BackgroundReference with its own
timing and scaling. The operation adapts the reference exposure for each selected
period. It reads complete good-bin support from the run; it does not infer how an
existing curve was cropped, rotated, or merged. An extra merge is relative to
the run’s base output bins. This is the same numerical operation used by the
histogram toolbar. The API is synchronous; interactive applications run expensive
preparation in their task infrastructure and can supply cancel_check.
Absent binning keys use fixed factor 1 and widths 0.08/0.25 µs. Present invalid
values raise errors, for example
binning mode 'Varaible' is not one of fixed, variable, constant_error. or
bunching factor must be an integer >= 1; got 'abc'. Both widths must be
finite and positive. A saved invalid grouping payload can be loaded; consuming
it for a profile or reduction raises the named error. A non-positive width raises, for example,
bin0_us must be finite and > 0; got -1.
Curves without raw counts
MuonDataset.merge_curve_bins
and merge_curve_bins() compute the mean
of consecutive curve points. The dataset method propagates retained counting
influences through the mean, preserving known shared acquisition and
background-estimator noise. The array helper assumes independent inputs.
Curve merging gives different values and uncertainties from counts-first
reduction for sparse or background-subtracted counts. Workdir-stored curves,
rotated-frame projections and unresolved custom/historical curves use this
explicitly named curve operation.
Single/global wizard merging instead uses counts-first preparation when the
actual histogram observation is recorded. Attached raw counts alone do not
establish that context. Cropping retains the selected output-bin membership
before a subsequent merge; base, toolbar, and wizard factors compose once.
coarse = dataset.merge_curve_bins(8)
A factor of one returns a copy. A trailing partial group is dropped. The per-point uncertainty for independent inputs without retained noise is \(\sqrt{\sum\sigma^2}/factor\). Unknown correlations cannot be recovered from marginal errors alone. Values and uncertainties retain the input’s fraction or percent scale, and timestamps are averaged. The raw acquisition record remains unchanged.
Notes
Fourier and MaxEnt analyses require uniform sampling. Count fitting retains its explicit fixed packing, even for a shorter selected window. If no complete fit bin remains, the requested fit reports no usable input before preparing unused corrections; see Count-domain fitting (α calibration & single histograms). Curve fits evaluate the model at the prepared point timestamps, with each point’s own error. This centre-point approximation does not account for signal averaging within wide bins: rapid oscillations can lose amplitude and acquire a phase shift. Nyquist is a sampling limit, not a guarantee of negligible bin averaging. Nonuniform weights alone do not make the point-model expectation exact.
Compared with other programs
WiMDA 1.326 offers Variable and Constant error width controls. On a controlled 0.1 μs acquisition grid with initial width 0.12 μs and Variable width at 10 μs of 0.25 μs, nearest-width selection at the actual left edge matches all eight Constant error point values and eleven shared Variable point values within 0.0005 percentage points (ASCII export precision). This is a bounded membership comparison, not universal output equality or a measurement of WiMDA’s tie policy.
The recorded WiMDA timestamps and terminal support differ from Asymmetry’s actual contributing-bin midpoints and inclusive nonuniform tail. Asymmetry uses the literal 10 μs Variable law above. The value-only control does not identify WiMDA’s internal growth approximation or establish the same positive-, sparse-, or corrected-count error treatment.
musrfit 1.12.1 (revision 708f777b, ROOT 6.40.04) uses integer packing for
ordinary count/asymmetry fits; this is not the same two-knob nonuniform law.
Matched interior count sums and means of native centre timestamps agree in
controlled packing cases. Terminal selection and integer-t0 versus exact-t0
coordinates must be matched separately; an observed terminal omission in that
build is not reproduced by Asymmetry. See the musrfit packing guide.
In Mantid, histogram Rebunch combines
whole bins and retains a partial final group; Rebin can redistribute
fractional overlaps and offers FullBinsOnly. Histogram-centre coordinates
identify the actual retained edges. These are distinct operations, not the
same Variable/Constant error controls. This comparison uses the documented
algorithms (reviewed Mantid 6.16 development); no matched native Variable or
Constant error comparison is claimed. The recorded fixed-packing/history control
in Asymmetry in the μSR software landscape has a different scope. Fit defaults to
CentrePoint and separately offers histogram evaluation for supported models.
The controls establish their stated count/bin membership, rather than identical spectral or no-bin diagnostics across these programs. Asymmetry honours authored binning without a spectral veto, retaining sampling guards on actual FFT requests.
Asymmetry also checks positive finite native widths, compatible count/variance arrays, and valid selected windows at their input boundaries. A malformed request raises a contextual error; these checks do not impose new facility-file admission rules. See Binning and timestamps for the comparison scope.
Gaussian fitting support
Counts-first preparation retains every contributing count, including bins whose individual ratio is undefined or has zero first-order variance. Usability is classified on each final requested output bin. Cropping retains the selected bin membership before another merge; it does not remove unusable observations before summing their counts. The full output time grid is retained for spectral operations. Gaussian fitting alone selects the usable observations, as described in Undefined and degenerate bins.
References
S. J. Blundell, R. De Renzi, T. Lancaster, and F. L. Pratt, Muon Spectroscopy: An Introduction (Oxford University Press, Oxford, 2022) — rebinning schemes and counting statistics.
Pratt, Physica B 289–290, 710 (2000).