Global fit wizard
The current ordinary model’s fixed time response applies throughout screening, candidates, and phase application. An analysis with a different response cannot be applied to the current setup. Reopen the wizard and analyse again after changing Time response; separation remains supplied context, outside the sharing and candidate tables.
The global fit wizard is the analogue of Fit wizard for an ordered
series of runs — a longitudinal-field decoupling series, a temperature scan, a
fallback run-order sweep — where the experiment is set up so that one common
composite model should describe every dataset, with each parameter either
shared globally across the series or free per run. The textbook use is a
longitudinal-field (LF) decoupling series where the field-distribution width
\(\Delta\) is shared across runs and the applied field \(B_L\) is
local to each run (LF decoupling and static-vs-dynamic field distributions), but the same
workflow applies to any ordered sweep you expect a single model family to fit
— an Oscillatory * Exponential + Constant precession signal followed
through one magnetic phase, say. Where the model qualitatively changes across
the series — a paramagnetic component appearing through a transition,
oscillations collapsing into a relaxation — the wizard partitions the series
into phases at the transition and fits each phase under its own template
and global/local assignment, instead of forcing one model across a break it
was never going to describe; see Phases: transitions and the penalty path
below.
The wizard is a five-step window, Scope → Screen → Compare → Phases → Apply, laid out as a stepper across the top so that what each stage does, and what comes next, is always in view. Scope reviews the series and chooses which model families to consider; Screen fits each family to every run independently and ranks the families; Compare holds the coupled global fits of the families you shortlisted, one row per sharing pattern, and sets two of them side by side; Phases partitions the series at a transition when the model changes along it; and Apply reviews exactly what will be handed to the global-fit tab before it is handed over. It differs from the single-spectrum wizard in one important way: it drives a two-stage screening-then-optimisation workflow rather than a single recommendation, and you choose on the Screen step which families earn the expensive coupled fits.
The reason for the two stages is cost. Screening builds a ranked table from independent single-dataset fits across the whole series — fast, and enough to see at a glance which candidate families look promising. The coupled global optimisation, which actually enforces the shared-parameter constraints, then runs only for the families you tick. Keeping the stages on separate steps makes it obvious which results are still only single-fit screening and which have been optimised under parameter sharing. The coupled step is where the wizard pays for itself: sharing a parameter usually tightens the uncertainties on the common quantities (typically the field-distribution widths and amplitudes) below what any single-run fit can achieve, and it cleans up the per-run trends in the local parameters by suppressing the noise that arises when each run independently re-optimises an otherwise common quantity. It is also a useful cross-check on a series you have already fit by hand — the screening stage should recover the same model family you converged on.
What a series fit is for is usually the trend: parameters that can be followed along the temperature or field axis, with error bars small against their variation. The best fit in the statistical sense is often not that fit. With thousands of points per run, freeing a parameter on every run almost always lowers an information criterion, and the parameters then trade against each other run by run — an amplitude against a background, an amplitude against a rate — and stop being trackable. By default the wizard therefore recommends the sharing pattern whose per-run parameters trend best among the patterns that fit adequately (see What “trends best” and “fits adequately” mean). The information-criterion ranking remains available as the other objective; the Recommend switch on the Scope step chooses between them.
Once the wizard has applied a model, Fitting engine covers running and refining the coupled fit and Assessing a Fit covers judging the result. For the single-spectrum version of the same guided approach, see Fit wizard.
The guided journey
Open the wizard from the global-fit tab with a run series selected. It uses the datasets, bunching, and fit range the tab is using at the time you open it, so candidates are compared on exactly the points a manual global fit would use. Completed wizard states are cached with the tab context and persisted in project files, so reopening the wizard on an unchanged series skips straight to the last result — the Compare step when coupled fits have been optimised, the Screen step otherwise — rather than rebuilding an unchanged screening table or rerunning finished optimisations.
Each step in the stepper shows its number, its title, and a one-line summary of where it stands, and its disc marks its state:
done — a green ✓: the step’s work is finished;
current — a filled disc on a highlighted tile: the step on screen;
ready — an outlined disc: the step’s inputs exist and it has not run (Compare reads “Next: optimise the shortlist” once screening is done);
stale — an amber “!”: the step’s results no longer match the scope, or were optimised for the other objective (see Scope: review the series and choose scope below);
running — a turning arc: an analysis for this step is in progress (“Screening…”, “Optimising the shortlist…”, or “Optimising phases…”);
skipped — a dashed disc: the step does not apply to this series (Phases reads “No transition found”).
Done, stale, ready, and running steps are clickable, so you can move back to Scope to widen the search, or leave a long run and read an earlier step while it goes; a pending step waits for its inputs. The summaries follow the analysis: Scope names the field direction and the number of models (“Longitudinal · 31 models”), Screen names the leading family (”Title leads”), Compare counts what was optimised (“2 sharing ladders climbed”, or “8 role splits optimised” under the statistical objective), Phases states the selected partition (“1 transition · 21 ± 3 K”), and Apply names what it holds (“Pick a model first”, “Ready: title”, and “Applied: title” once it is applied).
An analysis shows its progress inside the step it feeds: screening in Screen, the coupled optimisation of the shortlist in Compare, and the per-phase optimisation in Phases. The block carries a bold header, a short decision trail whose steps light up as the core reports progress, a collapsed Live log that captures every progress message in full, and Cancel, which stops a long run cleanly and returns you to the step you started it from. When the run finishes, the header, the trail, and Cancel go and the block collapses to a Run log disclosure that keeps the log. You can work in the main window while the analysis runs; if it ends up in front of the wizard, the wizard returns to the front by itself as soon as the analysis finishes.
Scope: review the series and choose scope
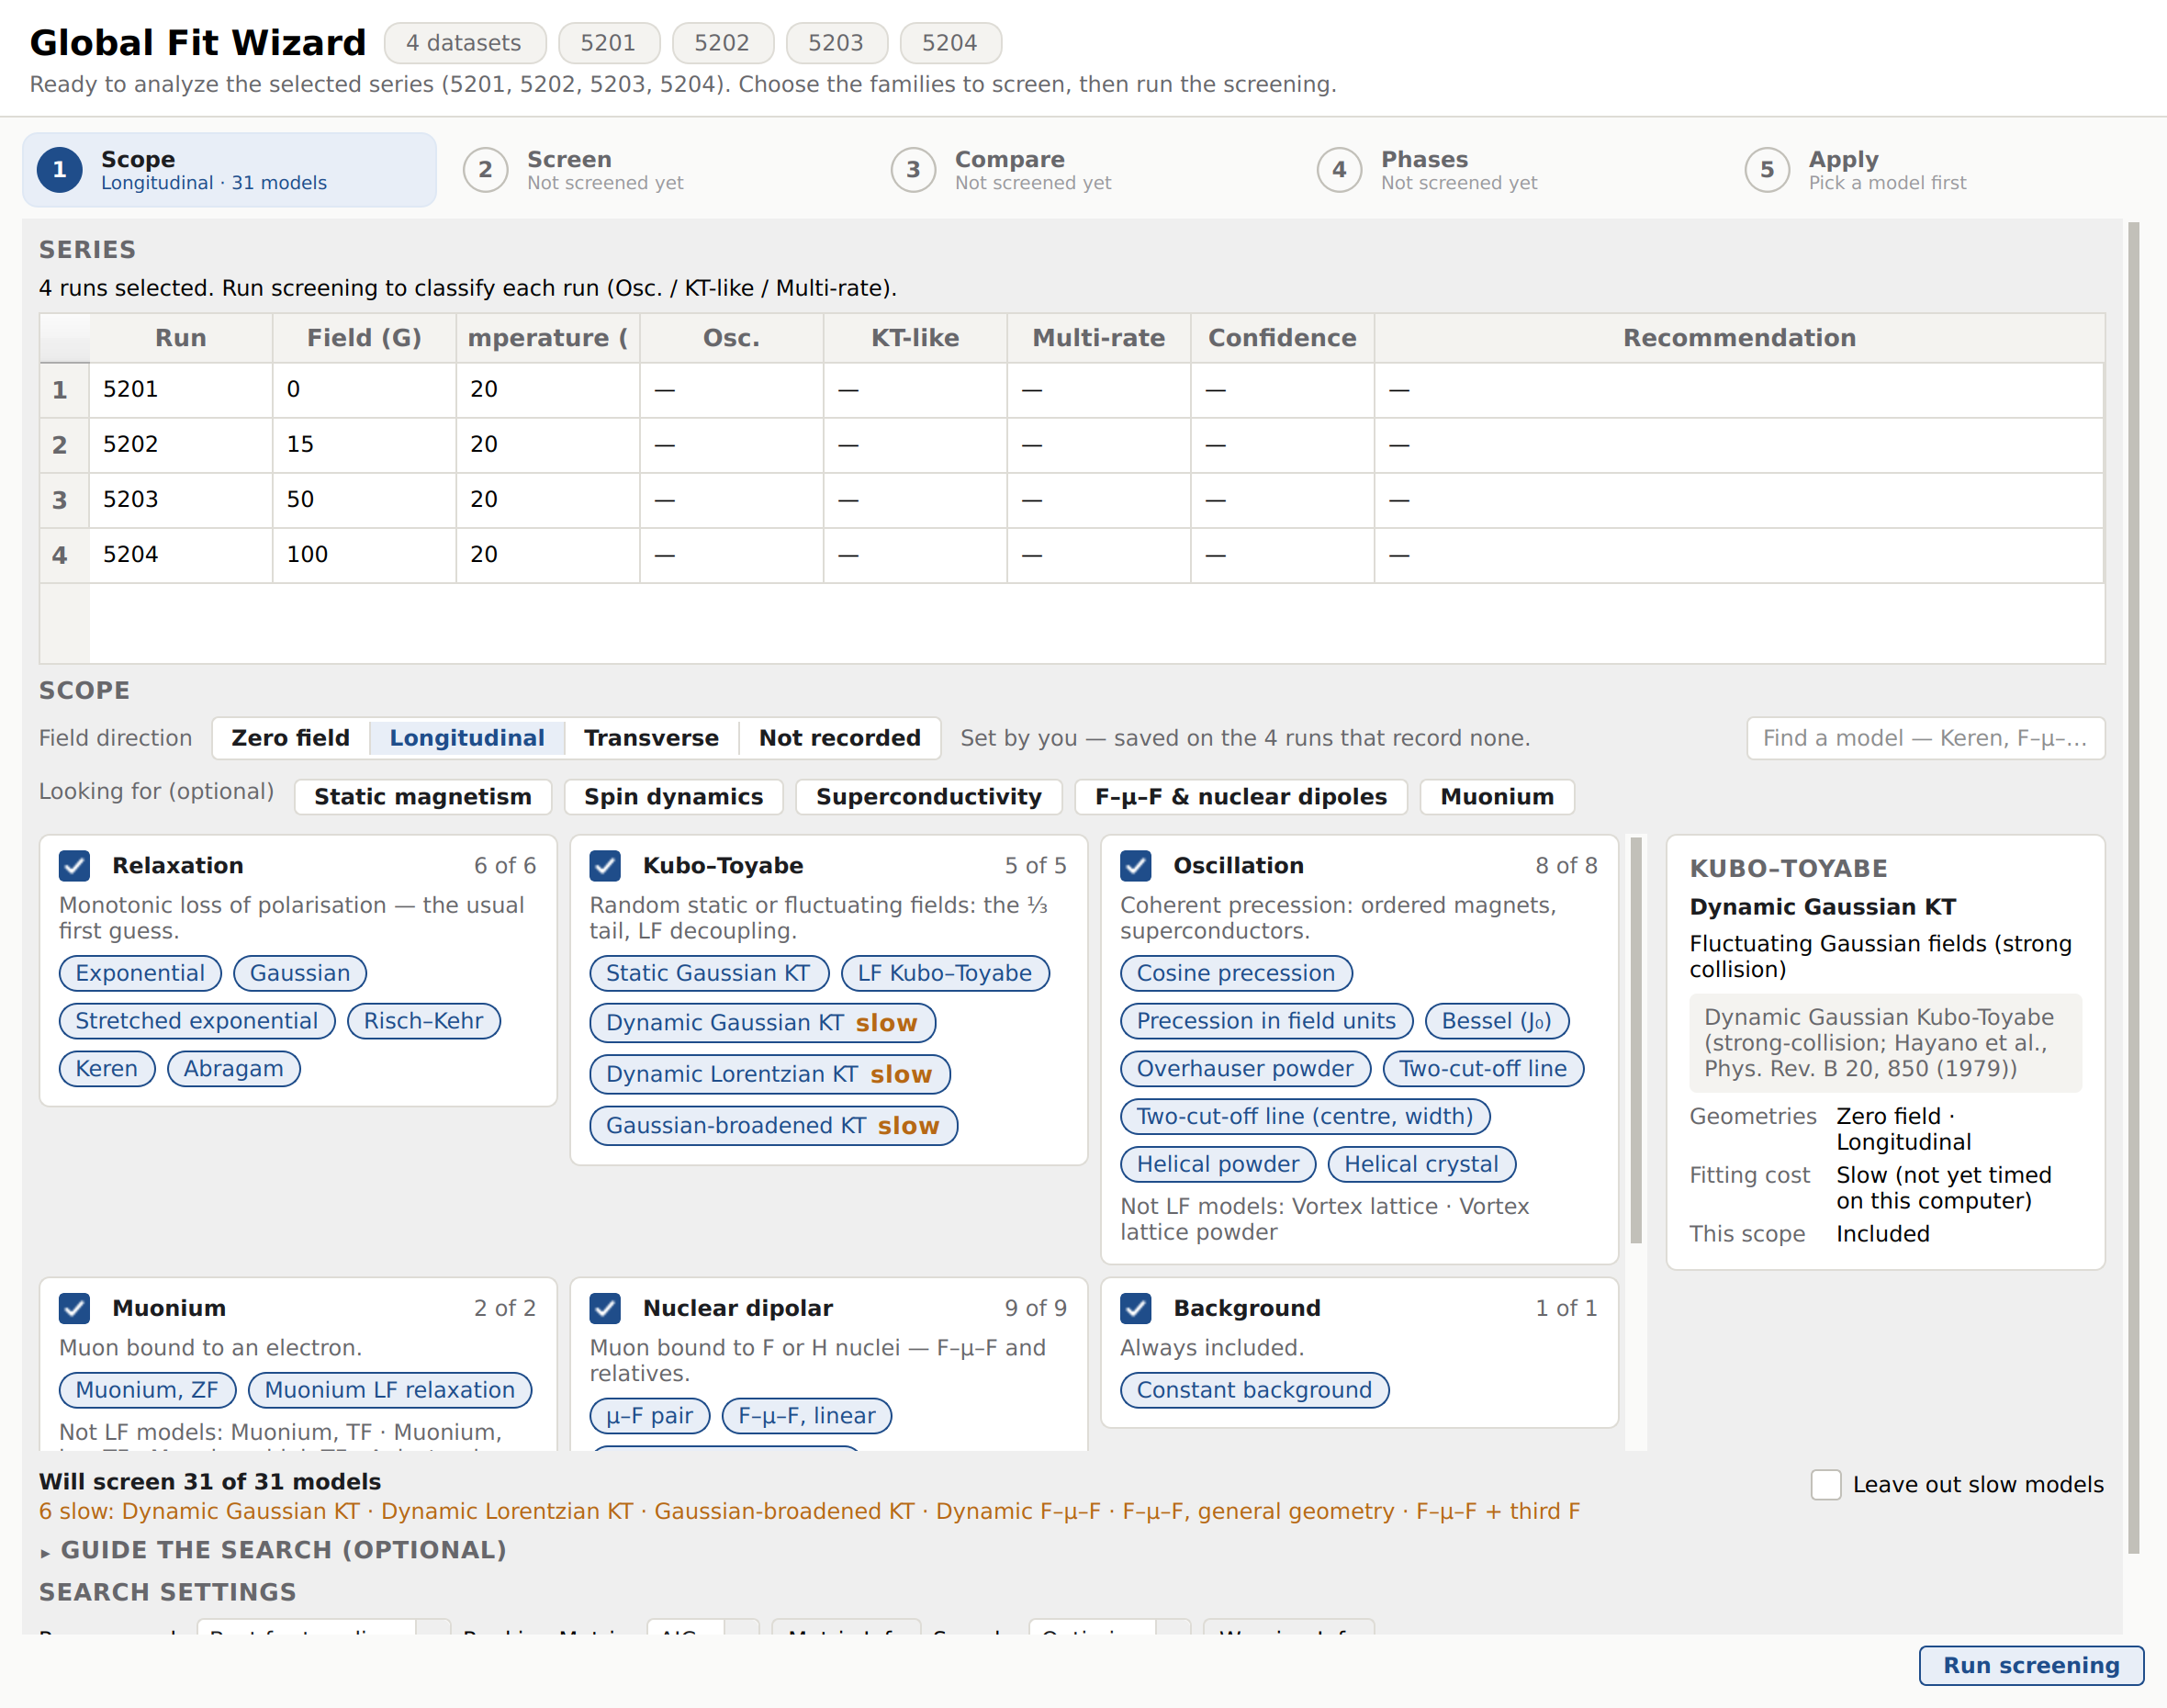
The Scope step on a four-field Ag longitudinal-field decoupling series. The
Series table lists each run as soon as the context arrives; the classification
columns stay — until screening runs. Below it, the Scope section holds the
model family picker: the files record no field direction, so the series was
answered “Longitudinal”, and because run 5201 sits at 0 G the zero-field
models stay in the screen too. Beneath the picker are the collapsed “Guide the
search (optional)” section, the search settings, and the primary “Run
screening” button.
The Series table lists one row per dataset with its Run,
Field (G), and Temperature (K) filled immediately — no need to run
screening first. Three further columns summarise the same deterministic
fingerprint hints the single-spectrum wizard uses — whether oscillations look
resolved (Osc.), whether the shape looks Kubo-Toyabe-like (KT-like),
and whether the envelope suggests more than one relaxation rate
(Multi-rate) — alongside a per-run Confidence grade and
Recommendation. These are computed during screening, so they read —
until you run it; afterwards the rows reorder to follow the inferred sweep axis.
The wizard infers one dominant sweep axis from the run metadata: a field sweep, a temperature sweep, or a fallback run-order series when neither field nor temperature varies. A temperature scan through a single magnetic phase is handled exactly like the field series shown here, with Temperature (K) as the axis. If both field and temperature vary materially, the wizard reports that it cannot make an automatic recommendation for that mixed grid.
The Scope section holds the model family picker, the same control the single-spectrum wizard shows on its welcome page; Choosing which models to screen describes it in full. From top to bottom it asks for the Field direction, offers the Looking for (optional) physics chips, lays out one card per model family with a pill per model, and ends with a footer that counts the models to be screened (“Will screen N of M models”), names the slow ones, and offers Leave out slow models. It is resolved over the whole series, so a model is offered when it applies to any run — a temperature series crossing a transition keeps both its ordered-state and paramagnetic families. A slow tag marks the models whose screening fits are expected to take more than 5 s per run on this computer at the series’ median run length (see which models are slow). Screening a series times its fits as well, so a series analysis refines the estimates for both wizards.
The direction row matters most on a series. When the files record no direction, every geometry is screened, which on a long series is the slow path. Answering the question saves the answer on every run whose file records none (“Set by you — saved on the 4 runs that record none.”), keeps it in the project, and never overrides a direction a file records; when some files record one, the note says how many do not, and when all of them do, the row reads “Recorded: …” instead. On an LF decoupling series like the one above, a Longitudinal answer also lets the wizard hold \(B_L\) at each run’s recorded field rather than fitting it (see The applied field is not a fitted parameter).
Changing the picker, including the direction, after screening has run marks the results stale. An amber banner reads “Scope changed since the last analysis, so these results are stale. Run screening again to refresh them.”, and the stepper marks Screen, Compare, and Phases with “!”. Their results stay viewable — click a stale step to read it — but Optimise N families → and the Transitions actions wait until Run screening refreshes them. A change made while an analysis is running cancels that run and discards its result. Changing the scope back to the one the results were screened under and pressing Run screening restores them at once, without screening again. Changing the Ranking Metric re-ranks the existing results in place and needs no new screening.
The collapsed Guide the search (optional) section is where you tell the wizard what you already know physically before the expensive search starts. Leave it closed and the defaults apply; open it to review the combined parameter list and set an expected role and bounds for each parameter:
amplitude-like parameters start as
Globalwith positive boundsrate-like parameters start as
Localwith positive boundsbackground-like terms stay
Globalunless you change them
These choices set the initial expectations and the bounds honoured during both
screening seeding and coupled optimisation. They do not force the final
recommendation unless you mark a parameter Fixed; a fixed parameter is left
untouched throughout. Invalid bounds are reported inline and stop the run
before any fitting starts.
The Search settings row starts with Recommend, which sets what the coupled optimisation is for:
Best for trending (the default) — “Recommends the sharing pattern whose per-run parameters vary most cleanly along the series, among the models that fit adequately.” The Compare step then lists each model’s sharing ladder (see What “trends best” and “fits adequately” mean).
Best statistical fit — “Recommends the model and sharing pattern with the best information criterion.” The Compare step then lists the role splits of the separable role search (see How the role search works).
Screening is the same under either, so changing Recommend never asks for a new screening. Fits that were already optimised keep saying what they were optimised for: a banner reads, for example, “These fits were optimised as “Best for trending”. Optimise the shortlist on the Screen step again, and the phases on the Phases step, to rank them as “Best statistical fit”.”, and the stepper marks Compare and Phases with “!” until you do. Their results stay viewable and can still be applied. Switching back restores them at once. The choice is stored with the result, as the metric is.
Beside it are the ranking metric (AICc by default; see
Ranking metrics) and the single optimisation mode, reached by
the primary Run screening button.
Screen: rank the families and pick a shortlist
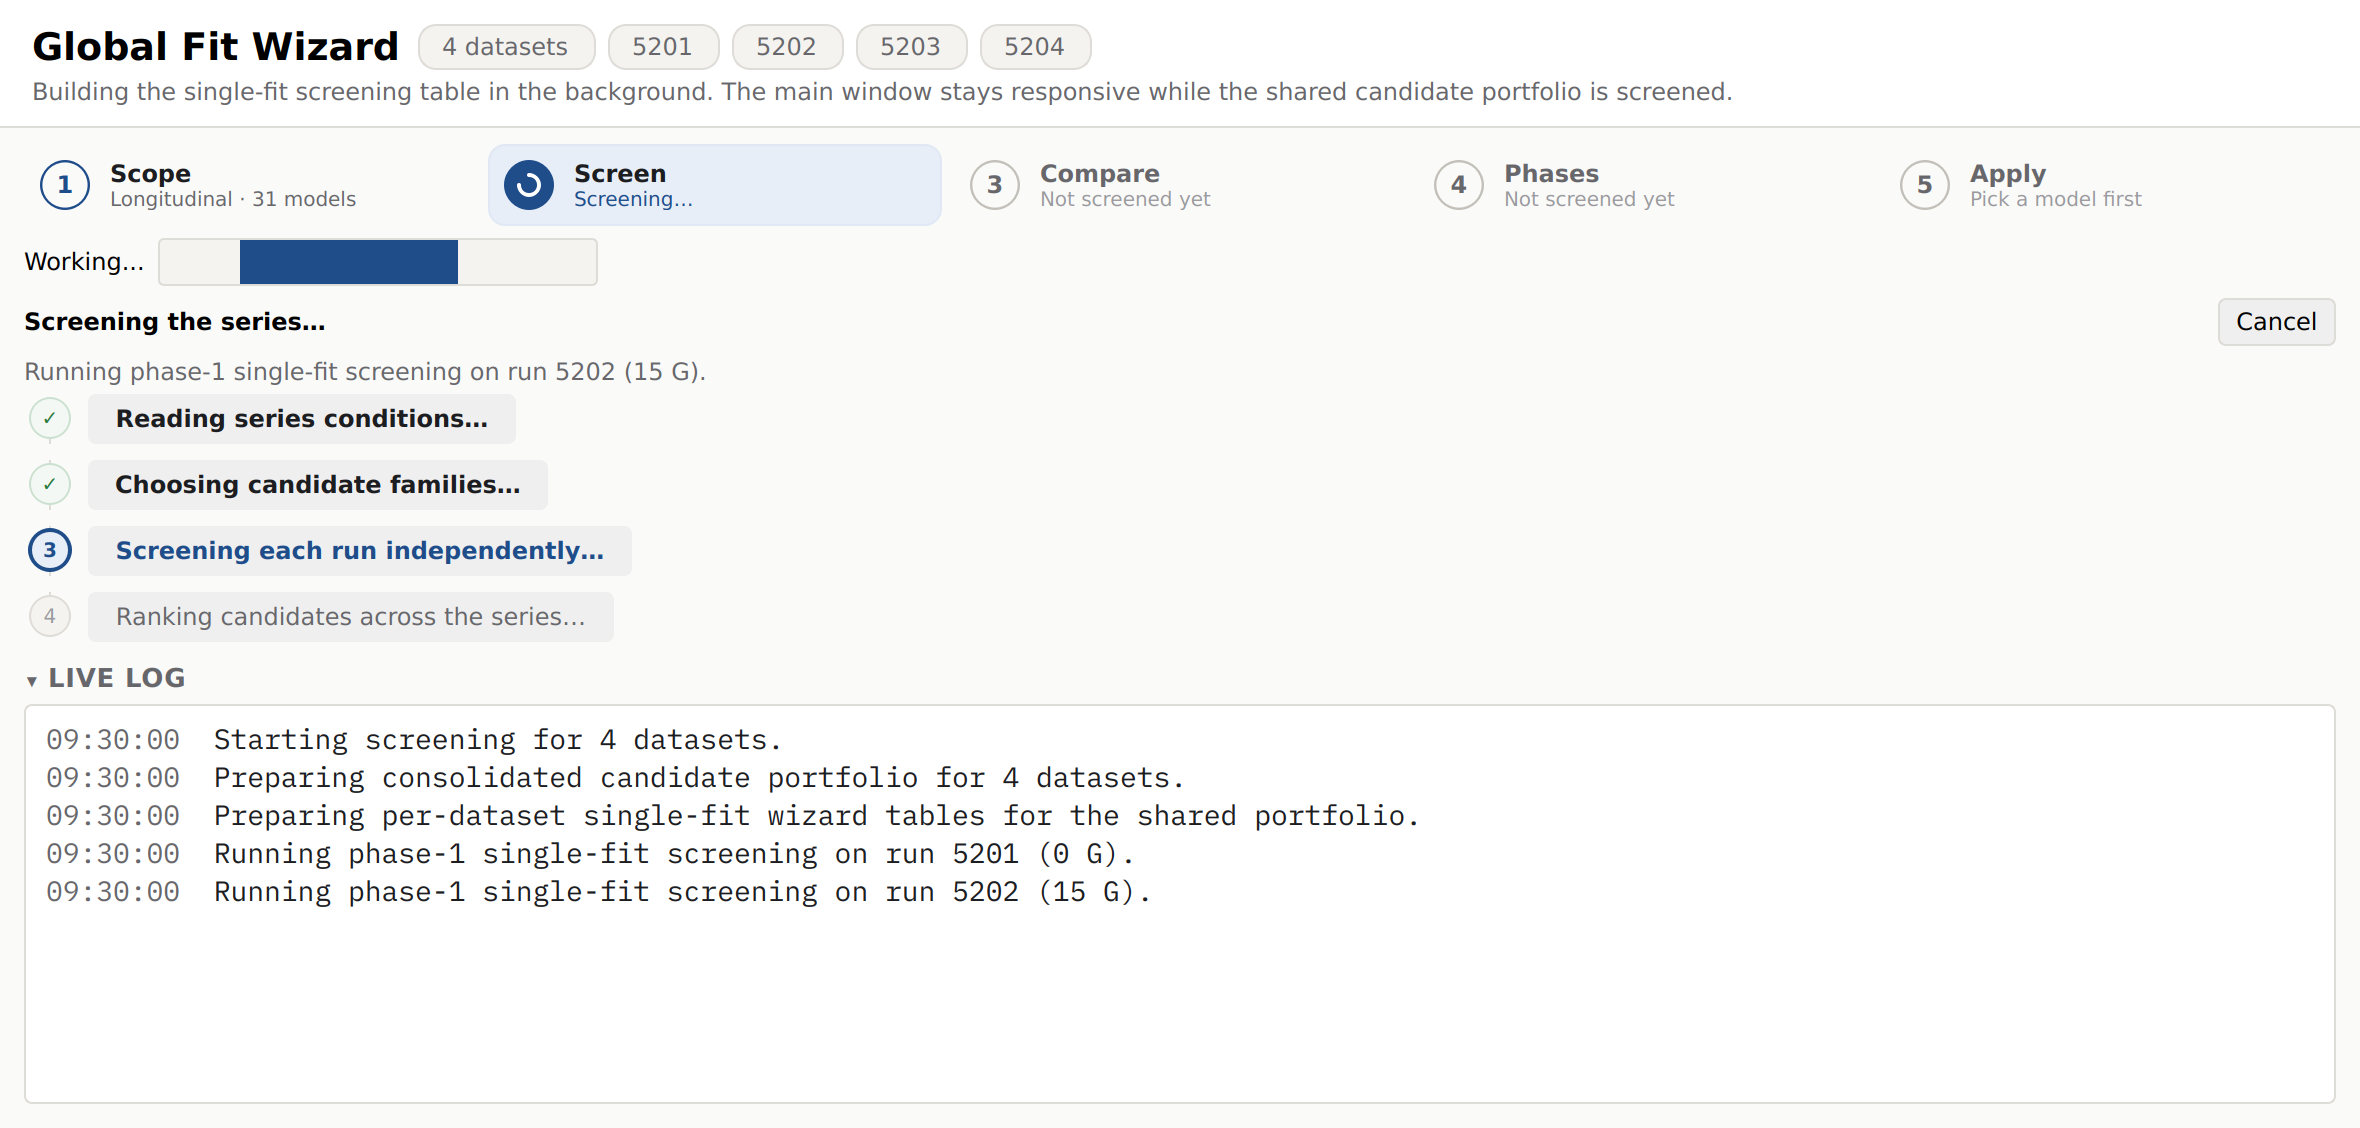
Screening in progress on the Screen step: the stepper marks the step “Screening…”, the first steps of the trail are done, per-run screening is active, and the Live log is expanded to show every progress message inline.
Run screening opens the Screen step and runs the screen there. Its trail reads the series conditions, chooses candidate families, screens each run independently, and ranks the candidates across the series. When it finishes, the step shows the family leaderboard.
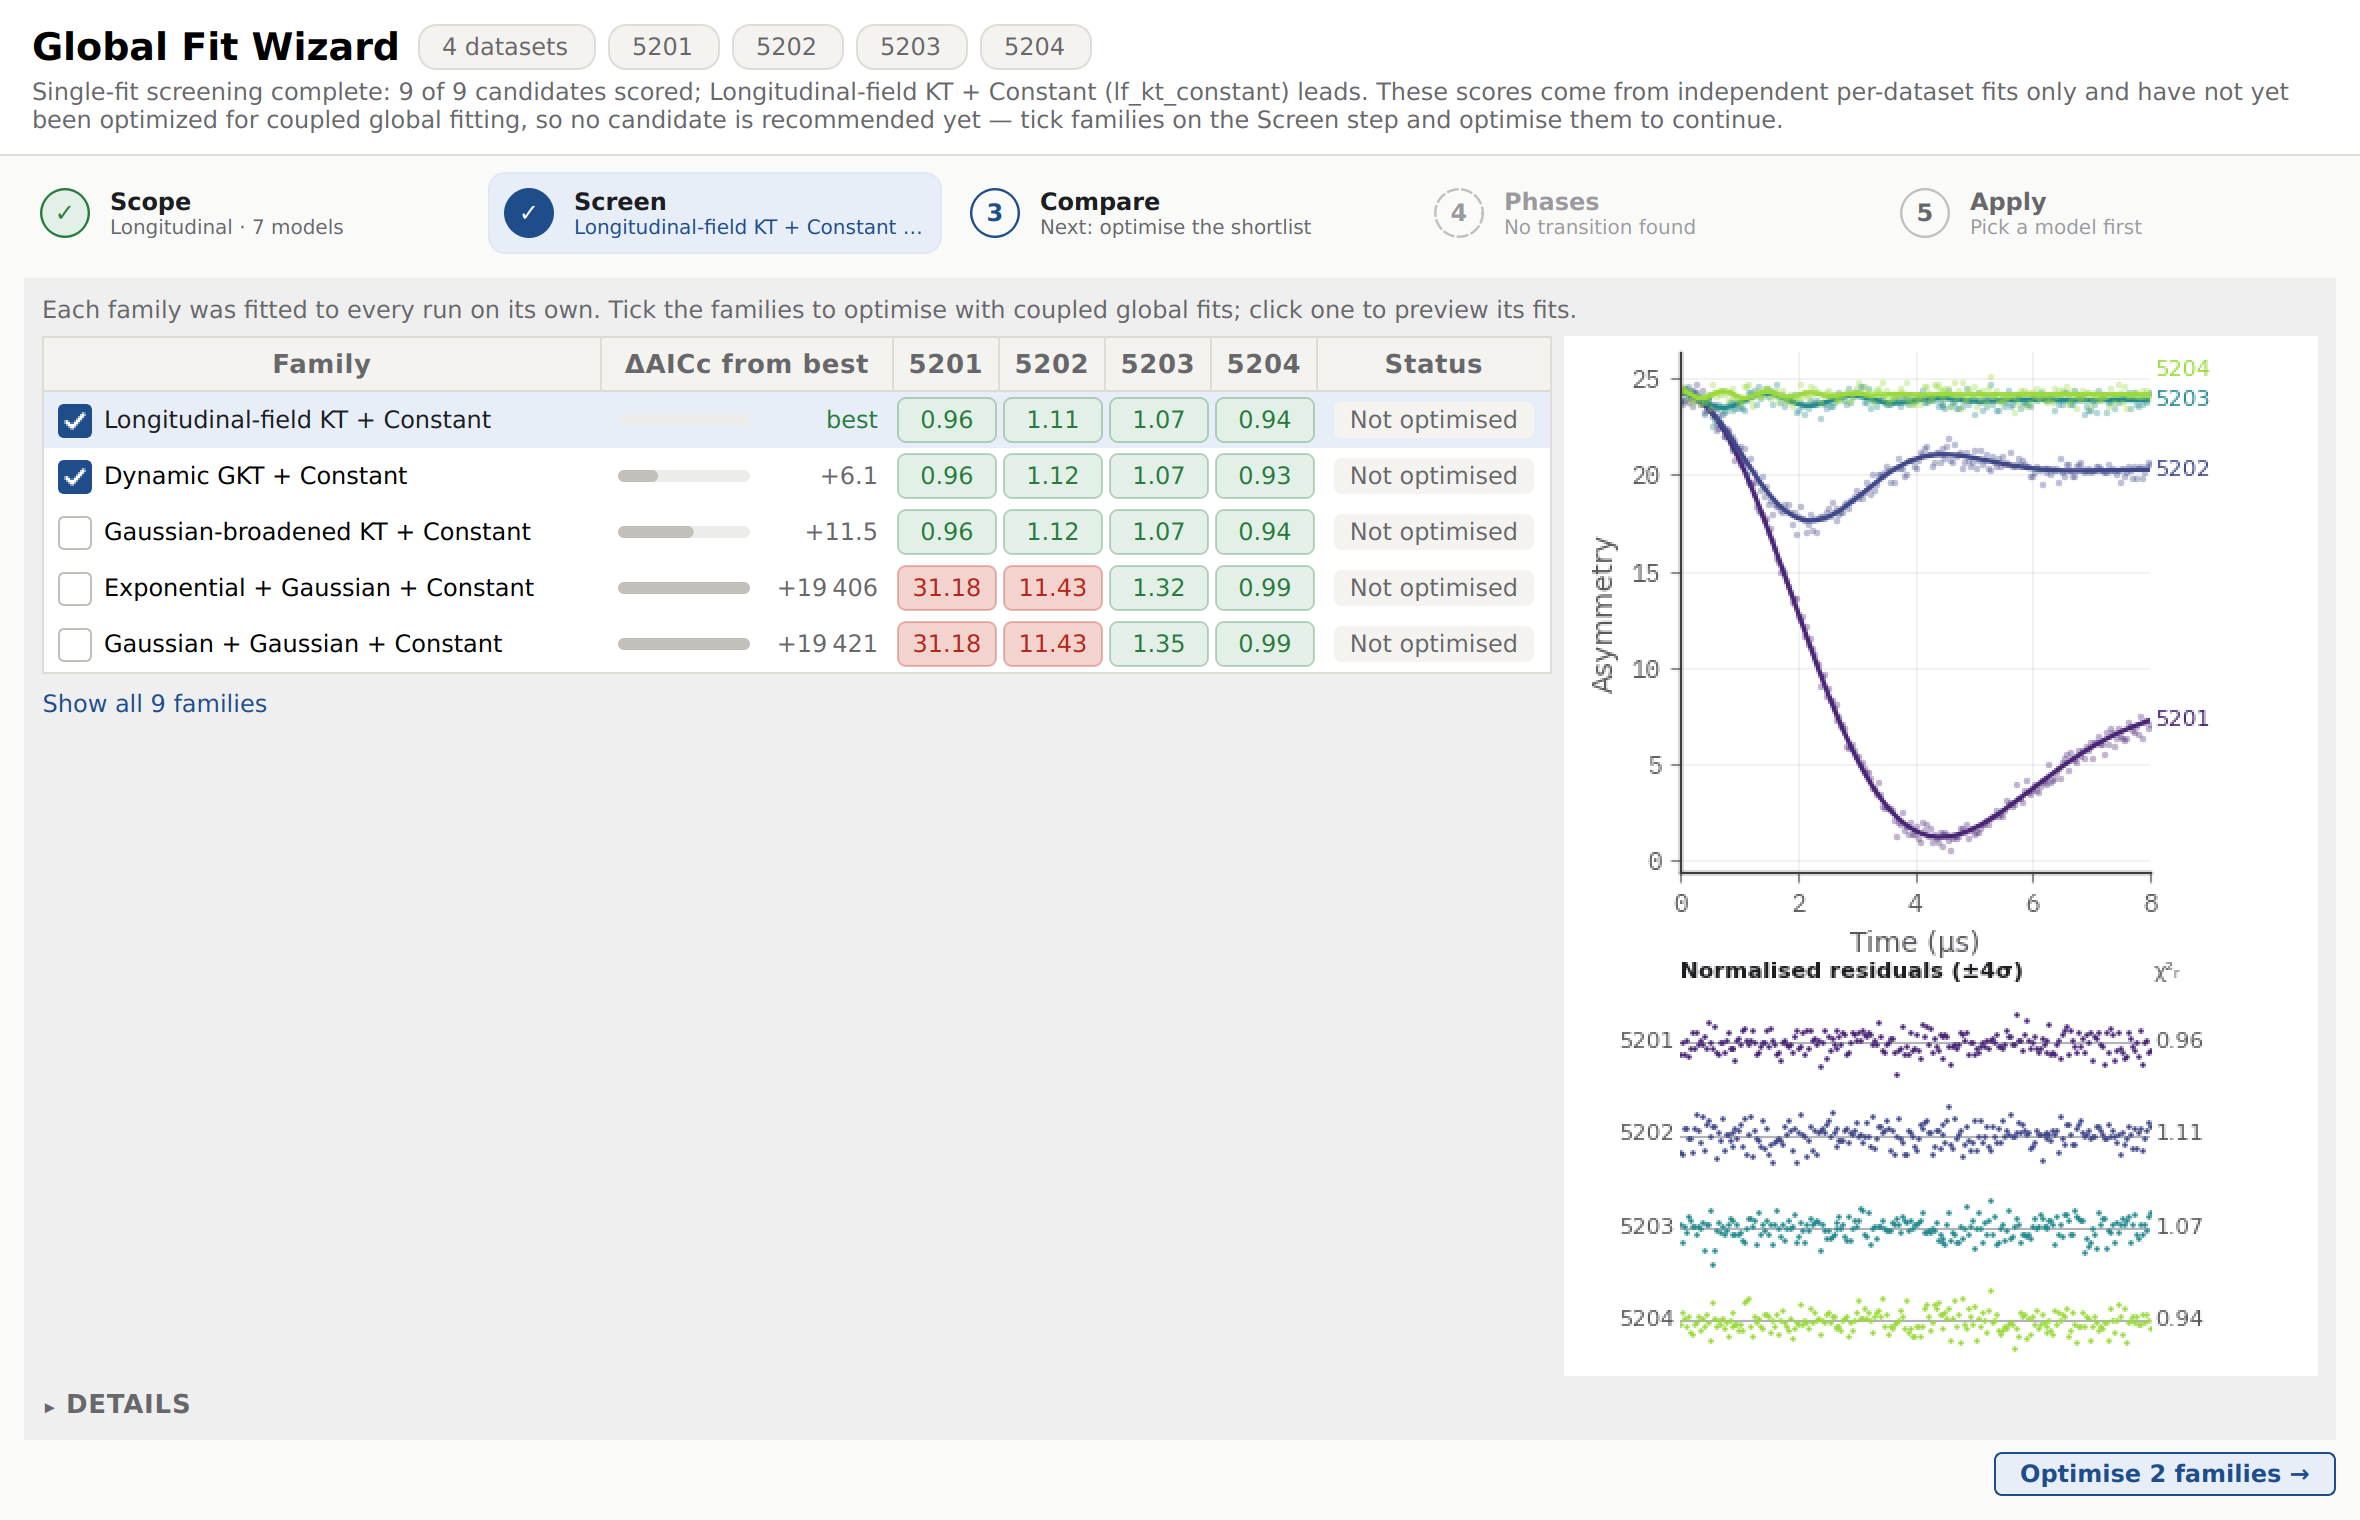
The Screen step after screening the Ag decoupling series with three Kubo–Toyabe models and the generic relaxation families in scope. Only three families survive to be scored. Longitudinal-field KT + Constant leads with every run’s χ²ᵣ graded good. The dynamic and broadened KT families trail by about 6 and 12 AICc units; the leading two lie within Δ ≤ 10 and are ticked. On the right, the leader’s per-run fits sit above their residual strips.
The leaderboard has one row per screened family, best first. Each row carries:
a tick box that puts the family on the shortlist for coupled optimisation;
the family’s title;
a bar for its difference from the best row on the ranking metric — the column header names it, “ΔAICc from best” — with the best row reading
best;one cell per run holding that run’s reduced chi-squared \(\chi^2_\nu\) from the family’s own single-run fit, graded good (\(\chi^2_\nu \le 1.5\), green), fair (\(\le 5\), amber), or poor (above 5, red);
a status badge:
Not optimised,Running,Optimised, orFailed.
The per-run cells show at a glance where a family fails — a Kubo–Toyabe dip the model cannot follow at low field, say — which a single series-wide score hides. Above eight runs the numbers no longer fit legibly, so the cells become a heat strip of graded squares, headed “χ²ᵣ per run, first → last: hover a square for its value”. A long board shows the ticked rows, the selected row, and the next three by rank; Show all N families lists the rest.
Click a row to preview that family’s per-run fits on the right: every run drawn with its fitted curve, colour-graded along the sweep axis, above one strip per run of normalised residuals \((y - f(t))/\sigma\) clipped at \(\pm 4\sigma\), labelled with the run’s \(\chi^2_\nu\). These are screening fits: a good row means the family looks promising when each dataset is fit on its own, not that it has survived coupled global fitting.
When screening finishes, the wizard pre-ticks the families within \(\Delta \le 10\) of the best on the ranking metric, up to three. The threshold follows Burnham and Anderson’s rule of thumb that a model more than 10 information units behind the best has essentially no support; the cap of three bounds the cost of the coupled fits that follow. Tick or untick any row, then press Optimise N families → (the count follows your ticks) to run their coupled fits; when several are ticked the wizard optimises them independently and, where it is safe to do so, in parallel. The collapsed Details section holds the raw screening table — Screening Score, AIC, AICc, BIC, Status, and the parameter counts — and the Candidate portfolio: every candidate family with its category, parameter count, and rationale.
Compare: candidate A against candidate B
The optimisation runs in the Compare step and lands there when it finishes; until one has run, the step reads “Optimise the shortlist on the Screen step first.” with a Go to Screen button. What the step lists depends on Recommend: sharing ladders under Best for trending, role splits under Best statistical fit. The comparison itself — pick A, pin B, read them side by side — is the same under both, and is described first.
Click a row to make it candidate A; Pin as B on any other row overlays it as candidate B, and Unpin B clears it. The recommended row starts as A. On the right, both are drawn over the data — A solid, B dashed, one colour per run along the sweep axis — above one residual strip per run, A in the run colour over B in grey, with each run’s \(\chi^2_\nu\) for A and B at the strip’s end (“χ²ᵣ A · B”); a series longer than twelve runs shows twelve strips spread along it. Below, a parameter table sets A beside B: a shared parameter as one value with its uncertainty, a local one as its per-run values, and a note column that flags a global both candidates share when the two values differ by two standard deviations or more (“differs by 3.1σ”), together with either side’s parameter flags. Continue with A → takes A to the Apply step.
Every row also carries the warnings the fit earned: the residual gate’s failing check with its runs spelled out (for example “runs-test z score suggests structure (-2.32) (run 5204)”), and parameter flags, each naming the runs that earned it — a value “at lower bound” or “at upper bound” (a plain fact — a rate pinned at zero is often physical), “not finite”, or “poorly determined” (its uncertainty exceeds its magnitude). A row shows at most three warning lines and hides the rest behind “+*k* more”.
Best for trending: the sharing ladders
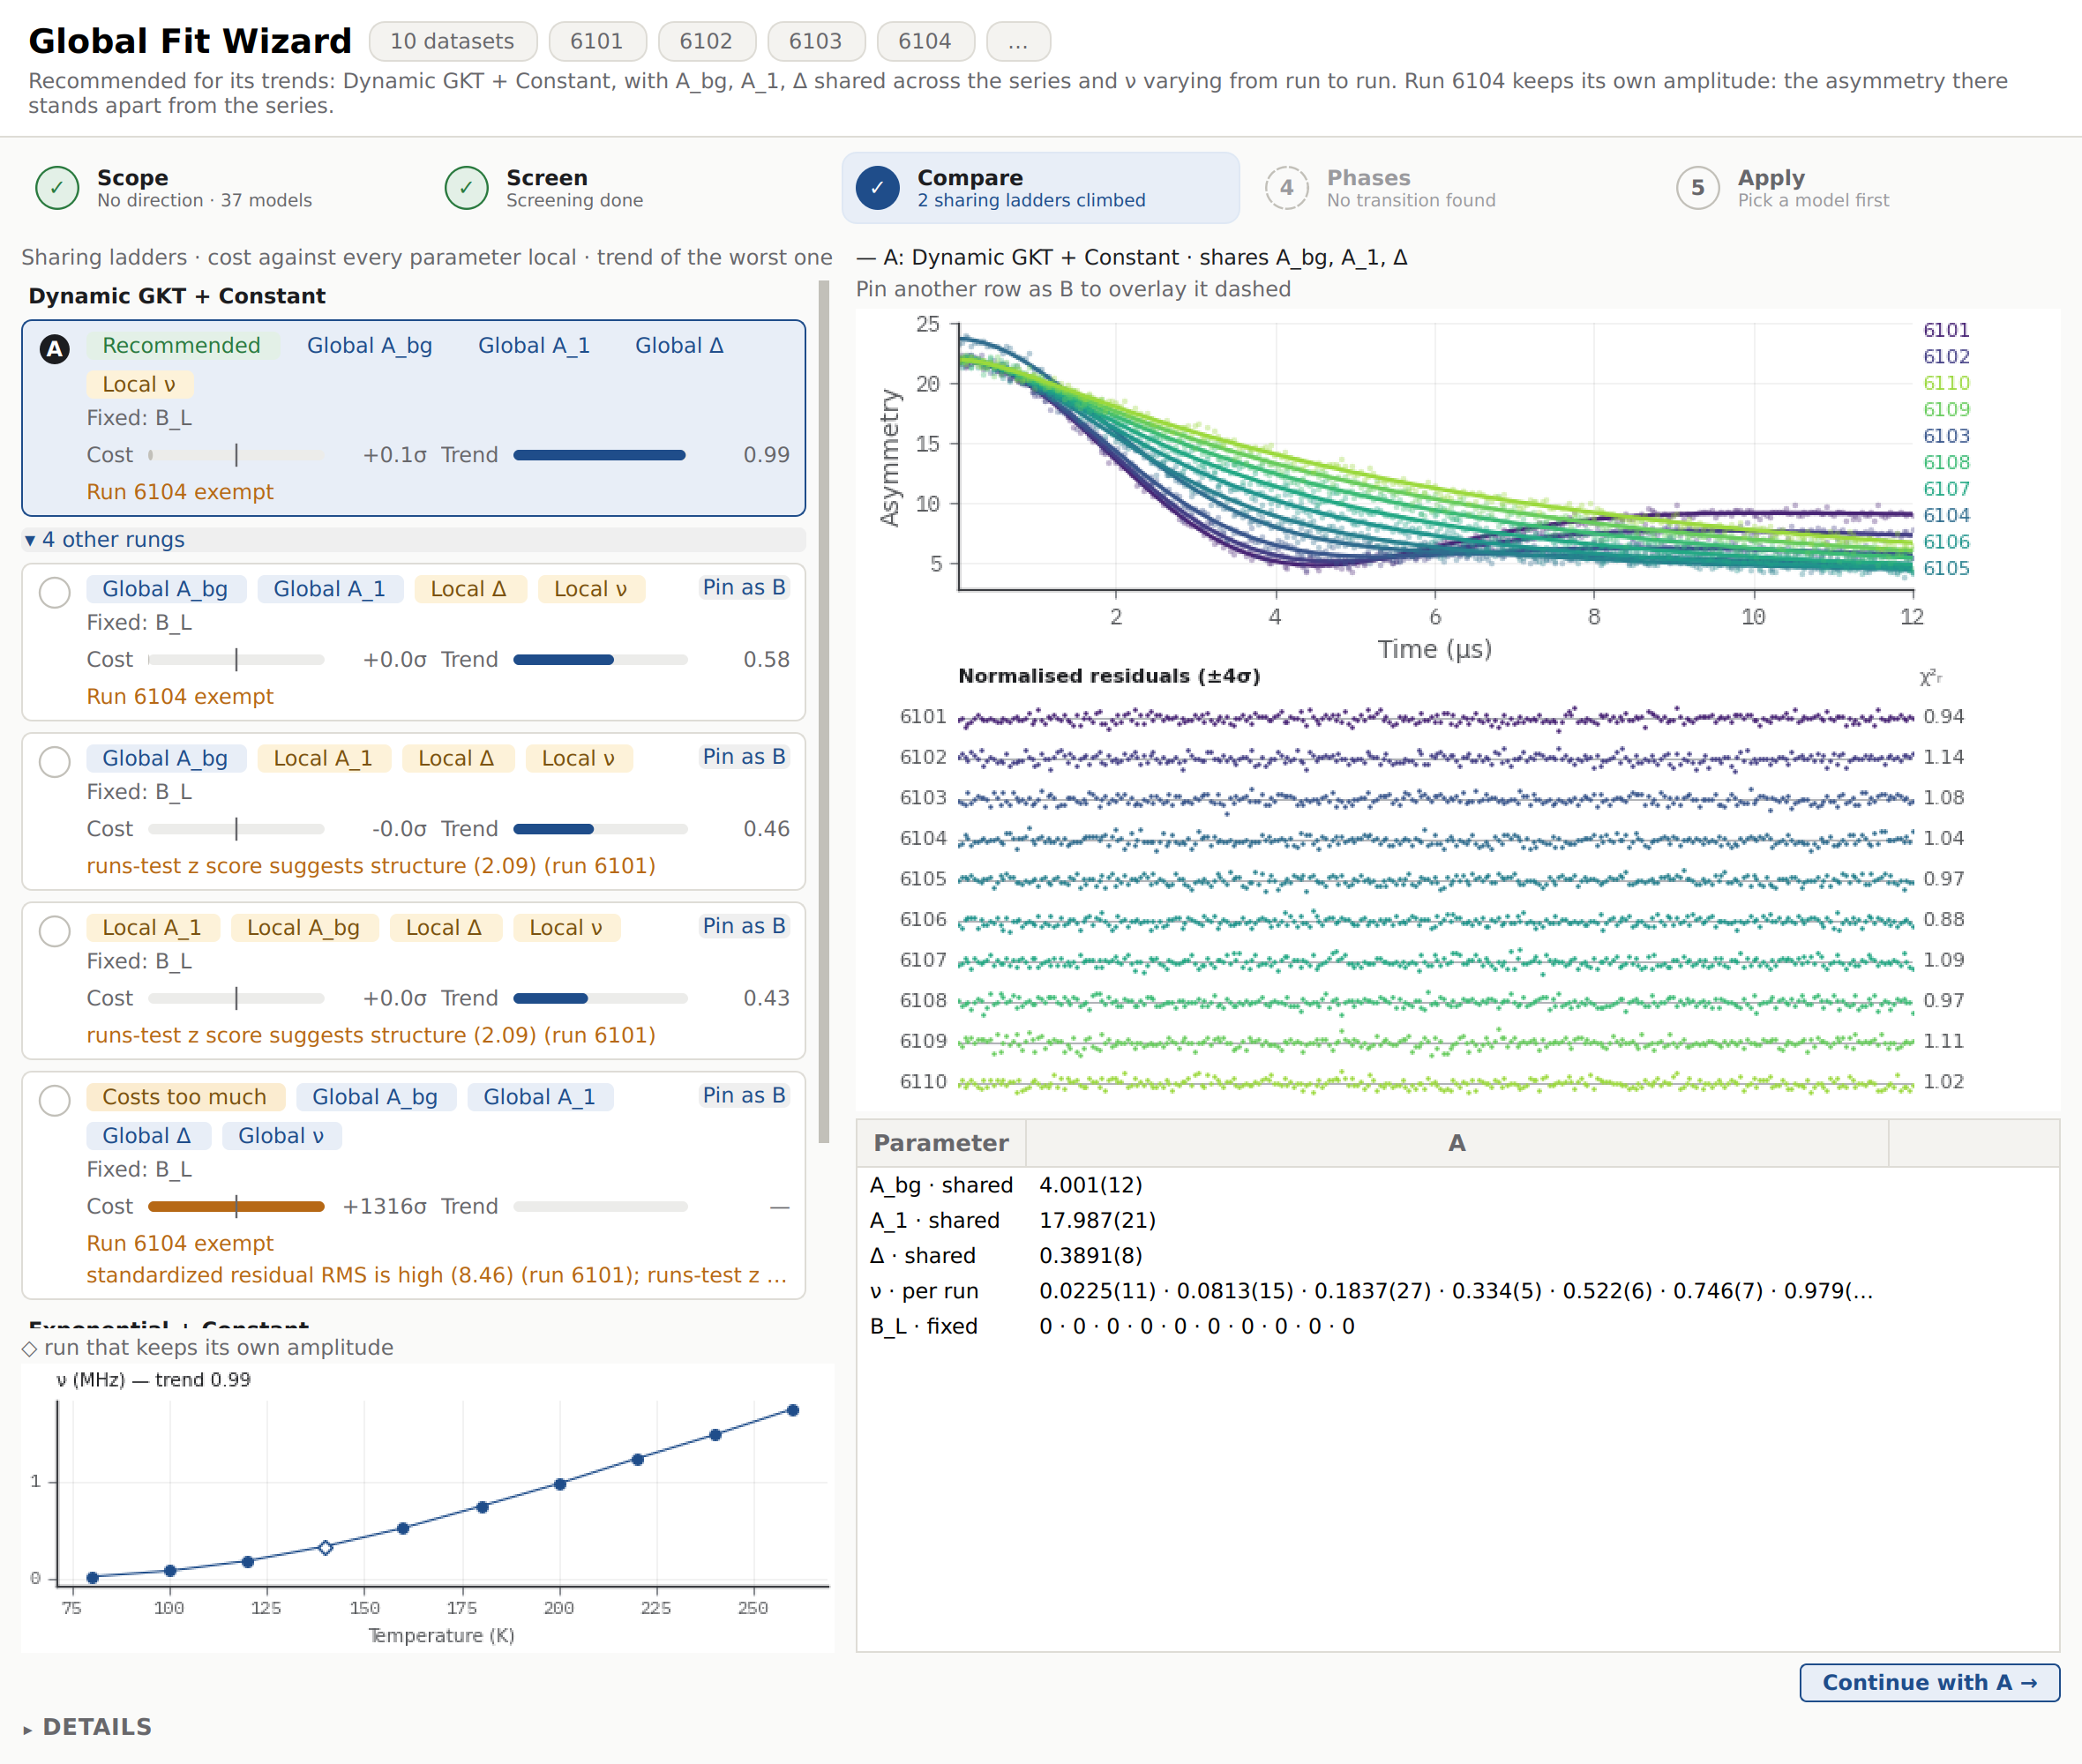
The Compare step on a synthetic zero-field temperature scan: a dynamic Gaussian Kubo–Toyabe signal with one static width and a hop rate that rises with temperature, and one run that carries 10 % more asymmetry. The recommended rung shares the background, the amplitude, and Δ, leaves ν local, and exempts run 6104. The model’s ladder is unfolded beneath it: with Δ or the amplitude still fitted run by run the worst trend falls to 0.58 and below, and sharing ν as well costs far more than the tolerance allows. The strip under the list traces ν against temperature, the exempt run drawn as a hollow diamond.
Under Best for trending the wizard fits, for each shortlisted model, a sharing ladder: the same model with nothing shared, then with the background shared, then the amplitudes, then one further parameter at a time, each rung a real coupled fit (What “trends best” and “fits adequately” mean gives the order and the rules). The left of the step lists the ladders model by model, under the caption “Sharing ladders · cost against every parameter local · trend of the worst one”. The models that fit about as well as the best one come first, in the order of their trends, so the recommended rung leads the list; models that fit worse follow, by how well they fit.
Each model shows one rung — the one its ladder pre-selects — and folds its others behind a toggle (”▸ 4 other rungs”). The pre-selected rung is a model’s answer and the rest are the evidence for it, so the default view is one answer per model and stays short however many parameters a model has; unfolding a ladder shows what each further act of sharing bought or cost. A ladder stays unfolded once you open it, and opens by itself when one of its folded rungs is A or B. A rung’s row carries:
a mark, when it has one:
Recommendedfor the rung the wizard recommends,Pre-selectedfor another model’s best adequate rung,Costs too muchfor a rung over the cost tolerance, andFit failedwhen the coupled fit did not converge on every run;one chip per parameter naming its role (
Global Δ,Local ν), and a “Fixed:” line for any fixed parameter;Cost: how far sharing raised the series \(\chi^2_\nu\) above the same model with every parameter local, in standard deviations of \(\chi^2_\nu\) (“+0.1σ”). The bar is full at twice the tolerance, with the 2σ tolerance marked half-way, and turns amber past it;
Trend: the trend quality of the worst parameter the rung leaves local, from 0 to 1 (“0.99”); hover it for every local parameter’s quality. A rung that shares everything has nothing left to trend and reads “—“;
the ladder’s findings about the rung, each with a sentence on hover:
“Run 6104 exempt” — “Run 6104 keeps its own amplitude: the asymmetry there stands apart from the series.”;
“Amplitude not shared through runs 1–3” — “Amplitude could not be shared through runs 1–3: possible missing asymmetry there, or an amplitude that really changes.”;
“Hard to justify: shares λ” — “Shares λ while the same component’s amplitude varies.”;
“Passes disagree on λ” — “Runs taken in separate passes disagree on λ.”;
“Outside the 3 % band” — “Fits worse than the best model by more than 3 %; listed for comparison.”
A rung that costs too much says so and stays pickable. The tolerance is a statement about noise, and a model that only reaches \(\chi^2_\nu \approx 1.5\) everywhere is already imperfect by more than the tolerance measures; when the pattern you know to be physical costs a little more than 2σ on such a model, pick it, read its residual strips against the pre-selected rung pinned as B, and continue with it. Likewise a model outside the 3 % band is never recommended, but it is listed with its trend quality and can be picked.
Beneath the list, a strip plots every parameter that A leaves local against the sweep axis, with its error bars, each plot titled with the parameter and its trend quality (“ν (MHz) — trend 0.99”). Hover a plot for the three factors behind the number. B’s values are overlaid hollow and dashed, and a parameter only B leaves local gets a plot of its own, so pinning the rung below A shows directly what sharing one more parameter did to the others. Runs that keep their own amplitude are drawn as hollow diamonds (”◇ run that keeps its own amplitude”). This strip is what the recommendation should be judged by: a parameter that rises smoothly through a dozen runs is worth more than a few units of information criterion. When A shares everything the strip reads “Every parameter is shared: nothing varies from run to run”.
The collapsed Details section holds the rungs’ scores (the ranking score, AIC, AICc, BIC, the gate, and the Global and Local parameters) and the Cost of A: the series \(\chi^2_\nu\) with every parameter local and for this rung, the cost with its tolerance, each local parameter’s trend quality, and a table with every run’s own \(\chi^2_\nu\) and Cost (σ). The Note column marks a run that is “exempt: keeps its own amplitude” and one that is “over the 2σ tolerance” on its own.
Unavailable criterion cells show “—” with a tooltip explaining the reason and recorded point and free-parameter counts. AICc never falls back to AIC.
Best statistical fit: the role splits
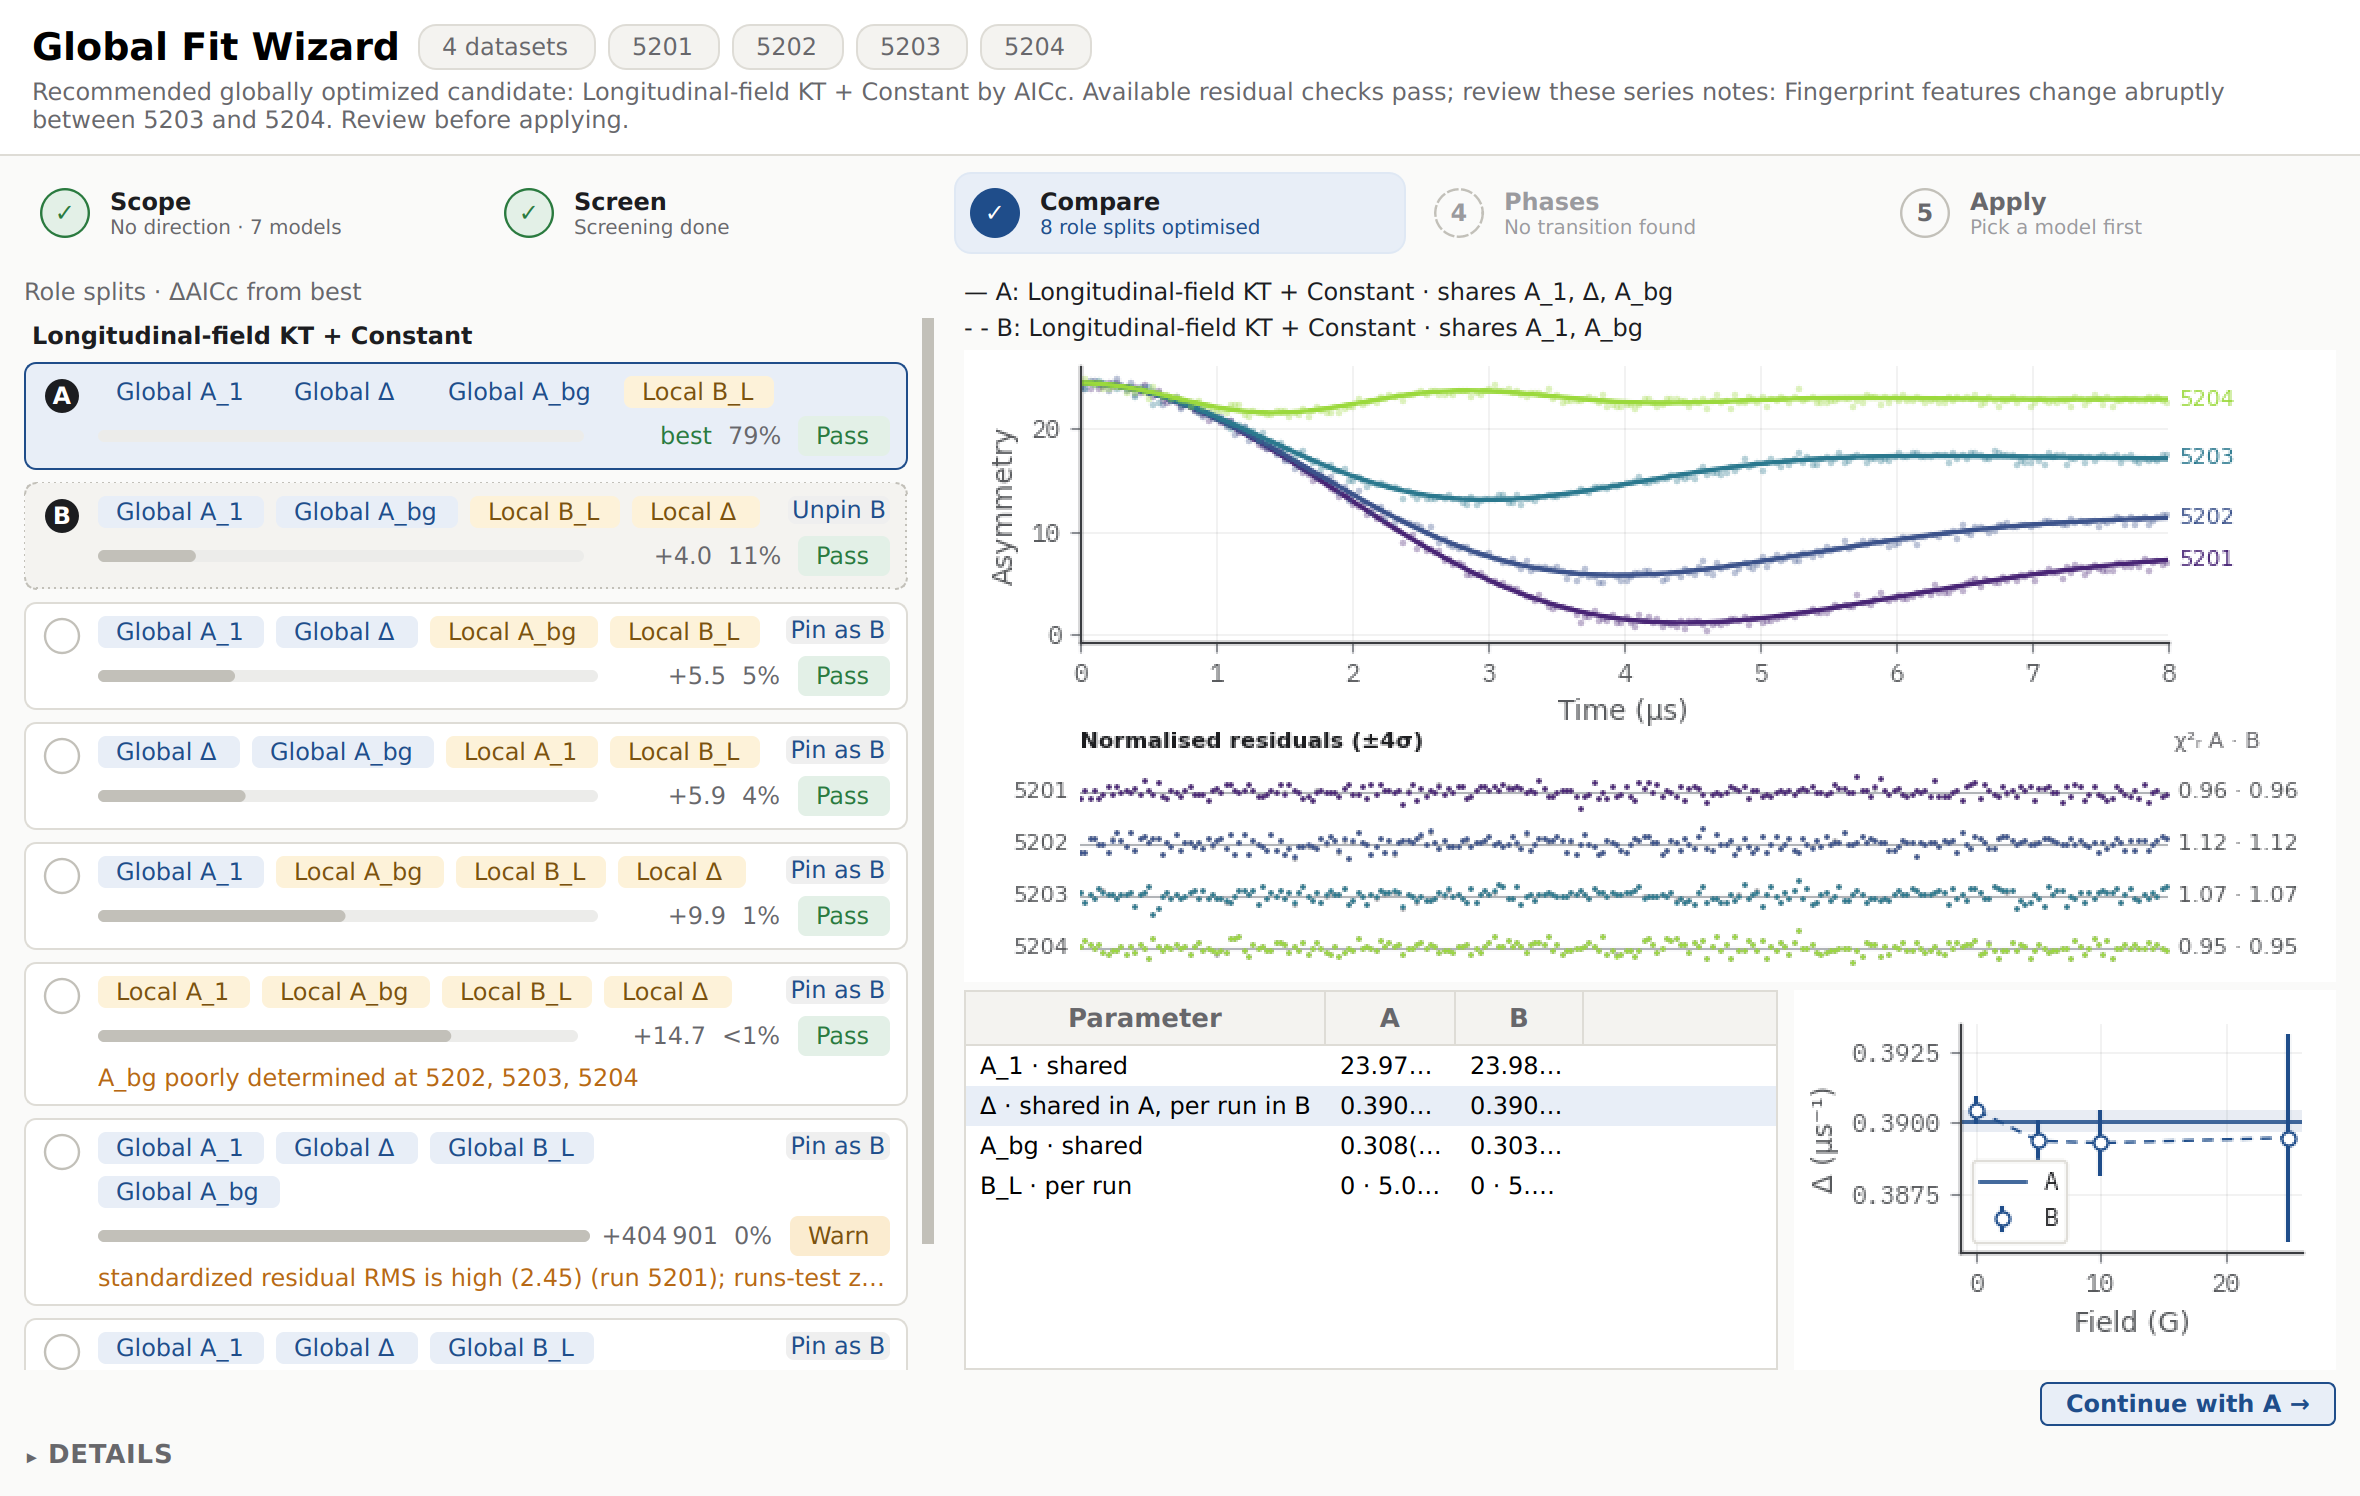
The Compare step under Best statistical fit after a coupled optimisation of Longitudinal-field KT + Constant on an Ag decoupling series at 0, 5, 10 and 25 G. A is the recommended split, with Δ shared and \(B_L\) per run. B, pinned dashed, frees Δ per run as well. It fits every run as closely by eye and passes every check, but its three extra parameters buy nothing: it scores +4.0 AICc. The trend plot follows Δ: A’s shared value is one line across the series, and B’s per-run values sit on it within their errors.
Under Best statistical fit the optimised candidates are grouped by model, best first, with one row per Global/Local split — a single template usually yields several, since the role search scores neighbouring assignments exactly — and every row is in view. In place of a cost and a trend, each row carries:
a bar for its difference from the best optimised split on the ranking metric (the caption above the list names the metric, “Role splits · ΔAICc from best”);
an evidence weight, the Akaike weight on the ranking metric, \(w_i \propto \exp(-\Delta_i/2)\), normalised over the optimised splits — the relative support each split has among those fitted, read as a percentage (a sliver of support reads
<1%);a gate badge,
Passwhen every run’s residuals pass the automatic checks andWarnotherwise.
Click the row of a parameter that is local to A or B in the parameter table to plot it against the sweep axis beside the table — A filled, B hollow and dashed, and a shared value drawn as one line with its \(\pm1\sigma\) band. In the LF decoupling example, the local \(B_L\) tracks the applied field — exactly the shared-\(\Delta\), local-\(B_L\) structure the model expresses.
Here the collapsed Details section holds the raw optimised table and the
Parameter roles for A: for each non-fixed parameter, the score with it
kept Global, the score with it made Local, and the difference. These
recommendations discourage overfitting: a model with more local parameters
usually fits better in raw \(\chi^2\), so the wizard only recommends
Local when the penalised information criterion improves enough to overcome
the extra flexibility.
Apply: review what the global-fit tab receives
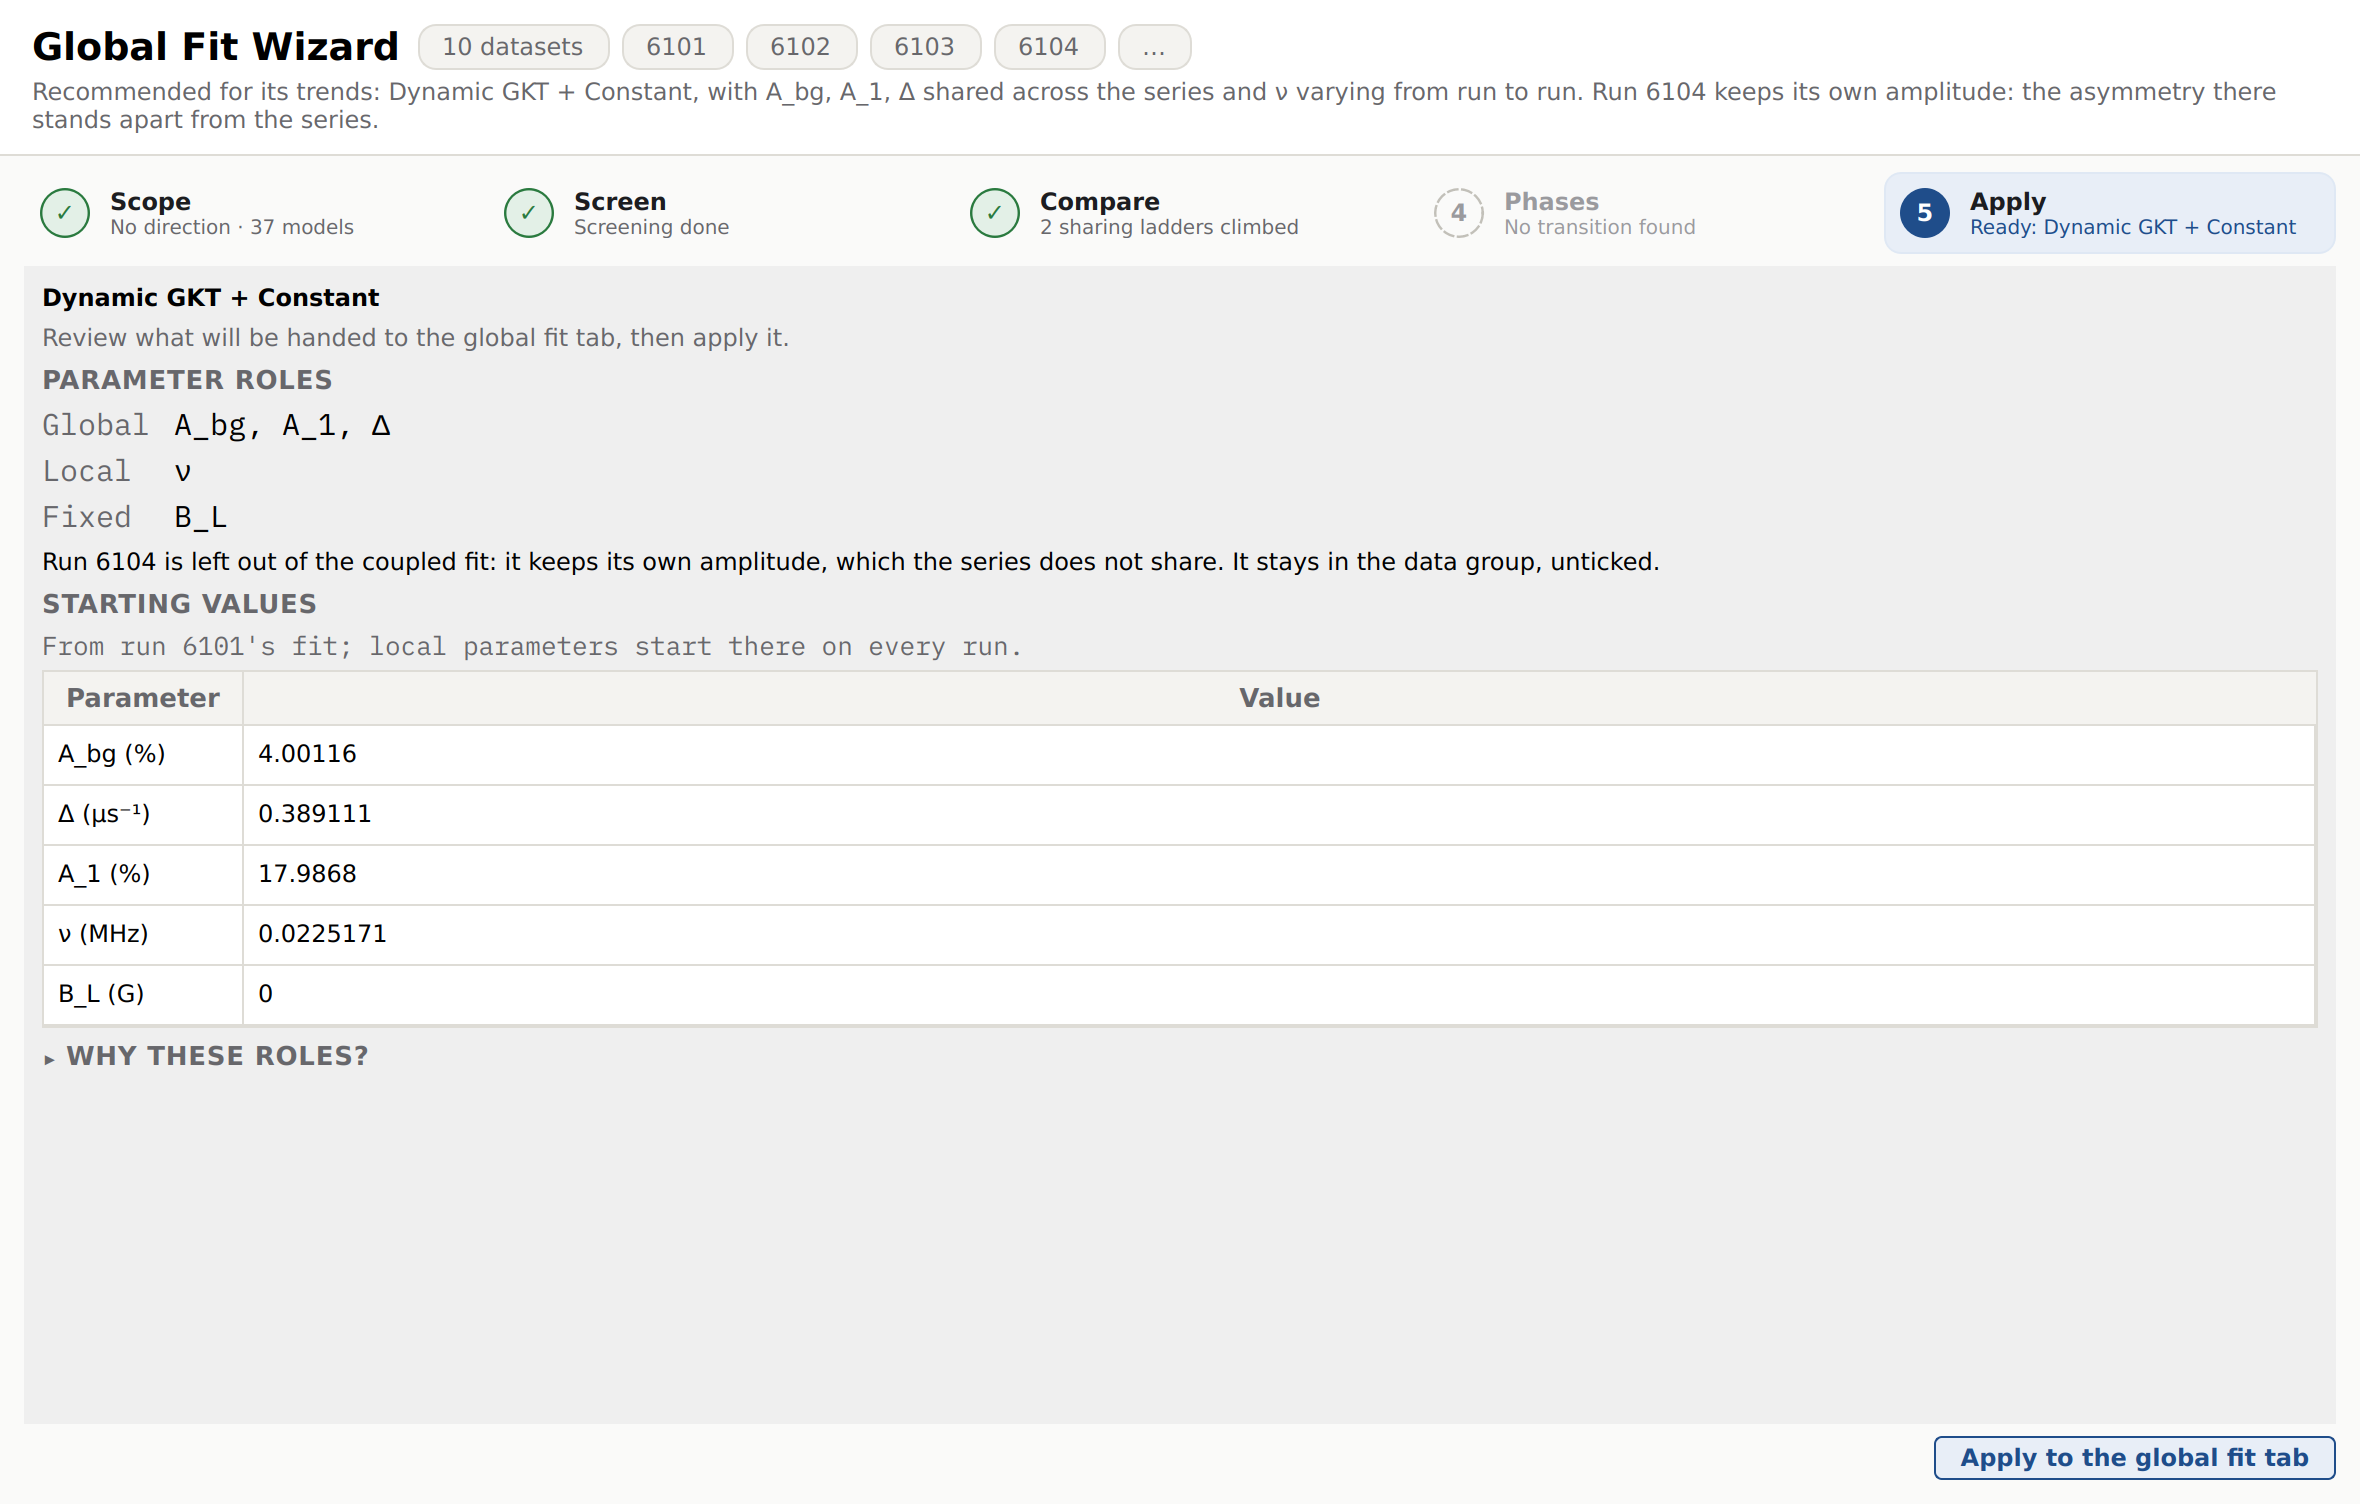
The Apply step after Continue with A → on the recommended rung of the hopping scan: the model, the parameter roles the global-fit tab will set, the run left out of the coupled fit, and the starting values from the first coupled run’s fit, above Apply to the global fit tab.
Choosing a model and committing it are separate acts, so Apply reviews exactly what will be handed over before anything changes: the model’s title, its parameter roles (Global, Local, and Fixed, as the global-fit tab will set them), the Starting values (“From run N’s fit; local parameters start there on every run.”), any series warnings, and a collapsed Why these roles? section — the cost, the trend qualities, and the findings of a ladder rung, or the role search’s rationale for each parameter of a role split. Apply to the global fit tab then updates the tab’s composite function, parameter values, bounds, and Global or Local roles directly, reusing the already-computed fit bundle so the plots and parameter views refresh immediately without rerunning the fit. Afterwards the step’s summary reads “Applied: title”. To apply a different row, go back to Compare, make it A, and continue again.
A rung is applied as it was fitted. When it shares one total amplitude and
leaves the fractions local (see What “trends best” and “fits adequately” mean), the
tab receives the model written that way — its signal terms in a fraction
group — with the total Global and the fraction Local. When it exempts
runs, those runs are left out of the coupled series: a parameter of the
global-fit tab is Global, Local, or Fixed, and “shared, except on these runs”
is none of the three. Apply says so before you commit — “Run 6104 is left out
of the coupled fit: it keeps its own amplitude, which the series does not
share. It stays in the data group, unticked.” — and the tab’s results card
repeats it afterwards. The exempt runs remain members of the series’ data
group and appear unticked in the tab’s member list, so the recorded series
lists them as excluded and the tab’s own fit over the remaining runs starts
from the rung’s pattern and values. Tick a run again to bring it back; the
shared amplitude then has to describe it too.
When the answer is a partition instead (see Phases: transitions and the penalty path), Apply reviews the phases — the partition’s summary sentence and one entry per phase with its range, template, Global and Local parameters, and its cost and trend quality (or its confidence, under the statistical objective), with the runs each phase leaves out — and offers Apply phases.
Phases: transitions and the penalty path
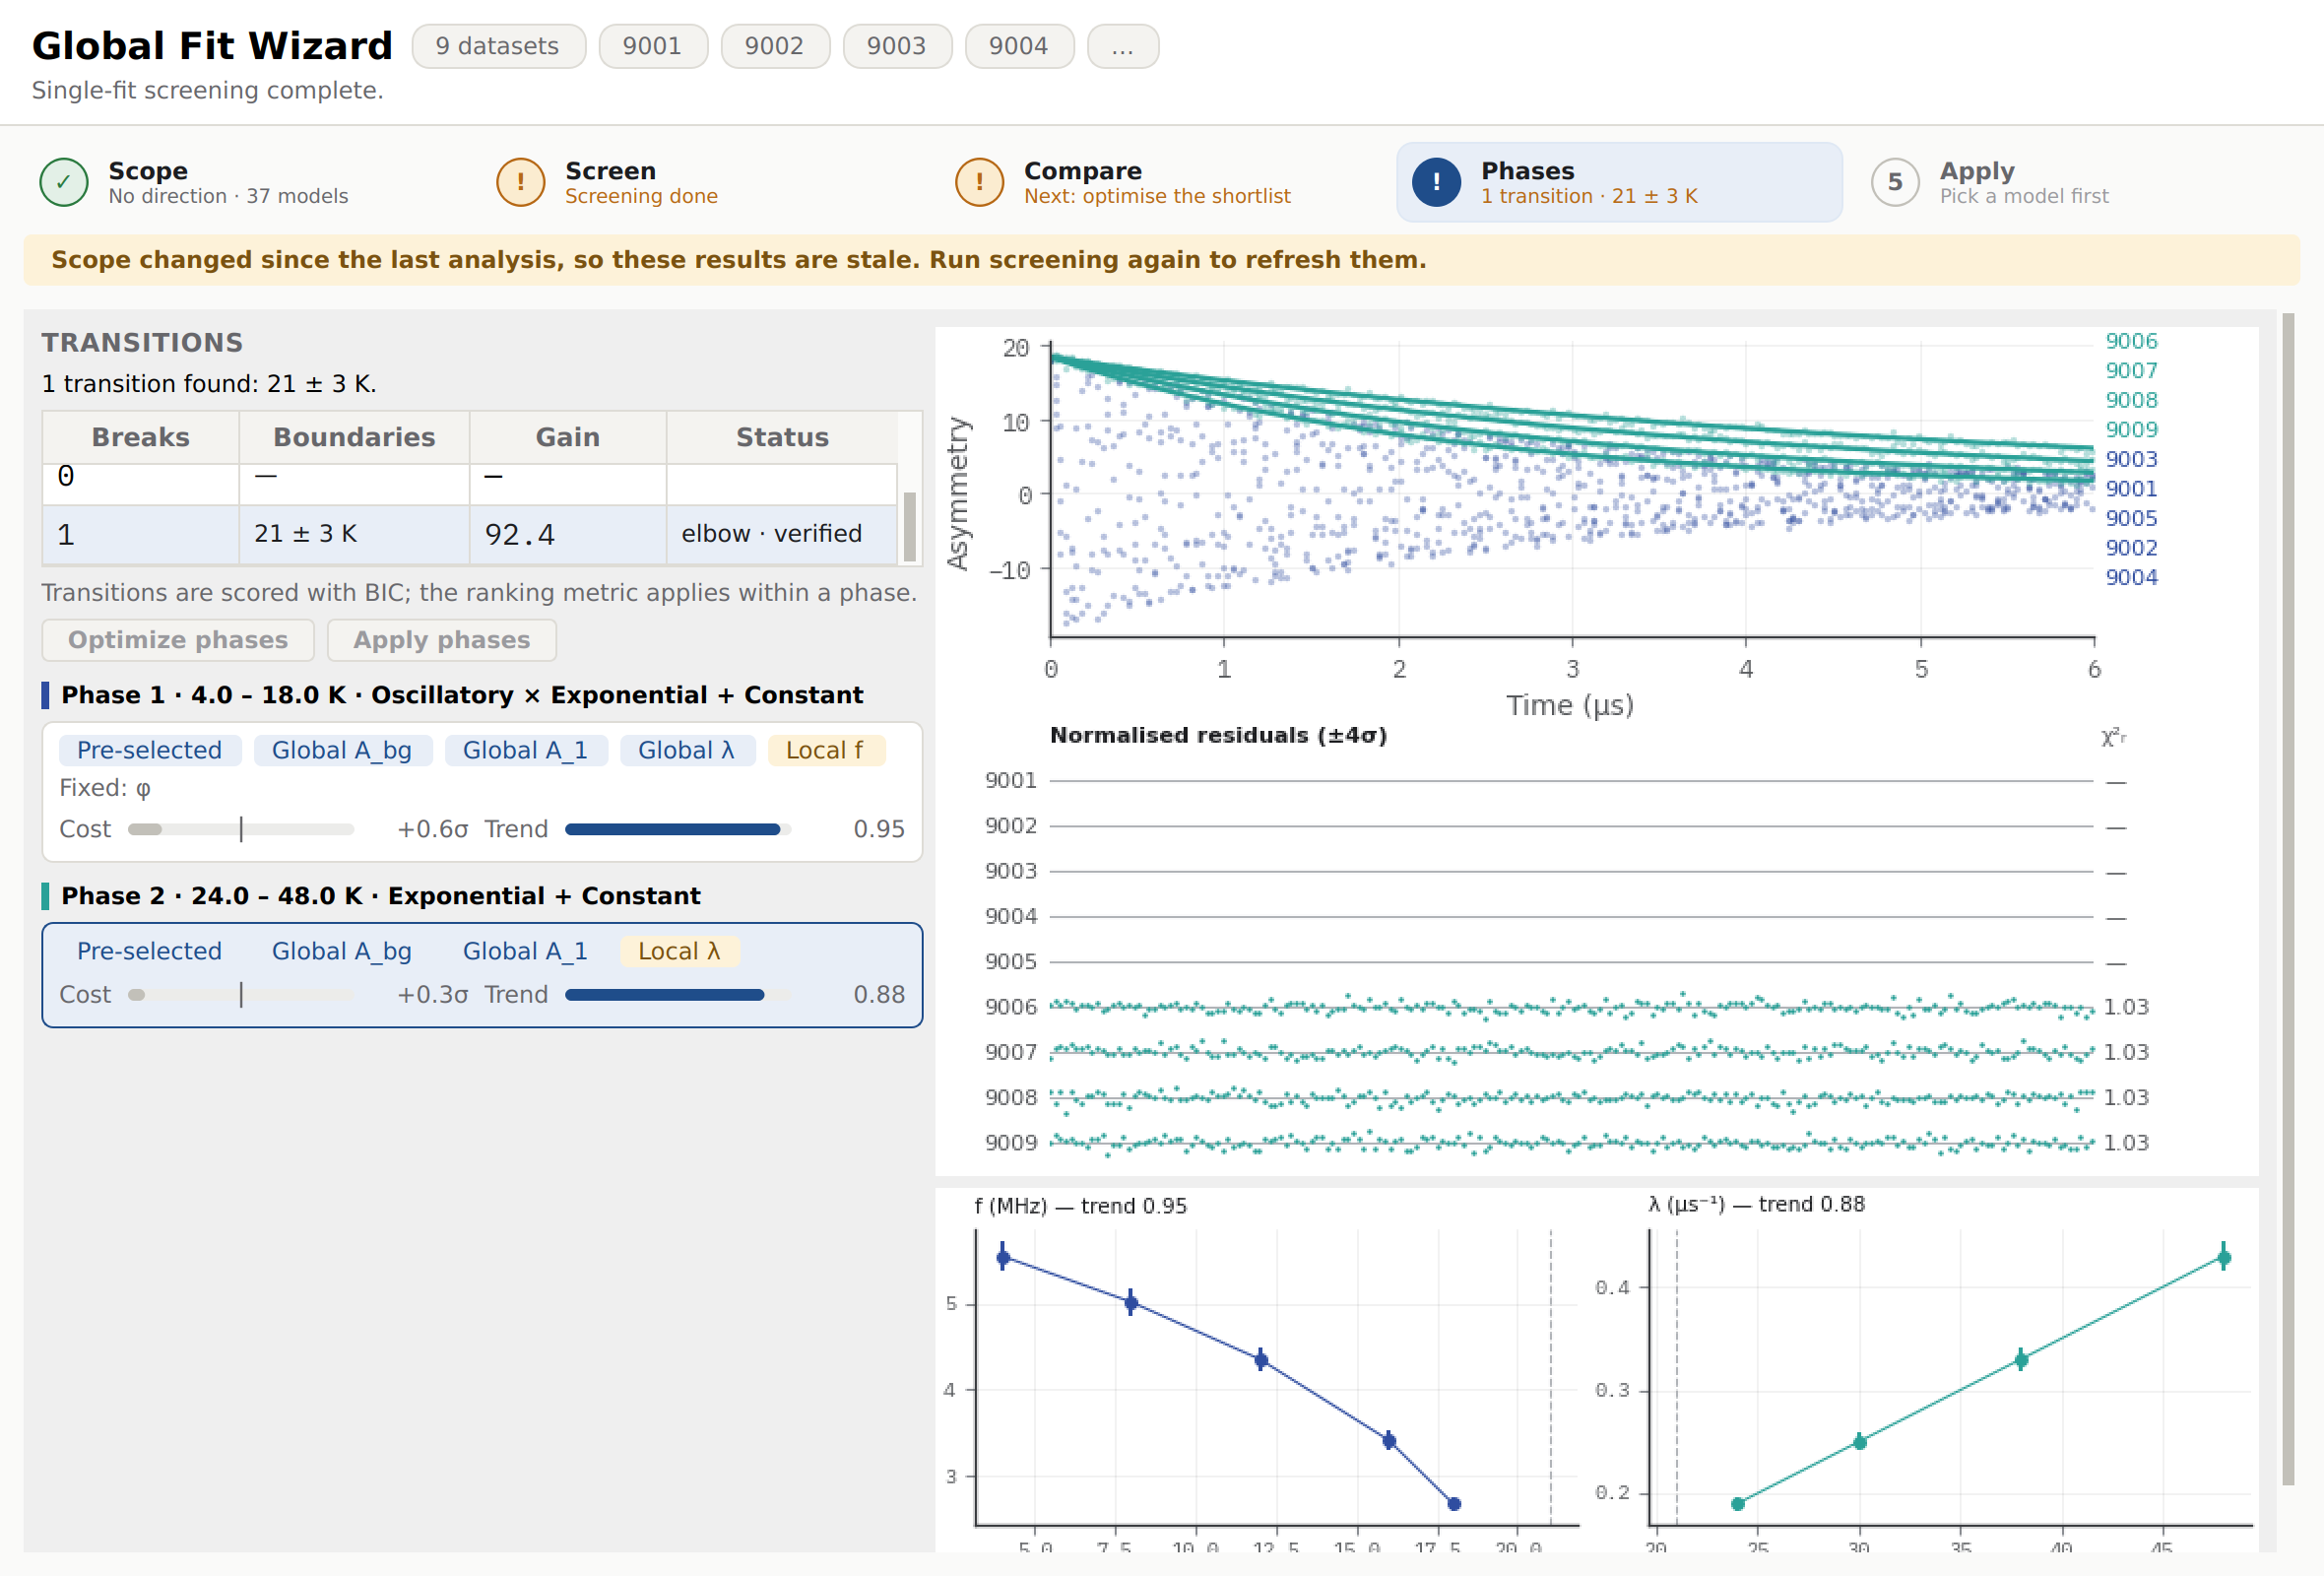
The Phases step after optimising a synthetic two-phase temperature scan: the Transitions card shows the penalty path (0 and 1 breaks, the elbow pre-selected and verified) above one row per phase with its sharing pattern, cost, and trend quality. The second phase is picked, so the overlay, coloured by phase, draws its coupled fit over its four runs. The strip beneath traces the precession frequency through the ordered phase and the relaxation rate above it, with the boundary dashed.
A temperature or field series can cross one or more transitions, and the model that describes the runs on one side does not describe the runs on the other — oscillations collapsing into a relaxation, a paramagnetic component appearing above an ordering temperature. Rather than fit the whole series under one template and hope the residuals stay clean, the wizard partitions the series into phases — contiguous runs along the sweep axis, each with its own template and its own Global/Local assignment — and fits each phase independently. A break between two phases is always a change of model family — damped oscillation, single relaxation, multi-rate relaxation, Kubo-Toyabe — never a change of template within a family, of Global/Local split, or of parameter values. Which template a phase uses (two damped lines or one, an exponential or a Gaussian envelope) and which of its parameters are shared are decided by the coupled fit within the phase; a global parameter that drifts smoothly along the whole series has exactly two honest representations, Global or Local, and can never be approximated by inserting breaks.
An oscillation that dies out is a change of family too. A damped-cosine template is read as oscillatory on a run only while at least one of its line amplitudes is measured — larger than twice its own fitted uncertainty — so on the runs where every line has collapsed into the envelope the template is describing relaxation, is not offered as an oscillatory phase there, and the wizard places a break where the lines stopped rather than carrying one oscillatory phase across them.
The Phases step is active whenever the series alphabet’s per-run scores
support a partition. Before screening it reads “Not screened yet”; when the
series has no penalty path (fewer than six runs), or the path’s own pick has
no break, the step is skipped and reads “No transition found”. Otherwise it
holds the Transitions card beside an overlay of the series coloured by
phase. The card states the whole penalty path — the best partition of the
series with exactly \(0, 1, 2, \dots\) breaks — as one row per solution,
in a table with Breaks, Boundaries, Gain, and Status columns;
a solution with nothing to show on a column (no boundary at zero breaks, no
gain at the top of the path) reads —. Gain is the drop in total BIC
against the solution with one fewer break — its column header carries the
tooltip “ΔBIC against the solution with one fewer break.” The path’s own
recommendation — the elbow, the largest number of breaks whose marginal gain
still clears a fixed penalty floor — is pre-selected and marked elbow in
Status; once a row’s phases have been fitted exactly it additionally reads
verified, and a phase too short to fit on its own is named directly
(excluded: run 706, or excluded: runs 706, 707 for more than one). A
short summary above the table states the selected row in plain language —
"2 transitions found: 16.5 ± 0.5 K and 28.5 ± 0.5 K.", or "No
transitions found: one phase describes the whole series." when the elbow
sits at zero breaks — with an excluded phase named in the same sentence:
" Run 706 is excluded from the global fit: it looks like a different
phase."
A footnote below the table reads “Transitions are scored with BIC;
the ranking metric applies within a phase.” — the partition is always scored
with BIC (a structural change between nested model families is nearly free
under AIC’s flatter penalty, so AIC/AICc would frequently see no elbow at all)
whatever ranking metric you have selected;
that metric still decides which candidate wins inside each phase. Selecting
a row recolours the overlay by phase, and the stepper’s summary follows it
(“1 transition · 21 ± 3 K”).
A phase must span at least three runs. A shorter run of leftover points is admitted only at either end of the series, where it is scored at its own per-run cost plus the usual break penalty and reported as excluded rather than forced into its neighbour’s fit; an interior run that does not fit its neighbours is a per-run gate failure instead (see When to trust the recommendation below), never silently dropped from the middle of a phase. A break’s position is reported as the midpoint between the two adjacent runs, with a half-gap uncertainty of half their separation — a break between runs at 15 K and 18 K reports as \(16.5 \pm 1.5\) K.
Selecting a row with at least one break enables Optimize phases, which runs the coupled search independently on each phase of that solution (plus the neighbouring solutions and shifted breaks the wizard checks to confirm the elbow, at no extra cost to you beyond the wait) — the break-free row is the ordinary series-wide answer that Optimise N families → on the Screen step already produces, so it carries no separate action here. The run shows in the Phases step under “Optimizing each phase…”, stepping from “Preparing the series screening table…” through “Optimising each phase…”, which becomes “Optimising phase i of N…” once individual phases start; the status line reads “Running the coupled global optimisation once per phase. Progress is streamed to the live log.”
What each phase’s answer is follows Recommend. Under Best for trending the sharing ladders are climbed on each phase’s own runs, and a phase’s answer is its best pre-selected rung among the models that fit that phase about as well as its best one. Once the run finishes, one row per phase appears beneath the card, headed by the phase’s ordinal, range, and template, and built like a rung row of the Compare step: the role chips, the Cost and Trend bars, and the ladder’s findings. Only the answer is kept for a phase, not its whole ladder, so there is nothing to unfold here; to see a phase’s other rungs, select its runs and run the wizard on them as a series. Click a row to draw that phase’s coupled fit over its runs, with residual strips. Beneath the overlay, a strip traces every parameter a phase leaves local, each phase in its own colour, with the boundaries dashed — the piecewise trend across the transition. The breaks themselves are still placed by BIC on the phases’ best fits: a rung may cost up to 2σ and a model up to 3 %, which on real point counts is more than a break is worth, so scoring breaks by the answer would let the objective move them.
Under Best statistical fit a strip of phase chips appears beneath the
table instead, one per phase, each naming its ordinal and range, its
template, its Global/Local split (Global: A_1, A_bg · Local: Lambda), and a
confidence line (“High confidence”, or “Medium confidence — check the
warnings”). Click a chip to draw that phase’s coupled fit.
The verified row’s Apply phases button opens the Apply step to review the phases; its own Apply phases then creates one nested data group per phase under the series group (see Phases within a group in GUI usage), records one global-fit series per phase (see Phase-owned series in Parameter trending), and binds the global-fit tab to the first phase. A run that a phase’s rung exempts stays in that phase’s group and is left out of its series, as for a series-wide rung. The main window’s status bar confirms what was created, e.g. “Applied 2 phases under Runs 901-906 (2 transition(s)).”, and names any runs left out.
What “trends best” and “fits adequately” mean
The trend objective answers two questions in turn: which sharing patterns the data allow, and which of those leaves parameters that can be followed along the series. Both are measured in units that do not depend on how many points a run holds.
Fits adequately. A sharing pattern is judged against the same model with every parameter local — the best that model can do on these runs — never against a fixed value of \(\chi^2_\nu\). Sharing can only raise \(\chi^2_\nu\), and for \(\nu\) degrees of freedom \(\chi^2_\nu\) scatters about one with standard deviation \(\sqrt{2/\nu}\), so the rise is counted in that unit:
A pattern is adequate while the cost is at most 2σ for the series and for every run taken on its own. The second condition matters: a parameter that is wrong for two runs out of twenty barely moves the series total. Between models the wizard applies a wider band: a model competes on its trends when its all-local \(\chi^2_\nu\) is within 3 % of the best model’s. An information criterion is not used for either judgement. On a run of tens of thousands of points a systematic difference no eye can see is worth tens of information units, which is how the statistical ranking comes to prefer everything local. Both tolerances are fixed; the ladder in the Compare step is the control, since it shows what every pattern costs and lets you pick a costlier one.
Trends best. Each parameter a pattern leaves local has a trace: its fitted value and uncertainty at every run, in sweep-axis order. Its trend quality is the product of three factors, each between 0 and 1:
the determined share — the fraction of runs whose value the data pin down. A run does not count when its uncertainty exceeds half its value and a quarter of the trace’s span; the second test keeps an order parameter that falls to zero from being called undetermined there;
the signal, \(s = r/(r + 3)\) with \(r\) the trace’s span (its 10–90 % range) over its median uncertainty. A parameter flat within its errors scores low — it has nothing to show, and should be shared;
one minus the zigzag share — the fraction of interior points that lie outside the interval their two neighbours span by more than two combined standard deviations. The test compares a point only with its neighbours, so it does not depend on scale: a rate rising smoothly over three decades has no zigzag, and a genuine peak or step costs a single point.
A pattern is as good as its worst local parameter (ties go to the mean, and last of all to the ranking metric). Each model’s ladder pre-selects its adequate rung that trends best, and the recommendation is the best pre-selected rung among the models inside the band. Trend qualities within 0.05 of the leader’s count as a tie, which goes to a rung that is not hard to justify (below) and then to the model that fits better. A pattern with nothing left local is not a trend, and is offered only when no other is adequate.
The sharing ladder. For each model the wizard climbs from the all-local fits, which screening has already made, sharing a little more at each rung:
the background;
the amplitudes — first as one shared total when the model has two or more signal amplitudes (below), then every amplitude;
one further parameter at a time, in the order phases, shape parameters, static widths, field and geometry parameters, then rates and frequencies last.
Amplitudes and the background come first because they are what a series is least expected to change and what trades most freely against everything else when left local. Each rung is one coupled fit, started from the series median of every shared parameter and each run’s own value of the rest. A parameter whose sharing is not adequate is put back to local and the climb goes on to the next one, so a ladder costs at most a handful of coupled fits per model. A model with many parameters on a long series stops trying further parameters once the search has used its time allowance; the background and amplitude rungs are always fitted.
A shared total. Through a transition the volume fractions of two signals often change while the total asymmetry does not. For a model with two or more signal terms side by side the ladder therefore also fits the model written with those terms under one total and \(n - 1\) fractions — the same parameter count — and shares the total while the fractions stay local. The background is not part of the total: in a transverse field the constant is a different quantity from the precessing signal. The form is used only where the series can be written in it (every run’s total of one sign, no line whose sign its amplitude carries).
Exempt runs. A few runs with slightly more or less asymmetry than their neighbours — a change of slits, a sample that moved — would otherwise veto sharing the amplitude for the whole series, or be absorbed by a rate. Isolated runs whose amplitude stands apart (never three in a row, and at most the larger of two runs and 10 % of the series) keep their own amplitude while every other run shares one; the rungs above inherit the exemption, and the runs are listed on every such rung.
The end block. When the runs that cannot share the amplitude form a block at one end of the series, they are not exempted. The amplitude stays local, where its trace shows what happens, and the ladder reports the block. It reads “possible missing asymmetry there, or an amplitude that really changes” deliberately: asymmetry lost to a fast-relaxing or wide-field fraction outside the time window and an amplitude that steps for another reason look the same to the ladder, and telling them apart is a question for the physics of the sample. A block in the middle of the series, or a drift along all of it, simply leaves the amplitude local.
Hard to justify. Sharing a relaxation rate or a frequency while the amplitude of the same component varies from run to run says that the amount of a signal changes but its dynamics do not. That can be true, so the pattern is never forbidden; it is flagged, and ranks behind an unflagged pattern that trends equally well.
Passes disagree. A scan taken in two passes — a coarse one, then infill — can give parameters that zigzag in temperature order and are smooth within each pass, because something changed between the passes. No sharing pattern repairs that. When a local parameter’s zigzag share is at least 0.3 along the axis and at most 0.1 inside the passes, the rung carries the caveat and the summary names the parameter. It takes two passes of three or more runs to say so.
Two further rules keep the list honest. A rung of a multi-line or Overhauser model is left out when its lines are consistent with zero on some run, as in a phase where the oscillation has vanished, and a model whose pre-selected rung goes this way does not compete. And a run that fails its residual gate does not veto a rung: adequacy against the model’s own all-local fits and the band are what admit it, and the summary names the runs to look at.
How the role search works
This section describes the search behind Best statistical fit. Once a
template is selected for coupled optimisation — for the whole series,
or for one phase of a partition — the wizard still has to decide, for every
promotable parameter, whether it is shared (Global) or free per run
(Local). This is the role search, and it is now separable: every
effort tier resolves to the same engine, so there is exactly one honest
optimisation mode rather than a slider that trades accuracy for speed.
The separable search never pays to discover the all-local answer: \(G\)
independent per-run fits already are the all-local assignment, so it is
assembled directly from the phase’s own per-run results — no joint fit. A
full-covariance surrogate (a generalised-least-squares collapse of the per-run
values and covariances) then scores every sharing pattern at once and hands
back a warm start for it — pooled shared values, plus each run’s conditional
local values. Backward elimination walks from all-local, promoting one
parameter to Global at a time — cheapest by the surrogate first — with one
exact, warm-started coupled fit per step, and stops as soon as a step no
longer improves the information criterion; a handful of the most promising
templates race through this together, so a template that falls behind early
keeps its free all-local score rather than being fitted further for no
benefit. Once elimination stops, the winner’s single-flip neighbourhood (every
parameter toggled once from the winning assignment) is fitted too, so the
per-parameter Global/Local recommendations in the Compare step’s Details are exact
rather than inferred from the path taken to reach them. Every one of these
fits runs at the series’ own search resolution (the coarsest rebinning any
run’s own analysis chose); in a series-wide search only the winner, and its
flip-neighbourhood, are refitted once more at full resolution for the numbers
you actually see. A phase (see Phases: transitions and the penalty path)
is reported at the search resolution instead — every row of the penalty path
is then scored on the same points, and the fit you apply from a phase seeds
the Batch tab’s own global fit, which runs on the native record. The whole
search costs on the order of \(P\) coupled fits per template, where the
previous exhaustive search cost \(2^P\).
Each of those coupled fits is solved by a sparse least-squares minimiser rather than by Minuit. A coupled node’s Jacobian is arrow-shaped — every residual depends on the shared parameters and on exactly one run’s local ones — so the solver is told that pattern up front and evaluates one finite-difference column for the same local across every run at once. The cost of a Jacobian then grows with the per-run parameter count rather than with \(n_\text{global} + n_\text{local}\,G\). On a wide node — a twelve-run phase with nine free parameters per run over a couple of hundred thousand points — that is the difference between minutes per fit and seconds, and the equivalent Minuit problem over ninety-odd parameters may not converge at all. The fitted values, \(\chi^2\) and parameter uncertainties are the same quantities Minuit reports (the uncertainties come from the Gauss–Newton curvature at the solution, which for a \(\chi^2\) cost is Minuit’s own convention), so nothing about the ranking or the reported numbers changes — only how long the search takes. Asymmetric MINOS intervals are the one thing this solver cannot produce; the wizard does not request them.
The exhaustive “wavefront” search that enumerates every \(2^P\) role
assignment has not gone away — it is retained behind the lower-level
search_engine="exhaustive" argument as the harness referee the separable
engine is measured against, and it remains reachable through the same
argument for the small set of callers that still want it explicitly. It is
never reached from the GUI or from effort_tier.
tools/global_wizard_harness.py --engine {separable,exhaustive} runs either
engine against the frozen golden-verdict baseline; acceptance for a candidate
is at least 95% verdict agreement with the frozen (exhaustive) baseline, with
every disagreement inside the harness’s IC-gap tolerance — measured at 100%
agreement on the harness’s case set.
Ranking metrics
Candidates are ranked, and can be reranked, with the same three information criteria as the single-spectrum wizard:
Here \(k\) is the total number of free global parameters plus the run-specific local parameters, and \(n\) is the total number of fitted points across the selected datasets. Screening rows and coupled rows both aggregate the objective, free columns and samples over the series before computing the criterion. A shared column counts once and a local column once per run; fixed and constrained followers do not count. AICc is unavailable when \(n-k-1\leq0\) or the sample count is unknown. Unavailable rows are excluded under that metric; AIC is never substituted. If every fitted row is excluded, the message is “No fitted candidate can be ranked by AICc.”
AICc is the conventional small-sample correction, with the Gaussian
assumptions described in Fit wizard. AICc is the default; BIC applies a
stronger complexity penalty and usually favours simpler descriptions. Changing
the metric reranks the already-computed rows without rerunning the analysis —
rebuilding the screening table is only required if the selected datasets, model,
bounds, or expected roles change.
The metric ranks the Screen step under either objective, and with it the shortlist. Under Best statistical fit it also ranks the Compare step. Under Best for trending the Compare step is ordered by trend quality and the metric only breaks ties between rungs that trend equally well; a rung’s exempt runs each count one extra fitted parameter per shared amplitude.
When to trust the recommendation
The wizard states its recommendation plainly, but it is a decision aid, not a verdict to accept unread. Its confidence is worth calibrating against what the gate logic actually checks.
Under Best for trending the status line states the recommendation in one sentence — “Recommended for its trends: model, with these shared across the series and those varying from run to run.” — and then one sentence for each thing to know about it: the runs that keep their own amplitude, an end block the amplitude could not be shared through, a pattern that is hard to justify, passes that disagree, the runs on which the model leaves structured residuals (“review them before applying”), and a model that fits about as well and is listed to compare. A recommendation with only its first sentence is the one to trust with least reservation. Each further sentence is a caveat, not a veto: the wizard recommends a pattern whenever some model could be fitted on every run, because an imperfect model with its faults named is a better starting point than no recommendation. Read the trace strip first. If a parameter there does something the physics does not lead you to expect, unfold the ladder and pin the rung below as B: the two traces side by side show whether the feature belongs to the data or to the sharing.
Under Best statistical fit the recommended candidate is the best-scoring optimised candidate whose residuals pass every automatic residual check on every run. When the top two are within a small score margin the wizard presents them as a comparable pair and prefers the simpler one as the starting A on the Compare step; the status line then adds “with a similarly scoring alternative to inspect”, and pinning the runner-up as B sets the two side by side. A clean recommendation means every run’s residuals look unstructured under the shared-parameter fit.
Two softer outcomes deserve a closer look. A recommendation can carry a series-level caveat: every run clears its own residual gate, but the spectra change abruptly somewhere along the series, and the status line names where. Treat it as a lead: the per-run fits are sound, but the series may hold a transition that one model should not be fitted through. A per-run gate failure is different, and under the statistical ranking it still blocks — it means the model does not fit some runs — where the trend objective names the runs and recommends anyway.
The per-run readouts in the Scope step’s Series table carry the same honesty. A run whose best single fit shows no significant structure — its winner cannot beat a flat or plain-exponential baseline by a clear margin — is flagged with an unmissable series-level banner naming the affected runs. This is a per-run statement, not a series-wide verdict: it is entirely normal for most of a temperature scan to show clean structure while a handful of runs near a transition, or at the noisy end of a decoupling series, do not. It usually means the data there are well described by a plain relaxation, and forcing the richer global model onto those runs would be over-fitting.
In every case the honest move is the same: before applying, read A’s residual strips and flags on the Compare step, pin its nearest rival as B, read the cost or the parameter-sharing diagnostics in Details, and check that the local-parameter trends behave the way the physics leads you to expect.
Programmatic global fitting
This wizard is the asymmetry-domain shared-parameter workflow, driven from
the GUI. To share fit-function parameters across runs programmatically, use
the count-domain API fit_grouped_series(relationship="global", ...) —
see Cross-run global fits from the API in
Grouped time-domain fitting.
Calling the global wizard from a script
build_global_fit_wizard_screening_recommendation starts by analysing every
dataset in the series with the single-run Fit Wizard — the same tiered family
screen, peak analysis and damped-line scan
build_fit_wizard_recommendation()
performs on one spectrum. The series’ candidate list is then the union of the
templates those per-run analyses assessed, so a model that describes only part of
a temperature series (a heavily damped pair below a transition, say) is
considered for the whole series instead of being averaged away. A few runs are
analysed side by side, in sweep-axis order, sharing one pool of worker
processes: each analysis spends much of its time in stages that use one core
(spectral detection, the pattern search, the tier gating), so overlapping them
lets one run’s fitting use the workers another run’s serial stages leave idle.
That pool is opened once for the whole of this phase and serves the scoring pass
below as well.
Each analysis is also started from the fitted values of the nearest run that has already finished — an extra first attempt per candidate, tried ahead of the seed ladder. When that warm attempt and the plain seed both converge to the same minimum, the rest of the ladder is skipped: a fitted answer for the same model on a neighbouring run agreeing with a cold start leaves the remaining seeds nothing to find. They are climbed as usual when neither converges or when the two land in different minima, and the top-ranked candidates are re-fitted from the full ladder afterwards either way, so the ranking the recommendation rests on is never the short ladder’s.
A candidate no partition of the series could ever select is then dropped from the list before any scoring: one whose bare χ² on every run already exceeds some one other candidate’s information criterion there cannot win a segment under any sharing, whatever the segment. A candidate a run’s own analysis recommended, or scored comparable, is never dropped this way.
Histogram observations use the same counts-first preparation as the single-run wizard, preserving base and toolbar merges and selected crop membership. Captured sample, held-period, and reference counts and supplied variances have owned read-only storage. Later edits through original array aliases leave cached analyses and reconstructed curves stable; reduce edited inputs again and rerun the wizard to analyse a new observation. G+R pools prepared counts before background, binning, and one ratio; G−R bins independently prepared sets on common native support before differencing. Curve-only, rotated, and unresolved historical/custom observations retain independent-curve means. Search decimation, common-resolution completion, and curve reconstruction use that same observation contract; coarse search winners are refitted at the existing final resolution before their scores enter the final leaderboard. Per-run preparation precedes worker fan-out, so candidate tasks carry fit arrays and lightweight provenance rather than detector, reference, or period arrays.
For conditional calibration errors and histogram Gaussian omission,
see Calibration conditioning and Undefined and degenerate bins.
Used/omitted counts and reasons travel with the core fit result through search,
completion, and rebuilding; model scores count only the fitted observations.
Detection keeps the full acquisition grid. When omission prevents a residual
FFT or acquisition-lag autocorrelation, the diagnostic is unavailable; a valid
fit remains available. No missing-bin interpolation is inserted. The single-run
Details view shows unavailable and the core result explains
Residual autocorrelation and FFT unavailable: Gaussian selection omits acquisition bins.
Historical scores retain their recorded meaning, while numerical reuse requires
the current observation policy.
These remain asymmetry-domain fits with conditional point errors and
centre-point model evaluation; TF alpha/beta count calibration stays separate.
Internal spectral diagnostics preserve uniform curves and prepare nonuniform
captured histograms on separate Fixed native bins (factor 1, merge 1) over
exactly the retained native support. Original base/toolbar/crop/merge selections
resolve before that grid is chosen; discarded incomplete tails stay excluded.
Screening, completion, rescue and reconstruction retain the fitted observations
and scores. Residual spectra evaluate the same model/parameters on the separate
count view; original RMS/runs and residual times/errors stay with the fit.
Nonuniform original residuals have no acquisition-lag autocorrelation.
The residual-gate cell shows Unavailable when a measurement is missing;
it cannot establish a passing model-evidence gate. The result
records the separate view, policy, source observation, interval/support and recipe.
Curve-only nonuniform inputs and sampled-only trends cannot supply this replay.
See Fourier analysis and Fit wizard for the diagnostic support rule,
unavailable cases and compared-program limits. Saved historical scores load
without automatic fitting, FFT regeneration or reinterpretation; missing
historical diagnostic provenance remains unknown.
Every remaining run is then scored against every candidate at one common rebinning factor — the smallest any run’s own analysis chose — so the fit costs and point counts can be aggregated before applying a criterion’s penalty. The separately named partition BIC charges each shared column \(\ln N\) for the phase’s total samples, and each local column \(\ln n_r\) for its run. With all columns local this equals the sum of the per-run BICs; it differs from the series-total BIC used by the leaderboard. The cells a run’s own analysis already holds at that factor and observation identity are kept; the rest are fitted, warm-started from that run’s or a sibling run’s values. A cell started from that run’s own values for the same model at another binning is the same data and the same model at a different sampling — the same minimum by construction — so it is fitted once, from those values. A cell started from a sibling run’s values is a different record, so it gets the plain seed alongside the warm one.
On a long series this legitimately runs for many minutes before it returns;
each completed analysis and each completed score row is reported through
progress_callback so you can see it advancing rather than guessing whether it
has stalled. Pass a cancel_callback if you need to be able to stop it — it is
polled several times a second throughout, including while fits are running in
worker processes.
The scoring pass fans out one task per cell — one run, one candidate — across
the same process pool, so the
if __name__ == "__main__": rule in
Calling the wizard from a script applies here too: an unguarded
script degrades to serial execution with a SpawnUnsafeWarning rather than
crashing.
A cached single-run analysis is reused instead of repeated when it answers the same question — same candidate scope, same user-declared frequencies, and the same observation, resolved reduction context, support, and preparation contract. That is what the Fit tabs’ own wizard results give the global wizard: analyse a run once in the Fit Wizard and the series analysis does not pay for it again.
The two stages behind that call are also available separately, for a caller
that wants to reuse phase 1 across several screening calls (a scope sweep,
say) instead of paying for it every time:
build_or_complete_single_fit_wizard_recommendations_for_global_portfolio()
returns a GlobalFitWizardScreeningTable — its portfolio, the completed
recommendations_by_run, the runs’ own single_fit_recommendations_by_run,
the generated_run_numbers, and the series_rebin_factor. Pass that
portfolio (together with the single_fit_recommendations_by_run that
covers it) into build_global_fit_wizard_screening_recommendation(...,
portfolio=..., single_fit_recommendations_by_run=...) and phase 1 is skipped
entirely.
Every screening recommendation also carries a partition_path — the whole
penalty path over 0, 1, 2, … structural breaks along the series (None on a
series of fewer than six runs, where a partition is not attempted); see
Phases: transitions and the penalty path above for what the path means.
partition_path.selected_k is the pre-selected elbow, and
transitions_summary(partition_path.solutions[k], recommendation.series_axis_label)
renders the same plain sentence the Phases step’s Transitions card shows for
that row.
Passing a partition_path together with a partition_k into
build_global_fit_wizard_recommendation switches it from one series-wide
answer to one answer per phase of that solution — the two arguments are
refused unless given together, since a bare index does not name a path. The
result’s phase_assessments then maps (partition_k, segment_index) to a
GlobalCandidateAssessment, and recommended_partition_k records which
solution was optimised.
build_global_fit_wizard_recommendation takes an objective, a
SelectionObjective, and the recommendation it returns records which one it
was ranked for. TREND is the default. It asks which fit lets the parameters
be followed along the series: for every candidate whose independent per-run
fits come within 3 % in \(\chi^2_r\) of the best candidate’s, the wizard
fits a ladder of sharing patterns — the background shared, then the amplitudes,
then one further parameter at a time — and keeps a parameter shared only while
the fit stays adequate, which means that \(\chi^2_r\) rises by no more than
two of its own standard deviations, \(\sqrt{2/\nu}\), for the series and
for every run. The recommended candidate is the adequate pattern whose
remaining local parameters trend best. Each candidate of such a recommendation
carries a rung: its cost in those standard deviations, the trend quality of
each local parameter, the runs that keep their own value of a shared amplitude
(also given by exemptions), and the block of runs at one end of the series
through which the amplitude could not be shared. A run that fails its residual
gate does not veto a recommendation under this objective; the summary names it.
STATISTICAL is the role search and information-criterion ranking described
on the rest of this page, and is what the search_engine and effort_tier
arguments apply to. One call computes one objective, and merging a result of
one objective into a recommendation of the other replaces its optimised
candidates.
tools/global_wizard_harness.py --engine {separable,exhaustive} is the
regression check for the role search itself; see How the role search
works above for what the two engines are and the acceptance bar between
them. --objective trend runs the trend objective on its own planted cases
instead.
Screening never sets recommended_key. That is deliberate — a pre-screen score
comes from independent per-dataset fits, which are not evidence about a coupled
global fit — but it means a script that reads recommended_key alone gets
None from a perfectly good screen. Read the ranked table instead
(sorted_prescreen_assessments()), or read summary, which now names how
many candidates scored and which one ranks first, and says explicitly when a
screen scored nothing — the failure case that used to be indistinguishable
from an ordinary one.
Buying a cheaper answer: effort tiers
Scoring cost is (candidates × datasets × per-fit cost), and the candidate list a broad scope produces includes numerically integrated dynamic Kubo-Toyabe models that can cost an order of magnitude more than the rest of the list combined. On a fourteen-dataset series that is the difference between a screen that returns and one that does not.
effort_tier controls it. It narrows the series’ candidate list after the
per-run analyses have produced it, so it buys a cheaper scoring pass, not a
cheaper per-run analysis:
EffortTier.LOWScores a small set of the cheapest, most parsimonious candidates. Coarse, and fast enough to be interactive.
EffortTier.BALANCEDDrops only the numerically expensive candidates.
EffortTier.THOROUGH/EffortTier.EXHAUSTIVE(the default)Score the whole candidate list, exactly as before.
Candidates a run’s peak search positively identified — a multiplet pattern match,
or a multiplet model built from that run’s detected lines — are never dropped:
those come from the data, so removing them would change the answer rather than
coarsen it. Whatever is skipped is announced through progress_callback and
listed in instrumentation["screening_skipped_template_keys"], so a coarser
answer always says what it was coarsened by.
This tier only ever narrows the screening candidate list. The coupled optimisation that follows — deciding which parameters of the surviving candidate are Global versus Local — is a separate stage with its own, single engine at every tier; see How the role search works above.
Timing: telling “slow” apart from “hung”
Both wizards fill in a standard timing block when you pass an instrumentation
dict, and emit structured per-stage events to a stage_callback:
from asymmetry.core.fitting.global_fit_wizard import (
    build_global_fit_wizard_screening_recommendation,
)
from asymmetry.core.fitting.wizard_scope import EffortTier

def main():
    instrumentation = {}
    events = []
    recommendation = build_global_fit_wizard_screening_recommendation(
        datasets,
        effort_tier=EffortTier.BALANCED,
        instrumentation=instrumentation,
        stage_callback=events.append,
    )
    timing = instrumentation["timing"]
    print(timing["elapsed_seconds"], timing["cpu_seconds"], timing["cpu_cores"])
    for stage in timing["stages"]:
        print(stage["stage"], stage["elapsed_seconds"], stage["cpu_cores"])

if __name__ == "__main__":
    main()
cpu_seconds covers this process and its reaped pool workers, so
cpu_cores is what distinguishes a slow computation (several cores busy) from
a stalled one (near zero) — the question that otherwise sends a caller to the
process table. Each stage_callback event carries the stage name, a
start/item/end marker, items done and total, and the elapsed and CPU
time so far, which is what you want a timeout to watch: absence of progress
rather than total runtime.
Compared with other programs
The count-packing comparison with WiMDA 1.326, musrfit 1.12.1, and documented Mantid muon preprocessing concerns the prepared observations. It does not establish an equivalent global model-search algorithm. See Binning and timestamps for sources, versions, and numerical limits.
References
R. Killick, P. Fearnhead, and I. A. Eckley, J. Am. Stat. Assoc. 107, 1590 (2012) — optimal partitioning of a series with a penalised cost, the basis of the penalty path.
N. R. Zhang and D. O. Siegmund, Biometrics 63, 22 (2007) — a BIC-type criterion for choosing the number of change points.
K. P. Burnham and D. R. Anderson, Model Selection and Multimodel Inference: A Practical Information-Theoretic Approach, 2nd ed. (Springer, New York, 2002) — Akaike weights and the rule of thumb that a model more than 10 information units behind the best has essentially no support.